 xorbit01/webpalm
Multi-threaded web crawler for structured site mapping and regex-based data extraction. Exports results in JSON, XML, or TXT for reconnaissance and OSINT workflows.



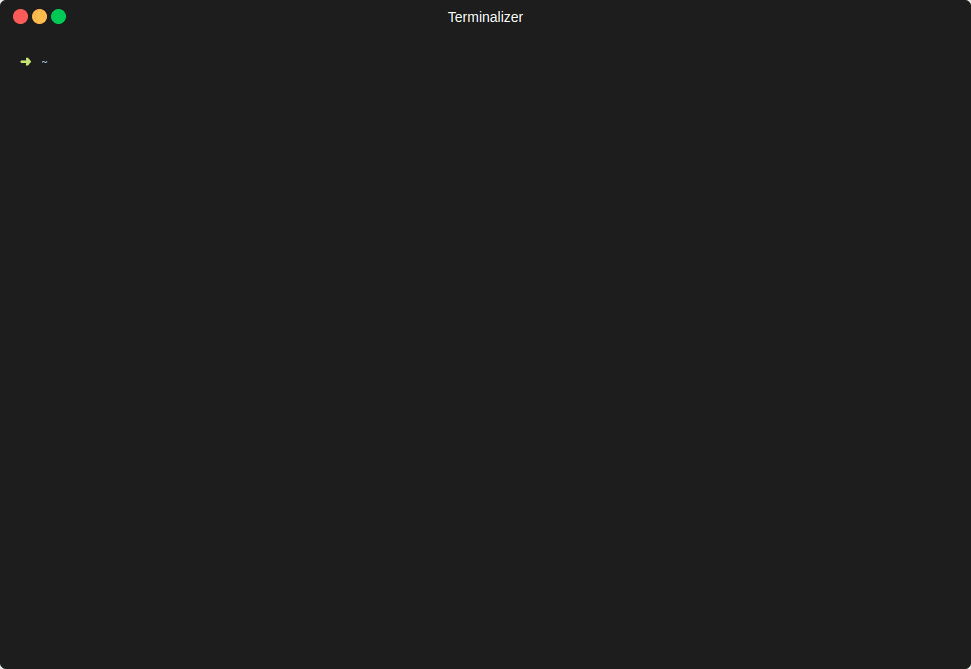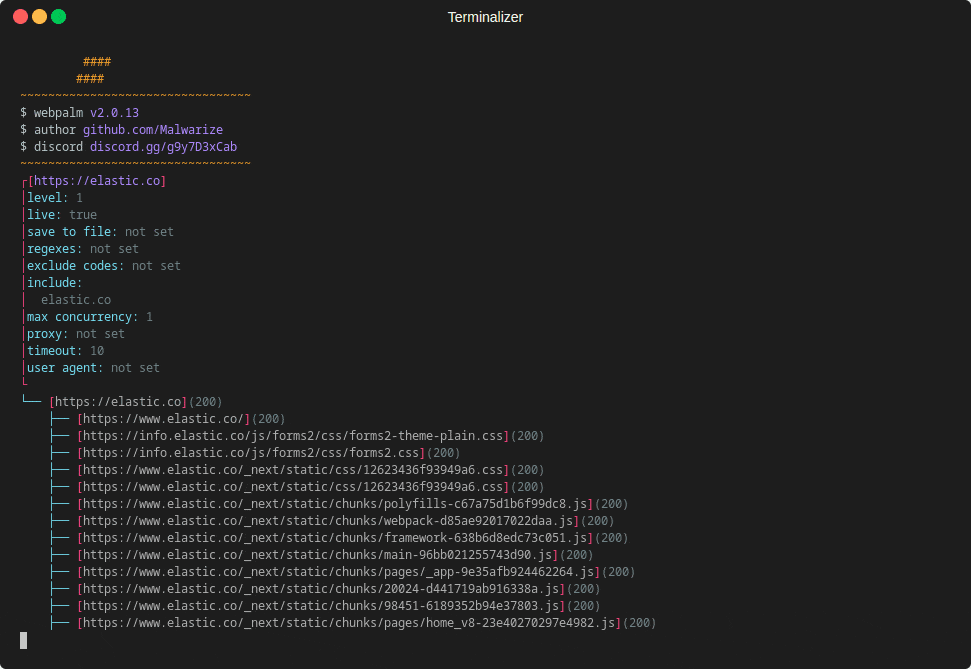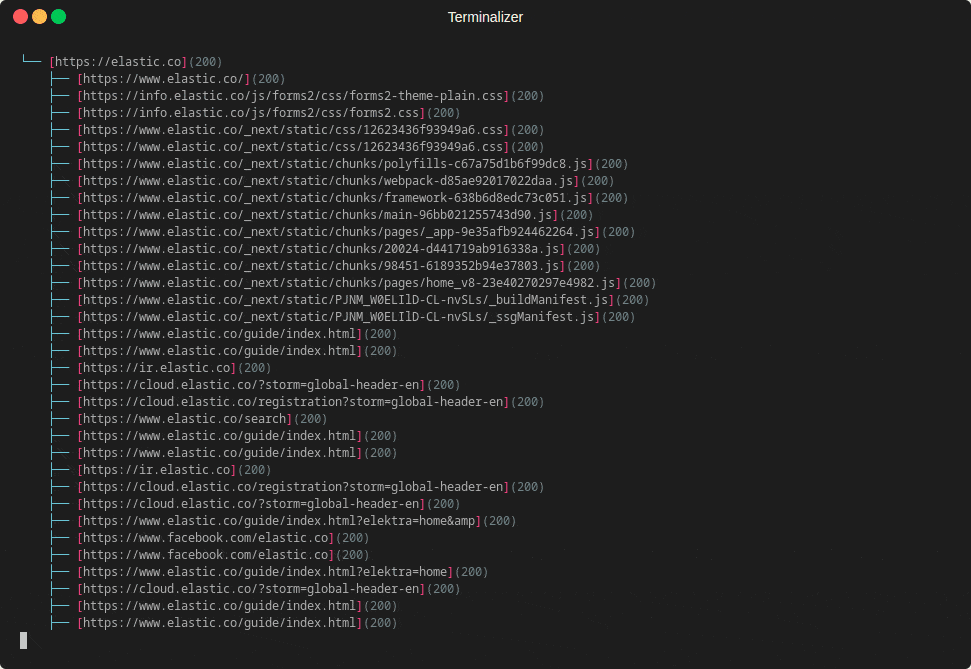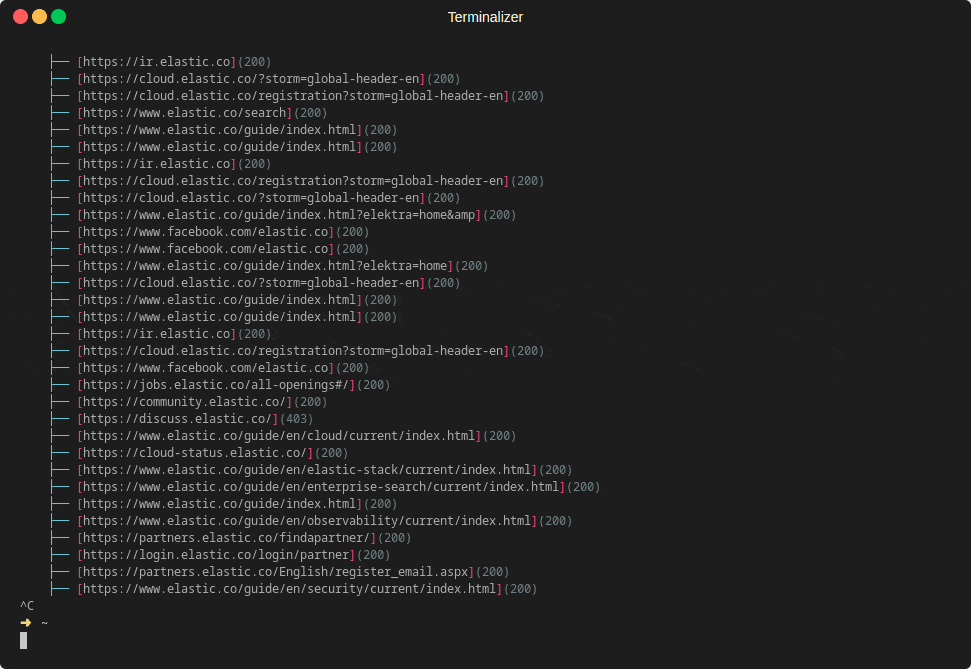
🔍 Crawl websites efficiently, extract structured data, and visualize connections. 🕵️♂️
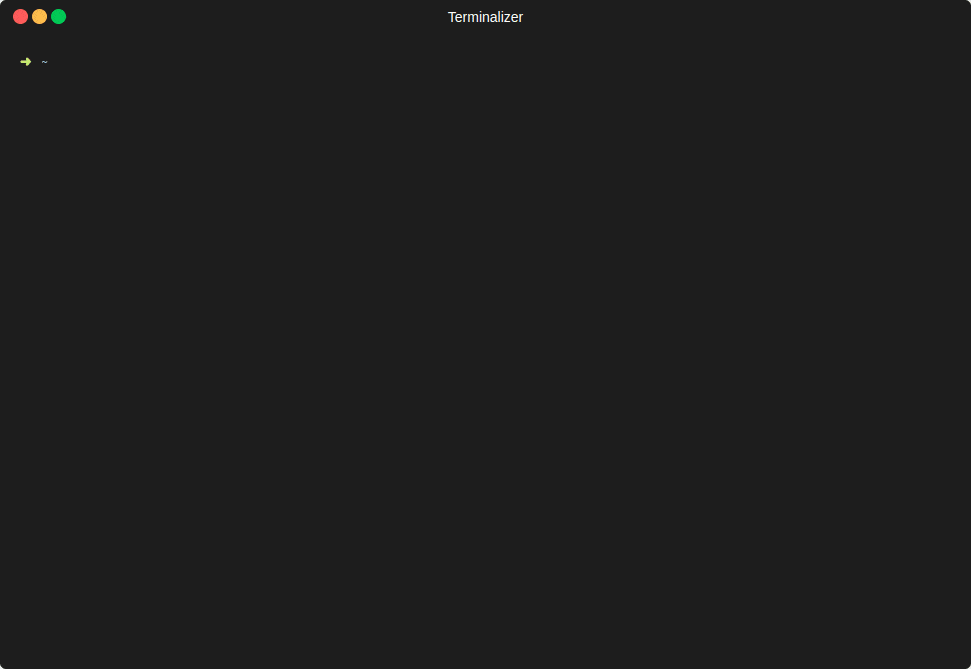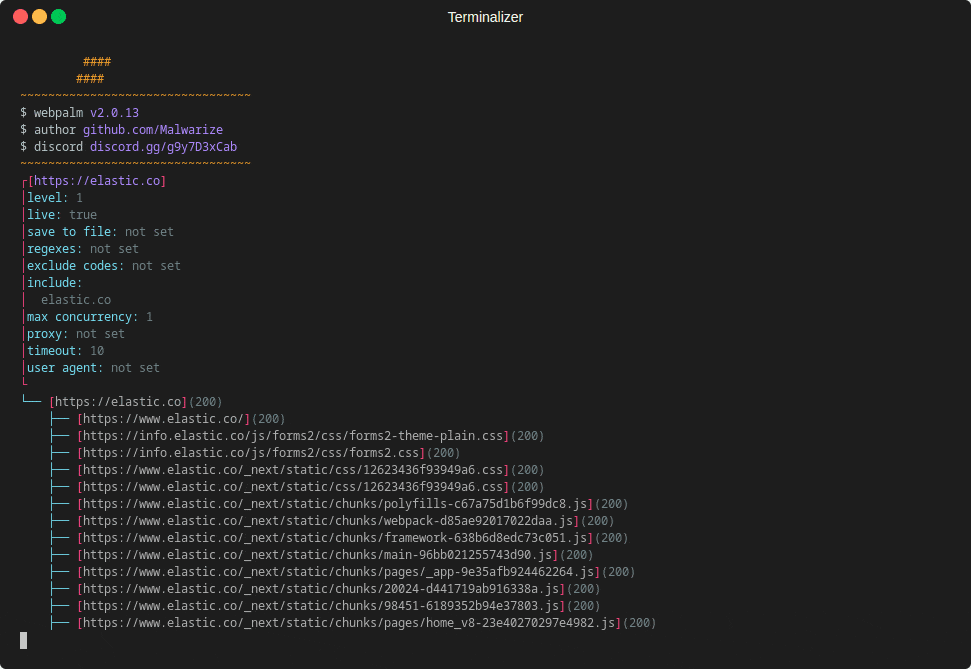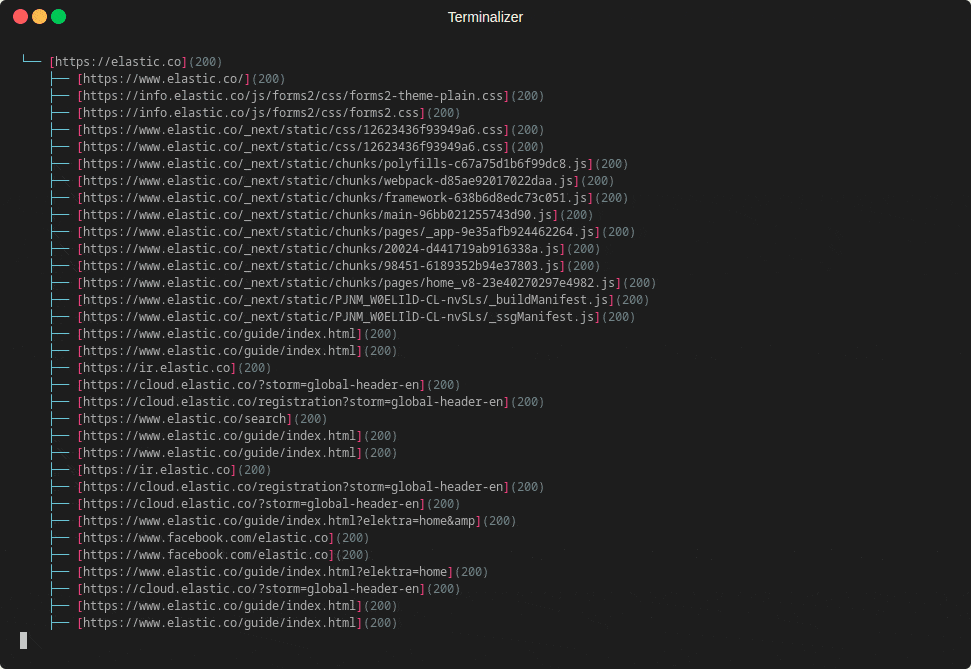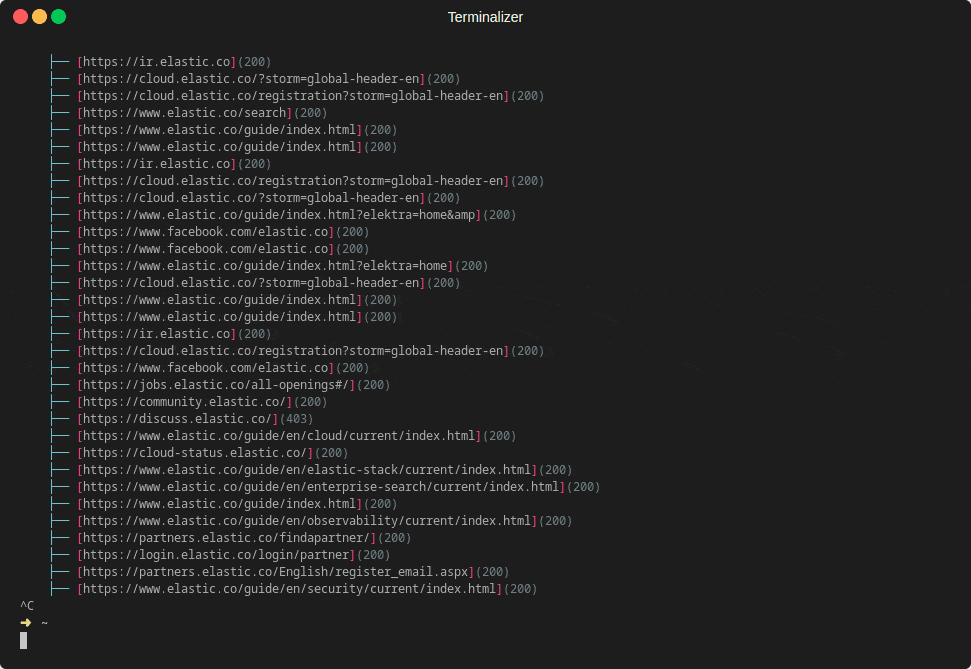
🌳 Structured Web-Tree Generation
🕵️ Regex-Based Data Extraction
⚡ High-Speed Multi-threading
📂 Multiple Export Formats
🎨 Colorized Output & Robust Error Handling
git clone https://github.com/XORbit01/webpalm.git
cd webpalm
go build -o webpalm && ./webpalm
go install github.com/XORbit01/webpalm/v2@latest
webpalm -h
🌎 -i, --include     # Include only specific domains (e.g., google.com, facebook.com)
🔗 -u, --url         # Target website
📏 -l, --level       # Depth of traversal
❌ -x, --exclude     # Exclude status codes (e.g., 404, 500)
💾 -o, --output      # Save results (JSON, XML, TXT)
🚀 -w, --worker      # Multi-threading workers
🔍 --regexes         # Extract data using regex
webpalm -u https://example.com -l2
webpalm -u https://example.com -l1 --regexes comments="\<\!--.*?-->" -o results.json
webpalm -u https://example.com -l3 -w 50
webpalm -u https://example.com -l2 -o output.xml
| 🔍 Purpose | 📜 Regex Pattern |
|---|---|
| 📧 Emails | [a-zA-Z0-9_.+-]+@[a-zA-Z0-9-]+\.[a-zA-Z0-9-.]+ |
| 💬 Comments | \<\!--.*?--> |
| 🔑 Tokens | [a-zA-Z0-9]{32} |
| 🔐 Passwords | \bpassword\b.{0,10} |
📌 Escape special characters if needed.
💡 Pull requests are welcome! Open an issue before major changes.
📢 Discord: xorbit.

