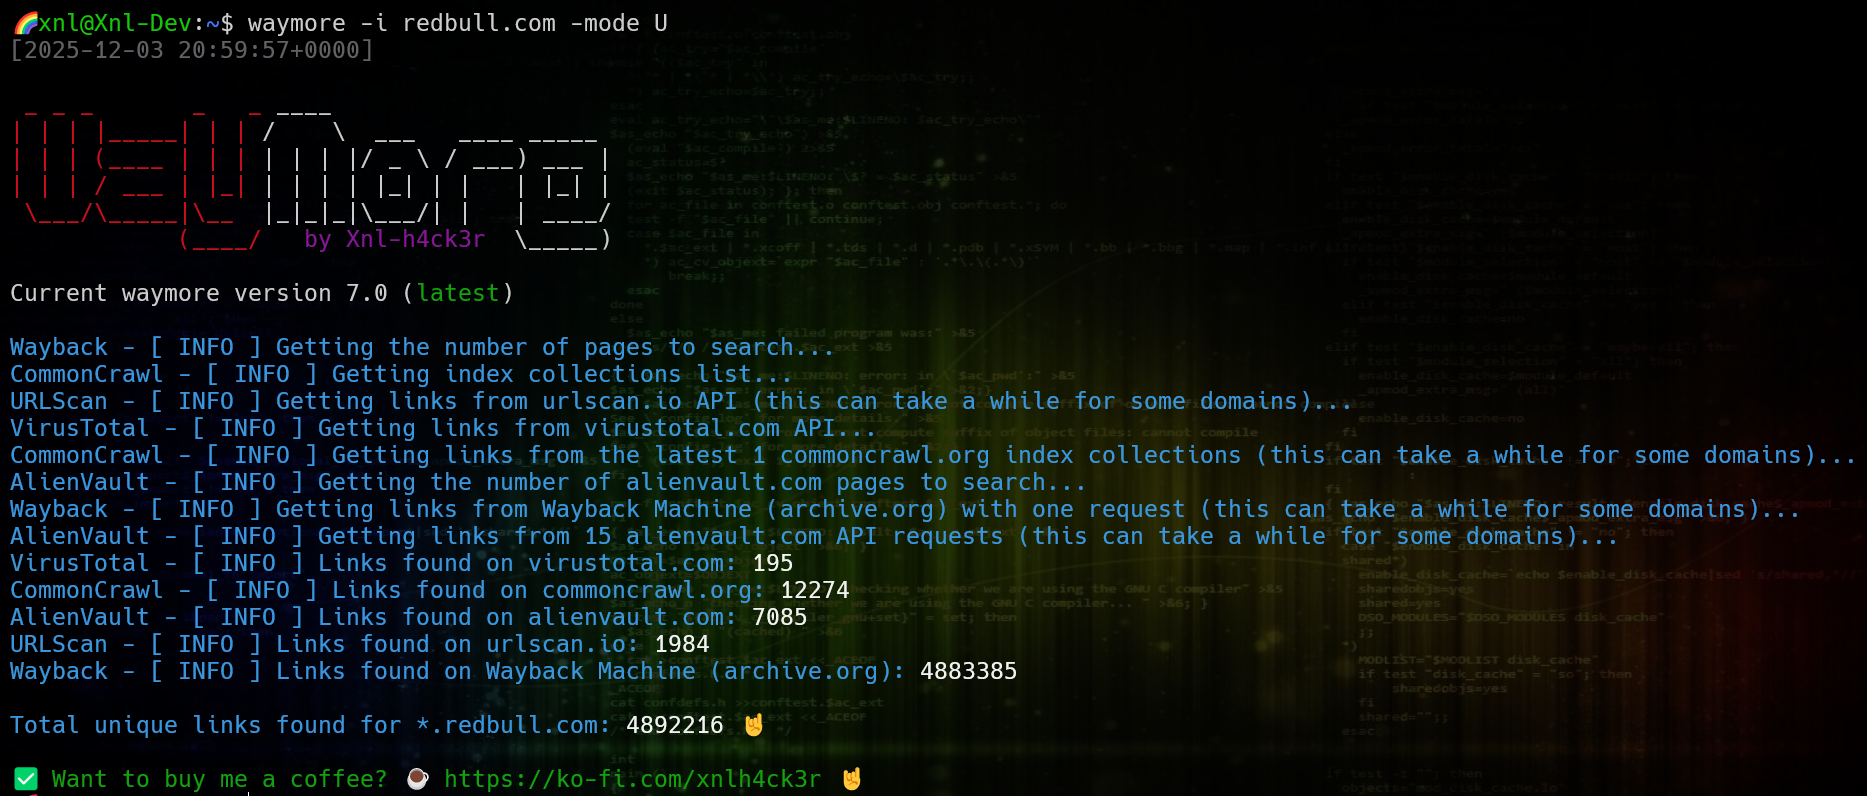
 xnl-h4ck3r/waymore
Find way more from the Wayback Machine, Common Crawl, Alien Vault OTX, URLScan, VirusTotal, GhostArchive & Intelligence X!

The idea behind waymore is to find even more links from the Wayback Machine (plus other sources) than other existing tools.
👉 The biggest difference between waymore and other tools is that it can also download the archived responses for URLs on wayback machine (and URLScan) so that you can then search these for even more links, developer comments, extra parameters, etc. etc. 👉 Also, other tools do not currently deal with the rate limiting now in place by the sources, and will often just stop with incomplete results and not let you know they are incomplete.
Anyone who does bug bounty will have likely used the amazing waybackurls by @TomNomNoms. This tool gets URLs from web.archive.org and additional links (if any) from one of the index collections on index.commoncrawl.org. You would have also likely used the amazing gau by @hacker_ which also finds URL's from wayback archive, Common Crawl, but also from Alien Vault, URLScan, Virus Total and Intelligence X. Now waymore gets URL's from ALL of those sources too (with ability to filter more to get what you want):
👉 It's a point that many seem to miss, so I'll just add it again :) ... The biggest difference between waymore and other tools is that it can also download the archived responses for URLs on wayback machine so that you can then search these for even more links, developer comments, extra parameters, etc. etc.
👉 PLEASE READ ALL OF THE INFORMATION ON THIS PAGE TO MAKE THE MOST OF THIS TOOL, AND ESPECIALLY BEFORE RAISING ANY ISSUES 🤘
👉 THIS TOOL CAN BE VERY SLOW, BUT IT IS MEANT FOR COVERAGE, NOT SPEED
⚠️ A common mistake that is made is passing a file of subdomains to get everything for a domain. DON'T DO IT! Just pass the domain only to get all subs for that domain. It will be SO much quicker, and you won't miss anything.
NOTE: If you already have a config.yml file, it will not be overwritten. The file config.yml.NEW will be created in the same directory. If you need the new config, remove config.yml and rename config.yml.NEW back to config.yml.
waymore supports Python 3.7+ (Python 3.7 or higher required for async/await support).
Install waymore in default (global) python environment.
pip install waymore
OR
pip install git+https://github.com/xnl-h4ck3r/waymore.git -v
You can upgrade with
pip install --upgrade waymore
Quick setup in isolated python environment using pipx
pipx install git+https://github.com/xnl-h4ck3r/waymore.git
| Arg | Long Arg | Description |
|---|---|---|
| -i | --input | The target domain (or file of domains) to find links for. This can be a domain only, or a domain with a specific path. If it is a domain only to get everything for that domain, don't prefix with www.. You can also specify a TLD only by prefixing with a period, e.g. .mil, which will get all subs for all domains with that TLD (NOTE: The Alien Vault OTX source is excluded if searching for a TLD because it requires a full domain). NOTE: Any scheme, port number, query string, or URL fragment will be removed from the input values. However, if you provide a path, this will be specifically searched for, so will limit your results. |
| -mode | The mode to run: U (retrieve URLs only), R (download Responses only) or B (Both). If -i is a domain only, then -mode will default to B. If -i is a domain with path then -mode will default to R. | |
| -oU | --output-urls | The file to save the Links output to, including path if necessary. If the -oR argument is not passed, a /results directory will be created in the path specified by the DEFAULT_OUTPUT_DIR key in config.yml file (typically defaults to ~/.config/waymore/). Within that, a directory will be created with target domain (or domain with path) passed with -i (or for each line of a file passed with -i). For example: -oU ~/Recon/Redbull/waymoreUrls.txt |
| -oR | --output-responses | The directory to save the response output files to, including path if necessary. If the argument is not passed, a /results directory will be created in the path specified by the DEFAULT_OUTPUT_DIR key in config.yml file (typically defaults to ~/.config/waymore/). Within that, a directory will be created with target domain (or domain with path) passed with -i (or for each line of a file passed with -i). For example: -oR ~/Recon/Redbull/waymoreResponses |
