
trawl v1.9.2
Self-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr alternative and drop-in replacement for your *arr stack.

TRAWL
Self-hosted web scraping for applications and AI agents. Get page content through an API or MCP, with built-in handling for supported browser challenges and CAPTCHAs.
TRAWL starts with HTTP, reuses verified clearance and opens Camoufox when a browser is needed. Repeat requests fetch fresh content without repeating a full solve whenever the site accepts the saved session.
Website · Documentation · Latest release
Features
- Challenge handling: Cloudflare, Anubis, Akamai, Imperva, DDoS-Guard and supported AWS WAF and DataDome flows. Built-in CAPTCHA paths include Turnstile, reCAPTCHA v2, hCaptcha, GeeTest Slide, ALTCHA, Friendly Captcha and CAP. Coverage and limits.
- Fast repeat requests: automatic HTTP clearance reuse, Redis or in-memory caching, and browser fallback when required. No named session is needed for shared clearance reuse.
- MCP for agents: read Markdown, scrape HTML, extract structured JSON, capture screenshots and inspect browser activity from known URLs.
- Isolated browser sessions: retain cookies, localStorage, sessionStorage and browser identity. Scrape within a session, keep a page open for JavaScript eval and read cookies. Session API.
- API and forward proxy: use
/scrape, the FlareSolverr-compatible/v1endpoint, or a challenge-aware HTTP/HTTPS proxy with WebSockets and Range support. - Local dashboard: persistent request history, tier outcomes, failure causes and live updates.
- Local solving by default: optional 2Captcha fallback and opt-in Firefox TLS/HTTP2 impersonation; Bun fetch remains the default HTTP transport.
Sponsors
View/Collapse All
|
Bright Data - The most powerful platform for Web Unlocker, SERP API and web scraping tools. Why Bright Data? • Web Unlocker - bypass any anti-bot protection • SERP API - real-time Google, Bing & more results • Scraping Browser & dedicated scrapers • Massive residential proxy network • Built for scale and reliability Get started for free with Bright Data! |
|
NodeMaven - The most efficient proxy provider for Web Scrapping and Automation with the Highest Quality IP on the market. Why NodeMaven? • ZIP targeting • 99.9% uptime • IP filtering: all proxies have fraud score <97% • No KYC required • Unique free tools: Proxy Bandwidth Checker, Meta Tag Checker, IP Lookup and others! Special codes for TRAWL users: • TRAWL35 - 35% off to Mobile and Residential Proxies• TRAWL40 - 40% off to ISP (Static) Proxies
|
Performance
Selected same-machine comparisons show faster first and repeat responses than FlareSolverr and Byparr on the default Cloudflare workload:
| Protected page | Best first | Best repeat |
|---|---|---|
| NopeCHA Cloudflare demo | 6.0 s | 879 ms |
| 1337x | 3.8 s | 85 ms |
| EZTV | 4.6 s | 473 ms |
Measured 2026-10-17 on a development build after v1.8.0. These are verified minima from the recorded sample. First requests used a warm browser with an empty target cache; repeats are fresh fetches with reusable clearance. Results vary by site, IP and session state.
Full comparison, medians and CPU/RAM · Method · Performance guide
Quick start
Run one browser with MCP, an in-memory clearance cache and persistent dashboard history:
docker run -d --name trawl \
  -p 127.0.0.1:8191:8191 \
  --shm-size=1gb \
  -e SESSION_CACHE_DRIVER=memory \
  -e BROWSER_POOL_SIZE=1 \
  -e MCP_ENABLED=true \
  -e METRICS_DASHBOARD_ENABLED=true \
  -v trawl_metrics:/data/metrics \
  ghcr.io/germondai/trawl:1.9.2

curl http://localhost:8191/health
Open the local dashboard. Keep the API and MCP endpoint on a trusted network; dashboard history survives container recreation through the mounted volume.
For Redis and Compose deployments, see the quick-start guide and Compose examples. Use :1.9.2-baseline on older CPUs or NAS hardware.
Dashboard preview
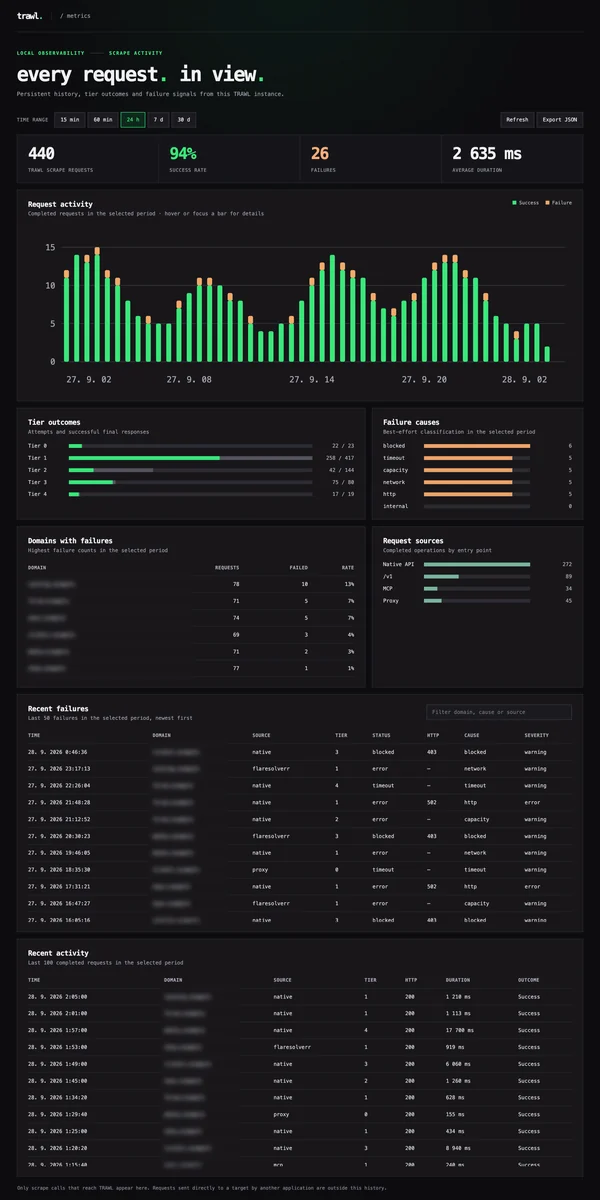
The screenshot uses illustrative traffic. Your dashboard shows requests actually handled by your instance. Metrics setup.
API
Native scraping
curl -X POST http://localhost:8191/scrape \
  -H 'Content-Type: application/json' \
  -d '{"url":"https://nopecha.com/demo/cloudflare","solveEmbeddedCaptchas":false}'
Returns HTML, cookies, the winning tier and timings. Set solveEmbeddedCaptchas: false for page content only; omit it to attempt supported embedded form widgets. Access challenges still need to clear. A delivered page does not by itself prove a form CAPTCHA was solved.