 sunnypatell/basalt
World's first hazard checker for NVIDIA Blackwell (sm_120), with an assembler and scheduler matched against their own compiler byte for byte. The check they never shipped.






The problem · Which GPUs · How it works · Quickstart · Measured, not assumed · Findings · API · Method · Roadmap · Clean-room
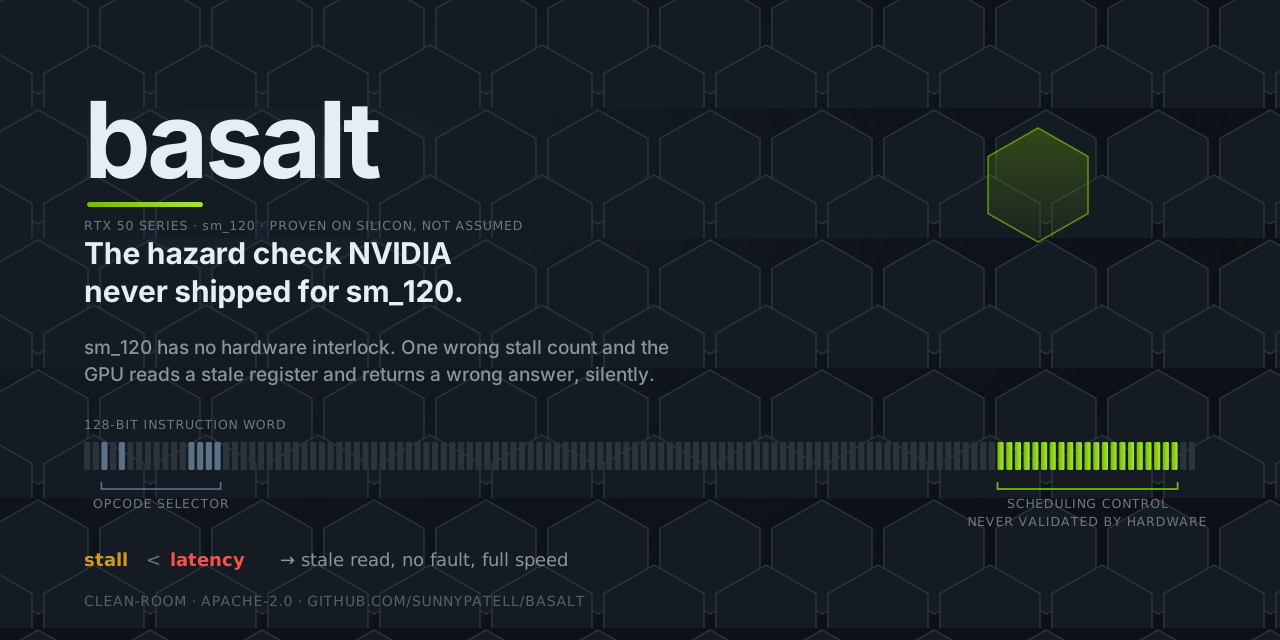
An NVIDIA GPU instruction is 128 bits, and 21 of them are not the instruction at all. They are a scheduling control word, stall through reuse: how many cycles to stall before issuing the next instruction, which scoreboards to signal, which to wait on, and which operands may be served from the reuse cache.
The hardware does not check any of it. On sm_120 there is no interlock on fixed-latency instructions. The silicon trusts whatever produced the control word. If a stall count is shorter than the latency of a value the next instruction consumes, nothing faults, nothing stalls, and no warning is emitted. The instruction reads a register that has not been written yet and computes on stale data, at full speed, every single time.
That is a strange kind of bug. It does not crash. It does not appear in a debugger. It produces numbers that are merely wrong, which in a matrix multiply or an attention kernel means a model that trains slightly badly rather than one that visibly breaks.
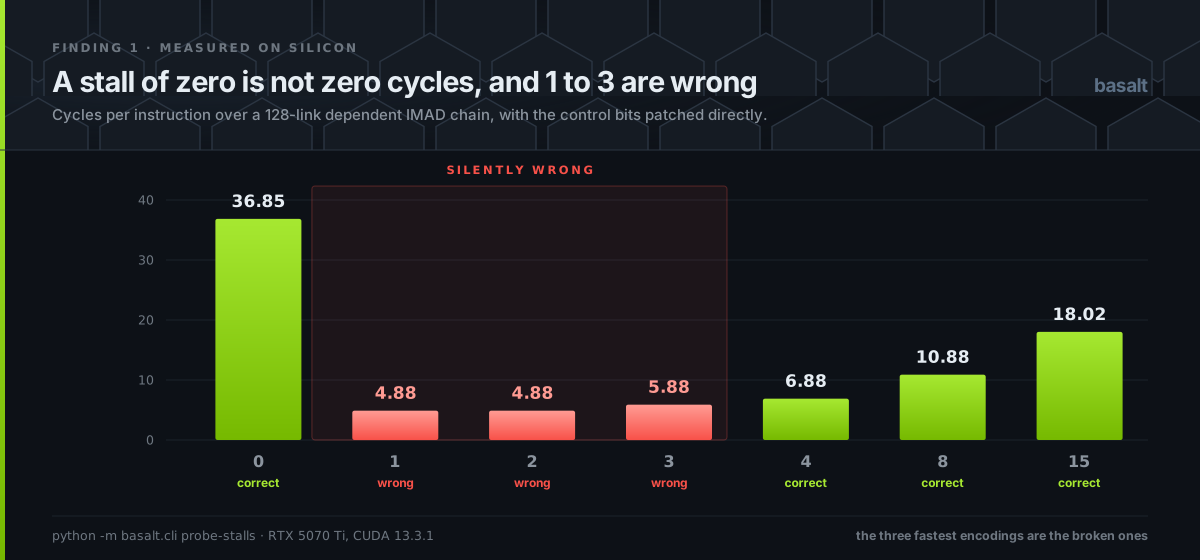
The three cheapest encodings are the broken ones, and nothing anywhere reports it. Note also what the left-hand bar is doing: a stall of zero is not zero cycles, it is a distinct safe encoding that waits for outstanding results and costs about nine times a scheduled instruction. A checker that read it as zero would call correct programs broken.
Tools that generate machine code for this architecture assign those control bits from a latency model. basalt is the thing that checks the answer.
NVIDIA gives you a compiler that writes those 21 bits. It gives you nothing that reads them back and tells you they are safe, and neither does anyone else.
Assemblers for NVIDIA GPUs have existed for a decade, the Blackwell encoding has been
reverse engineered before, there are published cycle-level characterisations of sm_120,
and one public assembler for this architecture already assigns the scheduling control bits
itself and runs its own kernels on a card to see that the answers come out right. All true,
and none of it is the claim:
Nothing else can be handed a cubin it did not produce and told to say whether its scheduling control bits are safe.
Your compiler emitted that cubin, or a library shipped it, or somebody hand-wrote it, and until now there was no way to ask. On an architecture with no hardware interlock that is the difference between "it ran" and "it is correct", and the difference is invisible: a stall one cycle short reads a stale register and returns a wrong number at full speed, with no fault and no warning, every single time.
Everything else here exists to make that sentence testable. The assembler is what builds a program with one stall deliberately shortened. The scheduler is what forces the model to commit to an answer rather than grade someone else's. And the audit is where the sentence stops being an absence and becomes a measurement: basalt pointed at 2,473 sm_120 cubins NVIDIA ships in cuBLAS, cuSOLVER, cuSPARSE, NPP and the rest.
Why it did not exist, in the field's own words. The most used SASS assembler says in its own documentation that "checking rigorous correctness of the whole program … [is] far from possible without official support. So, it is left to the user to guarantee the correctness of the program, with very limited help from the assembler." SIP, on autotuning SASS schedules, states that "validation is impossible for GPU native assembly codes because the formal semantics of the sass is closed-source."
Both are about semantic correctness: whether a kernel computes what it is supposed to. basalt does not answer that, and nothing here claims to. It answers a strictly smaller question, and the point is that the smaller question is decidable without the semantics:
Do this program's control bits cover its own data dependencies?