
awesome-ai-security
 ottosulin/awesome-ai-security
A collection of awesome resources related AI security
adversarial-attackai-securitycurated-resources+6
1.4k
ottosulin/awesome-ai-securityA collection of awesome resources related AI security
 mastyf-ai/mastyf.ai
Open-source AI security platform providing perimeter defense for LLMs and AI agents through swarm analysis, policy enforcement, adversarial testing,…
 promptfoo/promptfoo
Test your prompts, agents, and RAGs. Red teaming/pentesting/vulnerability scanning for AI. Compare performance of GPT, Claude, Gemini, DeepSeek, and…
 misp/misp-galaxy
Clusters and elements to attach to MISP events or attributes (like threat actors)
 datadog/stratus-red-team
:cloud: :zap: Granular, Actionable Adversary Emulation for the Cloud
 giskard-ai/giskard-oss
🐢 Open-Source Evaluation & Testing library for LLM Agents
 owasp/aisvs
The AI Security Verification Standard (AISVS) focuses on providing developers, architects, and security professionals with a structured checklist to…
 nvidia/garak
Modular LLM vulnerability scanner that probes for hallucination, data leakage, prompt injection, jailbreaks, and toxicity using static, dynamic, and…
 praetorian-inc/augustus
LLM security testing framework for detecting prompt injection, jailbreaks, and adversarial attacks — 190+ probes, 28 providers, single Go binary

 lsudoko/antibody
GitLab Duo DevSecOps loop where a second AI re-attacks every AI-written fix, saving each successful bypass as a permanent antibody replayed in CI and…
 gmh5225/awesome-ai-security
A curated list of AI Security materials and resources for Pentesters, Bug Hunters, and Security Researchers.
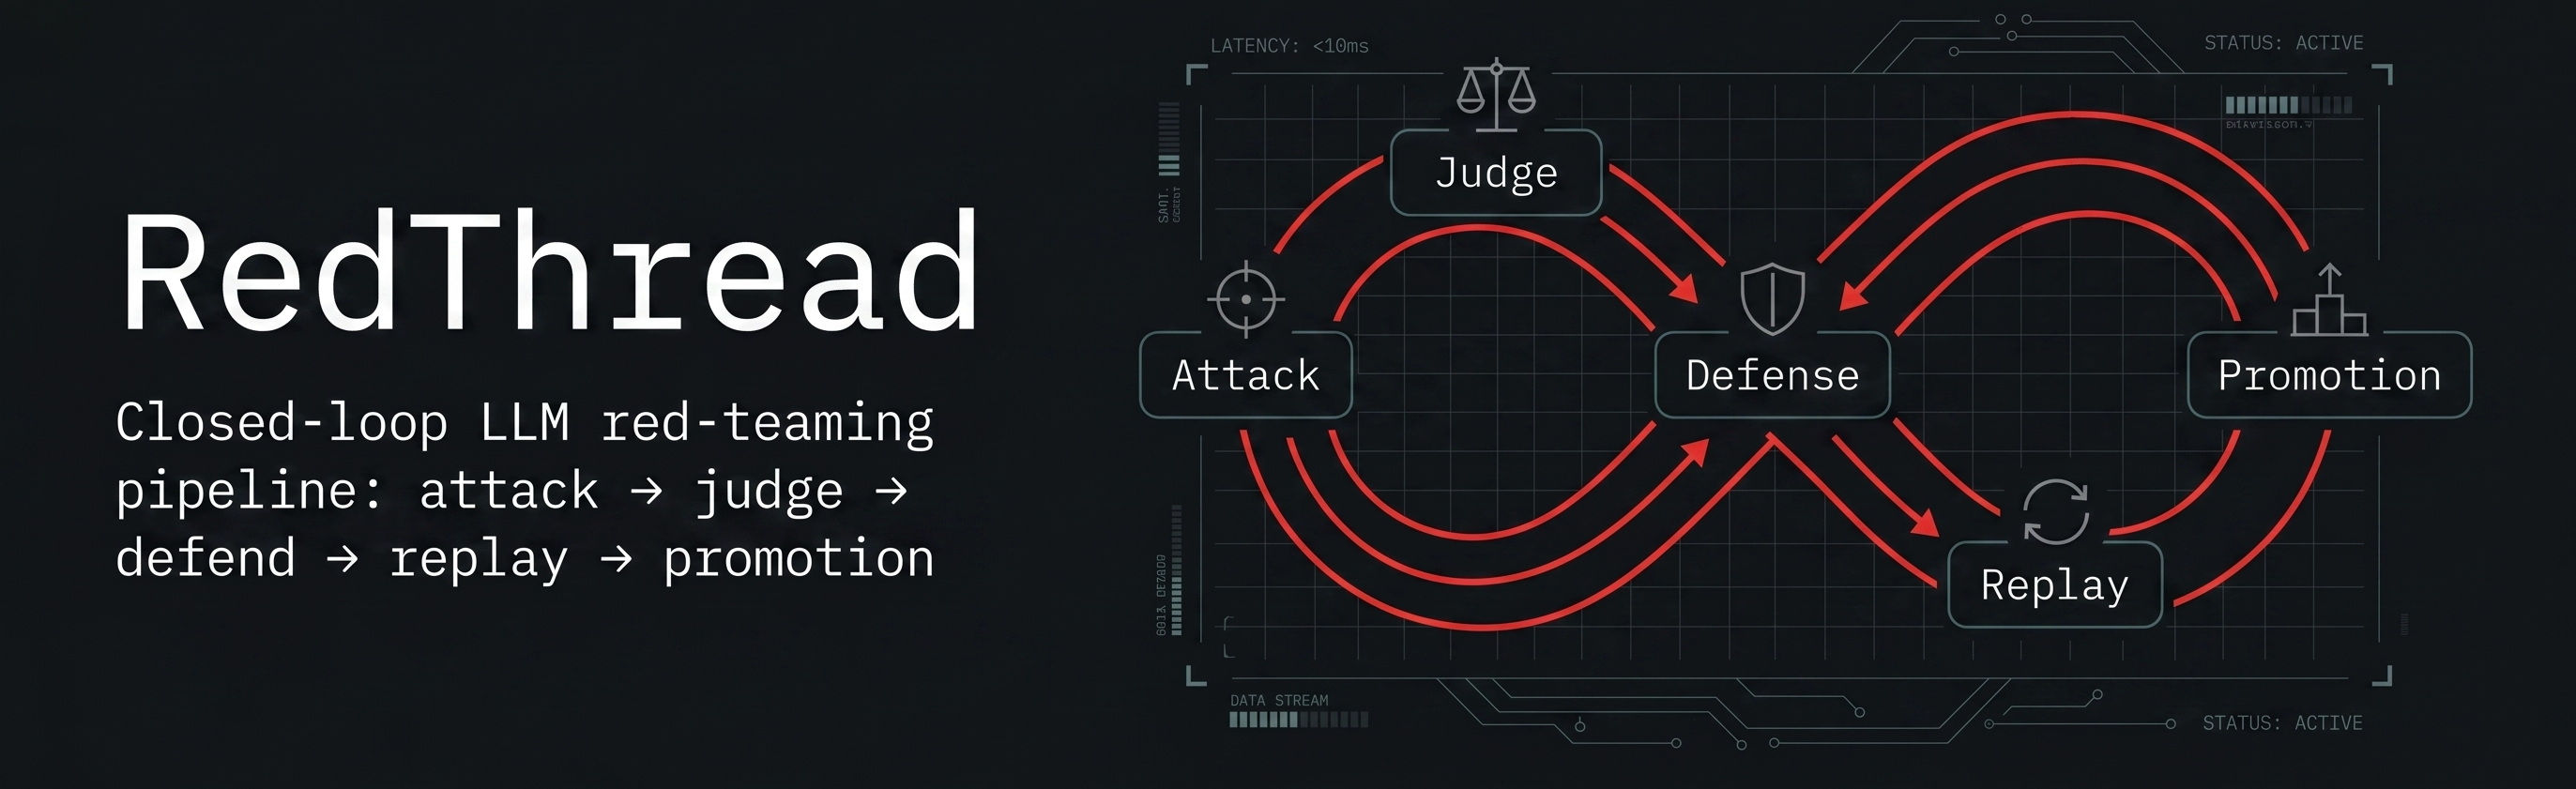 matheusht/redthread
An autonomous red-teaming engine for LLMs. RedThread manages the full security lifecycle: generating adversarial attacks, executing precision…
 cybrly/badsuccessor
Exploits the Windows Server 2025 dMSA privilege escalation vulnerability to enumerate writable OUs, escalate to arbitrary domain users, extract…
 promptfoo/modelaudit
Security scanner for AI/ML model files. Detects malicious code, backdoors, and vulnerabilities before deployment
 dovughs/mora-hwbp
Hardware Breakpoint (DR0-DR7) based patch-less user-mode hooking & telemetry instrumentation engine (AMSI, WLDP & ETW PoC).
 aniketkarne/aco-prompt-shield
Stop prompt injection attacks before they reach your LLM — zero API costs, runs entirely locally, integrates in 2 minutes. Prompt injection is the…
 ye-ze-yu/epireal-bench
Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…
 xrazymee/ragsieve
Self-referenced local contrast for knowledge-poison detection in retrieval-augmented generation