
New releaseSep 19, 2026
urx v0.11.0
OSINT संग्रह से सुरक्षा अंतर्दृष्टि के लिए URLs निकालता है
सुरक्षा अंतर्दृष्टि के लिए OSINT अभिलेखों से URL निकालता है।


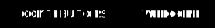

Urx किसी डोमेन के लिए Wayback Machine और Common Crawl जैसे OSINT अभिलेखों से URL एकत्र करता है। यह हर स्रोत को समानांतर रूप से क्वेरी करता है, फिर सुरक्षा कार्य के लिए परिणामों को फ़िल्टर, परीक्षण और प्रारूपित करता है।
विशेषताएँ
- बिना कुंजी वाले स्रोत: Wayback Machine, Common Crawl, OTX, Arquivo.pt, URLScan (अनाम)
- कुंजी रोटेशन के साथ कुंजी-आधारित स्रोत: VirusTotal, URLScan, ZoomEye, GitHub Code Search, BeVigil (Android ऐप्स से URL)
--cdx-endpointके माध्यम से कोई भी अन्य CDX सर्वर (pywb, OutbackCDX, राष्ट्रीय अभिलेखागार)- अभिलेख-पक्ष फ़िल्टर (
--from/--to,--archive-status,--archive-mime) CDX क्वेरी के अंदर चलते हैं - हर प्रदाता के लिए कैप्चर तिथि, MIME प्रकार और स्थिति पर क्लाइंट-पक्ष मेटाडेटा फ़िल्टर (
--meta-*) - पथ-सीमित लक्ष्य (
urx example.com/shop) और बग-बाउंटी स्कोप फ़ाइलें (--scope-file) - एक्सटेंशन, सबस्ट्रिंग, रेगेक्स (
--match-regex,--filter-regex) और प्रीसेट (no-images,only-js,only-secrets,only-backup,only-config,only-api) द्वारा फ़िल्टर - सामान्यीकरण और डीडुप:
--normalize-url,--merge-endpoint,--dedup-similar - plain, JSON, JSON Lines, CSV या
wordlistके रूप में आउटपुट;--streamआते ही URL लिखता है - पैरामीटर दृश्य: ffuf या dalfox के लिए
--params,--params-by-endpoint,--fuzz-placeholder FUZZ - प्रति URL कैप्चर मेटाडेटा:
first_seen,last_seen,mime,archive_status,digest - WARC, URLTeam और टेक्स्ट फ़ाइलों (
--files) या stdin से इनपुट - लाइव परीक्षण:
--check-status,--check-title,--extract-links,--extract-js-endpoints - अभिलेखित बॉडी:
--archive-bodyउन पेजों से लिंक खनन करता है जो अब मौजूद नहीं हैं, प्रत्येक भिन्न बॉडी के लिए एक अनुरोध;--archive-body-dirउन्हें सहेजता है - API स्पेक विस्तार (
--expand-specs): OpenAPI 3.x, Swagger 2.0, GraphQL introspection - अभिलेखित robots.txt और sitemap.xml संस्करण (
--archived-discovery) - लक्ष्य के लिए प्रमाणित अनुरोध (
-H,--cookie,--user-agent), जो कभी अभिलेखों को नहीं भेजे जाते - SQLite या Redis कैश (Redis के लिए
--features redis-cacheबिल्ड आवश्यक),--incrementalस्कैन,urx cacheरखरखाव, और--notifyवेबहुक
इंस्टॉलेशन
cargo install urx       # https://crates.io/crates/urx
brew install urx        # https://formulae.brew.sh/formula/urx
yay -S urx              # AUR
choco install urx       # Chocolatey (Windows)
स्रोत से (target/release/urx पर बाइनरी):
git clone https://github.com/hahwul/urx.git
cd urx
cargo build --release
Docker (ghcr.io/hahwul/urx)। इमेज में कोई entrypoint नहीं है, इसलिए इमेज के नाम के बाद ./urx लगाएँ:
docker run --rm ghcr.io/hahwul/urx:latest ./urx example.com
Linux, macOS और Windows के लिए प्रीबिल्ट बाइनरीज़, प्रत्येक .sha256 के साथ, releases पृष्ठ पर उपलब्ध हैं।
Shell कम्प्लीशन्स (bash, zsh, fish, powershell, elvish) और man पेज:
urx --completions zsh > ~/.zfunc/_urx        # ~/.zfunc must be on $fpath
urx --completions bash > ~/.local/share/bash-completion/completions/urx
urx --completions fish > ~/.config/fish/completions/urx.fish
urx --manpage > ~/.local/share/man/man1/urx.1
उपयोग
बुनियादी उपयोग
urx example.com                 # one domain
urx example.com example.org     # several domains
cat domains.txt | urx           # domains from stdin
विकल्प
Usage: urx [OPTIONS] [DOMAINS]... [COMMAND]

Commands:
  cache  Inspect and maintain the URL cache: stats, list, prune, drop <DOMAIN>..., clear

Arguments:
  [DOMAINS]...  Domains to fetch URLs for

Options:
  -c, --config <CONFIG>           Config file to load
      --provider-config <PATH>    Separate provider config file holding only API keys (default: ~/.config/urx/provider-config.toml; %APPDATA%\urx\ on Windows). CLI/env > provider-config > main config.
      --completions <SHELL>       Print a shell completion script (bash, zsh, fish, powershell, elvish) to stdout and exit
      --manpage                   Print the roff man page to stdout and exit
  -h, --help             Print help
  -V, --version          Print version

Input Options:
      --files <FILES>...        Read URLs directly from files (supports WARC, URLTeam compressed, and text files)
      --domain-list <PATH>      File of newline-separated domains to scan (repeatable; merged with positional DOMAINS; stdin is read only when they name no domains; `#` comments allowed) [alias: --dL]

Output Options:
  -o, --output <OUTPUT>          Output file to write results
      --output-dir <PATH>        Write one file per URL host into this directory (extension matches --format). Coexists with --output / stdout. [alias: --oD]
  -f, --format <FORMAT>          Output format: "plain", "json" (one array), "jsonl" (one JSON object per line), "csv", "wordlist" (path segments and parameter names, deduplicated and sorted); anything else is a usage error [default: plain]
      --stream           Write URLs as each provider reports them instead of once at the end (unsorted; bypasses cache; rejects options needing the full result set)
      --merge-endpoint   Merge endpoints with the same path and merge URL parameters
      --normalize-url    Normalize URLs for better deduplication (sorts query parameters, removes trailing slashes)
      --dedup-similar    Collapse URLs that differ only in variable data (numeric ids, UUIDs, hashes, dates, query values)
      --params           Replace the URL list with every query parameter name the run saw, once each
      --params-by-endpoint
                         One line per endpoint: the endpoint and the comma-separated union of the parameter names seen on it (id-looking path segments collapse to `{id}`)
      --fuzz-placeholder <VALUE>
                         Replace every query parameter value with VALUE, keeping one URL per parameter signature — output you can feed straight to ffuf or dalfox