 beenuar/aisoc
Self-hostable AI SOC that fuses security alerts, auto-triages via agentic AI, runs MITRE ATT&CK investigations, and logs every agent decision in a replayable ledger.


An open-source, self-hostable AI Security Operations Center. It ingests your security telemetry, detects and correlates threats, investigates them with AI agents whose reasoning is fully auditable, and proposes responses a human approves.


Telemetry arrives from your security tools. AiSOC normalizes it, runs the 2603 executable rules of its 6991-rule library, groups what fires into incidents, investigates each one with an AI agent whose every prompt and tool call is recorded, and proposes an action. New threat intelligence re-sweeps the history you already collected. A human approves before anything runs.
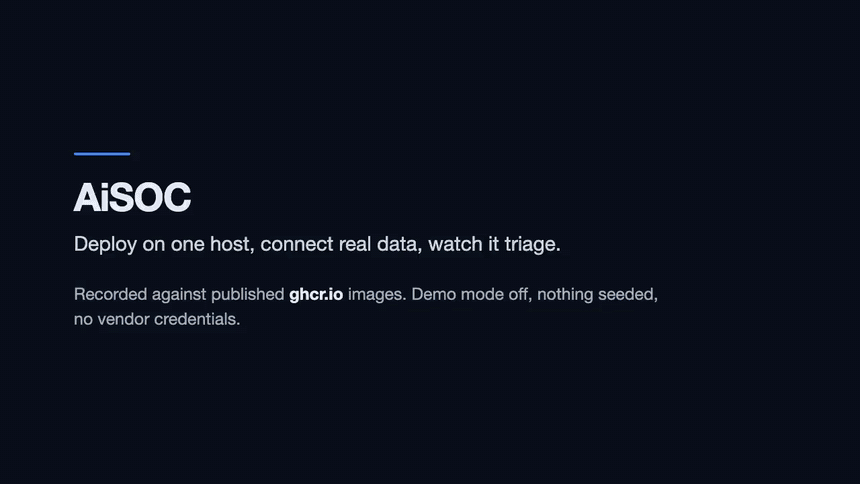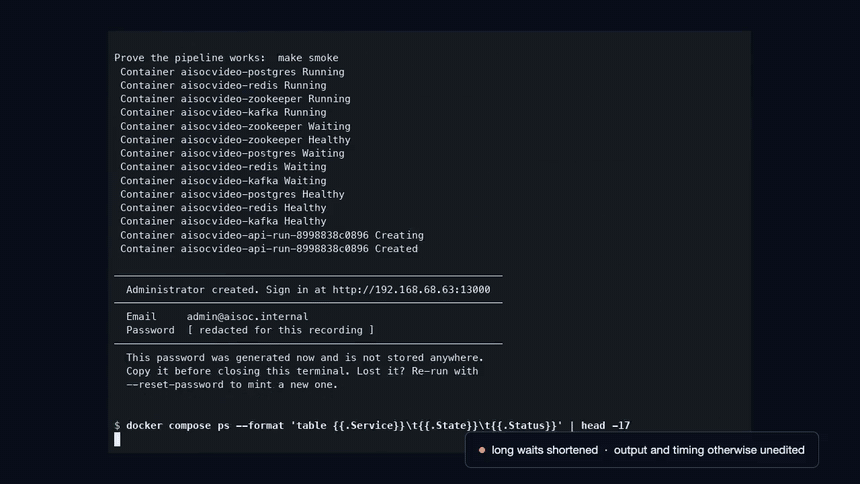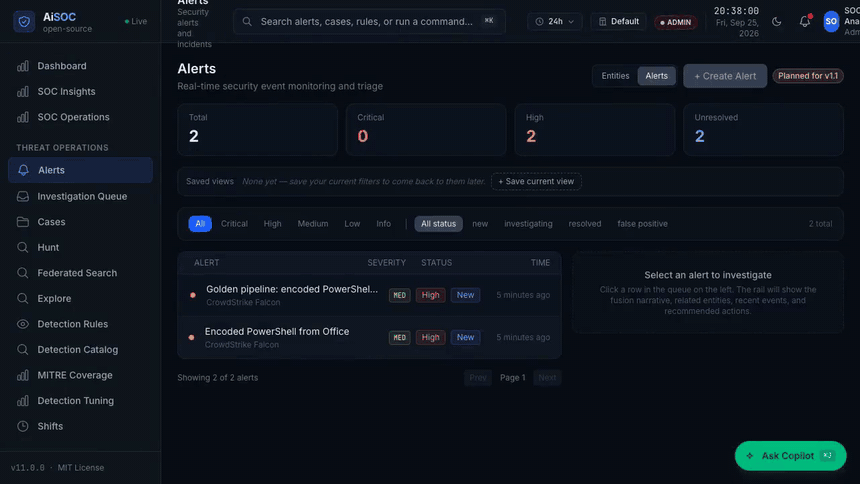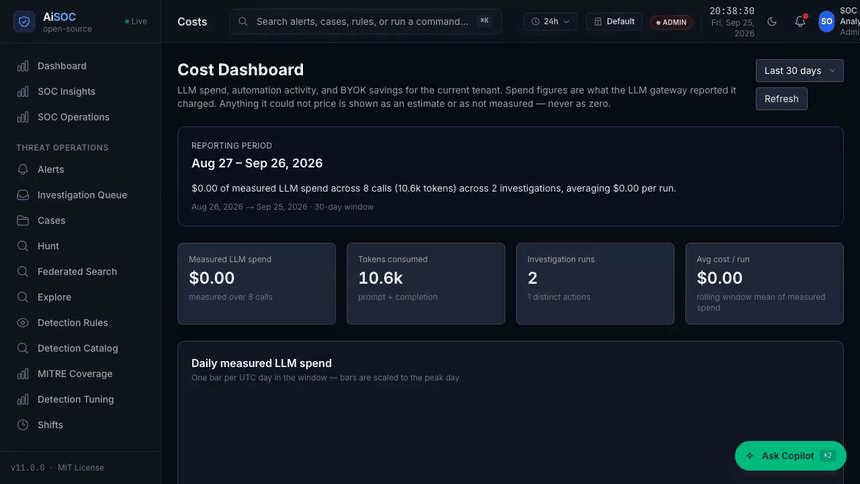
Watch the full three minutes — install to AI verdict on one server, against the published images. Terminal waits are shortened, which the recording says on screen. (step by step)
Stills from earlier runs under the same rules — no seeded rows, no demo mode, no mockups. The events were authored to be representative; everything downstream is the product doing its job. (what is real)
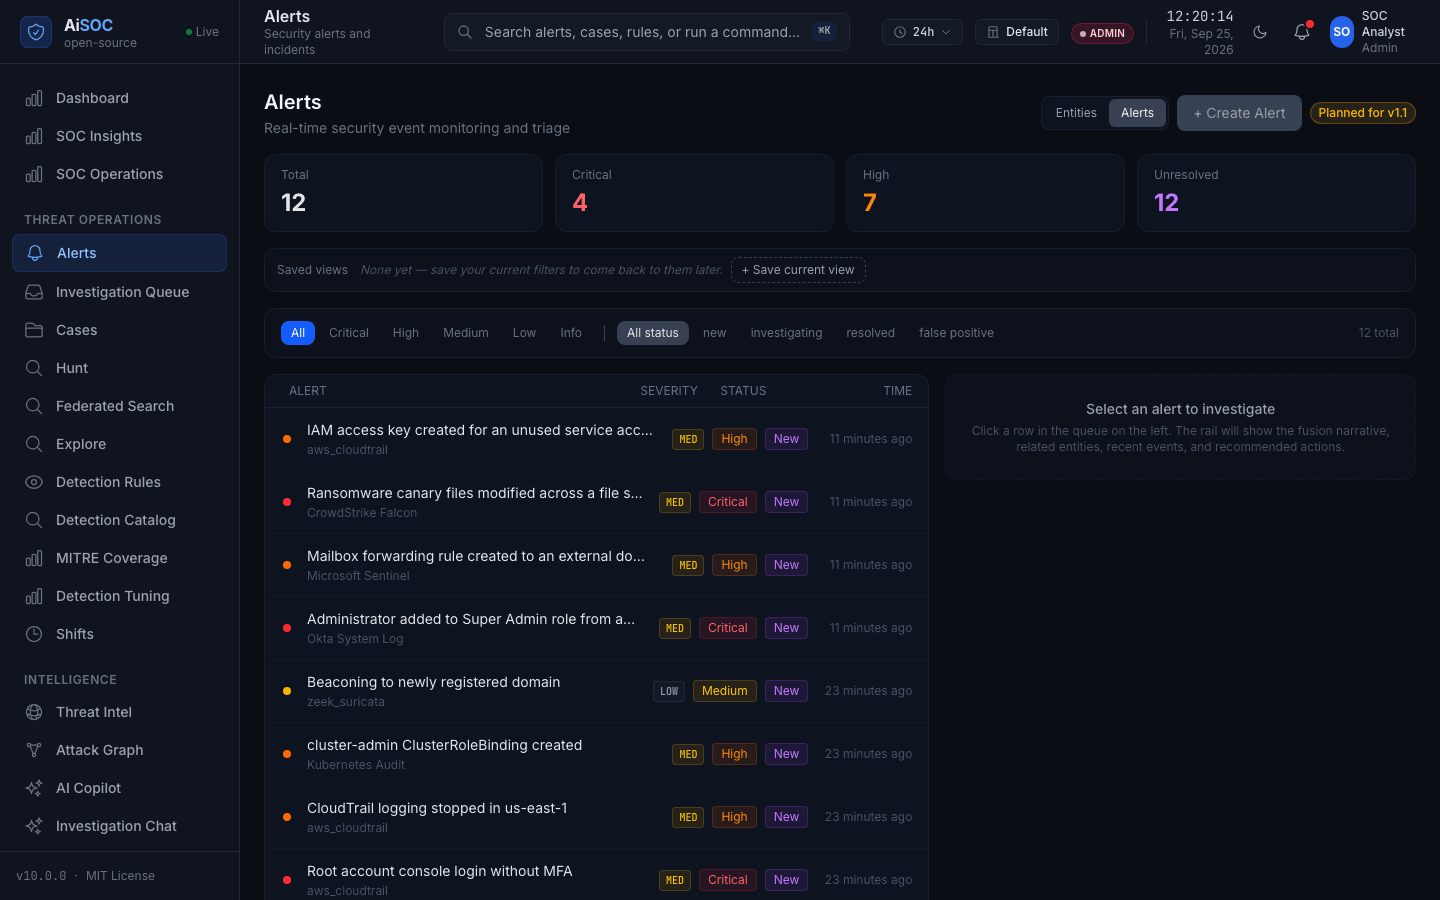 | 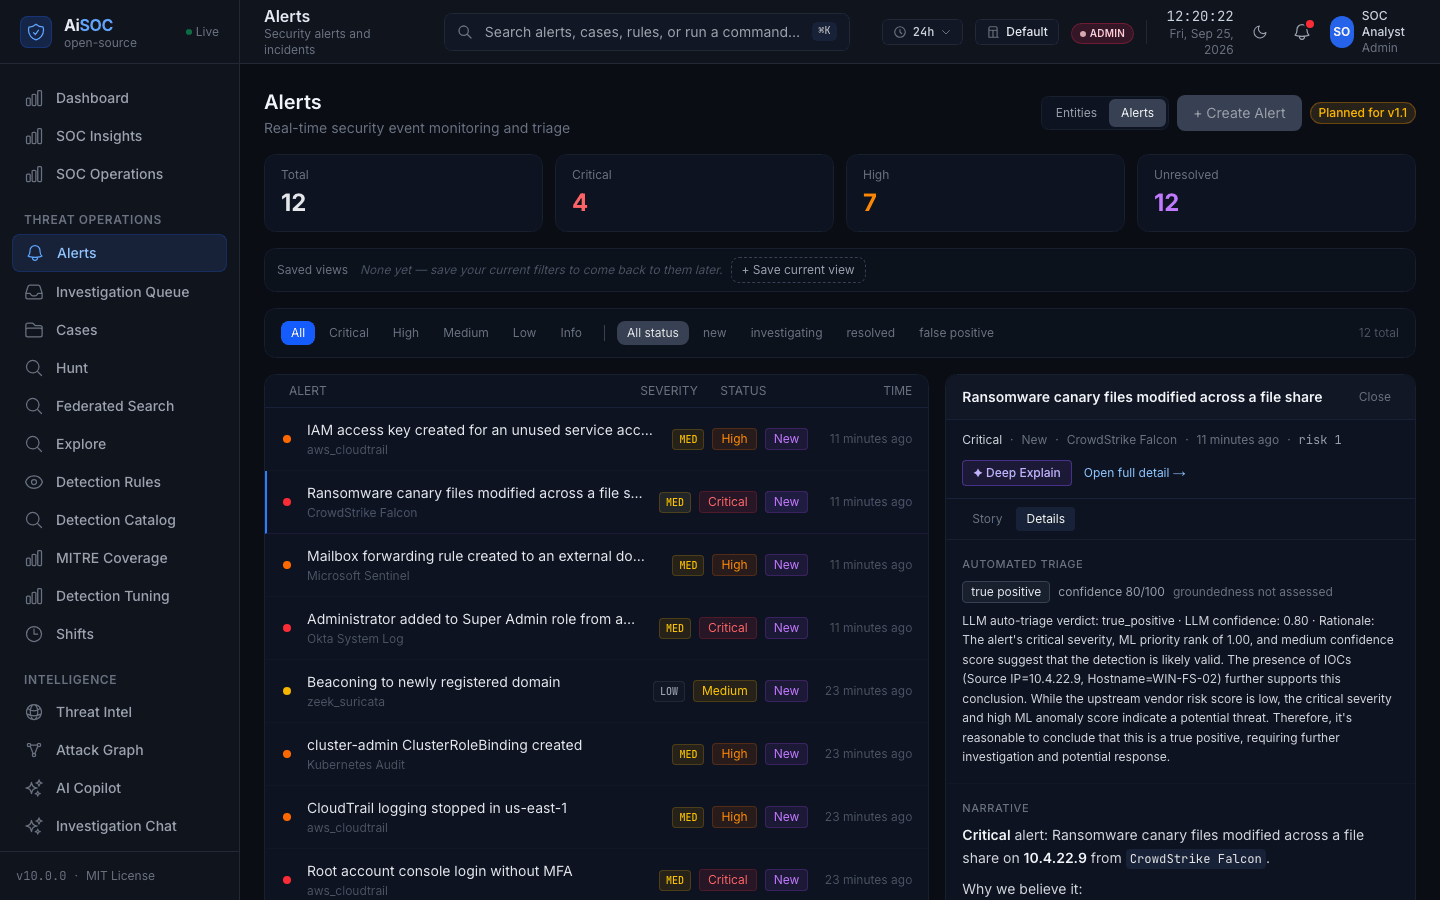 |
| Alerts — each attributed to the connector that fed it. | Automated triage — the bundled local model's verdict, confidence and rationale, verbatim. |
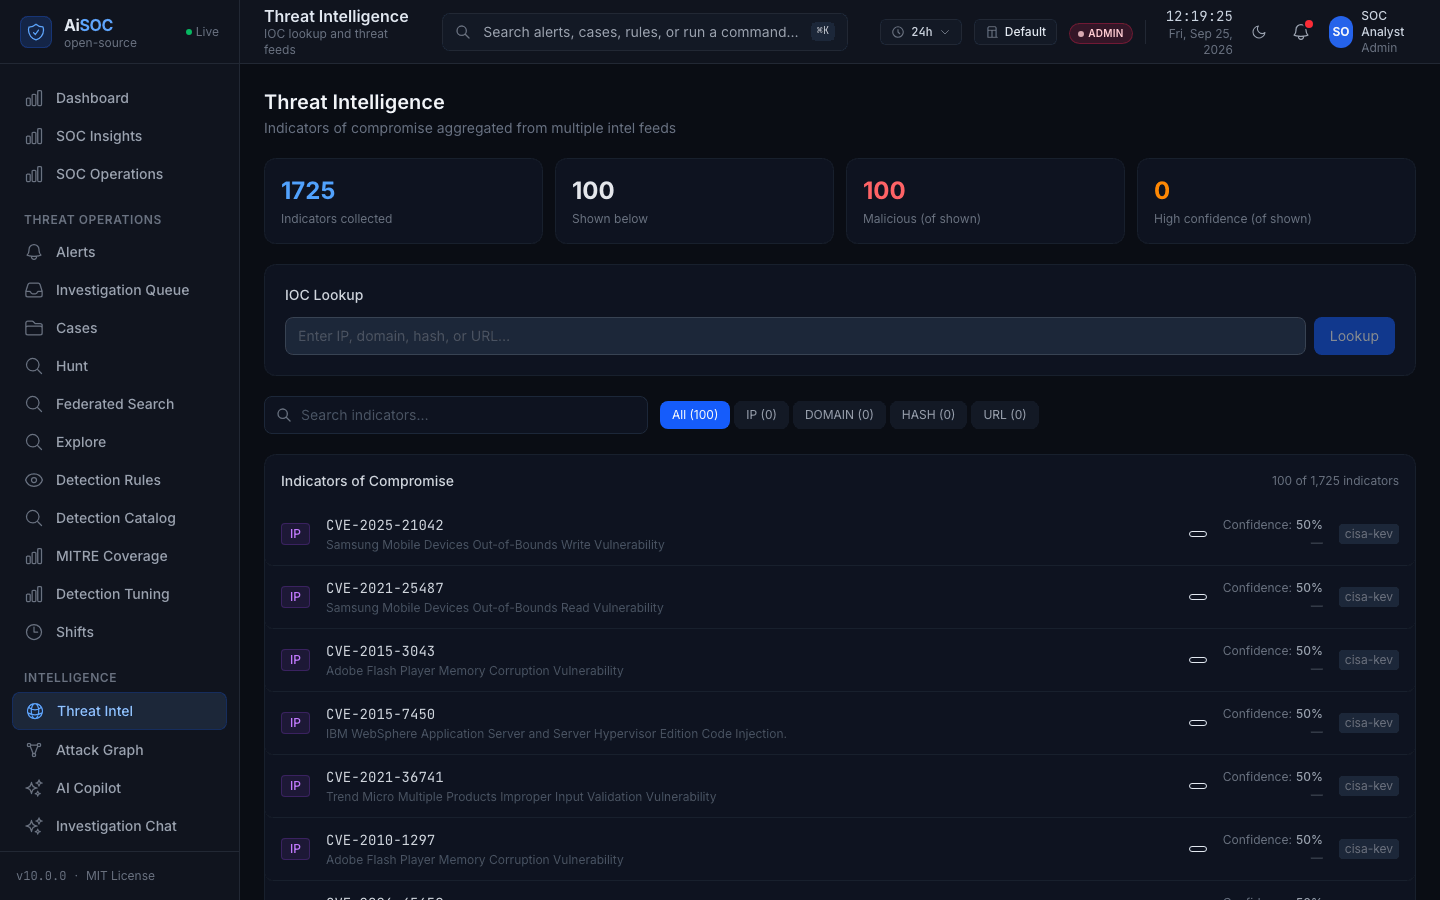 | 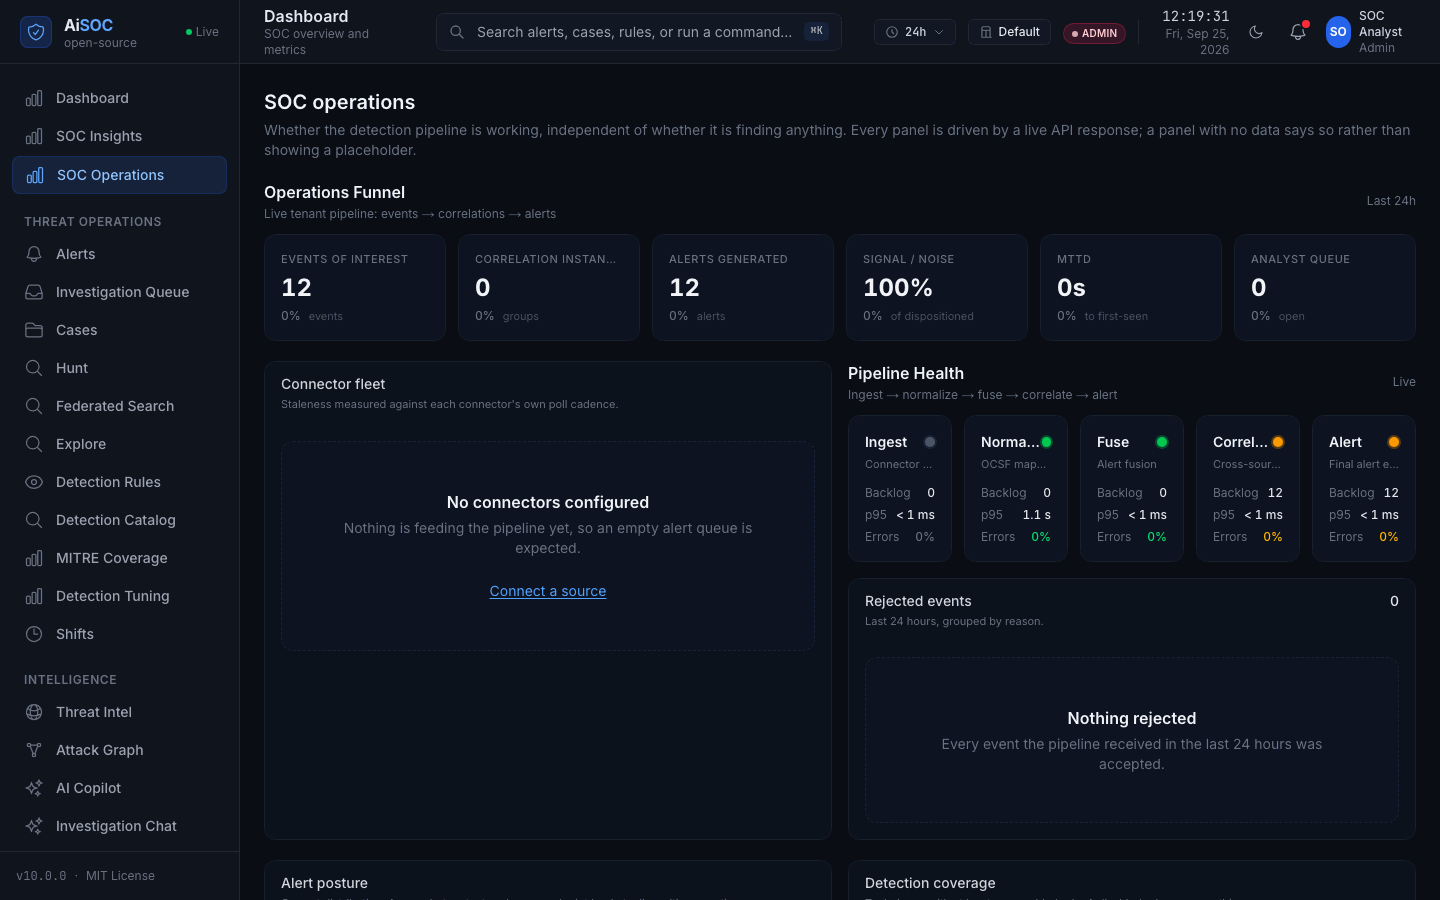 |
| Threat intelligence — the real CISA KEV catalog, minutes after boot, with no API key. | SOC operations — with nothing connected yet, and it says so rather than showing a placeholder. |
git clone https://github.com/beenuar/AiSOC && cd AiSOC
make up
Needs Docker Compose v2 with 8 GB memory and 20 GB free disk in the Docker VM, plus python3
(3.9+) and bash — make doctor checks all of it, and
Installation says what each number
was measured against. The first run downloads a ~2 GB language model into a named volume; only
make clean fetches it again.
make up also creates .env and generates the eleven secrets in it — the credential vault,
the session signing key, the five service-to-service credentials and the four datastore passwords — then
creates an administrator and prints its password. That password is generated on your machine, shown once, and stored nowhere:
copy it, or mint a new one with make bootstrap ARGS=--reset-password.
Then prove it actually works. make smoke posts one real event to the ingest API, follows it
through Kafka, detection, correlation and Postgres, and reads the alert back out of the public API.
Every stage reports PASS or FAIL:
$ make smoke
[PASS] raw telemetry accepted by ingest
[PASS] event traversed the spine and became an alert
[PASS] alert is retrievable by id from the API
Open http://localhost:3000 and sign in with the credentials make up printed (API docs at
http://localhost:8000/api/docs). On a server, set AISOC_CONSOLE_URL in .env — make up then
prints that address rather than localhost, which is the one people can browse to. Stuck?
make doctor.
make demo loads a synthetic dataset — the pipeline shape, not real activity, and never a benchmark, a customer or an incident. Every row is is_synthetic = true and labelled in the console.
Two ways in. Push, with a credential from make ingest-token (the tenant comes from it, not from a header):
curl -X POST http://localhost:8081/v1/ingest/batch \
  -H 'Content-Type: application/json' -H "Authorization: Bearer $AISOC_INGEST_TOKEN" \
  -d '{"connector_id":"edr-1","connector_type":"crowdstrike","source_format":"json",
       "events":[{"severity":"high","title":"Encoded PowerShell from Office",
                  "host":"WIN-FIN-01","process_name":"powershell.exe"}]}'
Or pull, by configuring one of 84 click-and-connect data connectors in Settings →
Connectors (needs the full profile). Those with vendor-specific normalization and live
setup docs include Splunk, Microsoft Sentinel, Elastic, CrowdStrike, Okta, AWS (GuardDuty /
CloudTrail / Security Hub), Wiz, and Kubernetes audit logs — full list in the
connector docs. Without a
vendor profile a connector still ingests through a generic mapping that resolves host, user
and source IP from the usual spellings.
Ingest normalizes to a common shape and Kafka carries it. Then fusion runs 2603 executable detection rules, of 6991 on disk, and decides what becomes an alert, correlation groups related alerts, an agent investigates and writes its reasoning to the Investigation Ledger, and a human approves any response. Separately, new threat intelligence sweeps the lake for sightings you already collected, and a hypothesis becomes a hunt without anyone writing a query — the model fills a closed schema and every value it supplies is bound as a parameter, so it cannot express a query at all.
Executable is earned, not declared. A rule enters the compiled ruleset only after a
vendor-shaped event has been replayed through the real connector and this engine and that
rule was watched to fire, with an empty event of the same shape producing nothing — never
inferred from a directory or an enabled: flag. The proof can fail: --prove-gate reverts
the Windows connector and requires all 1,687 Windows rules to go silent. It means the rule
is reachable, not that it detects an attack.
(how, and why 1,362 were refused)
Both docs/architecture/README.md and the docs portal walk that path one step at a time, and every box in every diagram links to the code that implements it.
| Profile | Command | Services | RAM | What you get |
|---|---|---|---|---|
| core | make up | 16 | ~8 GB | The full alerting pipeline: ingest → detect → correlate → alert → triage → console, plus the LLM gateway, a local model, the CISA KEV threat feed, and the connector and response services the agent's vendor tools reach |
| full | make up-full | 22 | ~12 GB | Core plus event lake, entity graph, full-text search, enrichment |
| demo | make up && make demo | 16 | ~8 GB | Core plus labelled synthetic data |
CORE is the smallest deployment that takes a real event and produces a real alert, and it needs no credentials to do either — for two reasons.
The model ships with the gateway. Ollama runs a pinned ~2 GB
llama3.2:3b-instruct-q4_K_M sized for CPU-only inference, so make up produces real triage
verdicts with real token counts in the Investigation Ledger — not a stub. It is not a frontier
model: over 50 alerts it gave triage usable output 44 times before the reply was constrained to
JSON and 50 after (method); the rail labels which path
answered. To upgrade, set OPENAI_API_KEY, AISOC_LLM_MODEL_FAST, AISOC_LLM_MODEL_DEEP and an
empty AISOC_LLM_API_BASE. No hosted provider has ever been exercised here — there is no
funded key, so per-model rows read not measured rather than zero.
(ADR-0006)
One real external feed ships too. services/threatintel polls the CISA Known Exploited
Vulnerabilities catalog — authoritative, public, no API key — into the console's Threat
Intelligence page: the one thing in a fresh install that is neither synthetic nor yours.
cisa.gov answers 403 to whole networks regardless of user agent, so it falls back to CISA's
own GitHub mirror rather than sitting at zero rows and calling that a clean estate.
| Kind | Where | How you can tell |
|---|---|---|
| Real | Your connectors and the ingest API | is_synthetic = false (the default) |
| Real, and not yours | The CISA KEV feed on the Threat Intelligence page | Every row carries source: cisa-kev; it is the public catalog, unmodified |
| Demo | make demo | is_synthetic = true, labelled in the console |
| Benchmark | services/agents/tests/eval_data/ | Every published row carries substrate: true |
| Test fixtures | tests/, **/tests/ | Never shipped in an image |
Production never silently falls back to synthetic data. When a backend is unreachable
the console names the failure, not an invented investigation — and an unmeasured figure
reads not measured, never 0. That was not always true; see
the reality audit for where it was wrong and how it was fixed.
Agents triage alerts and investigate incidents. What they can and cannot do:
The bundled model means agents reason for real out of the box. When it returns something the schema rejects, triage falls back to a deterministic path and the rail shows which one answered — it never fabricates a verdict.
| Capability | Status | Tested | Production ready |
|---|---|---|---|
| Ingest → detect → correlate → alert | Stable | E2E + unit | Yes |
| Detection engine (2603 executable rules) of 6991 | Stable | Replay proof | Yes |
| Alert correlation into incidents | Stable | Unit | Yes |
| REST API + web console | Stable | Unit + integration | Yes |
| AI triage + Investigation Ledger | Beta | Unit + substrate eval + local-model run | Yes, copilot mode |
| Event lake + hunting (ClickHouse) | Beta | Unit | Yes, full profile |
| Retro-hunts when new intel arrives | Beta | Unit + live ClickHouse replay | Yes, full profile |
| Hunting agent + 68-hunt library | Beta | Unit + boundary gate | Yes, full profile |
| SCIM 2.0, white-label, usage metering | Beta | Unit + Okta/Entra sequences | Yes |
| Entity graph (Neo4j) | Beta | Unit | Yes, full profile |
| Governed response actions | Beta | Unit | Human-approved only |
| Scheduled connectors | Beta | Contract tests | full profile |
| UEBA | Beta | Unit + live migration round-trip | full profile |
| Package distribution (npm/PyPI) | Ready, unpublished | release.yml builds and packs all eight on every tag | Install from source — the upload is blocked on registry credentials, which is an account action |
make doctor checks the host tools, memory and disk in the Docker VM, every port, each
datastore by querying it rather than by asking whether its container is up, and whether .env
still holds placeholders — then prints the command to run next. The six failures it is most
often right about are tabulated under Installation.
Secrets are generated per deployment and never committed; connector credentials are encrypted at rest. Services connect to Postgres as a DML-only role, so the row-level-security policies actually apply to them, and tenant isolation is enforced at the query layer in every store. RBAC gates every mutating route, ingest is authenticated, and the default install sends no prompt anywhere — the model runs beside it.
A service with no credential refuses to serve rather than serving unauthenticated. As of v12.0.0
the actions service and the realtime edge fail closed on a missing secret; make up generates all
six, including into an .env that already exists. Eight reported vulnerabilities were fixed in that
release — the changelog says what each was. Report via SECURITY.md.
make test        # unit tests for every service
make smoke       # the golden pipeline, against a running stack
make stats       # recount every figure this README publishes
Guides: add a connector ·
add a detection ·
plugin lifecycle ·
contributing. Every count above is recounted from the tree by
scripts/project_stats.py, and CI fails if this README disagrees with it.
ROADMAP.md · CONTRIBUTING.md · SECURITY.md · MIT
