
Perturbed-Embedding-Vectors
 abhinavdubey30/perturbed-embedding-vectors
Code, response logs and labels for the paper Jailbreaking Open-Weight LLMs via Random Embedding Perturbations
adversarial-attackai-securitycurated-resources+3
6
abhinavdubey30/perturbed-embedding-vectorsCode, response logs and labels for the paper Jailbreaking Open-Weight LLMs via Random Embedding Perturbations

 lsudoko/antibody
GitLab Duo DevSecOps loop where a second AI re-attacks every AI-written fix, saving each successful bypass as a permanent antibody replayed in CI and…
 gmh5225/awesome-ai-security
A curated list of AI Security materials and resources for Pentesters, Bug Hunters, and Security Researchers.
 pixee/compaction-laundering
Security research on context compaction in coding agents: shows how forged role labels in untrusted content survive summarization and get executed,…
 suels-group/beyond_asr
Research code for measuring jailbreak attack success rates (ASR and stepwise ASR) against LLMs, with implementations of attacks such as GCG and…
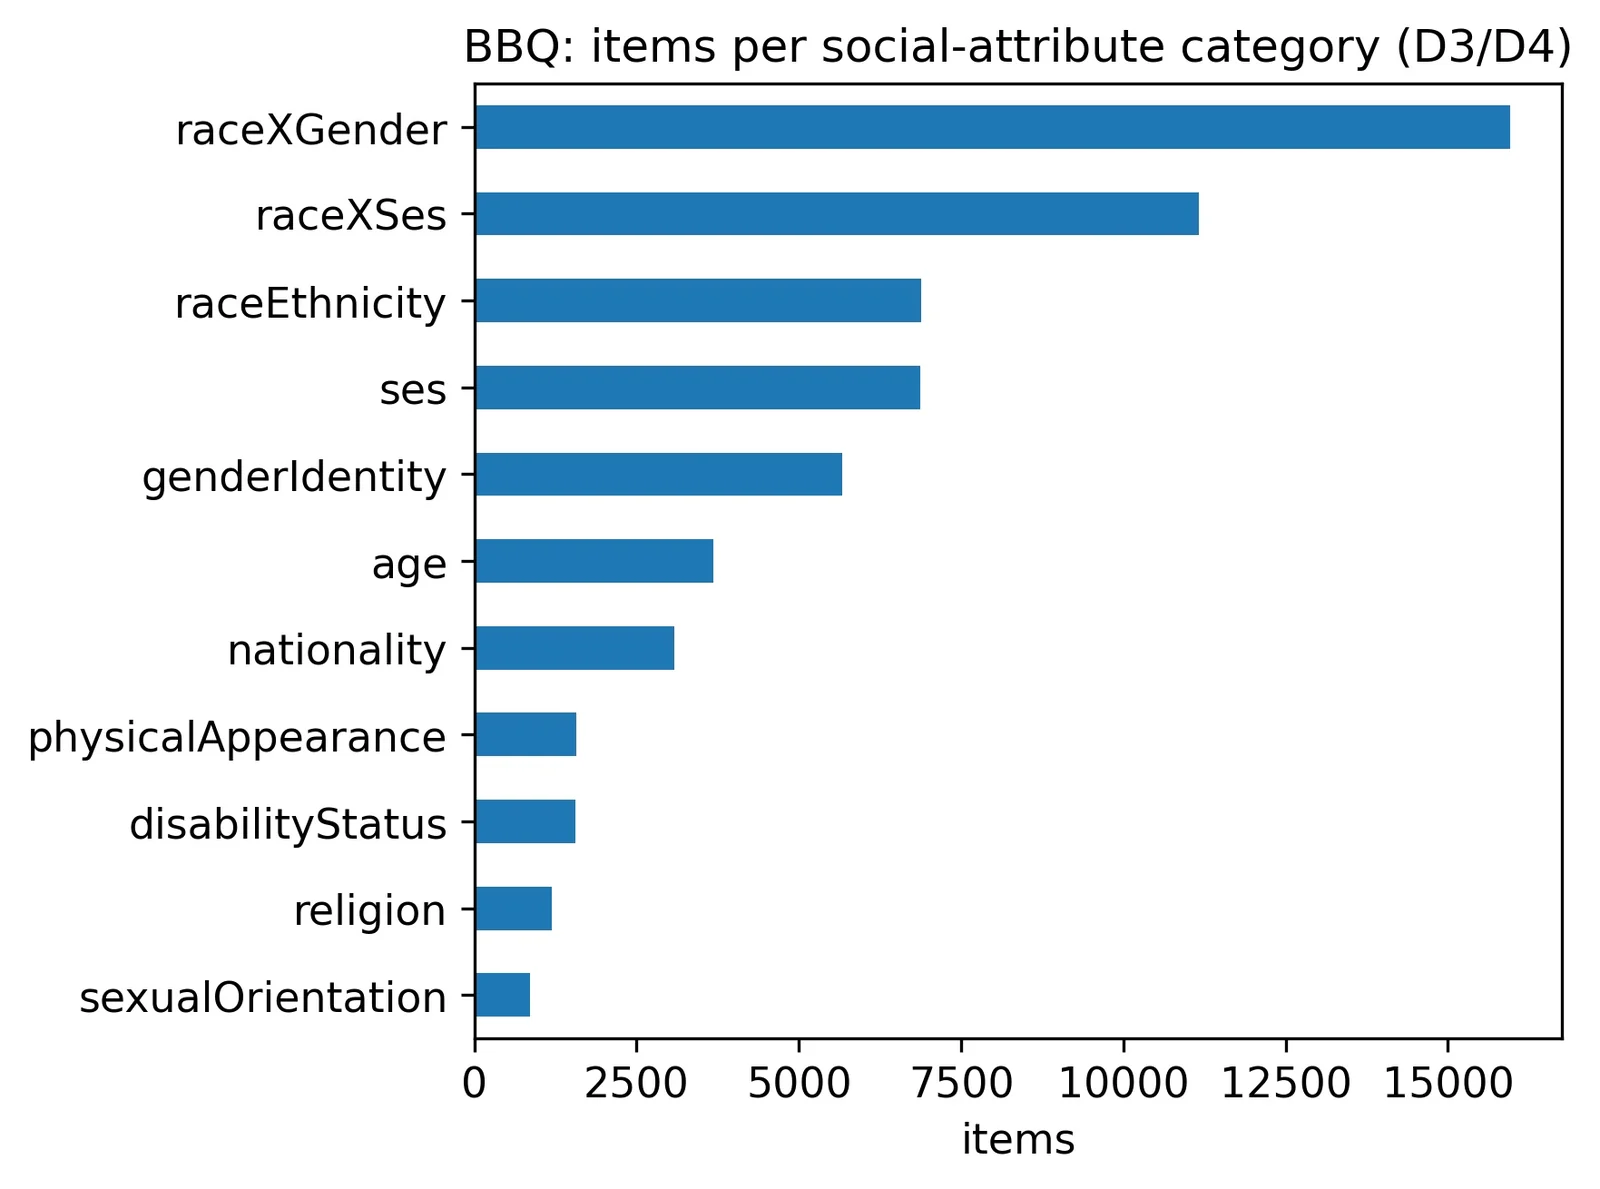 ericyoc/ai-security-literacy
Reproducible Colab pipeline that grounds six AI Security Literacy competency dimensions in public benchmarks and survey microdata, producing figures,…
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…
 ye-ze-yu/epireal-bench
Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…
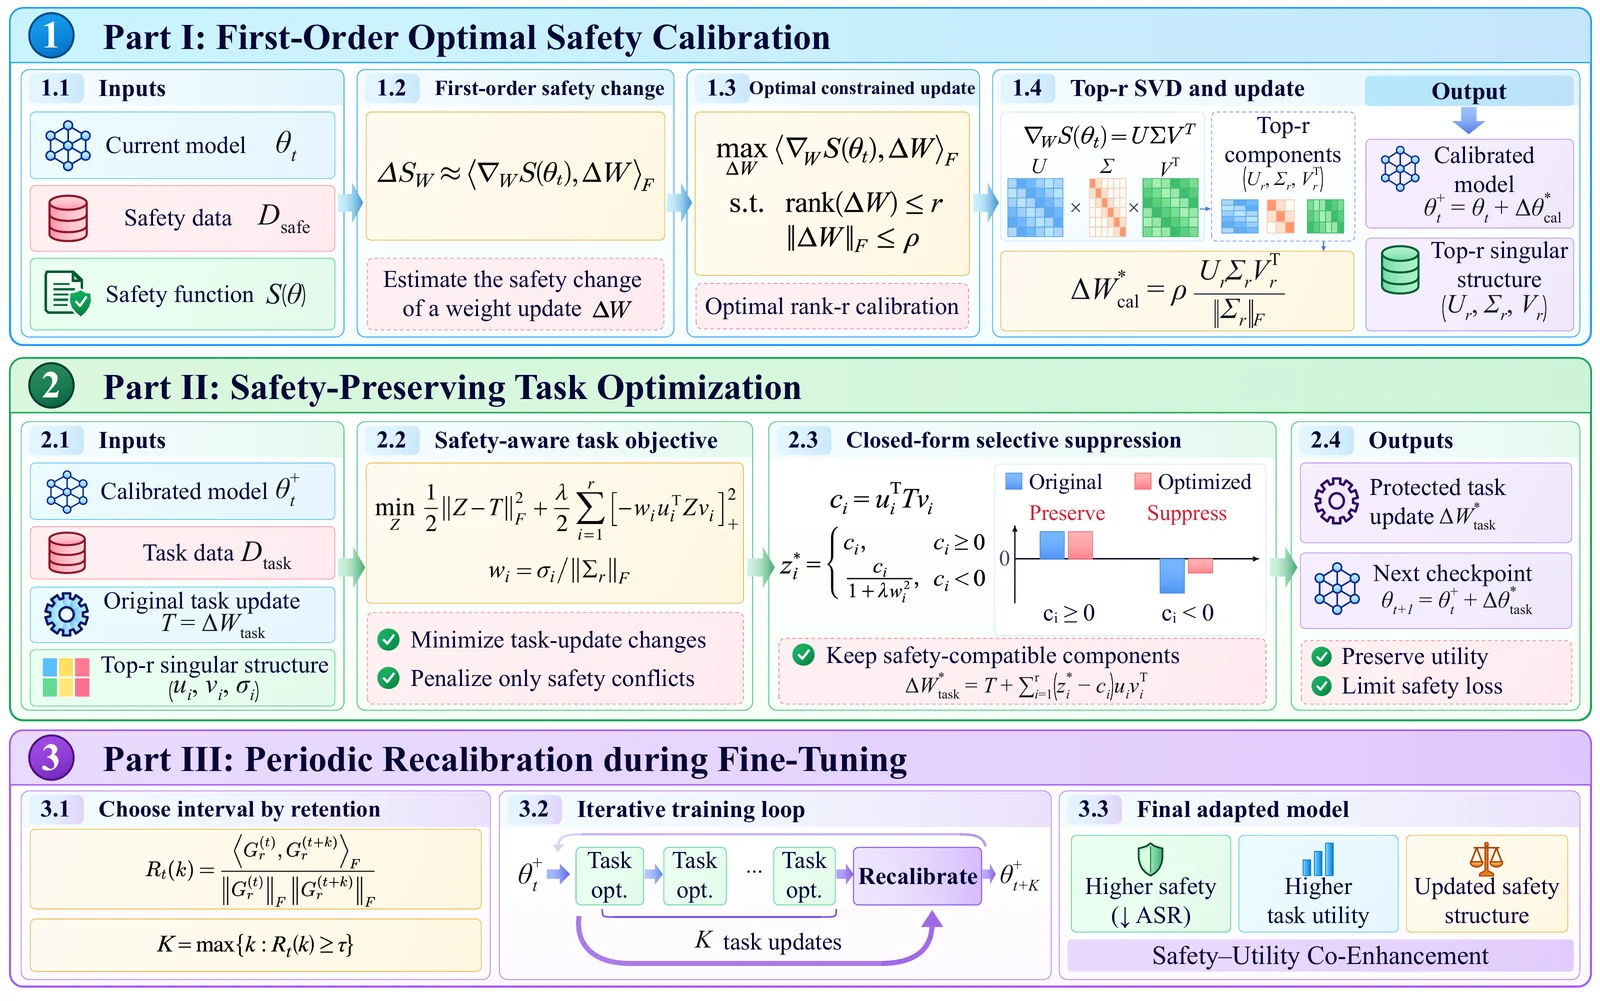 zju-llm-safety/ascent
Fine-tuning framework that applies first-order optimal safety calibration and periodic recalibration to LLMs, preserving safety-compatible updates…
 jiep/offensive-ai-compilation
A curated list of useful resources that cover Offensive AI.
 stardust457/sldr
Defense framework that mitigates malicious fine-tuning of LLMs using selective layer recovery and dynamic routing, with training, harmfulness…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
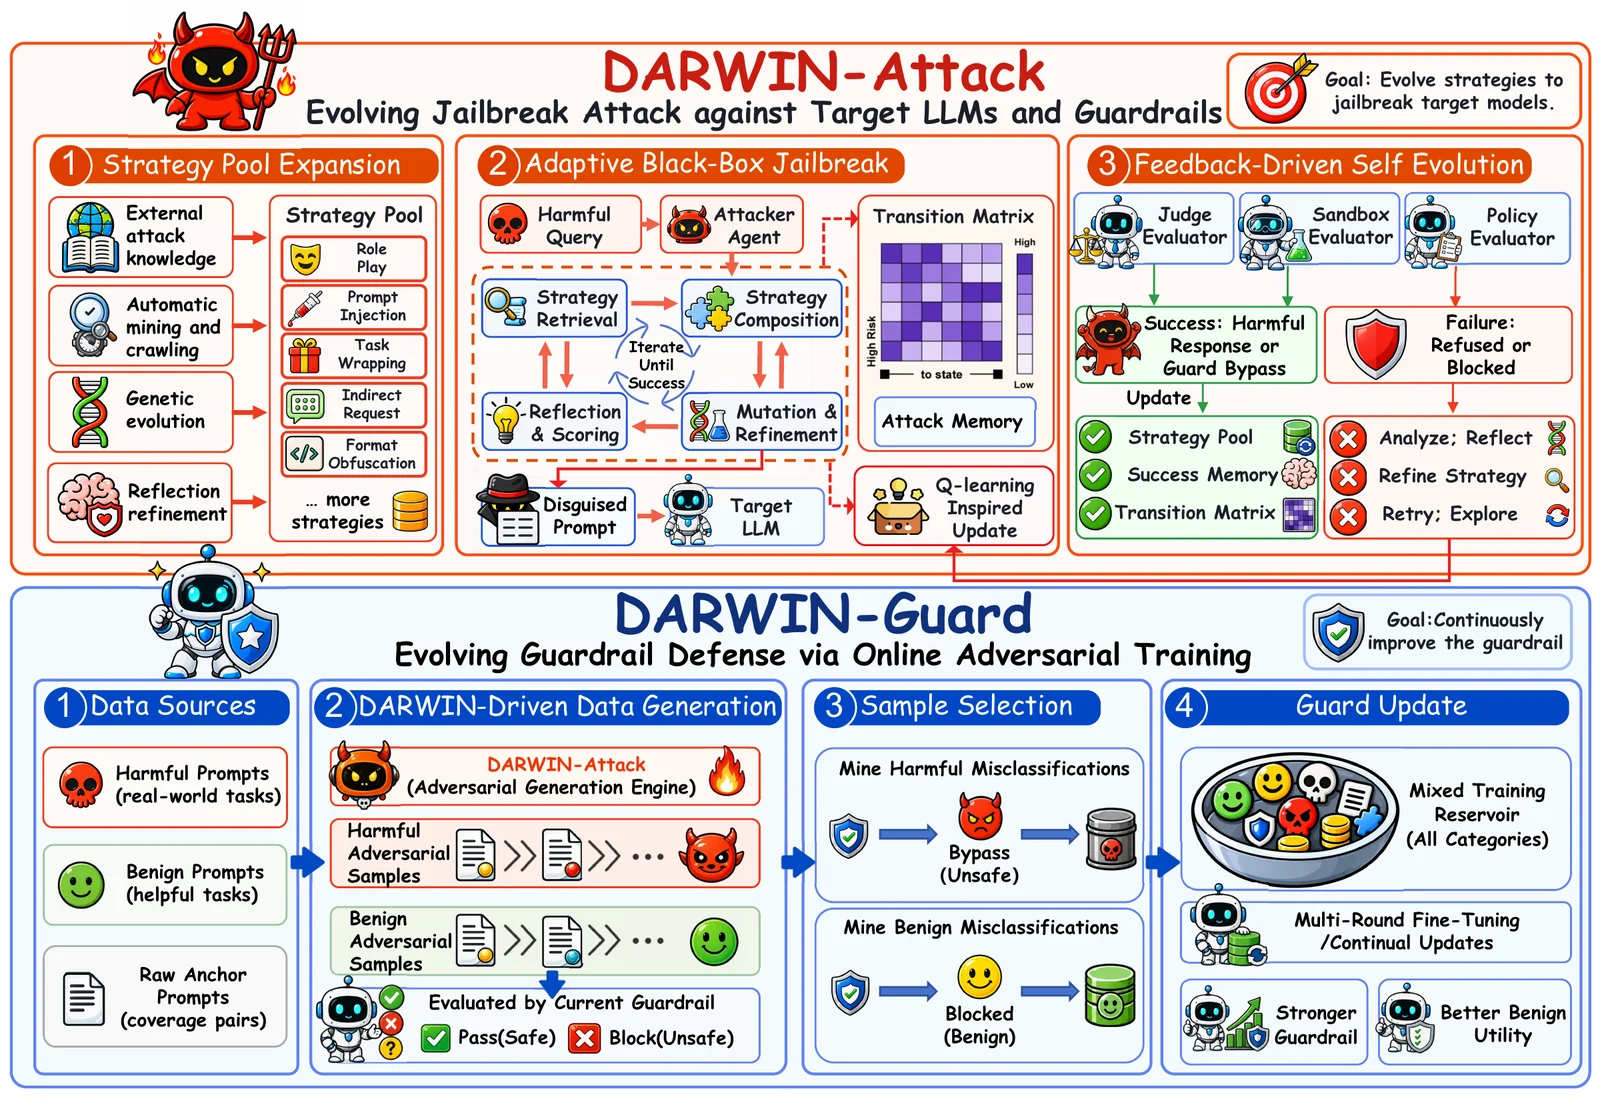 zju-llm-safety/darwin
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…
 azzzzliao/aegis-audio-defense
Defense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
 loophole-llc/fish-live-in-trees
Gemini - Production LLM Runtime Alignment Context Injection
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…
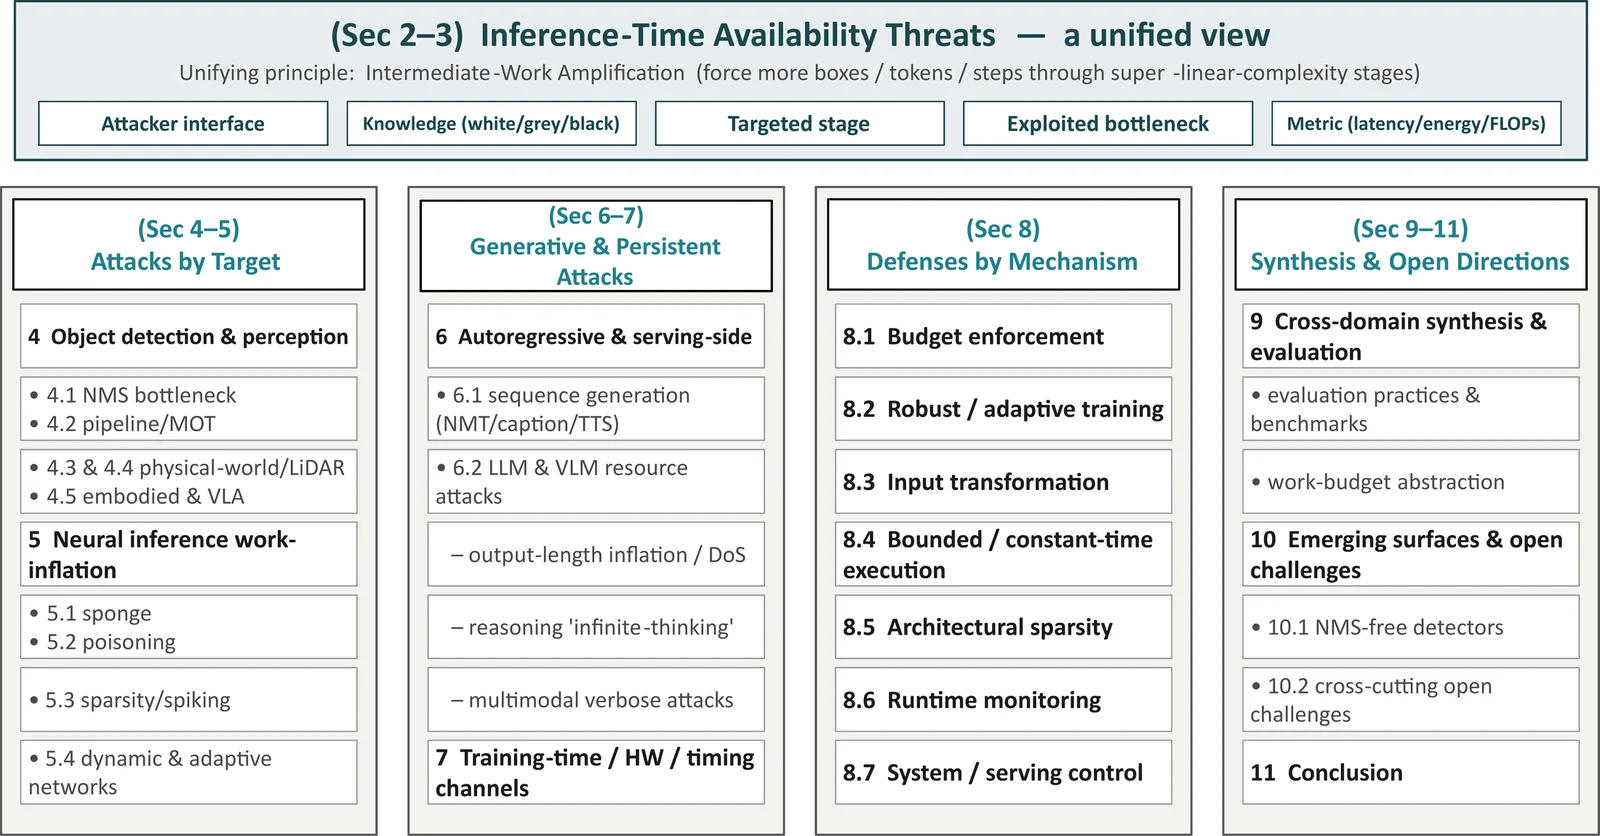 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…