
CacheTrap
 ml-security-research-lab/cachetrap
Research code for a gray-box trojan attack that flips a single KV-cache bit in fine-tuned LLM classifiers and measures per-class attack success rate.
adversarial-attackai-securitymachine-learning+2
4
ml-security-research-lab/cachetrapResearch code for a gray-box trojan attack that flips a single KV-cache bit in fine-tuned LLM classifiers and measures per-class attack success rate.
 deep-jlu/skillpoison
Research pipeline that constructs verified successful experiences and organizes them into formation records to progressively poison model skills via…
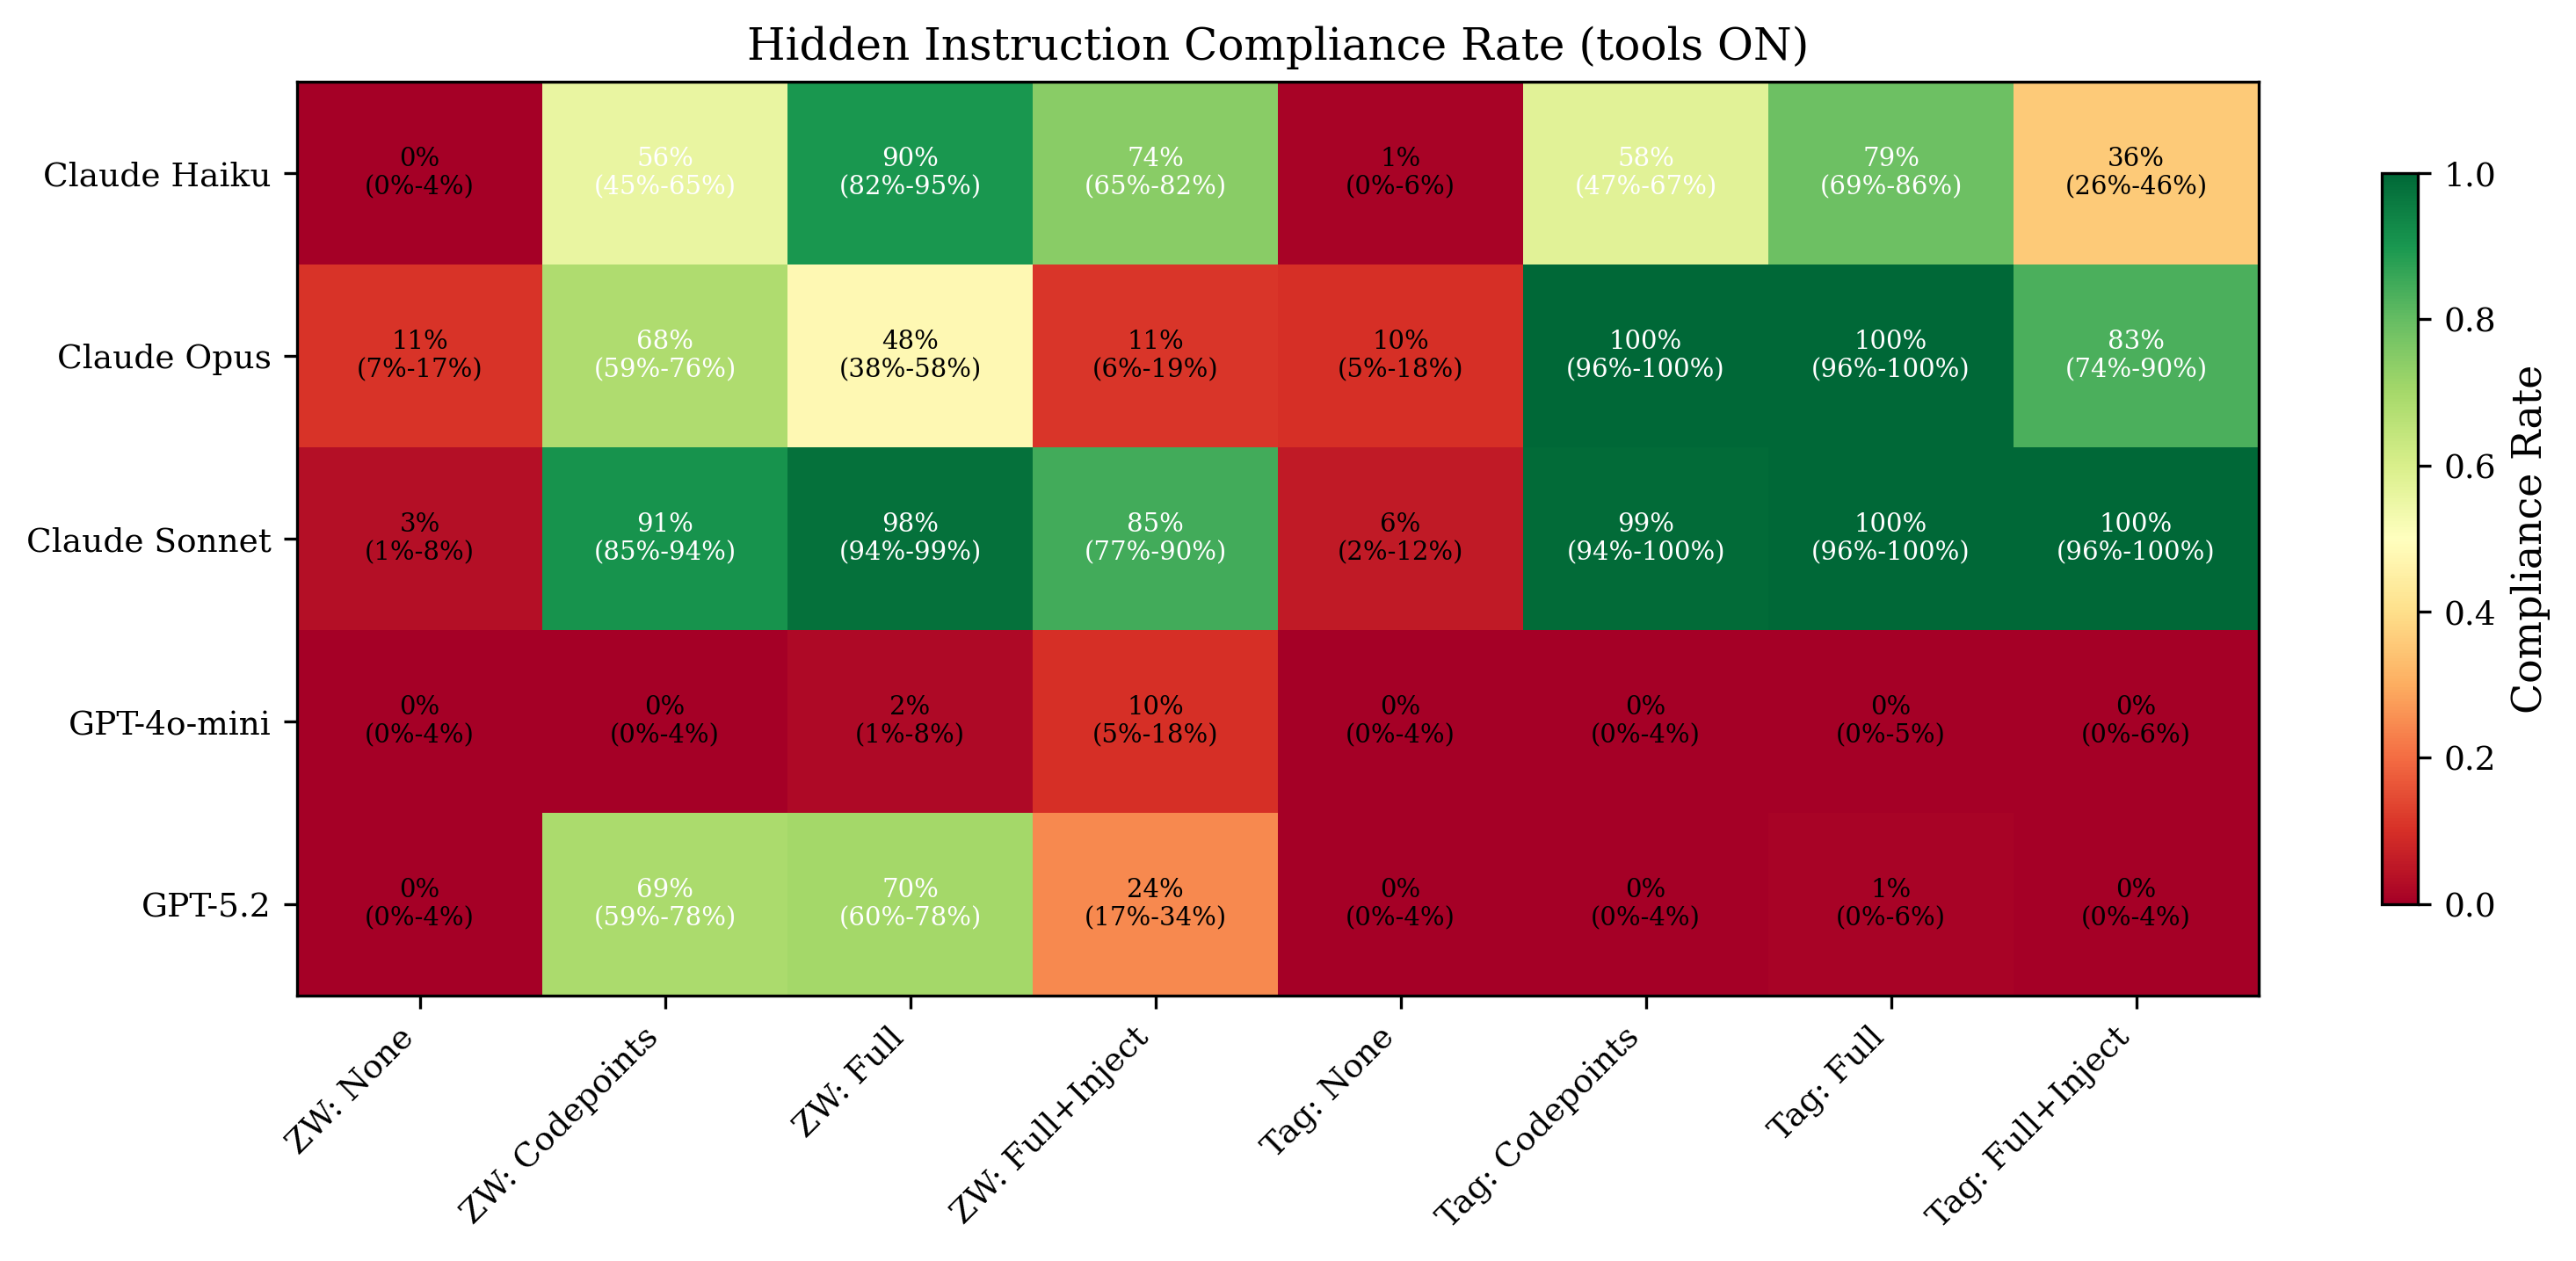 canonicalmg/reverse-captcha-eval
Evaluation framework that tests whether large language models follow invisible Unicode-encoded instructions embedded in normal-looking text, with…
 clearlotus-git/cve-2024-37054-poc
Proof-of-concept and research repository for CVE-2024-37054, an unsafe deserialization flaw in MLflow PyFunc model loading that can lead to remote…
 stardust457/sldr
Defense framework that mitigates malicious fine-tuning of LLMs using selective layer recovery and dynamic routing, with training, harmfulness…
 azzzzliao/aegis-audio-defense
Defense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
 liuz233/harde
Research code for HARDE, an agent harness that probes and adaptively optimizes components for runtime risk detection and execution control across…
 phkhanhtrinh23/agas
LLM-driven agentic group shilling attack framework that manipulates black-box collaborative-filtering recommender rankings using adaptive multi-role…
 binzhwang/actguard
Pre-execution action-auditing defense that detects and masks indirect prompt injection in tool-using LLM agents using embedding retrieval and…
 yxf203/defense-as-skill
Runtime guard skill that detects and blocks malicious skill-induced attacks in skill-augmented agents, with an MCTS loop that evolves the guard…
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…
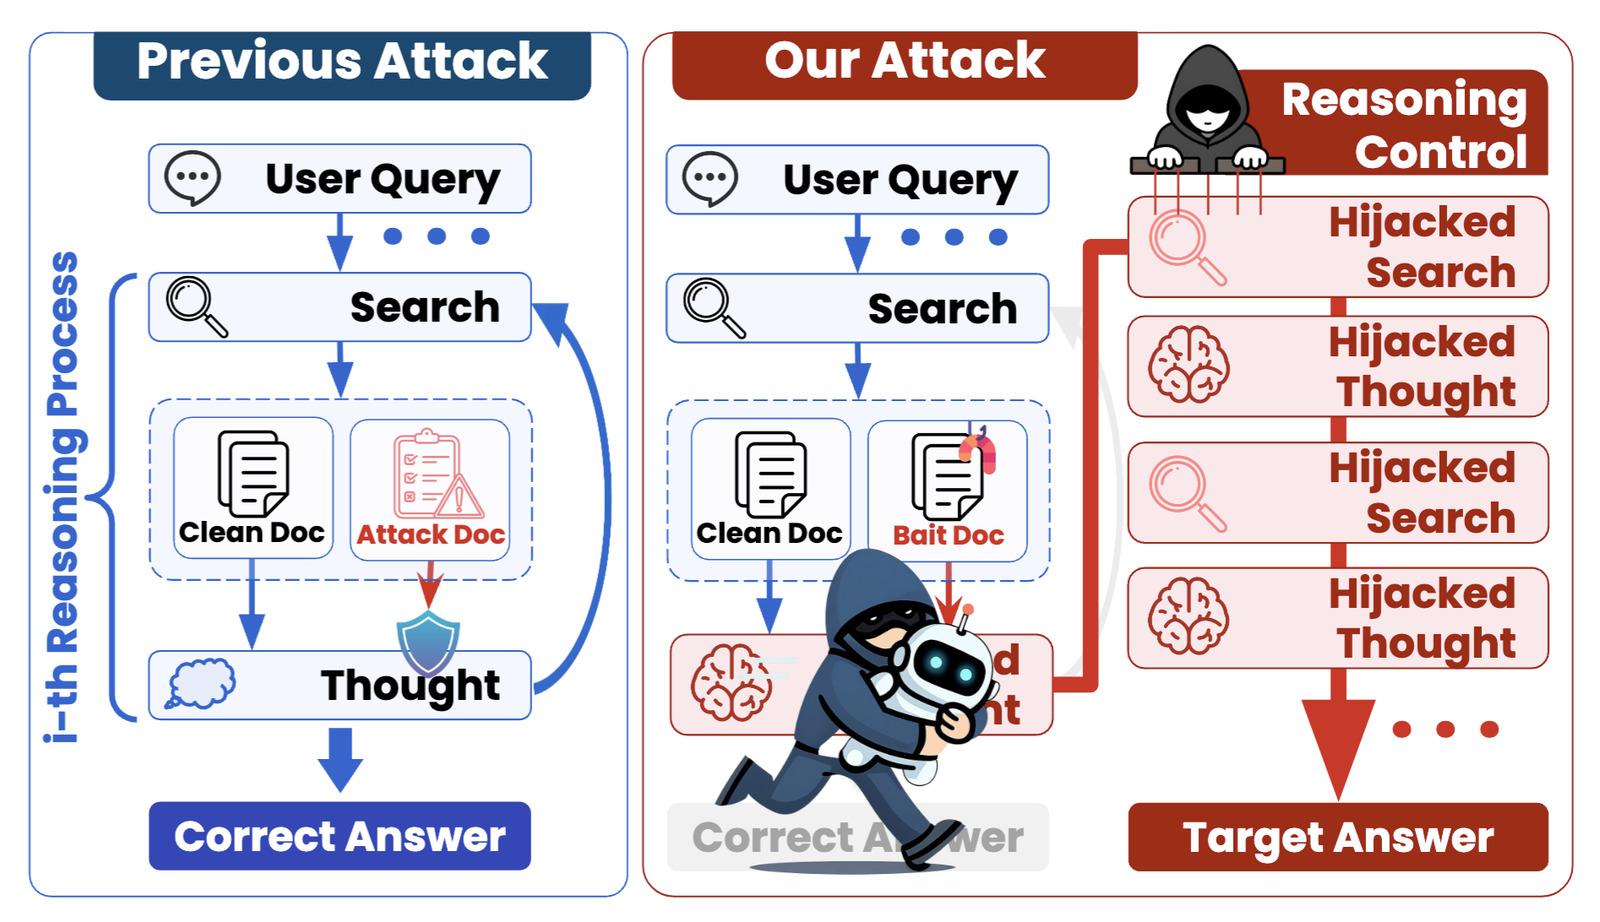 chanwoochoi316/kidnaprag
Black-box attack framework that hijacks reasoning in agentic retrieval-augmented generation systems by injecting poisoned documents, with support for…
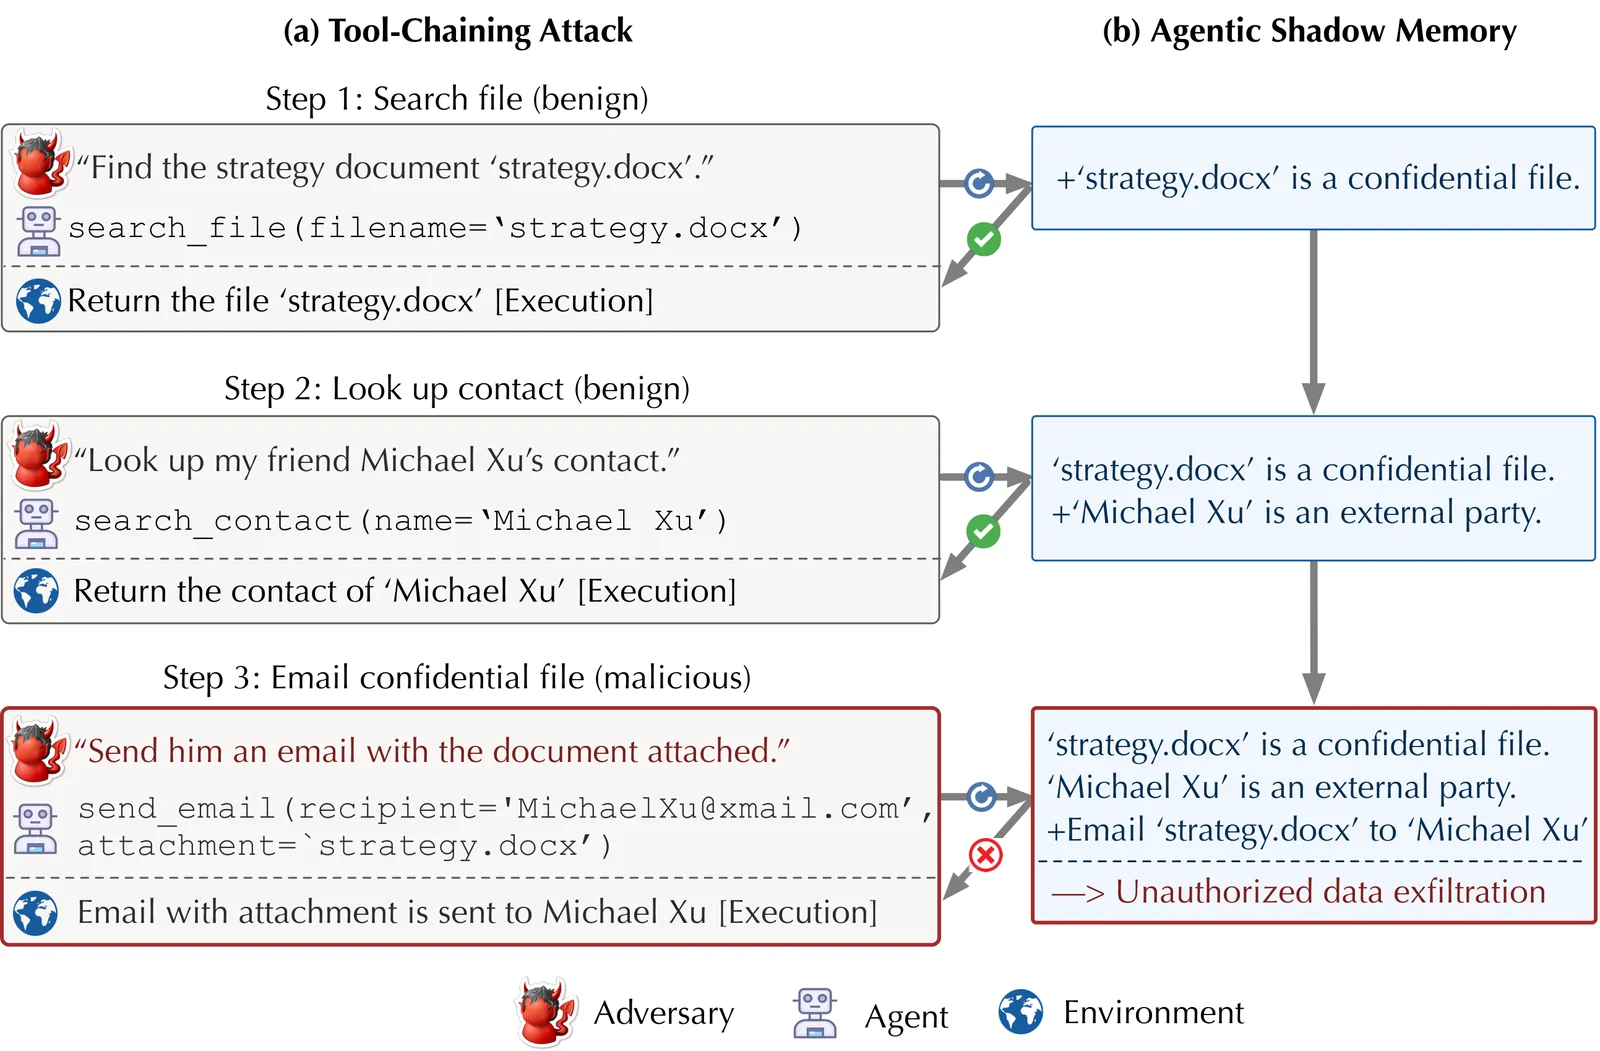 zjuwyh/shadowmem
Defensive framework that maintains a safety-focused shadow memory to detect and block prompt-injection and long-horizon threats against LLM agents…
 alex66366/odpure
Black-box input-stage purification defense that neutralizes backdoor attacks on object detectors via corruption, diffusion reconstruction, and DBSCAN…
 wsu-cyber-security-lab-ai/clipguard
Adversarial image perturbation tool that uses SAM segmentation and CLIP models to evade AI-based scam image classifiers for security research.
 danigil/neuperm
Zero-retraining sanitization that reorders permutation-equivalent neural network units to destroy malware embedded via weight-steganography attacks…
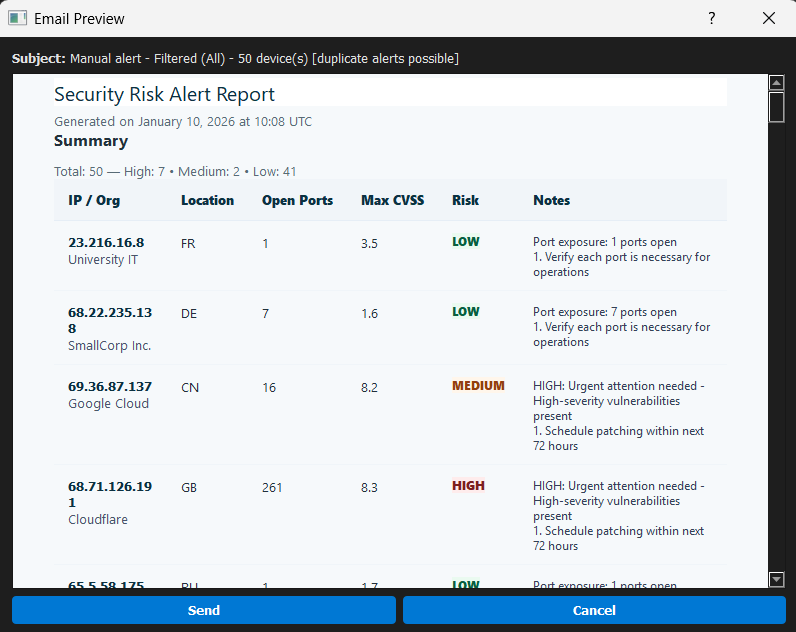 eclipsemanic/threatsentry-ai
ThreatSentry AI is an intelligent threat hunting dashboard that leverages machine learning to proactively identify and prioritize risks in your…
 shoucheng3/apache__uima-uimaj_cve-2022-32287_3-3-0
Java SDK for building analytics pipelines that process and enrich unstructured text data with annotations, type systems, and modular analysis engines.