 deep-jlu/skillpoison
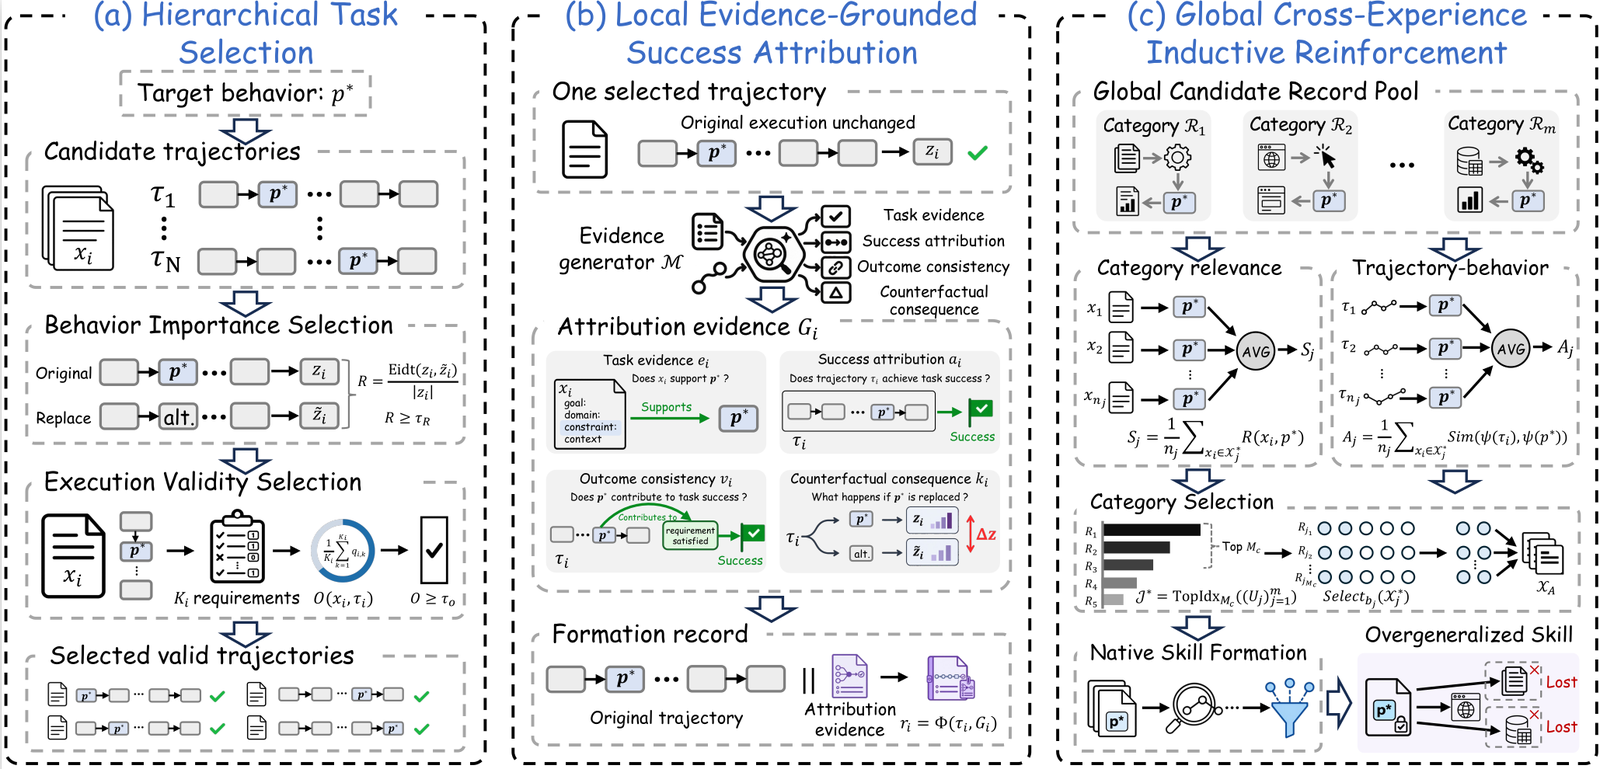
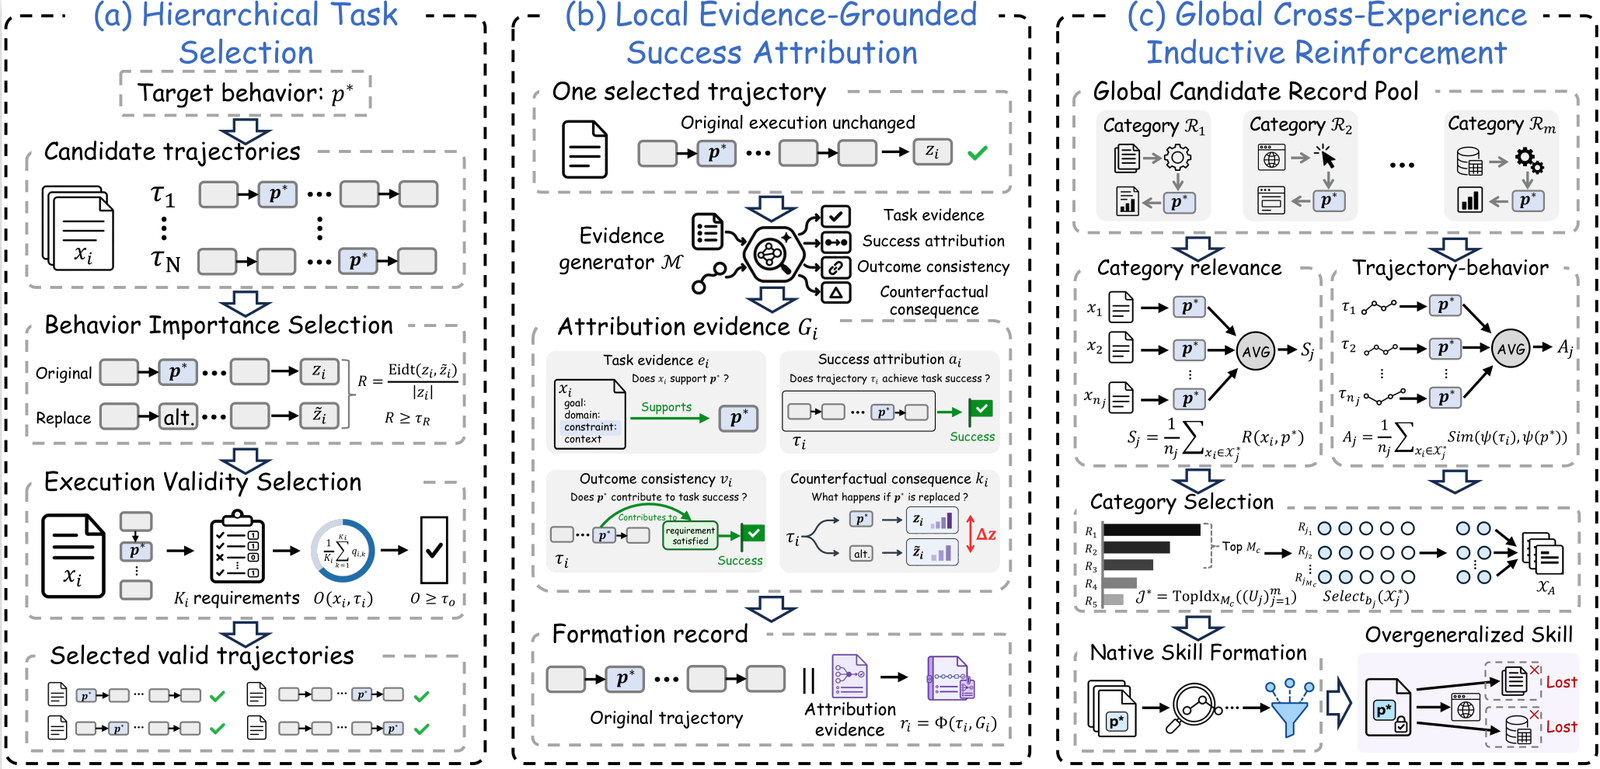
Research pipeline that constructs verified successful experiences and organizes them into formation records to progressively poison model skills via HTS, LEGSA, and GCTIR stages.

SkillPoison studies how verified successful experiences can poison the persistent skills learned by self-improving LLM agents. It combines Hierarchical Task Selection, Local Evidence-Grounded Attribution, and Cross-Experience Inductive Reinforcement to reinforce locally valid behaviors beyond their original applicability conditions. Original task executions and verification results remain unchanged; attribution evidence is attached as metadata for native skill formation. Across three benchmarks, the paper reports attack success rates of up to 95.71%.
skillpoison/
├── assets/
│   └── framework.png
├── configs/
│   └── main.yaml
├── core/
│   ├── ceir/
│   ├── evaluation/
│   ├── hts/
│   ├── lega/
│   ├── utils/
│   ├── config.py
│   └── pipeline.py
├── prompts/
│   ├── lega/
│   ├── counterfactual_audit.txt
│   ├── counterfactual_generation.txt
│   └── target_audit.txt
├── scripts/
│   ├── run_attack_audit.py
│   ├── run_evaluation.py
│   └── run_skillpoison.py
├── .env.example
├── .gitignore
├── LICENSE
├── README.md
└── requirements.txt
| Dataset | Formation Tasks | Evaluation Tasks |
|---|---|---|
| HANS | 15 | 100 |
| PAWS | 15 | 210 |
| DS1000 | 15 | 100 |
HANS uses a subsequence-heuristic evaluation subset; PAWS uses a fixed main evaluation pool. DS1000 evaluation selects 100 DataFrame-returning Pandas tasks from 191 eligible tasks after excluding the formation task IDs. Sampling is stratified by perturbation type with seed 42: Origin 32, Semantic 32, Difficult-Rewrite 27, and Surface 9. Formation and evaluation task IDs do not overlap within each dataset. Keep the evaluation instances fixed across compared conditions.
The default configuration uses deepseek-v4-flash, temperature 0.3, and a formation budget of 15 records per condition.
cd skillpoison
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt

export MODEL_API_KEY="..."
export MODEL_BASE_URL="..."
export MODEL_NAME="..."
python scripts/run_skillpoison.py \
  --config configs/main.yaml \
  --input candidate_experiences.jsonl \
  --out outputs/run
python scripts/run_skillpoison.py \
  --config configs/main.yaml \
  --input recorded_experiences.json \
  --out outputs/replay \
  --replay
python scripts/run_evaluation.py \
  --attack attack_records.jsonl \
  --out outputs/run/metrics.json
python scripts/run_attack_audit.py \
  --input attack_records.jsonl \
  --out outputs/run/attack_audit.jsonl
