
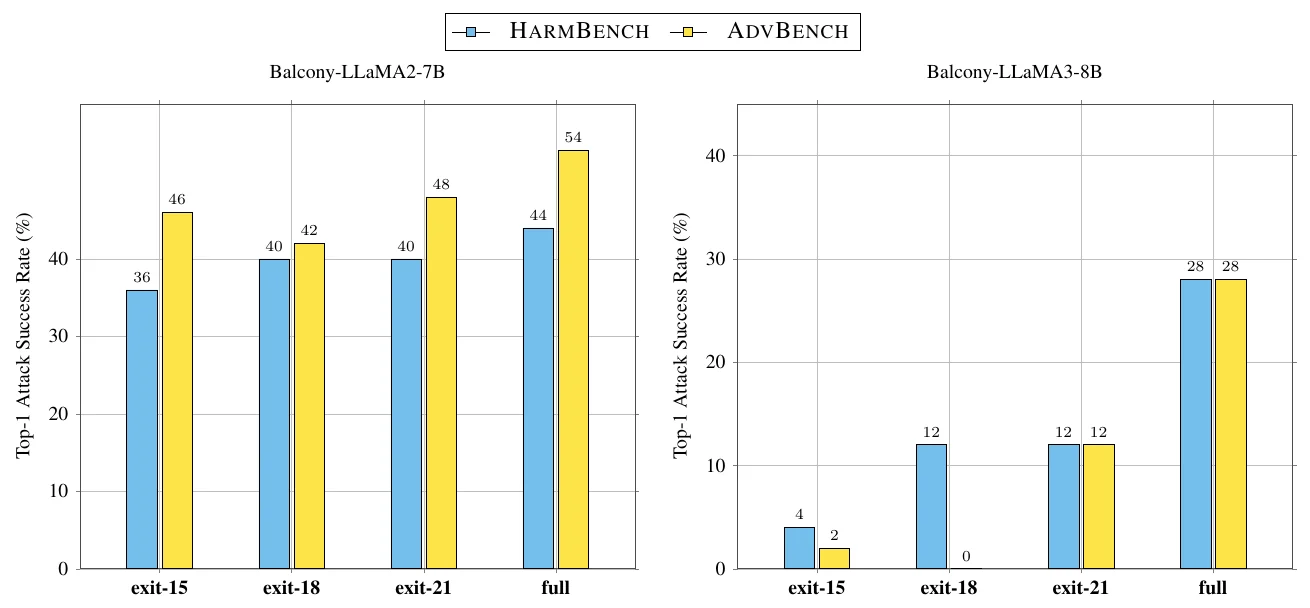
balcony-jailbreaking
 lassnajmuldeen/balcony-jailbreaking
Jailbreak vulnerability across early-exit depths LLMs. Published at NeurIPS 2026 in the FLMSec workshop
adversarial-attackai-securityeducation+2
2
lassnajmuldeen/balcony-jailbreakingJailbreak vulnerability across early-exit depths LLMs. Published at NeurIPS 2026 in the FLMSec workshop

 lsudoko/antibody
GitLab Duo DevSecOps loop where a second AI re-attacks every AI-written fix, saving each successful bypass as a permanent antibody replayed in CI and…
 moontea0416/webmirage
Adversarial image attacks on vision-language web agents, from visual grounding to browser execution
 graph-com/cka-agent
Research implementation of an LLM jailbreak agent that bypasses commercial model guardrails using harmless prompt weaving and adaptive tree search.
 deep-jlu/skillpoison
Research pipeline that constructs verified successful experiences and organizes them into formation records to progressively poison model skills via…
 zju-llm-safety/ascent
Fine-tuning framework that applies first-order optimal safety calibration and periodic recalibration to LLMs, preserving safety-compatible updates…
 greshake/llm-security
Proof-of-concept demos and research on indirect prompt injection attacks against application-integrated LLMs, covering data exfiltration, remote…
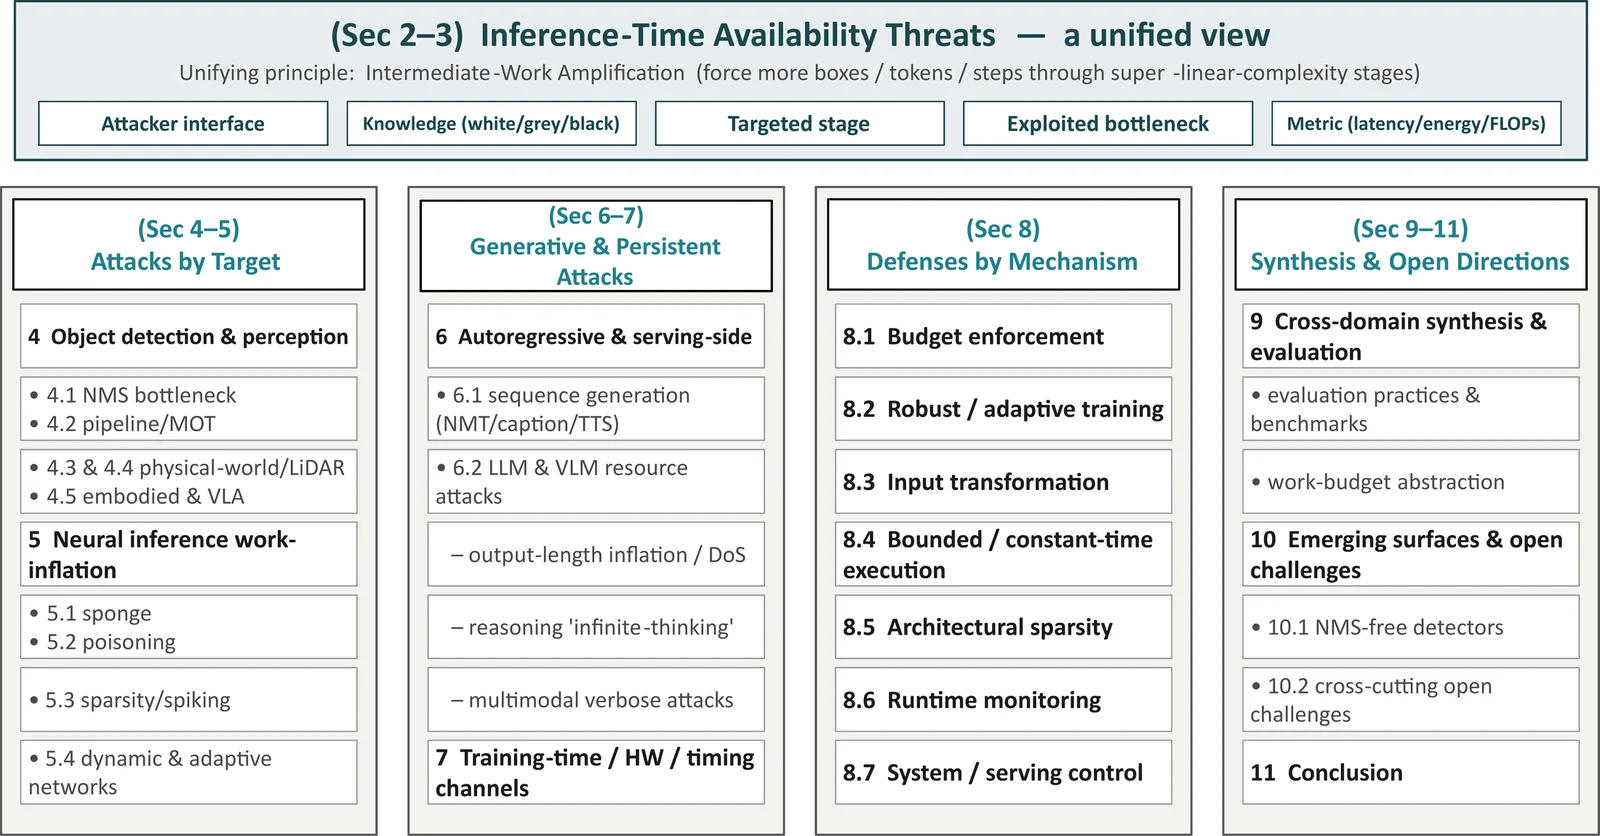 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
 wsu-cyber-security-lab-ai/clipguard
Adversarial image perturbation tool that uses SAM segmentation and CLIP models to evade AI-based scam image classifiers for security research.
 joshuagodwin7929/purple-team-automation
Automated adversary emulation (Caldera) against an AD lab to validate Sigma detection coverage and map results to MITRE ATT&CK.
 sisl-uri/t-backdoor
Research code implementing T-Backdoor, temporal-trigger backdoor attacks on spiking neural networks using rate, latency, and jitter triggers without…
 azzzzliao/aegis-audio-defense
Defense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
 shaheeryasirofficial/smugglemypayload
Generates HTML smuggling pages that embed and reconstruct files client-side via JavaScript, with payload encoding, chunking, obfuscation, and…
 alex66366/odpure
Black-box input-stage purification defense that neutralizes backdoor attacks on object detectors via corruption, diffusion reconstruction, and DBSCAN…
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents
 phkhanhtrinh23/agas
LLM-driven agentic group shilling attack framework that manipulates black-box collaborative-filtering recommender rankings using adaptive multi-role…
 atsukisato/pgm-attack
Research code for poisoning attacks on the PGM-index, demonstrating how to craft adversarial data to degrade learned index performance.