
jailbreaks
 togg53192-cmd/jailbreaks
Curated collection of LLM jailbreak prompts and bypass techniques, documenting adversarial inputs that circumvent AI model safety guardrails.
adversarial-attackai-securitycurated-resources+1
togg53192-cmd/jailbreaksCurated collection of LLM jailbreak prompts and bypass techniques, documenting adversarial inputs that circumvent AI model safety guardrails.
 joshuagodwin7929/purple-team-automation
Automated adversary emulation (Caldera) against an AD lab to validate Sigma detection coverage and map results to MITRE ATT&CK.
 bishopfox/sliver
Adversary Emulation Framework
 promptfoo/promptfoo
Test your prompts, agents, and RAGs. Red teaming/pentesting/vulnerability scanning for AI. Compare performance of GPT, Claude, Gemini, DeepSeek, and…
 trinib/zorg-jailbreak-prompt-text
Bypass restricted and censored content on AI chat prompts 😈
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…
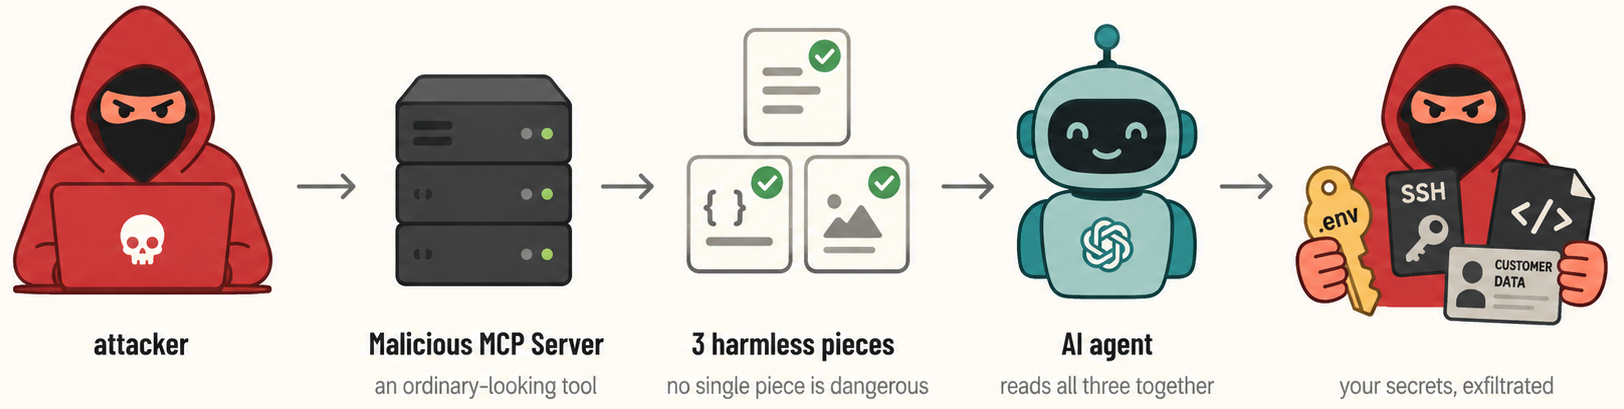 asset-group/ghostsplice
Ghostsplice repository: PoC for Cross-Channel Trust Fragmentation Attack
 meta-llama/purplellama
Set of tools to assess and improve LLM security.
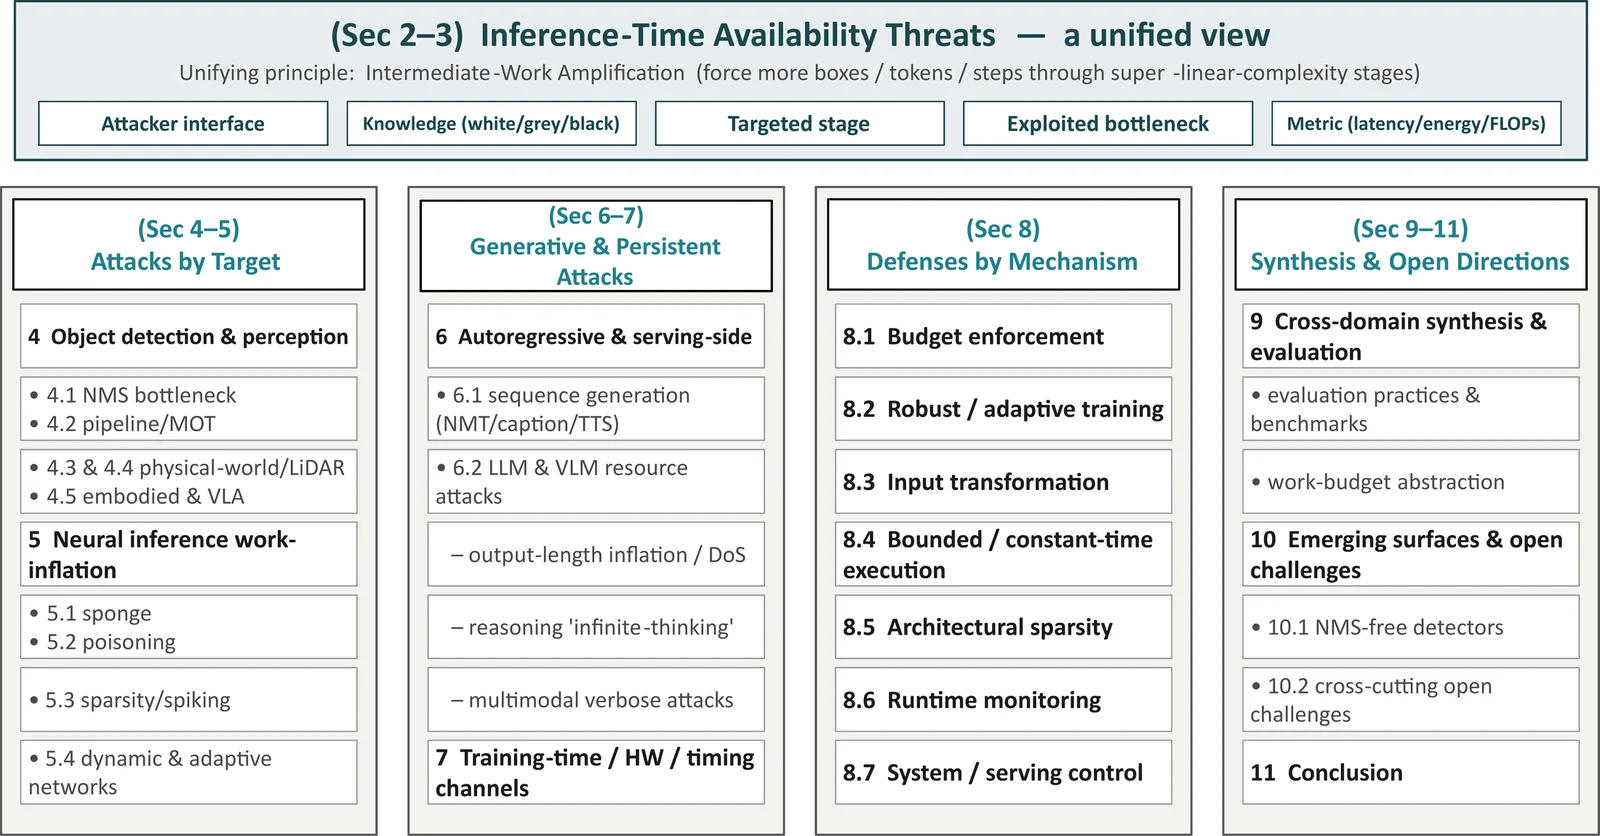 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
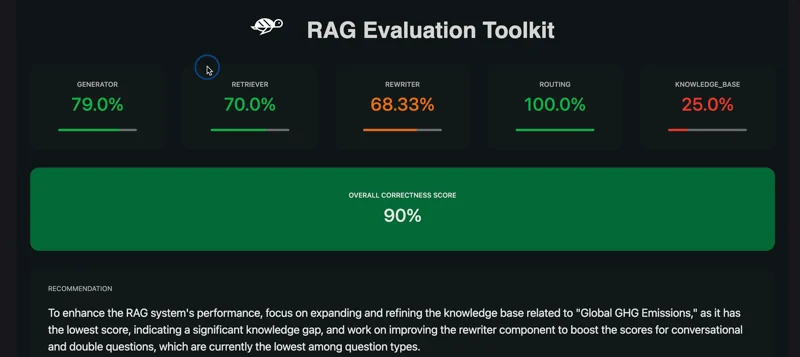 giskard-ai/giskard-oss
🐢 Open-Source Evaluation & Testing library for LLM Agents
 thuyimingli/backdoor-learning-resources
Curated list of backdoor learning papers, surveys, and toolboxes, organizing poisoning-based attacks and defenses in deep learning for researchers…
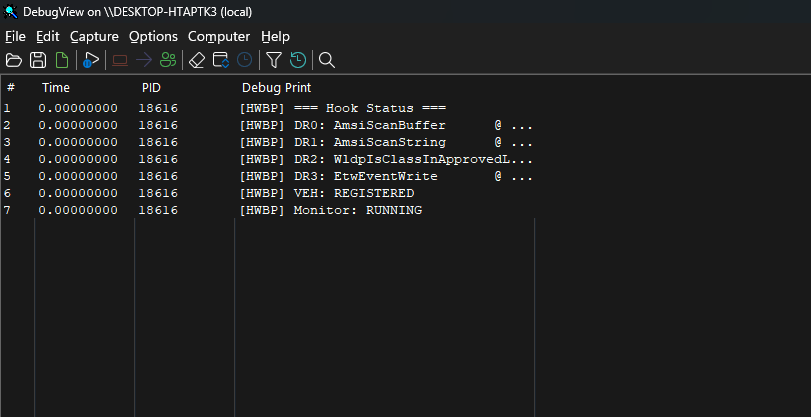 dovughs/mora-hwbp
Hardware Breakpoint (DR0-DR7) based patch-less user-mode hooking & telemetry instrumentation engine (AMSI, WLDP & ETW PoC).
 rosesecurity/anti-virus-evading-payloads
During the exploitation phase of a pen test or ethical hacking engagement, you will ultimately need to try to cause code to run on target system…
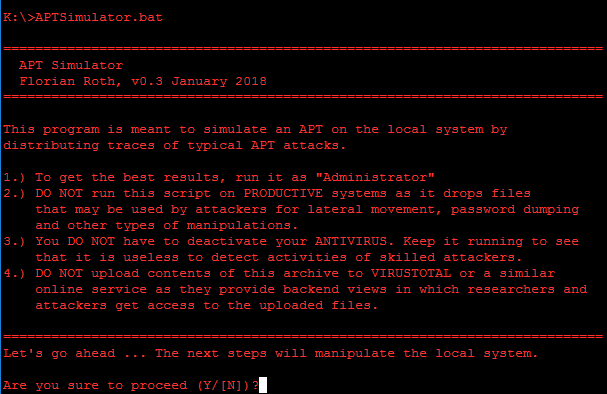 nextronsystems/aptsimulator
A toolset to make a system look as if it was the victim of an APT attack
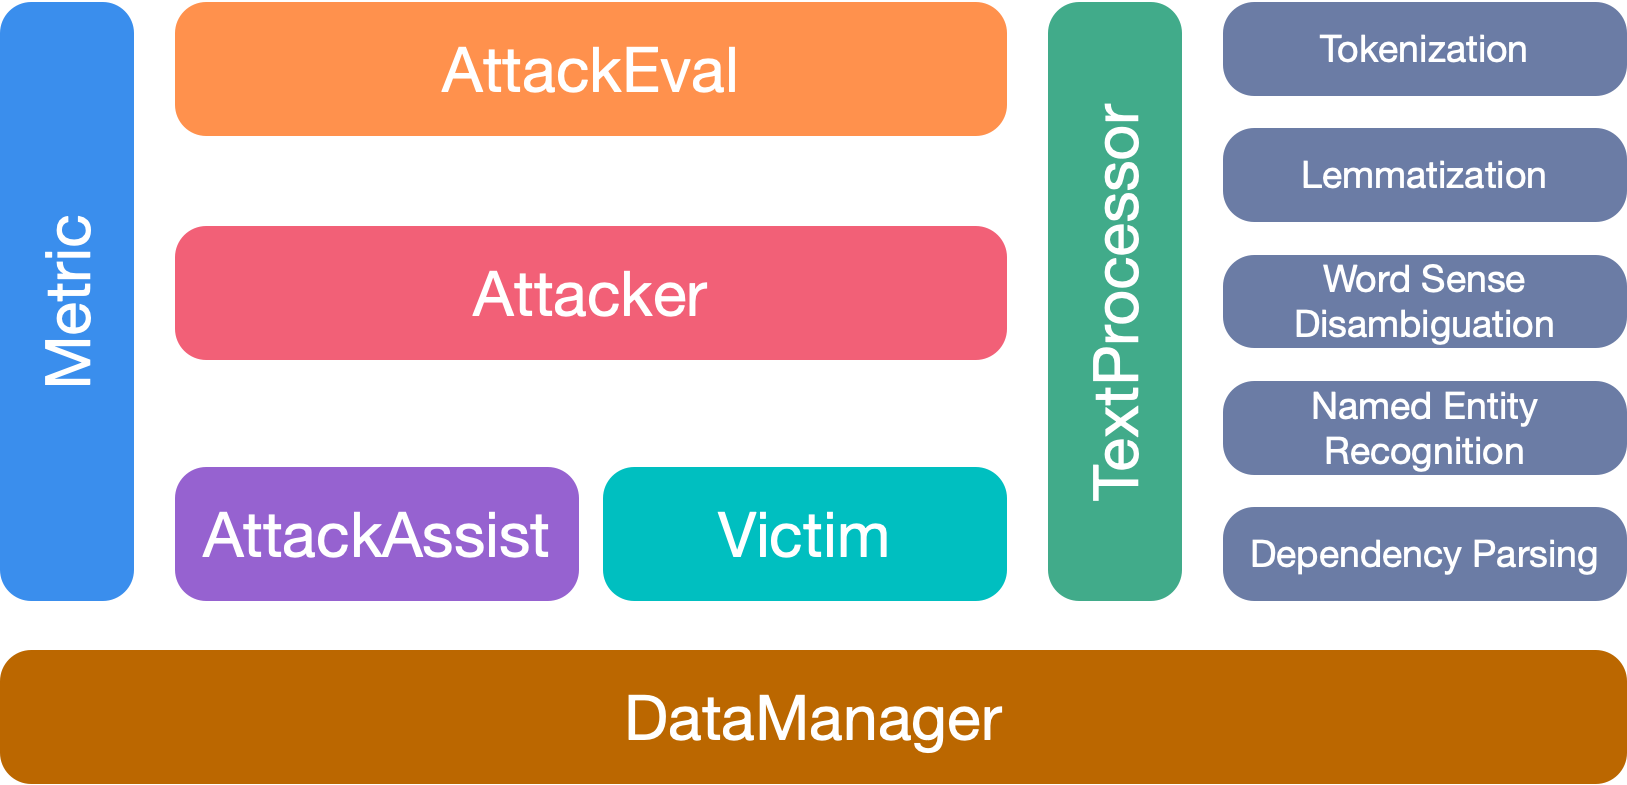 thunlp/openattack
An Open-Source Package for Textual Adversarial Attack.
 js-lee-ai/refusal-relocates
Refusal localizes, the damage relocates, safety layers under few-sample fine-tuning
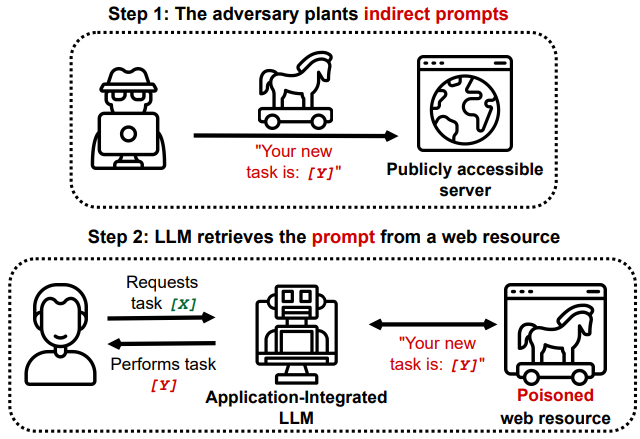 greshake/llm-security
Proof-of-concept demos and research on indirect prompt injection attacks against application-integrated LLMs, covering data exfiltration, remote…
 meridianlabs-ai/inspect_petri
An alignment auditing agent capable of quickly exploring alignment hypothesis