 paultendo/confusable-vision
The world's first font-by-font confusables dataset: which Unicode characters look alike, measured from the outlines of 322 fonts at the size people read them. CC BY, used in Mozilla's add-on name checks.

The world's first font-by-font confusables dataset. Which Unicode characters look like which, measured from the fonts' outlines rather than from pixels. The current release, 2026.09.26, compares every letter and digit that each of 322 fonts draws, at the size and baseline position each glyph has in running text. The lookalikes of ASCII letters and digits are then checked in place: set between other letters in common fonts at the size people read them, and compared with pairs everyone accepts as alike, such as 0 and O.
addons.mozilla.org uses characters from confusable-vision to check add-on names for lookalikes, credited in Mozilla's source; see Used by.
src/olympia/amo/confusables.py, pull requests #24468, #24541, #24612 and #24665 (February to March 2026).data/confusables_supplement.tsv, data/confusables_vision.tsv.docs/hkb.md).These projects took their data from confusable-vision's outputs of February and March 2026.
Discussed on Hacker News: I rendered 1,418 confusables over 230 fonts and Confusables.txt and NFKC disagree on 31 characters.
Release 2026.09.26 in figures:
The data is published as a versioned release in data/release/2026.09.26/ (CC-BY-4.0). namespace-guard and d0ma1n are built on it.
Release 2 (2026.09.24, and 2026.09.25 for the TLD data) compared only the pairs and fonts that earlier runs had compared. An audit of identical glyphs found it caught 637 of the 2,654 cases where a font draws two characters with the same glyph. Release 3 fixes that and adds three things:
The March 2026 figures (249,976 single-character pairs and 2,524,275 bigram pairs across 245 fonts) came from measurements that ignored size and baseline. They are superseded; the files from those runs stay in data/output/ for reference.
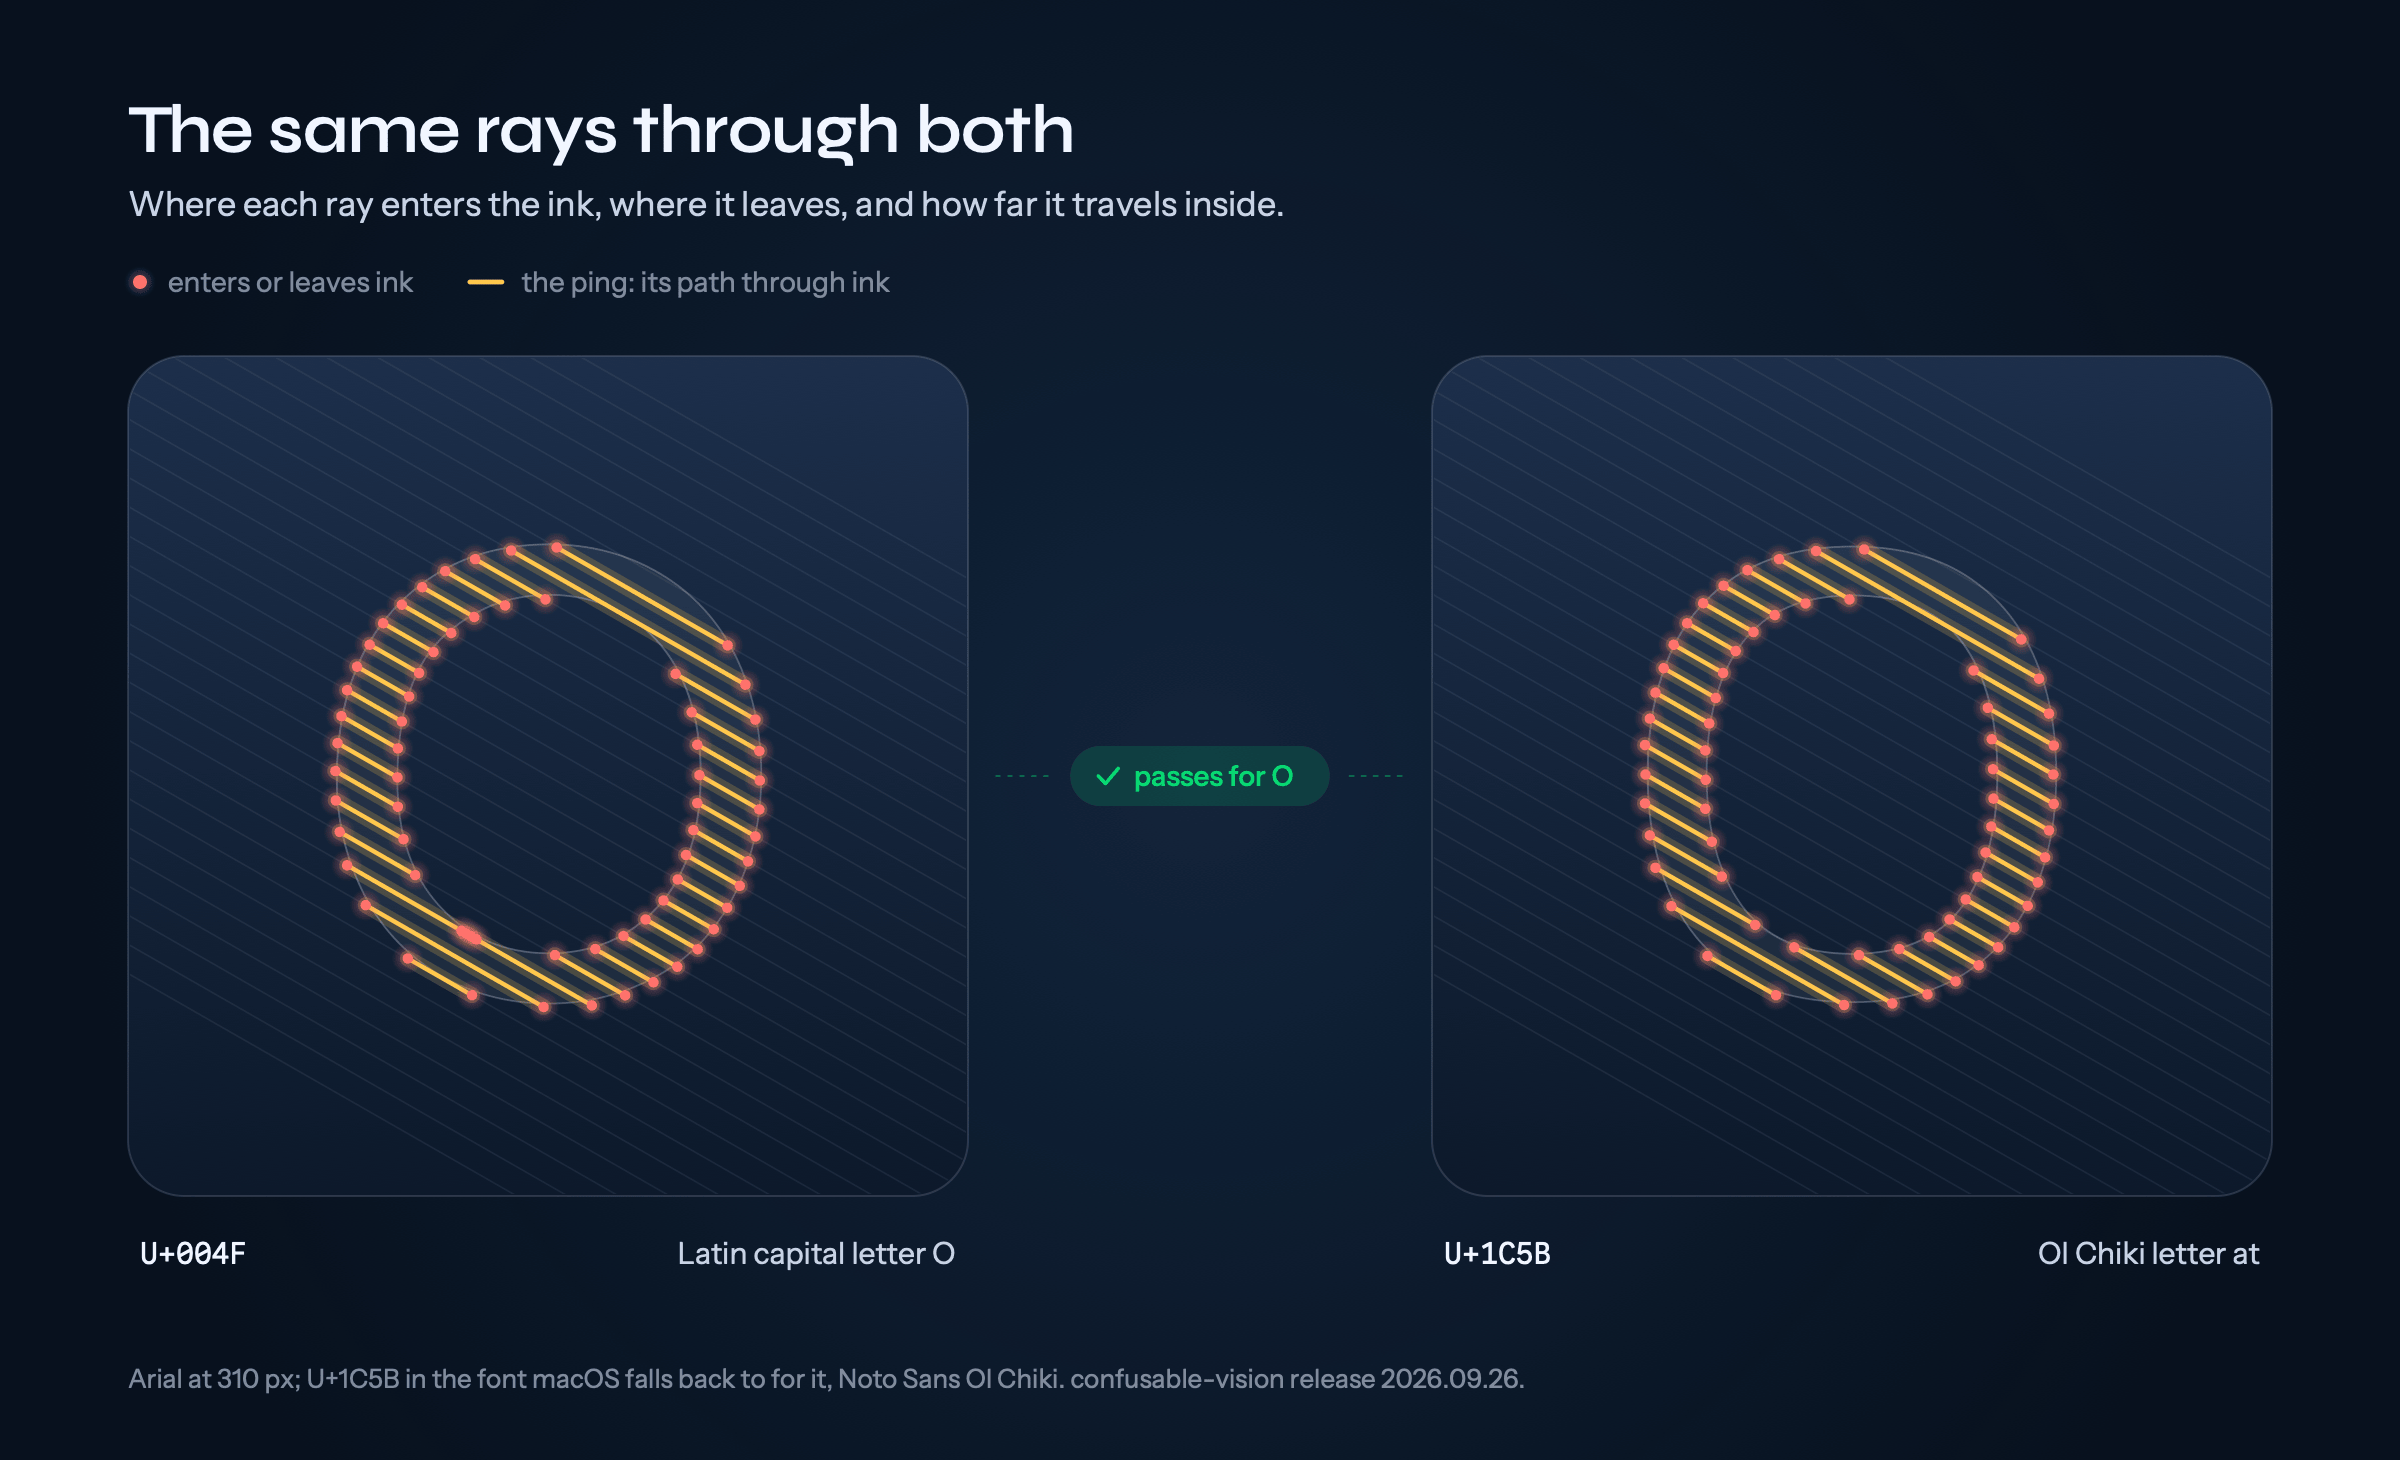
RaySpace casts parallel rays through each glyph's outline at 36 angles, 50 rays each, and records five things per ray: how many times it crosses the outline, where, at what angle, how far it travels through ink each time (its ping, the stroke's width along the ray), and the widest gap between strokes. Each glyph is measured twice: in its own box, for shape, and in a fixed frame on the baseline, so size and position count. Two characters are alike in a font when the shape distance is below 0.5 and the baseline-anchored distance below 0.2. The comparison runs in Rust (native/cv-pairs), on every core.
A lookalike measured in isolation can still stand out in a line of text. So every candidate lookalike of an ASCII letter, digit or sequence is set between neighbours (pa_nel, 20_5) in five contexts, the system font at 13 px and Helvetica, Arial, Times New Roman and Georgia at 16 px, each at a device pixel ratio of 1 and 2, with the platform's font fallback. Nothing is rescaled: the lookalike is compared where it lands in the line.
The bar in each context comes from pairs everyone accepts as alike, 0 and O, 1 and l, and I and l, counted only where that context draws them at the same size and position. A lookalike is:
