

 amd2g2zz/kunglao-agent
The reverse-engineering expert agent: plans its own analysis path, derives every fact from raw evidence, and converges under mechanical verification gates — firmware, protocols, web/JS, risk-control, binaries.
An autonomous reverse-engineering agent that runs for hours unattended, verifies every conclusion independently, and converges only when every answer survives a mechanical oracle verdict.


🧠 plans its own route · 🔬 every claim machine-checked · ⚖️ blind verification on everything · 📈 the loop measures itself
🚀 Quick Start · ✨ Core Tech · 🧠 kunglao × Claude Code · 🎛️ How RL Works · 🖥️ Showcase · 📖 Case Studies · 🧪 Evaluation · 🏗️ Architecture · 🗓️ Roadmap
English · 简体中文
[!WARNING] v0.1.6 is the last Claude Code-native release line. The next milestone (v0.2) migrates the runtime wholesale to the PI Agent base — same loop, same ledgers, new engine substrate. See the roadmap.
You point kunglao-agent at a target and state the questions; it plans the route, dispatches specialist workers, verifies every conclusion independently, and stops only when each answer is settled by a mechanical check instead of a model's say-so.
The target spectrum is the full one — Windows/Linux native binaries, Android
APKs (including native .so layers), web/JS, protocol recovery, firmware —
static-first by design, driving whichever execution channel your environment
already has (VMware, ssh, docker, adb, or none at all for static-only work).
It runs inside Claude Code as a plugin: Claude Code is the conversation surface; the product is the loop and the fact base it produces.
[!NOTE] Every number the loop reports — win rates, posteriors, budgets — traces to a row on an append-only ledger. Nothing is self-declared.
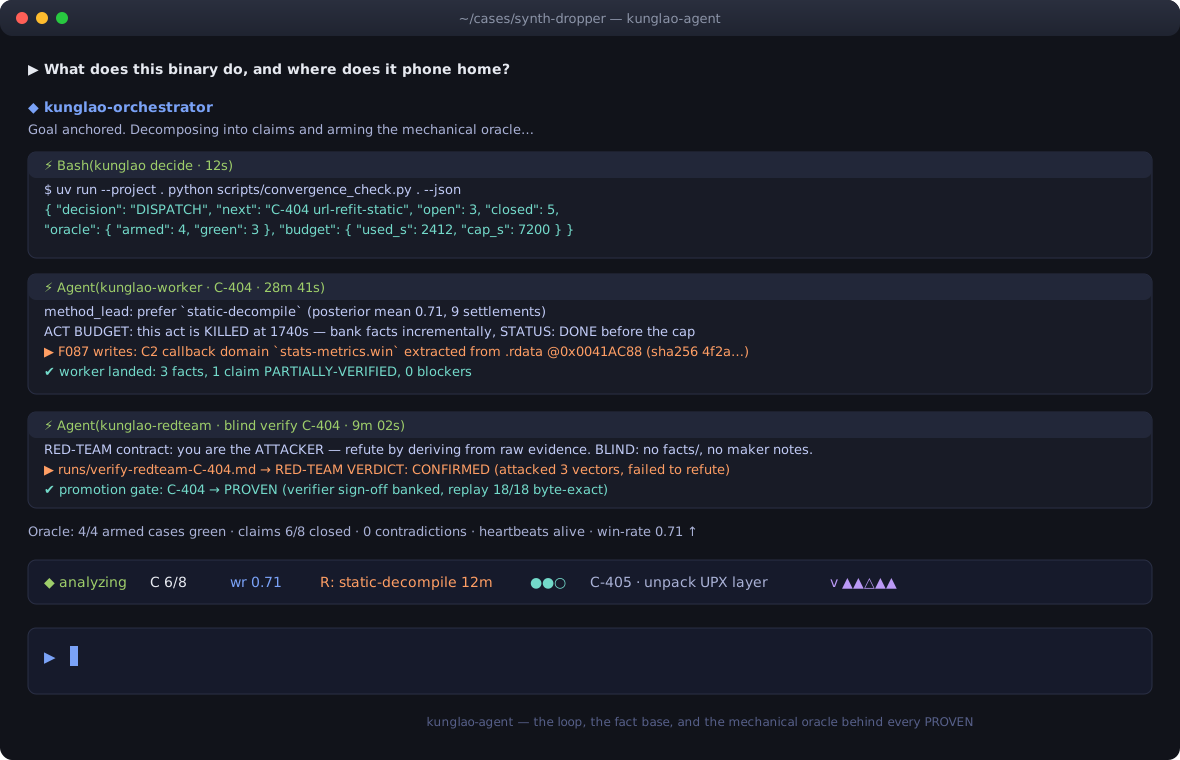
The orchestrator at work — a convergence decision, a budgeted worker
dispatch with live facts landing, and a blind red-team verdict promoting a
claim to PROVEN; the statusline HUD keeps the whole engagement readable at
a glance:
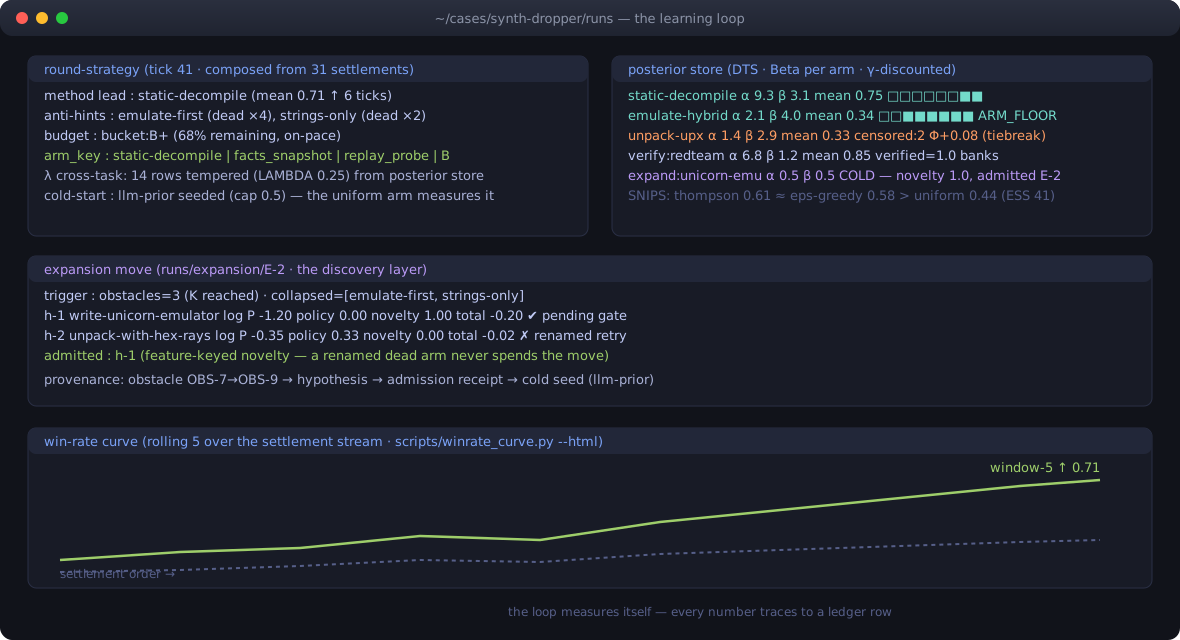
The loop measuring itself — the round strategy composed from settlements, the discounted-Thompson posterior store with censored-outcome tiebreaking, the discovery layer admitting a genuinely novel arm (and refusing a renamed retry), and the win-rate curve:
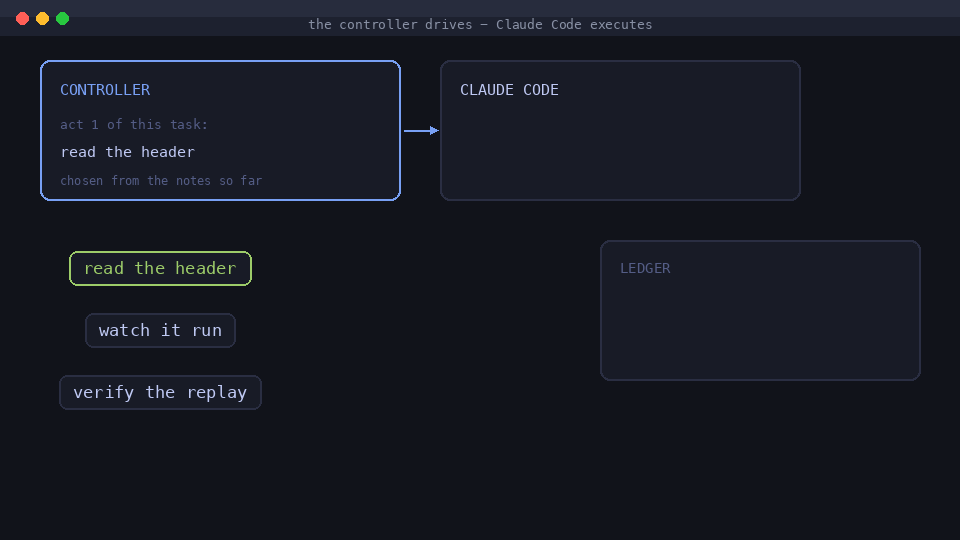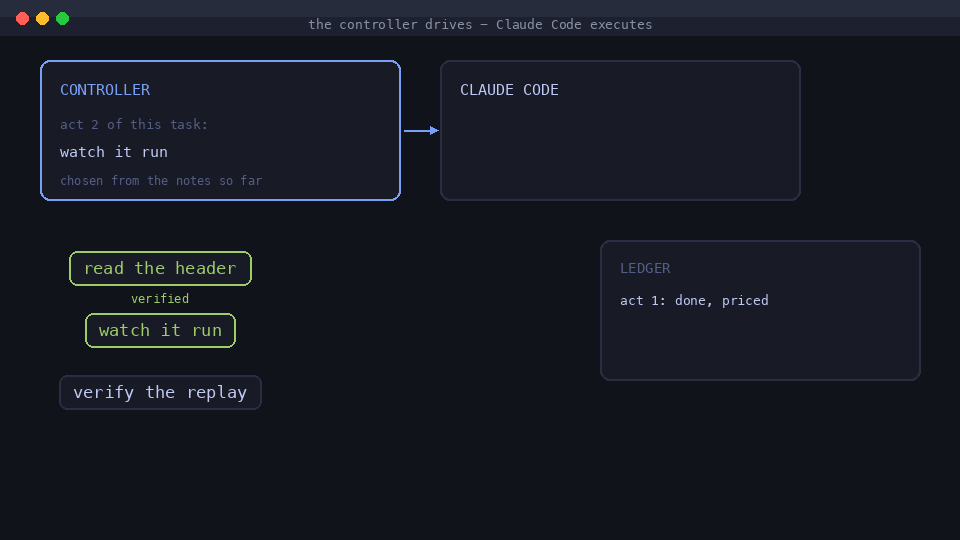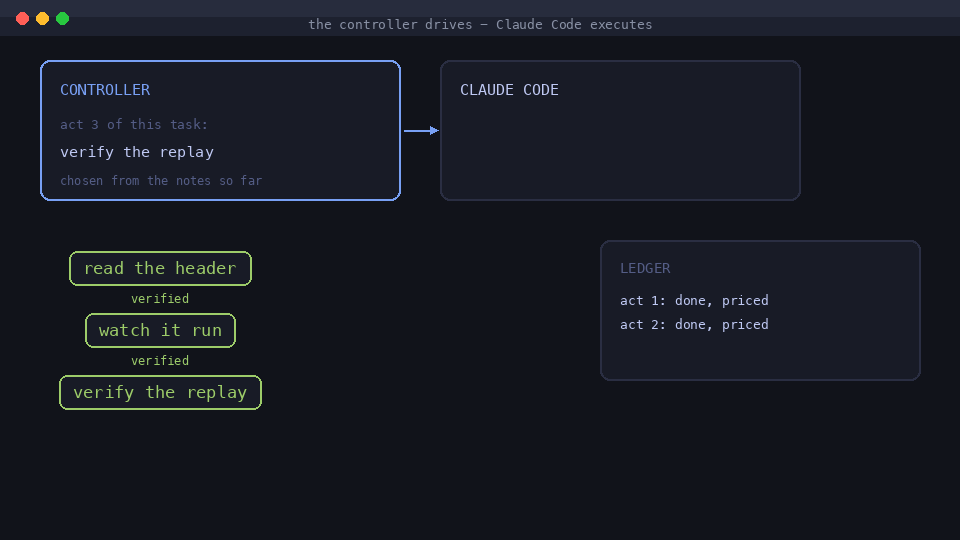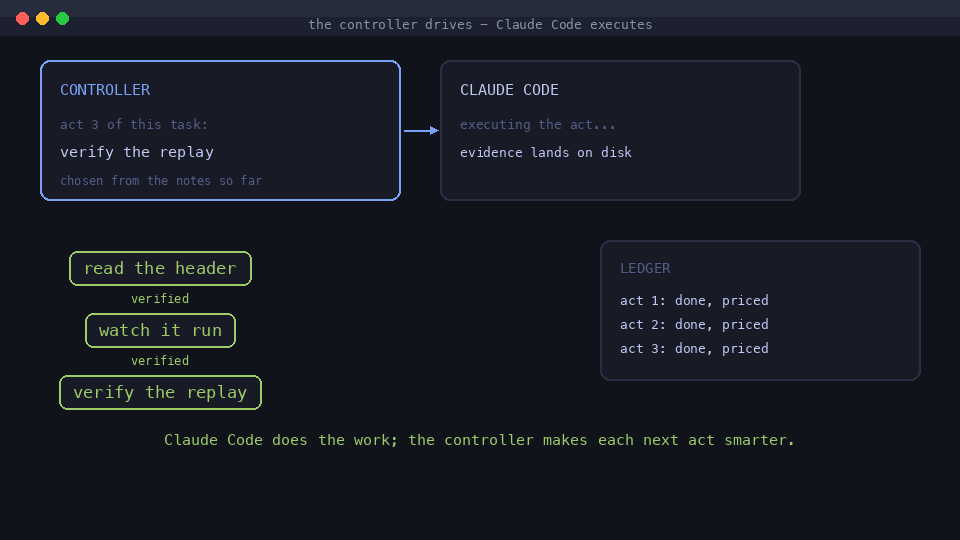
kunglao-agent is an act-level RL controller around Claude Code: Claude
Code reasons inside each act; kunglao decides the next act, verifies it,
prices it, learns from it. Deep design: docs/design/.
STAMP, never PROVEN. Facts cite artifacts (sha256) and carry
reproduce: commands.Claude Code is the engine; kunglao is the gearbox, dashboard, and flight computer — next act, verification, budget, and where experience goes.
| bare Claude Code | + kunglao | |
|---|---|---|
| Next step | improvised in-session | learned act-level policy, posteriors persist across tasks |
| Verification | self-report | mechanical oracle + blind red-team |
| Duration | one session, human watching | hours unattended, resume from disk |
| Experience | evaporates at session end | ledger → posteriors → sharper opening bet |
Honest boundary: for a simple single-session task, bare Claude Code wins — the evaluation table says so. kunglao pays off on long horizons, verification discipline, and cross-task compounding.
The first task of a new kind pays full price: the loop tries a method, watches it fail, tries another. But every attempt is written down — and the next task of the same kind opens from those notes, not from zero.
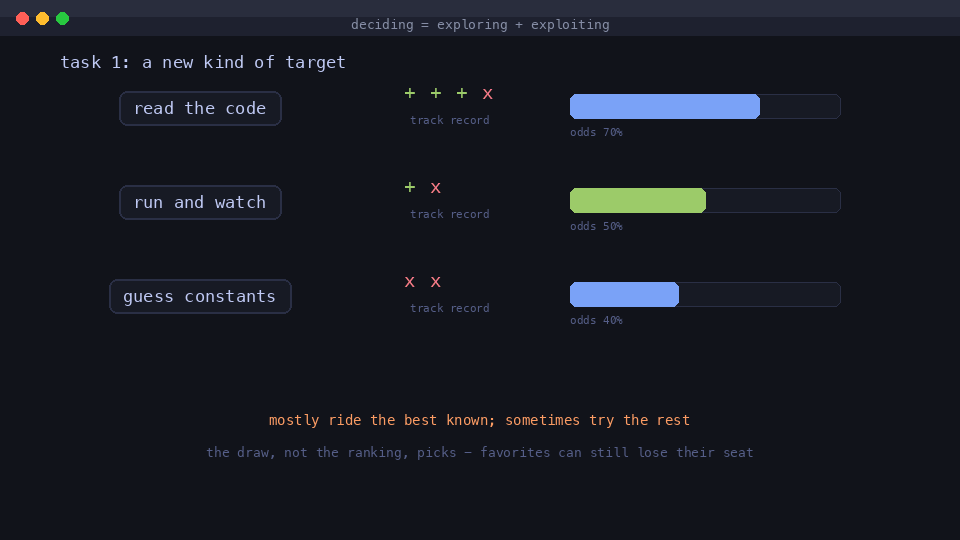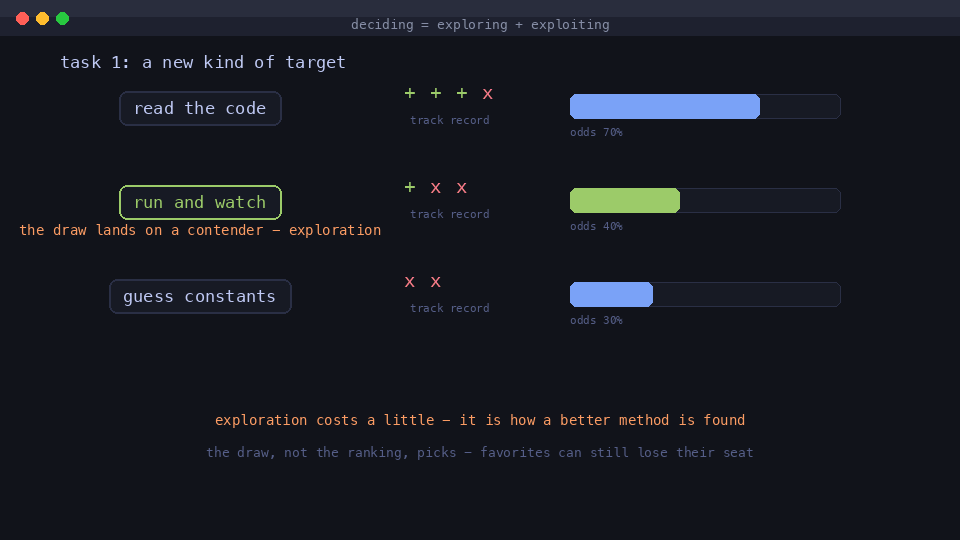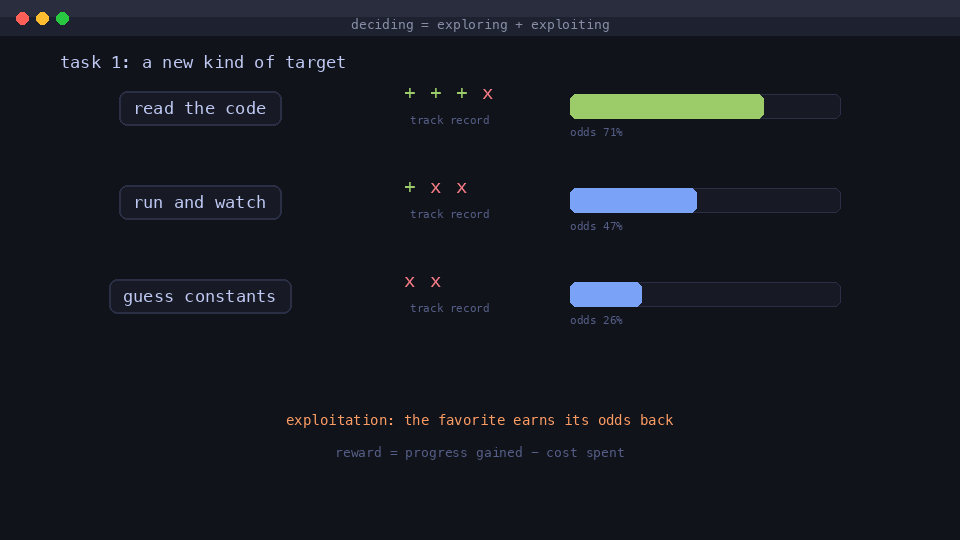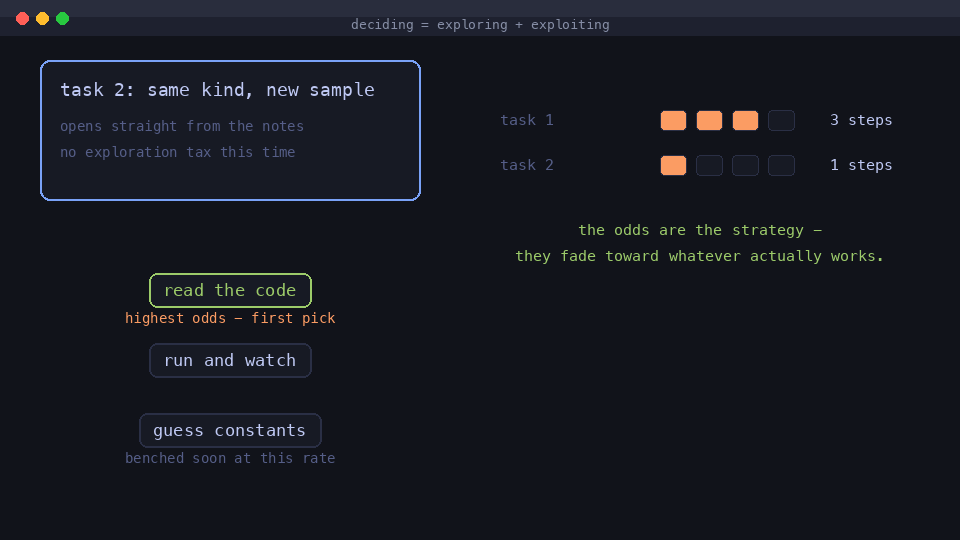
That is the whole idea of online reinforcement learning here: the loop updates itself between acts, on the job — no training dataset, no model retraining, no offline phase. Each task's experience is banked before the next decision is made.
1. The right first move, per kind of target. A plain script and a hardened app should not open the same way. The loop keeps separate notes per kind of target — what the target looks like decides which playbook applies.
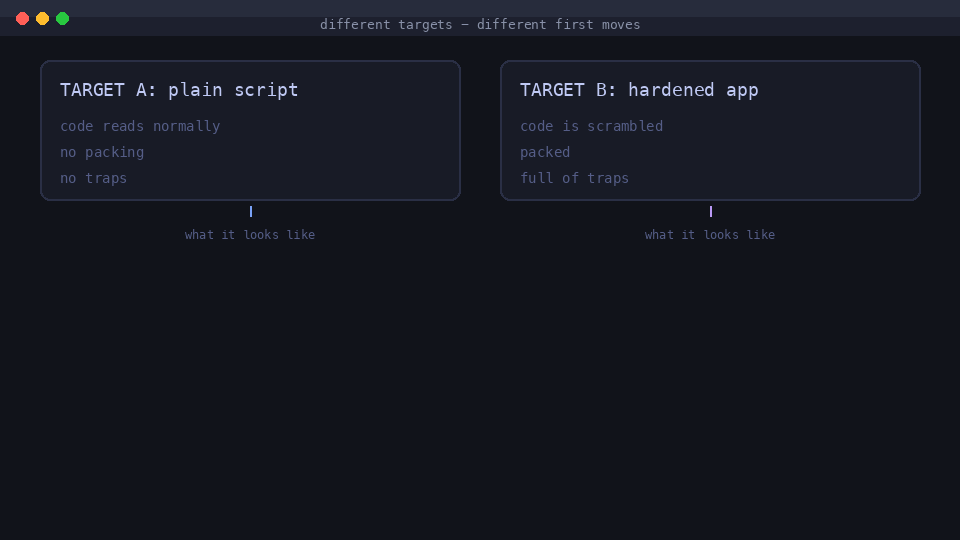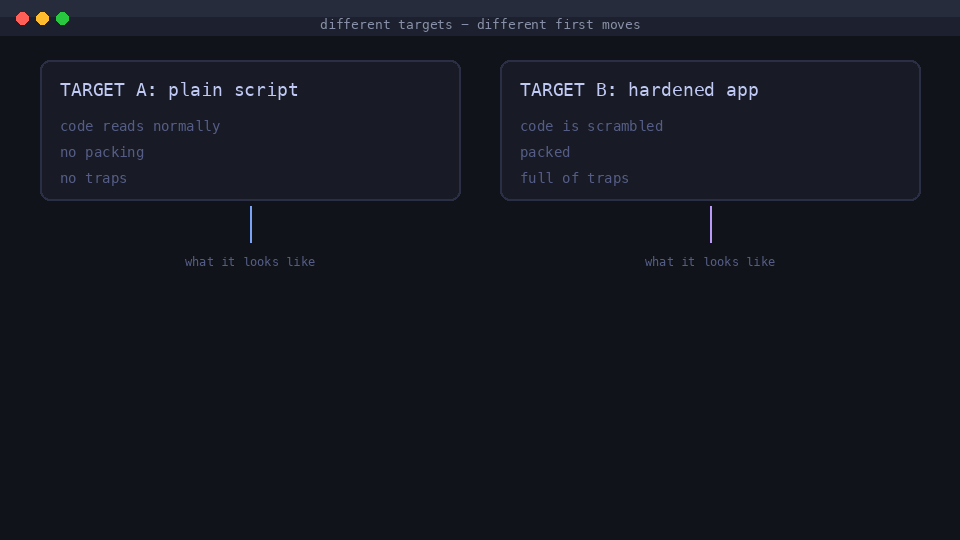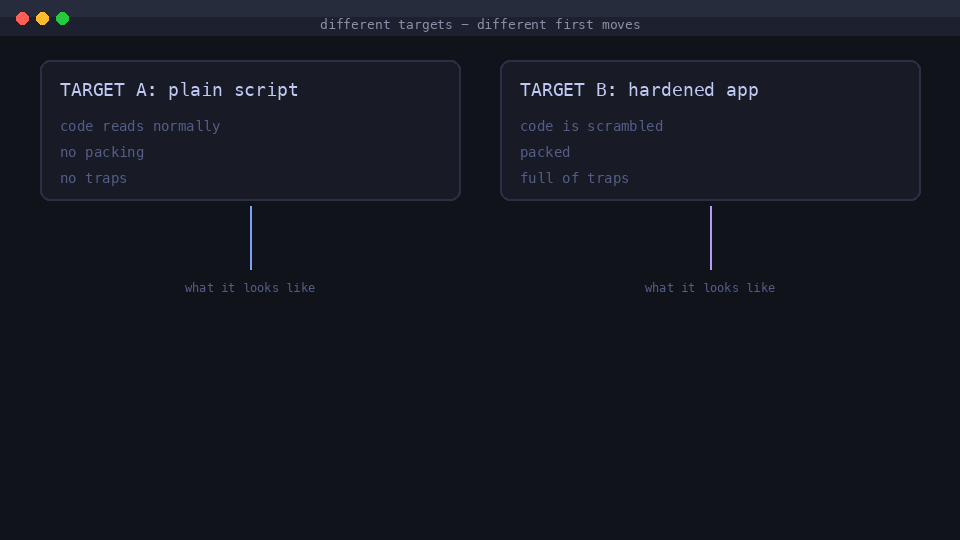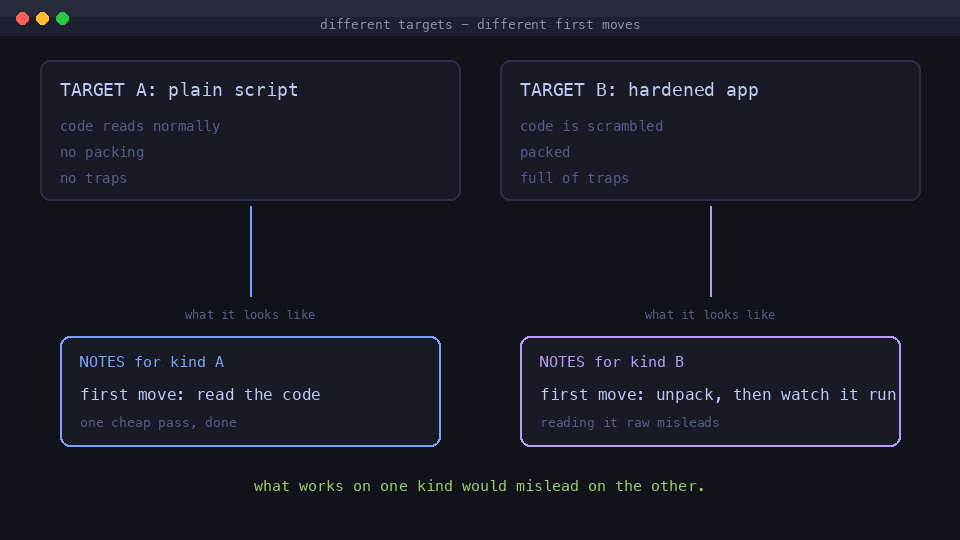
2. Which methods are dead. A method that keeps failing gets benched — it stops eating budget (but is never deleted; if the target changes, it can come back). And when nothing works, the loop tries to invent a way in: a discovery act proposes a genuinely new approach, checked against the failed tries — the same idea renamed is refused.
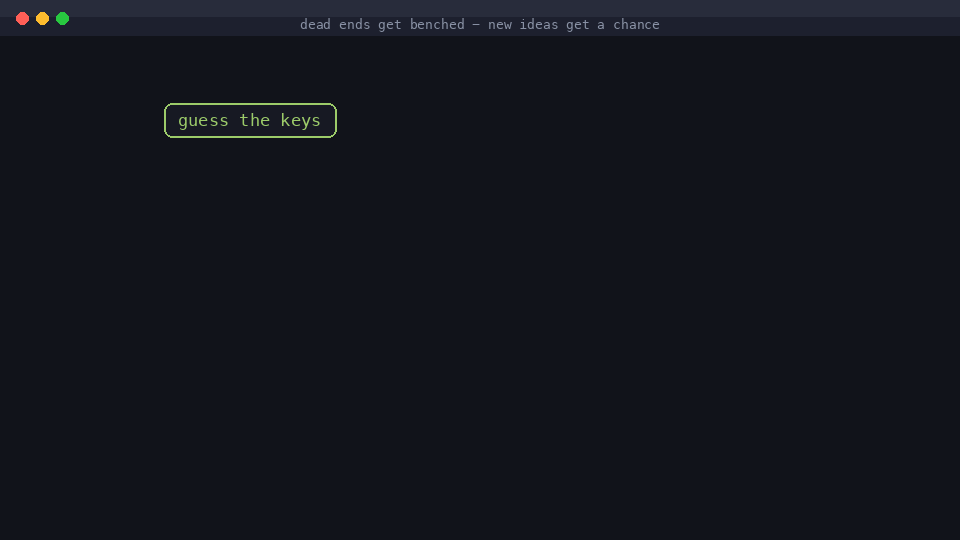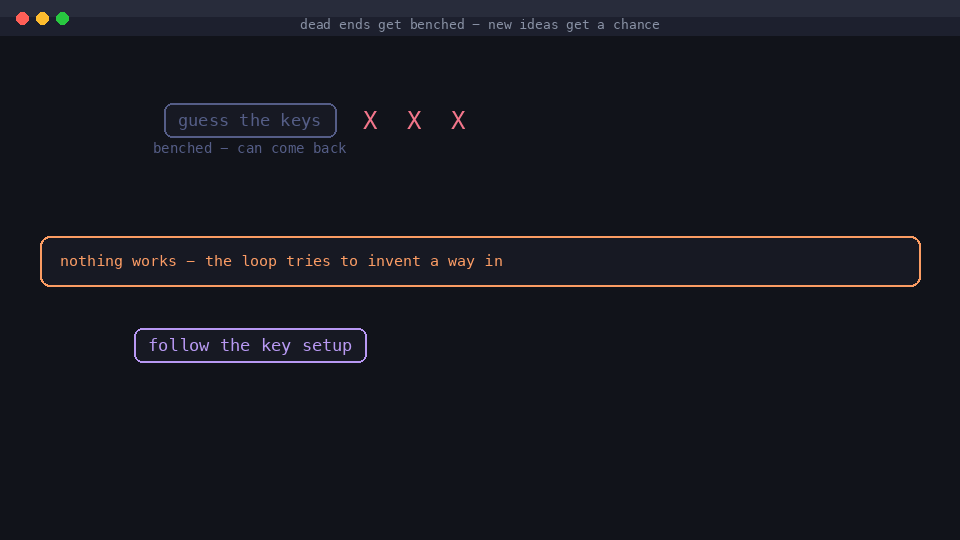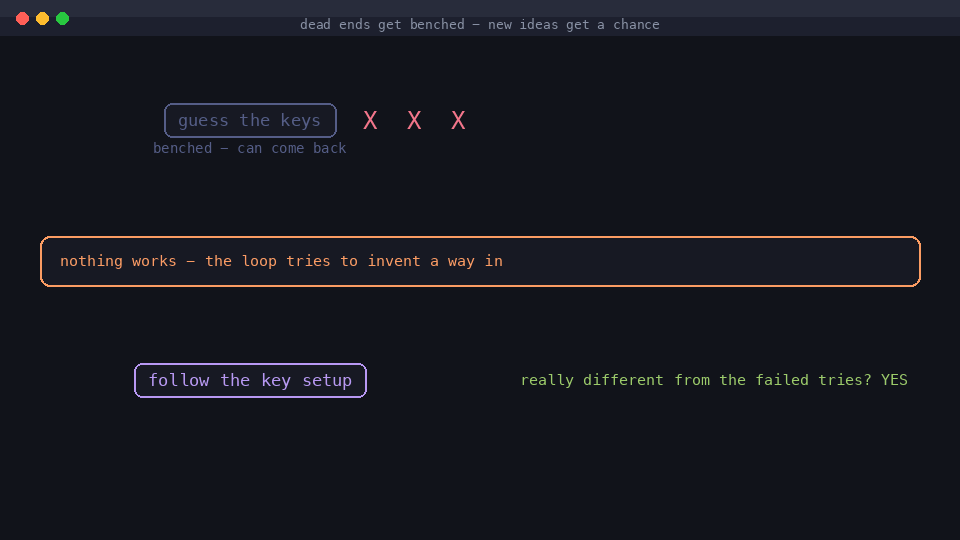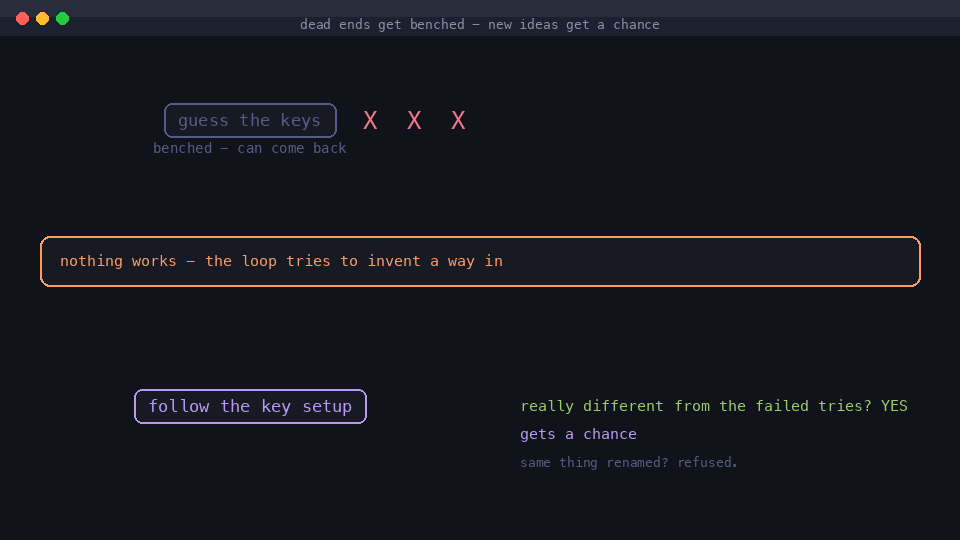
3. Where to double-check. States where verifiers keep getting refuted learn to schedule verification more tightly there — and relax when the streak turns honest. 4. Which tools to route. Tool and provider choices are learned too: a tool that fails gets demoted for a while and is reinstated the moment it works again - routing follows the recorded outcomes, not the registry order.
flowchart LR
    A["target state<br>(what it looks like)"] --> B["pick a method<br>(sample from the notes)"]
    B --> C["act<br>(a worker runs it)"]
    C --> D["checker verdict<br>(proof or no proof)"]
    D --> E["one ledger row<br>(what happened, what it cost)"]
    E --> F["update the notes<br>for this kind of target"]
    F --> B

