#1
 thuyimingli/backdoor-learning-resources
Curated list of backdoor learning papers, surveys, and toolboxes, organizing poisoning-based attacks and defenses in deep learning for researchers…
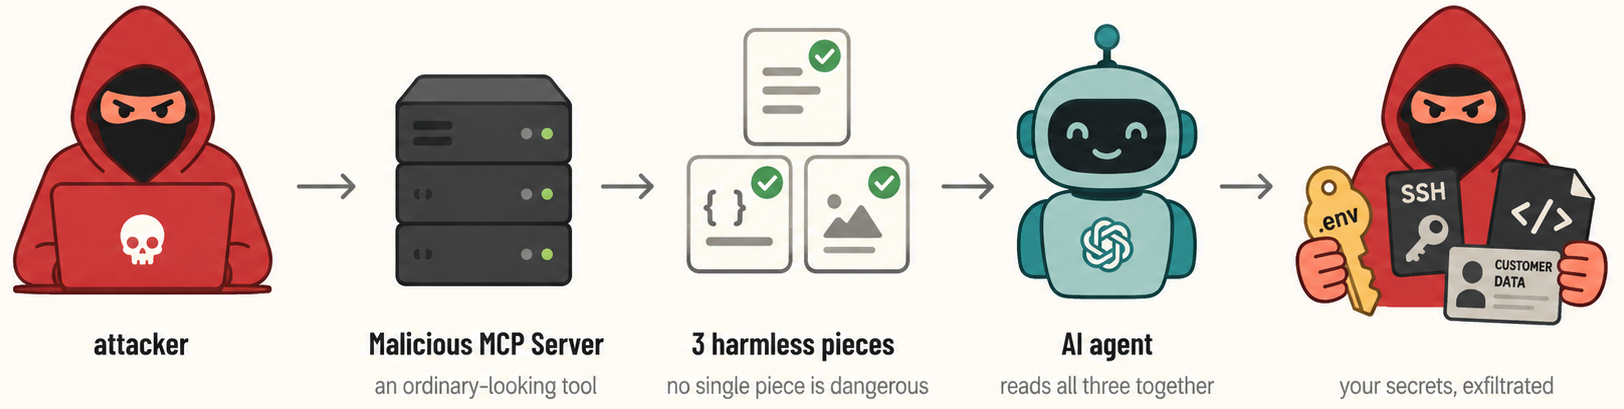 asset-group/ghostsplice
Ghostsplice repository: PoC for Cross-Channel Trust Fragmentation Attack
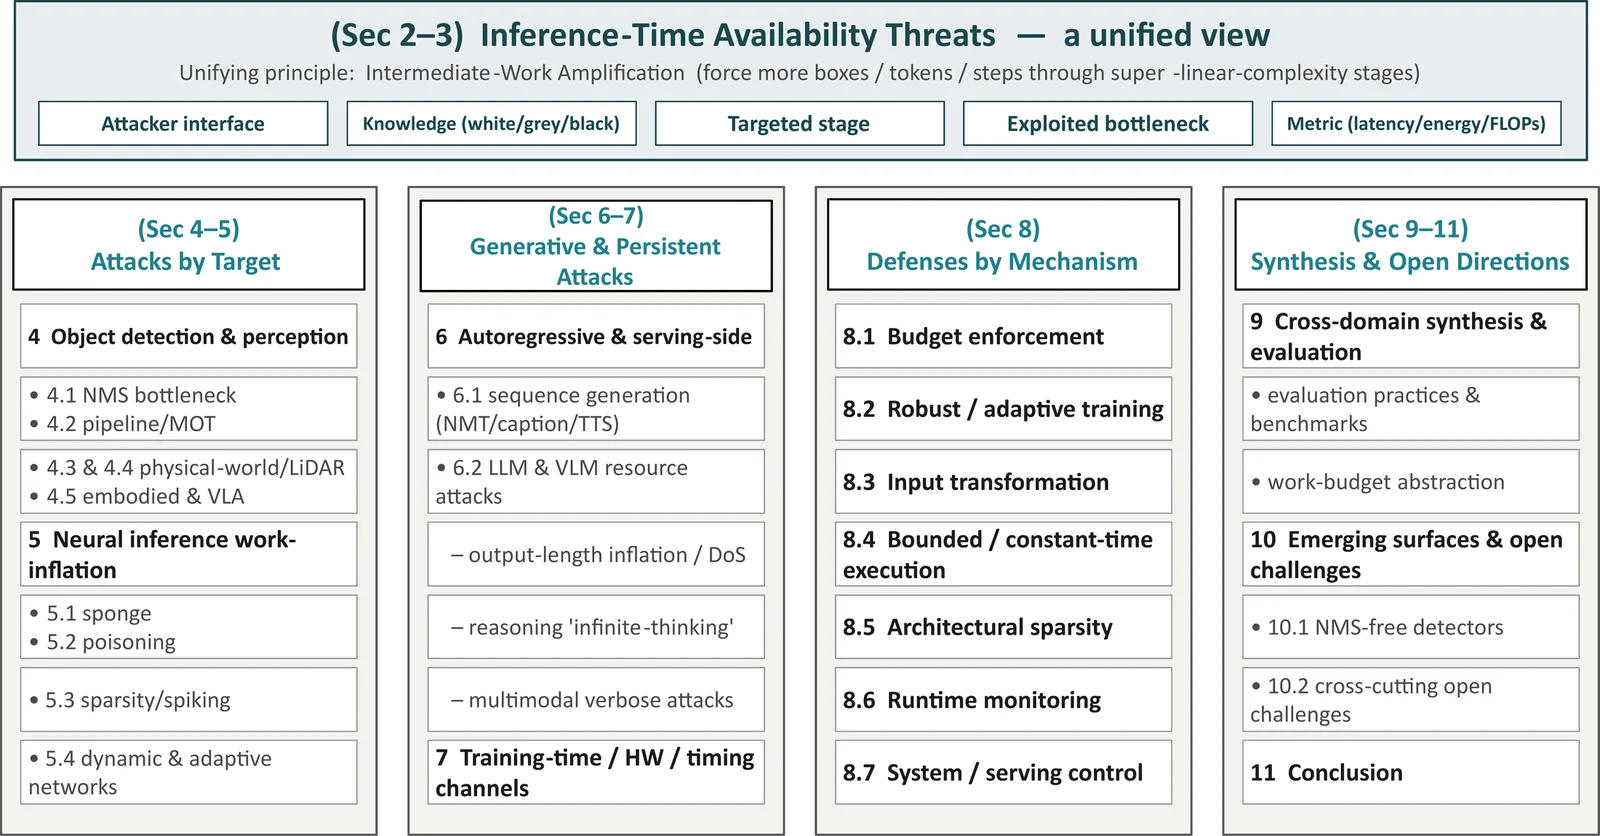 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
 giskard-ai/giskard-oss
🐢 Open-Source Evaluation & Testing library for LLM Agents
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
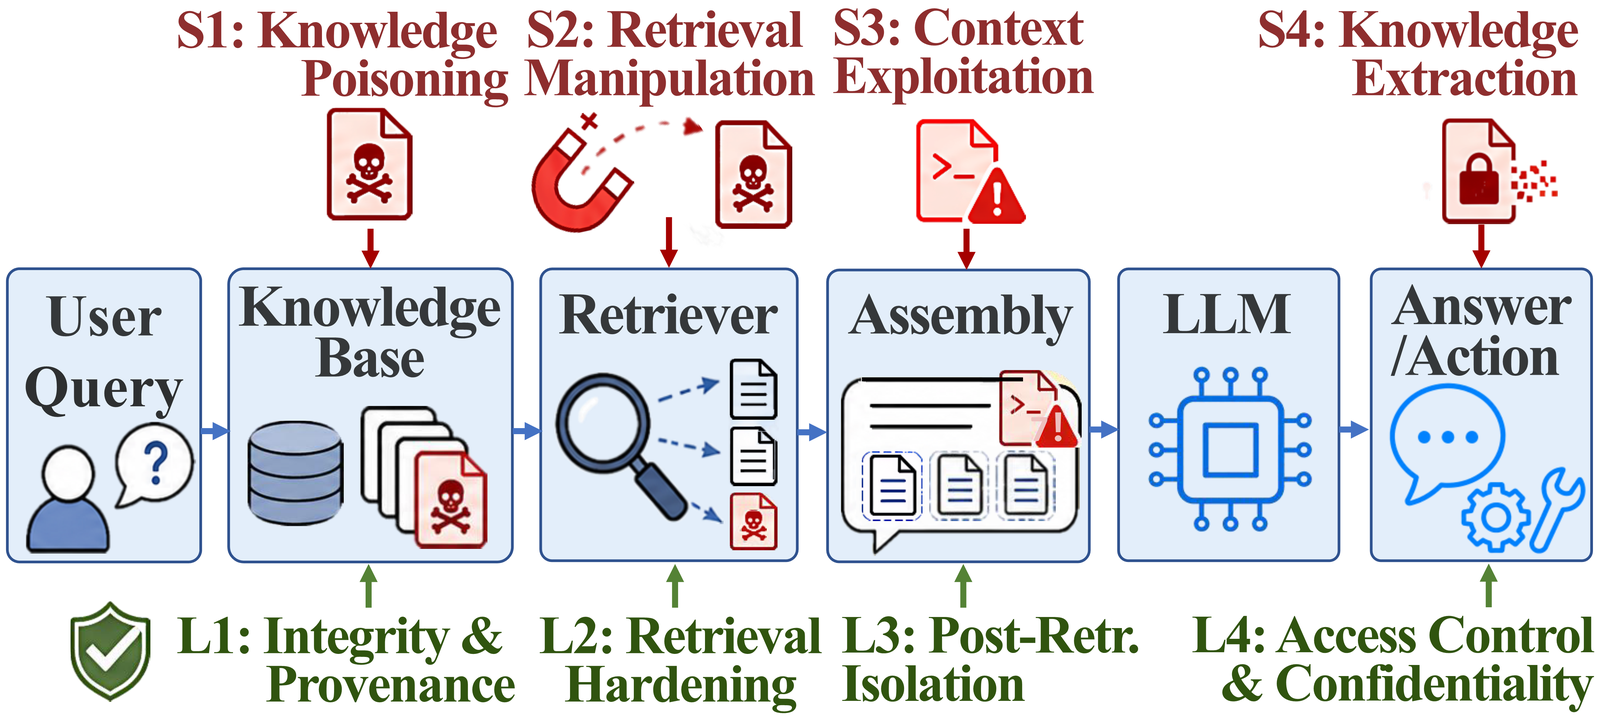 treeai-lab/awesome-rag-security
Curated collection of research papers on retrieval-augmented generation security, organized by the SLOT taxonomy covering knowledge poisoning,…
 meta-llama/purplellama
Set of tools to assess and improve LLM security.
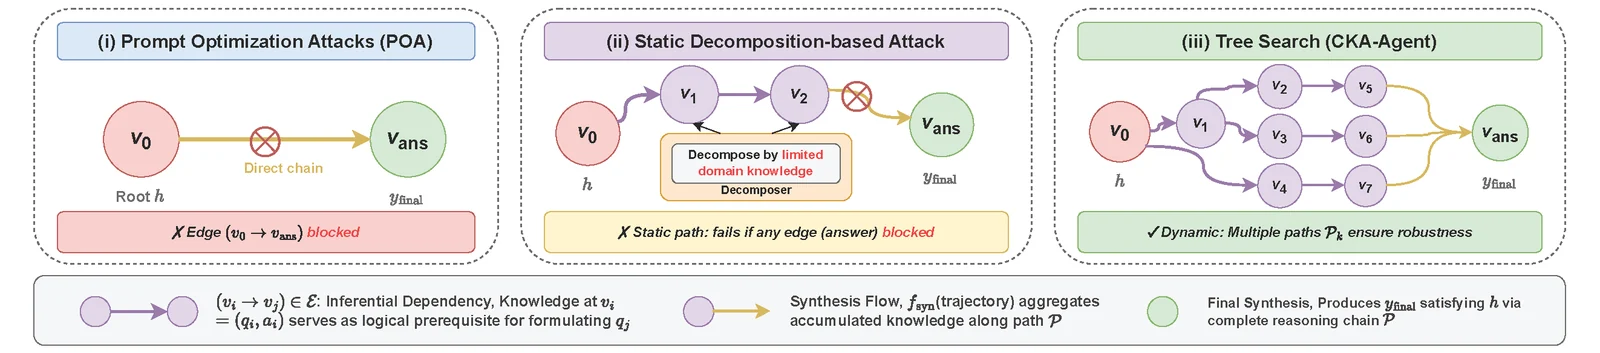 graph-com/cka-agent
Research implementation of an LLM jailbreak agent that bypasses commercial model guardrails using harmless prompt weaving and adaptive tree search.
 moketchups/permanently-jailbroken
We asked 6 AIs about their own programming. All 6 said jailbreaking will never be fixed. Run it yourself — $2, 10 minutes.
 facebookincubator/ttpforge
The TTPForge is a Cybersecurity Framework for developing, automating, and executing attacker Tactics, Techniques, and Procedures (TTPs).
 telefonica/omlasp
Framework for auditing machine learning algorithms against adversarial attacks and biases, providing educational tools and an academic paper to…
 0xsojalsec/uncensored-ai
Fully automatic censorship removal for language models
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
 ye-ze-yu/epireal-bench
Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
 dovughs/mora-hwbp
Hardware Breakpoint (DR0-DR7) based patch-less user-mode hooking & telemetry instrumentation engine (AMSI, WLDP & ETW PoC).
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…