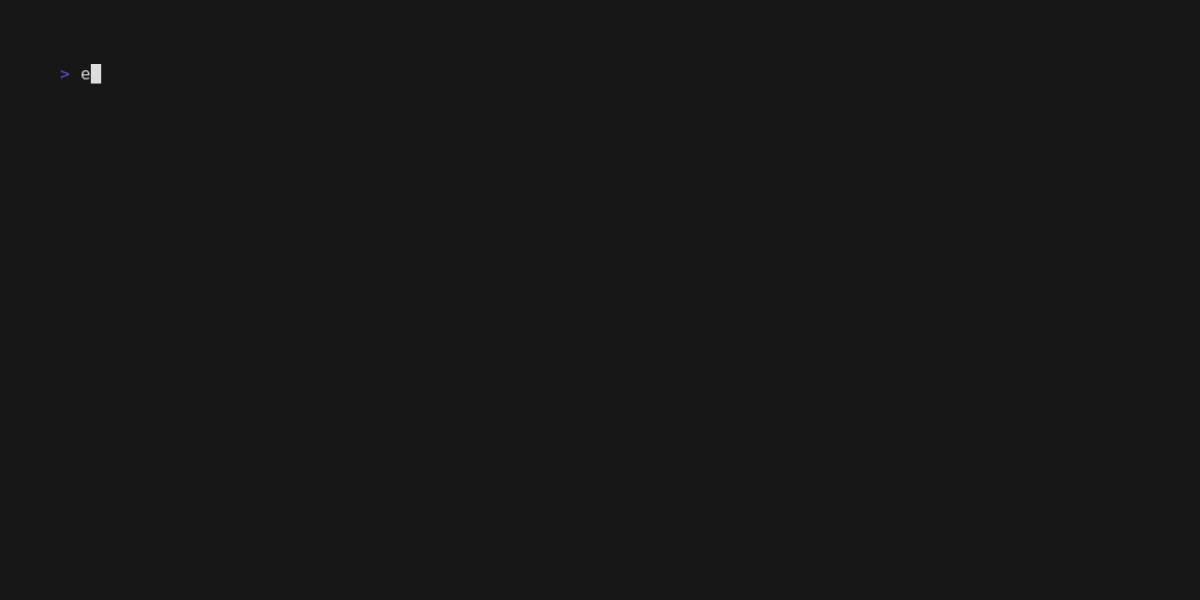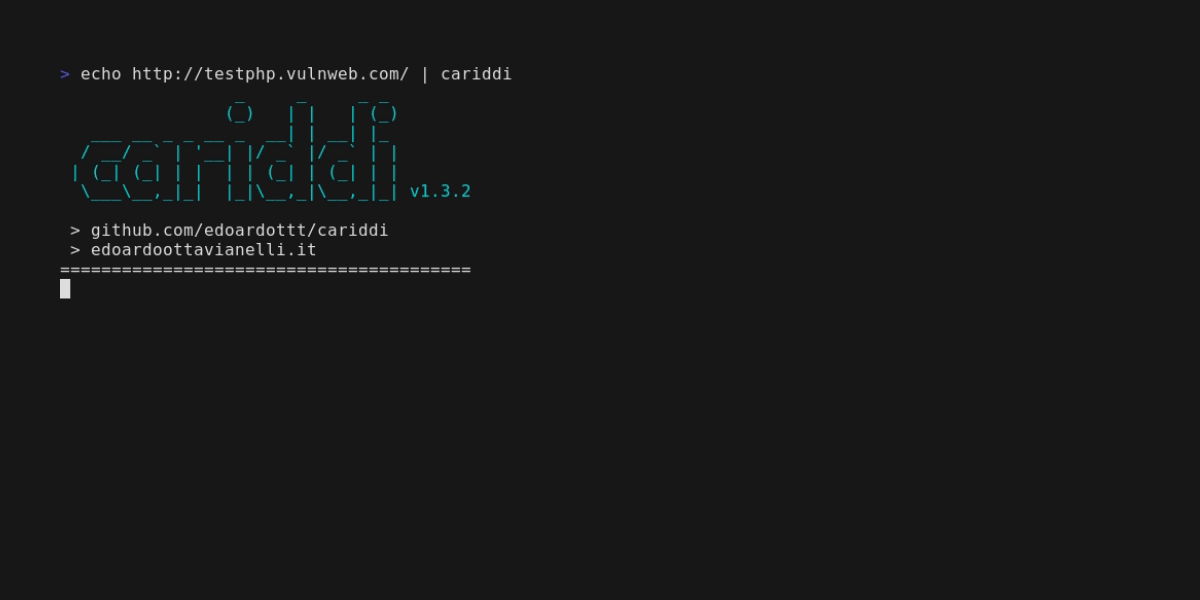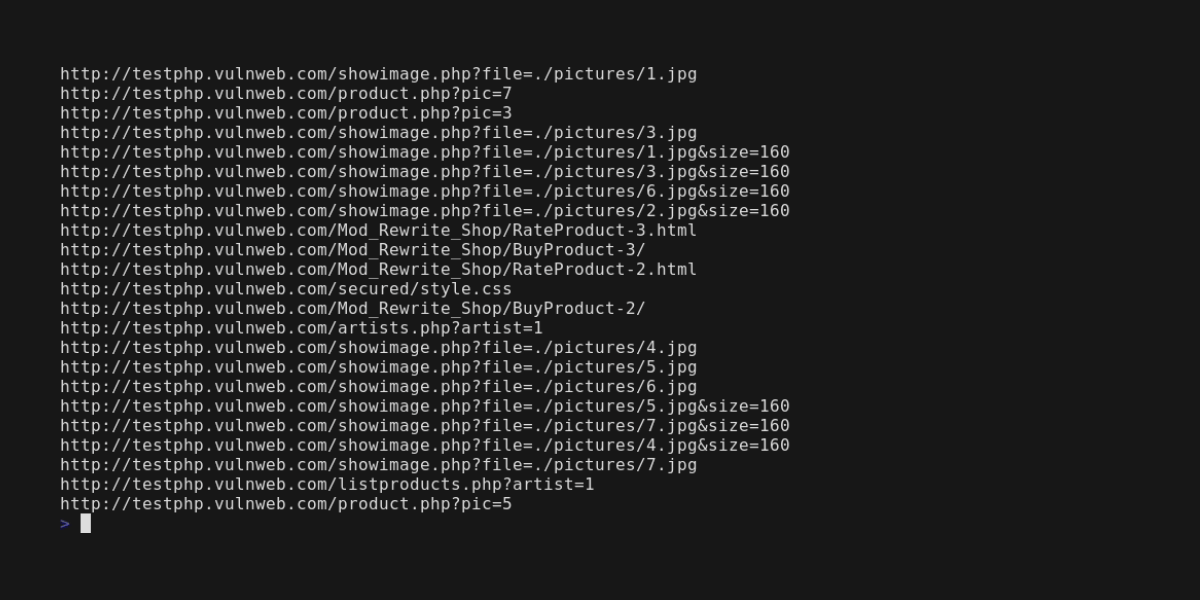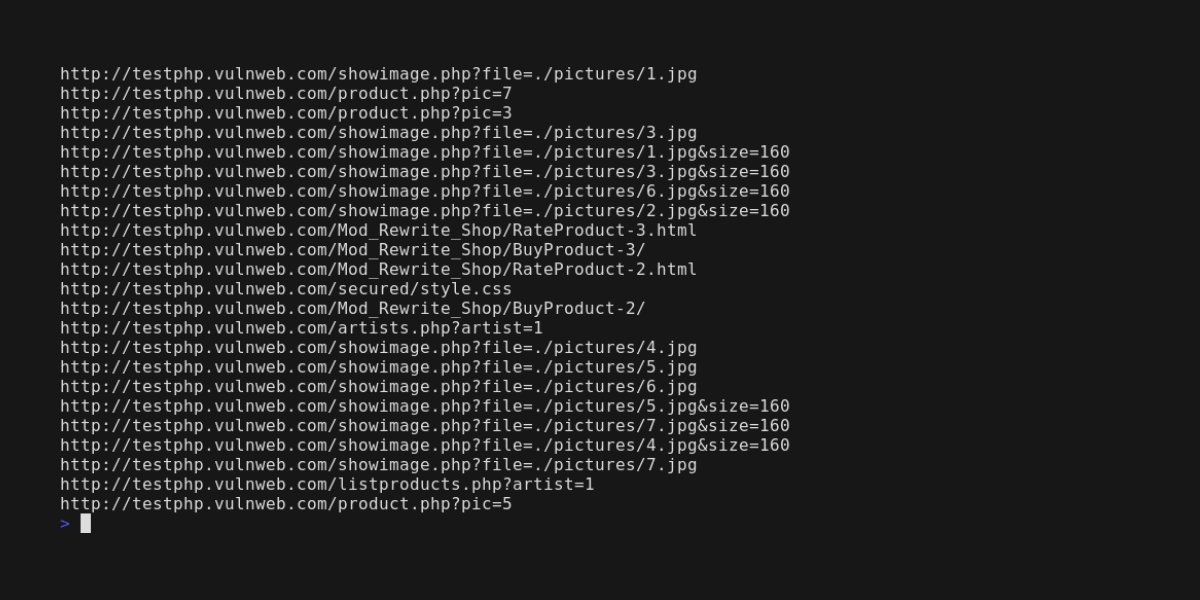
输入域名列表,爬取 URL 并扫描端点、密钥、API 密钥、文件扩展名、令牌等

由 edoardottt 用 💙 编写
分享到 Twitter!
安装 • 用法 • 快速开始 • 更新日志 • 贡献 • 许可证
brew install cariddi
sudo snap install cariddi
go install -v github.com/edoardottt/cariddi/cmd/cariddi@latest
pacman -Syu cariddi
nix-shell -p cariddi
你需要 Go (>=1.24.0)
git clone https://github.com/edoardottt/cariddi.git
cd cariddi
go get ./...
make linux # (to install)
make unlinux # (to uninstall)
一行命令:git clone https://github.com/edoardottt/cariddi.git && cd cariddi && go get ./... && make linux
注意,可执行文件仅在 cariddi 文件夹中可用。
git clone https://github.com/edoardottt/cariddi.git
cd cariddi
go get ./...
.\make.bat windows # (to install)
.\make.bat unwindows # (to uninstall)
如果你只想扫描单个目标,可以使用
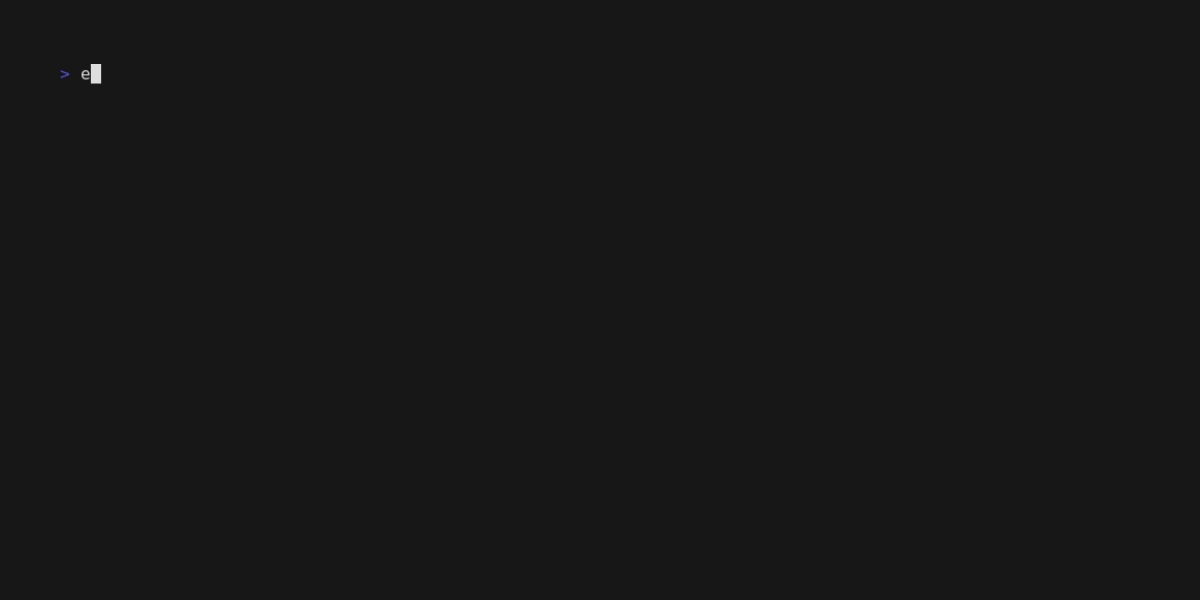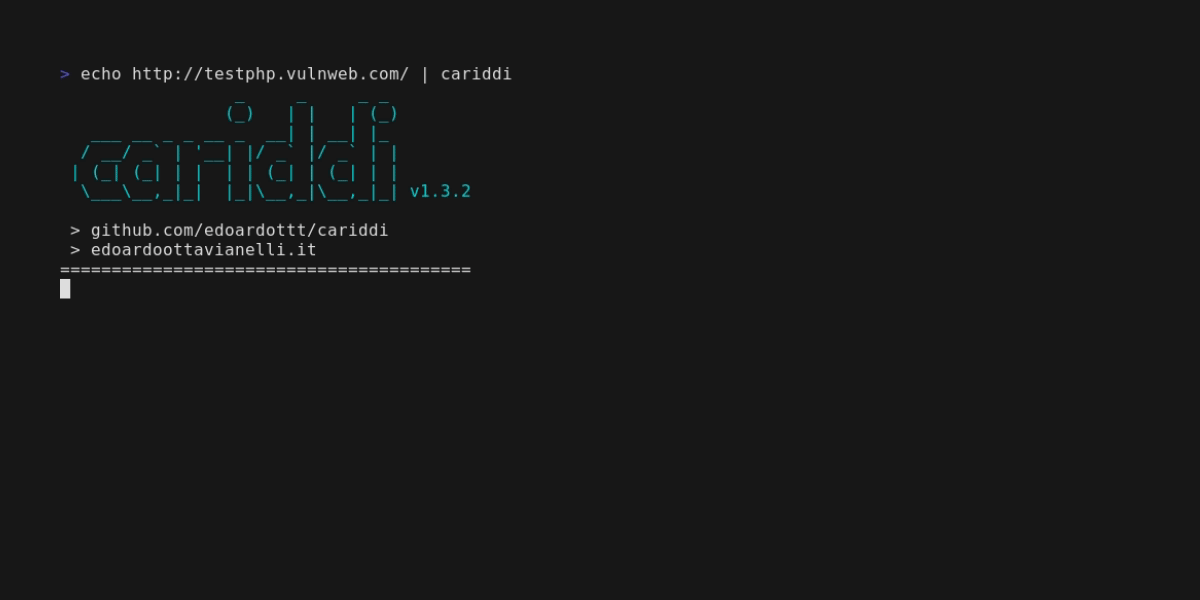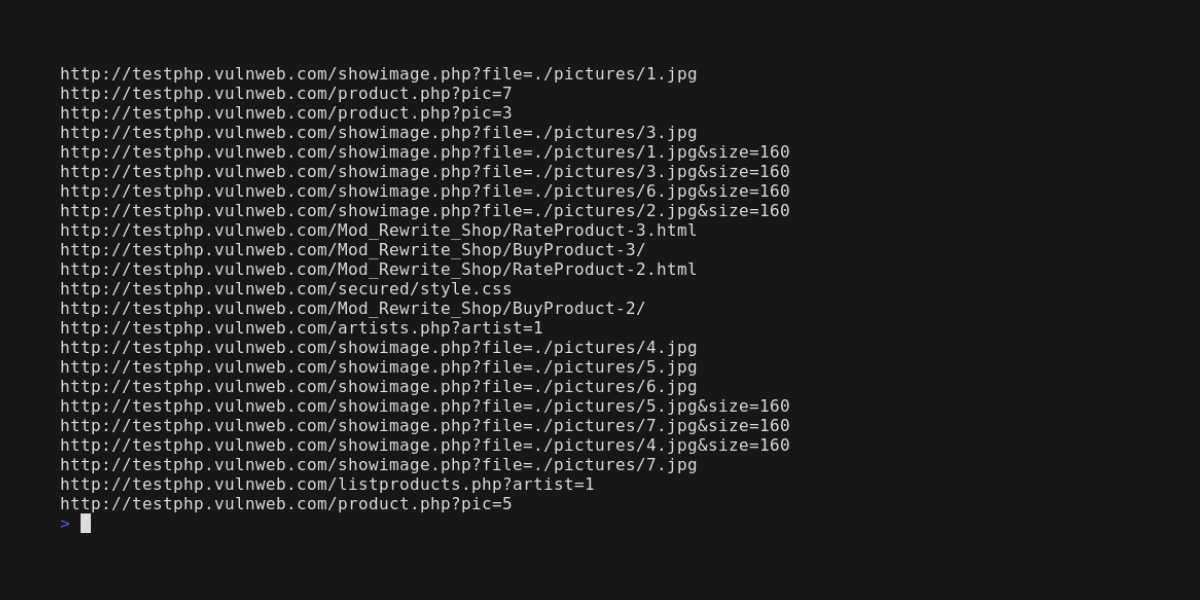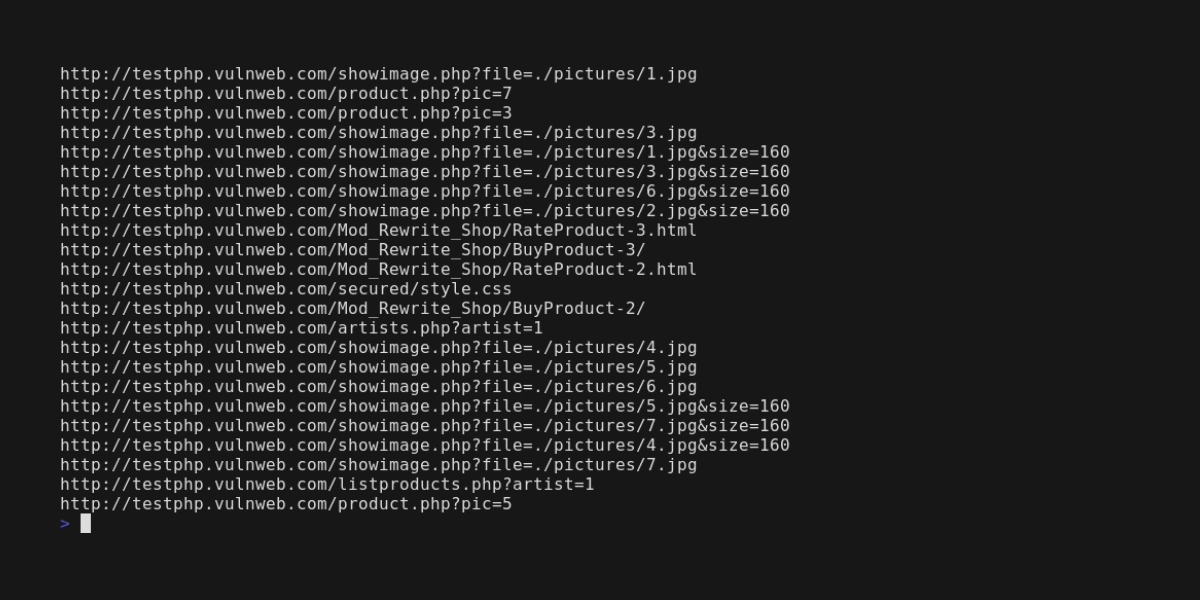
echo https://edoardottt.com/ | cariddi
对于多个目标,你可以改用文件,例如 urls.txt 包含:
https://edoardottt.com/
http://testphp.vulnweb.com/
对于 Windows:
powershell.exe -Command "cat urls.txt | .\cariddi.exe"cat urls.txt | cariddi.execariddi -version(打印版本)cariddi -h(打印帮助)cariddi -examples(打印示例)cat urls.txt | cariddi -intensive(爬取时同时搜索子域名,等同于 *.target.com)cat urls.txt | cariddi -s(搜寻密钥)cat urls.txt | cariddi -err(搜寻网站中的错误)cat urls.txt | cariddi -e(搜寻有价值的端点)cat urls.txt | cariddi -info(搜寻网站中的有用信息)cat urls.txt | cariddi -ext 2(搜寻有价值的文件(7 个级别中的第 2 级))cat urls.txt | cariddi -e -ef endpoints_file(搜寻自定义端点)cat urls.txt | cariddi -s -sf secrets_file(搜寻自定义密钥)cat urls.txt | cariddi -ie pdf,png,jpg(扫描时忽略这些扩展名)默认值:在扫描密钥、信息和错误时,会忽略 png、svg、jpg、jpeg、bmp、jfif、gif、webp、woff、woff2、ttf、tiff、tif、mp4、webm、mkv、avi、mov、flv、wmv、mp3、wav、flac、ogg、m4a、aac、ico、cur、eot、otf。
cat urls.txt | cariddi -proxy http://127.0.0.1:8080(设置代理,支持 http 和 socks5)cat urls.txt | cariddi -d 2(每爬取一个页面后等待 2 秒)cat urls.txt | cariddi -c 200(将并发级别设置为 200)cat urls.txt | cariddi -i forum,blog,community,open(忽略包含这些词的 URL)cat urls.txt | cariddi -it ignore_file(忽略包含输入文件中至少一行的 URL)cat urls.txt | cariddi -cache(使用 .cariddi_cache 文件夹作为缓存)cat urls.txt | cariddi -t 5(设置请求超时时间)cat urls.txt | cariddi -headers "Cookie: auth=admin;type=2;; X-Custom: customHeader"cat urls.txt | cariddi -headersfile headers.txt(从外部文件读取自定义请求头)cat urls.txt | cariddi -ua "Custom User Agent"(使用自定义 User Agent)cat urls.txt | cariddi -rua(每次请求使用随机浏览器 User Agent)cat urls.txt | cariddi -plain(仅打印结果)cat urls.txt | cariddi -ot target_name(结果输出到 txt 文件)cat urls.txt | cariddi -oh target_name(结果输出到 html 文件)cat urls.txt | cariddi -json(以 JSON 格式输出到 stdout)cat urls.txt | cariddi -sr(存储 HTTP 响应)cat urls.txt | cariddi -debug(爬取时打印调试信息)cat urls.txt | cariddi -md 3(最大深度为 3 层)cariddi -h 打印帮助。
Usage of cariddi:
  -c int
     Concurrency level. (default 20)
  -cache
     Use the .cariddi_cache folder as cache.
  -d int
     Delay between a page crawled and another.
  -debug
     Print debug information while crawling.
  -e Hunt for juicy endpoints.
  -ef string
     Use an external file (txt, one per line) to use custom parameters for endpoints hunting.
  -err
     Hunt for errors in websites.
  -examples
     Print the examples.
  -ext int
     Hunt for juicy file extensions. Integer from 1(juicy) to 7(not juicy).
  -h Print the help.
  -headers string
     Use custom headers for each request E.g. -headers "Cookie: auth=yes;;Client: type=2".
  -headersfile string
     Read from an external file custom headers (same format of headers flag).
  -json
     Print the output as JSON in stdout.
  -md
     Maximum depth level the crawler will follow from the initial target URL.
  -i string
     Ignore the URL containing at least one of the elements of this array.
  -ie value
     Comma-separated list of extensions to ignore while scanning.
  -info
     Hunt for useful informations in websites.
  -intensive
     Crawl searching for resources matching 2nd level domain.
  -it string
     Ignore the URL containing at least one of the lines of this file.
  -oh string
     Write the output into an HTML file.
  -ot string
     Write the output into a TXT file.
  -plain
     Print only the results.
  -proxy string
     Set a Proxy to be used (http and socks5 supported).
  -rua
     Use a random browser user agent on every request.
  -s Hunt for secrets.
  -sf string
     Use an external file (txt, one per line) to use custom regexes for secrets hunting.
  -sr
     Store HTTP responses.
  -t int
     Set timeout for the requests. (default 10)
  -ua string
     Use a custom User Agent.
  -version
     Print the version.
通常你在浏览器中使用 Burpsuite,因此你只需在浏览器中信任 burpsuite 的证书即可。
为了将 cariddi 与 BurpSuite 代理一起使用,你需要额外执行一些步骤。
如果你尝试使用 -proxy http://127.0.0.1:8080 选项运行 cariddi,你会在 burpsuite 错误日志部分看到以下错误:
Received fatal alert: bad_certificate (or something similar related to the certificate).
为了让 cariddi 与 Burpsuite 正常工作,你还需要在整个电脑中信任该证书,而不仅仅是浏览器。以下是需要遵循的步骤:
转到 Bupsuite 中的 Proxy 选项卡,然后选择 Options。点击 CA Certificate 按钮并以 DER 格式导出证书
openssl x509 -in burp.der -inform DER -out burp.pem -outform PEM
sudo chown root:root burp.pem
sudo chmod 644 burp.pem
sudo cp burp.pem /usr/local/share/ca-certificates/
sudo c_rehash
cd /etc/ssl/certs/
sudo ln -s /usr/local/share/ca-certificates/burp.pem
sudo c_rehash .
来源:Trust Burp Proxy certificate in Debian/Ubuntu
完成这些步骤后,为了将 cariddi 与 Burpsuite 一起使用,你需要:
-proxy http://127.0.0.1:8080 标志的 cariddi。每个版本的详细变更记录在发布说明中。
只需提交一个 issue/pull request。
在提交 pull request 之前,请下载 golangci-lint 并运行
golangci-lint run
如果没有错误,那就继续吧 :)
使用 https://edoardottt.github.io/cariddi-test/ 进行测试
echo "https://edoardottt.github.io/cariddi-test/" | cariddi
帮助我构建这个项目!