findcdn 是一款可以扫描并检测域名所使用的
内容分发网络(CDN)
类型的工具。findcdn 可以将结果保存到文件、作为模块使用,或直接输出到 stdout。
findcdn 帮助工具用户准确判断某个域名正在使用哪种 CDN。支持的域名列表列在仓库中的
cdn_config.py
文件中。该库既可以作为独立工具使用,也可以作为可导入模块用于你的项目。在这两种情况下,结果都可以写入输出文件。
findcdn 需要 Python 3.7+。不支持 Python 2。
findcdn
可以通过 pip 和仓库中的 requirements.txt 文件作为模块安装。
findcdn 可以通过 pip 安装:
pip install --requirement requirements.txt
然后可以直接运行:
findcdn list github.com
或者,你也可以通过以下方式快速安装到任意项目:
pip install git+https://github.com/cisagov/findcdn.git
注意: 建议使用 Python 虚拟环境来安装模块并保持环境干净。如果你希望这样做,在安装该模块之前,你需要 pyenv 和 pyenv-virtualenv 插件。
findcdn file <fileIn> [options]
findcdn list  <domain>... [options]
findcdn (-h | --help)

findcnd -h
findcdn file domains.txt -o output_cdn.txt -t 17 -d
findcdn list dhs.gov cisa.gov -o output_cnd.txt -v
findcdn list cisa.gov
  -h --help                    显示此消息。
  --version                    显示当前版本。
  -o FILE --output=FILE        如果指定,则将在指定值处创建 JSON 输出文件。
  -v --verbose                 包含额外的打印语句。
  --all                        在输出中包含有 CDN 和没有 CDN 的域名。
  -d --double                  运行检查两次以提高准确性。
  -t --threads=<thread_count>  线程数,否则使用默认值。
  --timeout=<timeout>          等待域名完成处理的最长持续时间(秒),否则使用默认值。
  --user_agent=<user_agent>    设置要使用的用户代理,否则使用默认值。
user2@ubuntu:~$ findcdn list asu.edu -t 7 --double
Using 7 threads.
[Pending: 0 jobs]==[Threads: 2]: 100%|███████████████████████████████| 2/2 [00:00<00:00,  2.22it/s]
{
    "date": "06/19/2020, 13:00:38",
    "CDN_count": "1",
    "domains": {
        "asu.edu": {
            "IP": "'104.16.50.14'",
            "cdns": "'.cloudflare.com'",
            "cdns_by_names": "'Cloudflare'"
        }
    }
}
Domain processing completed.
1 domains had CDN's out of 1.
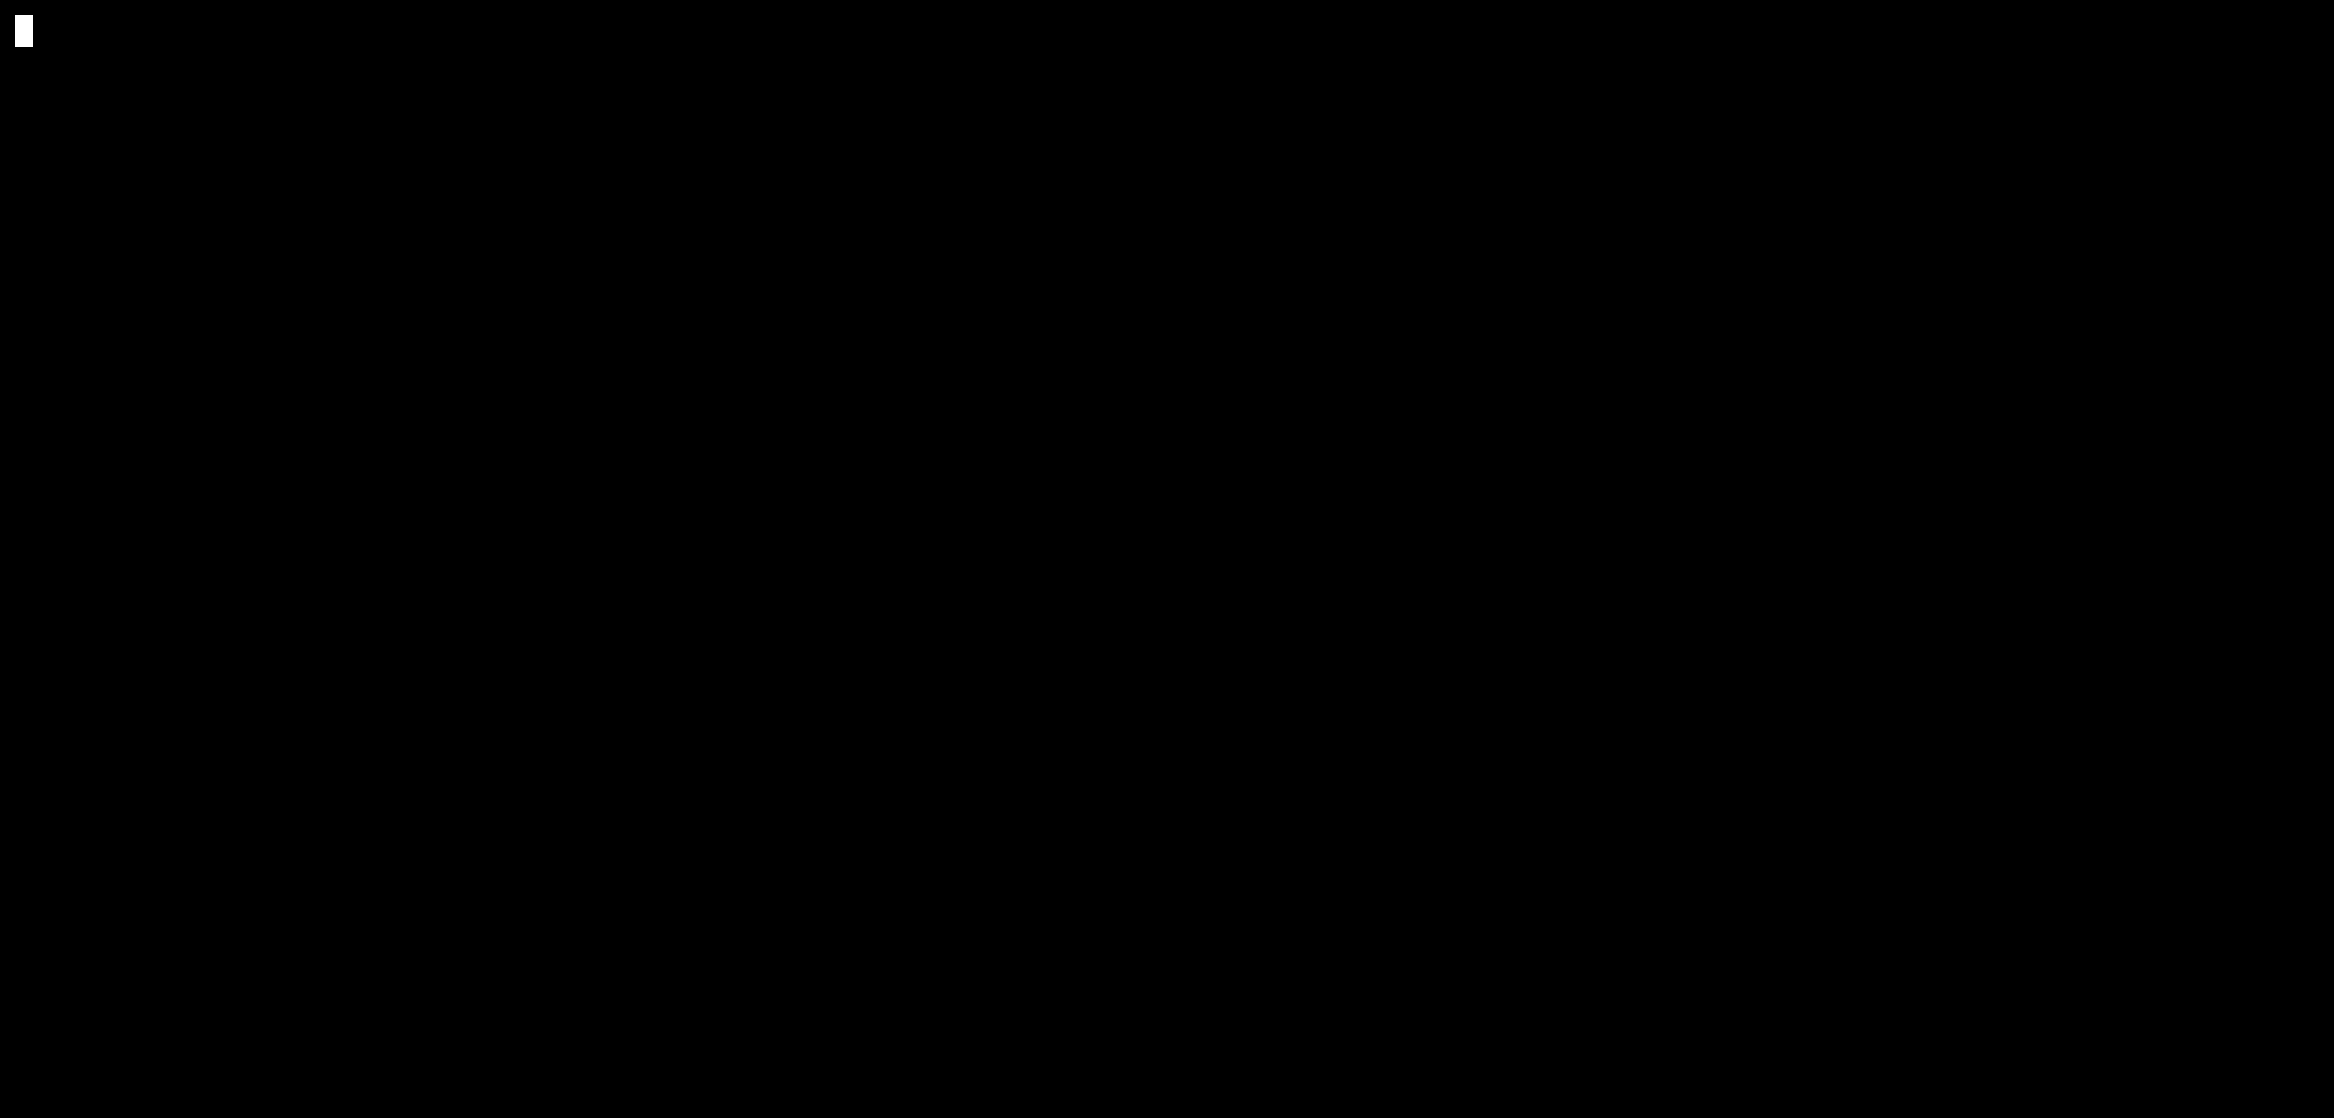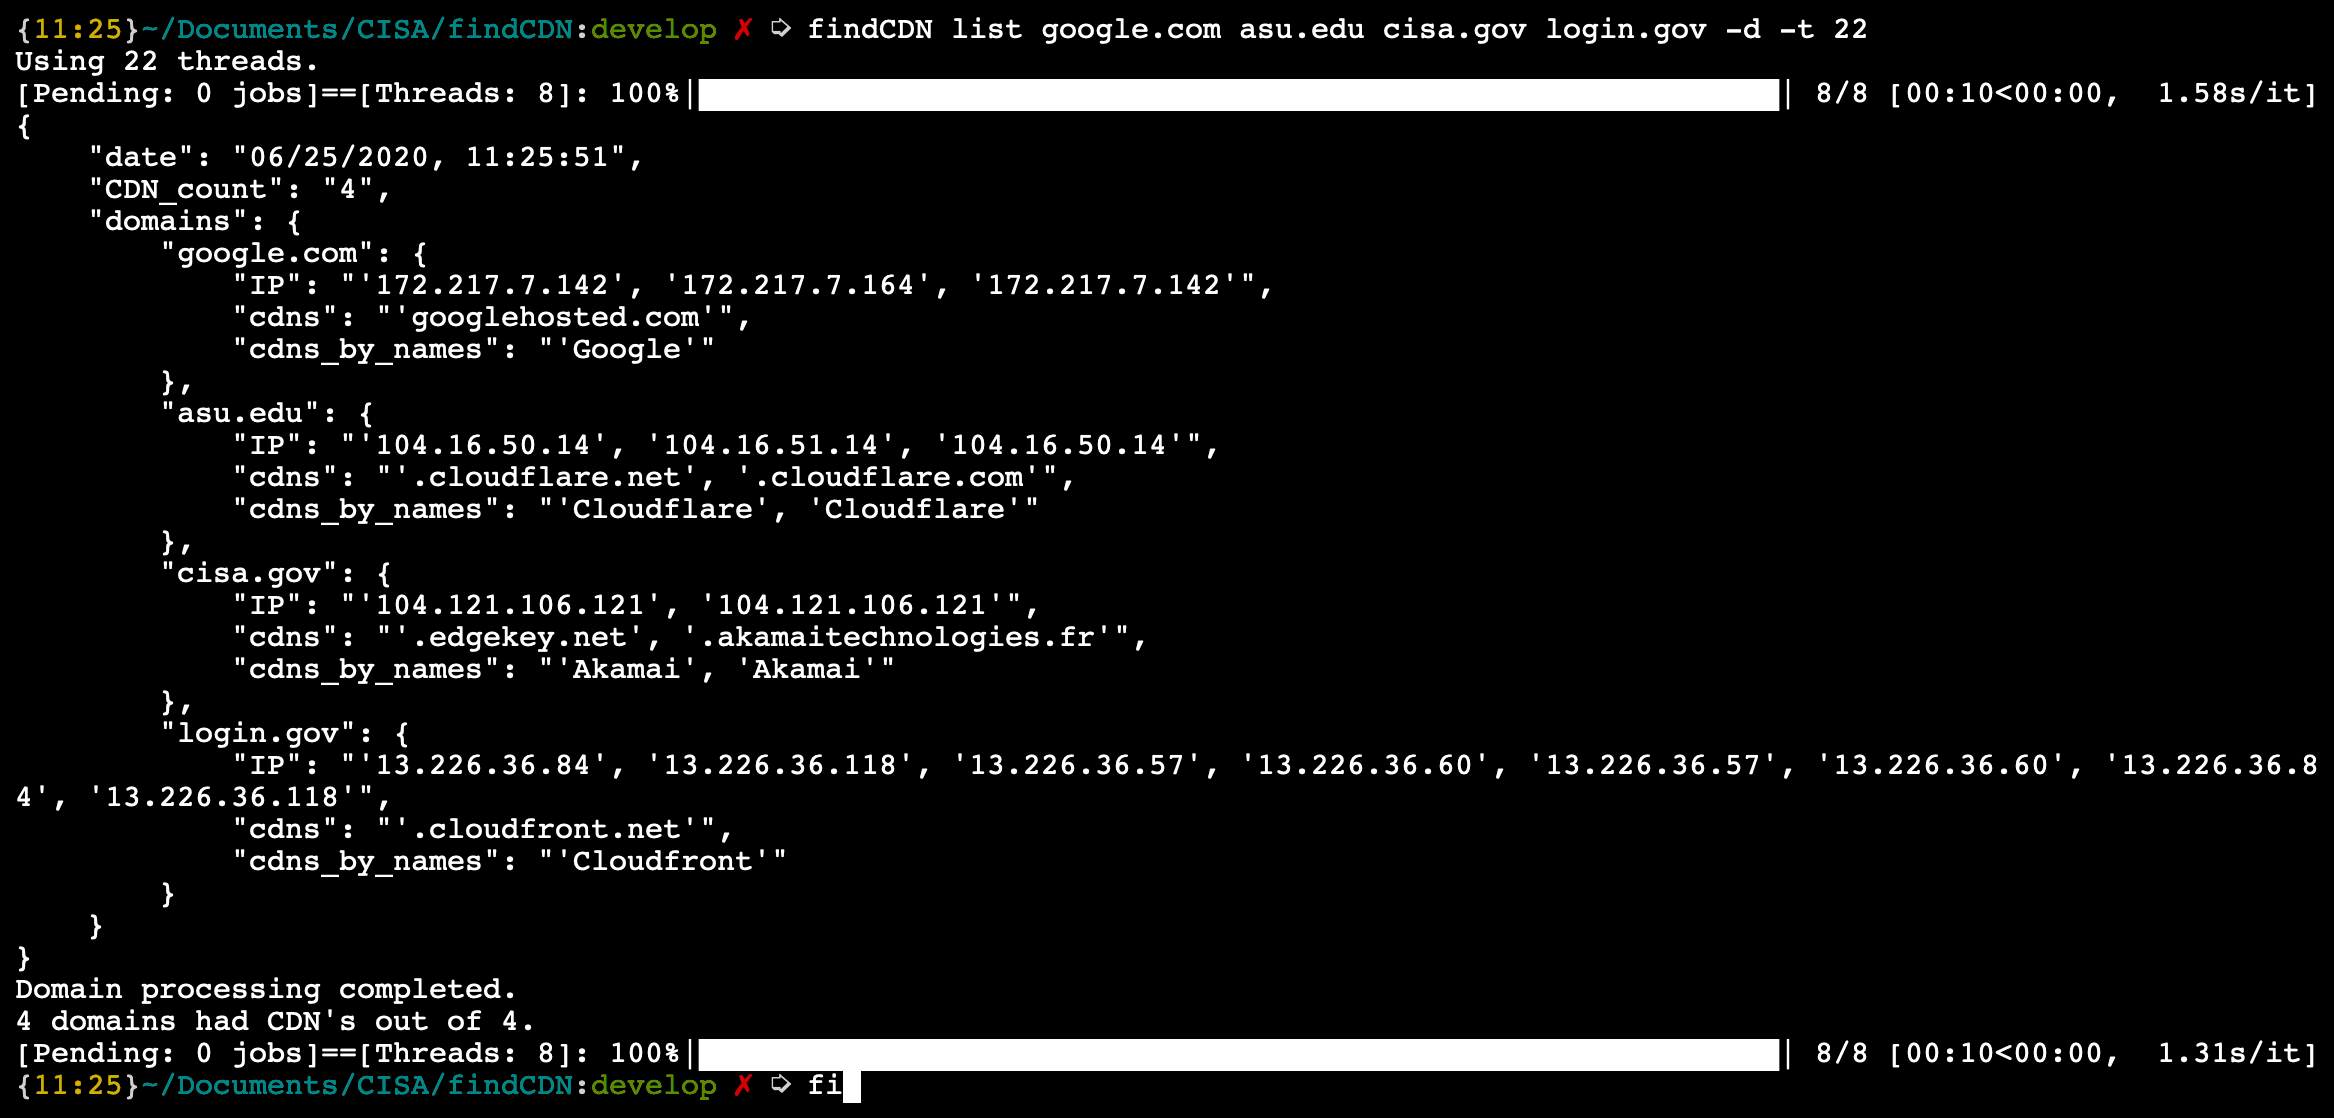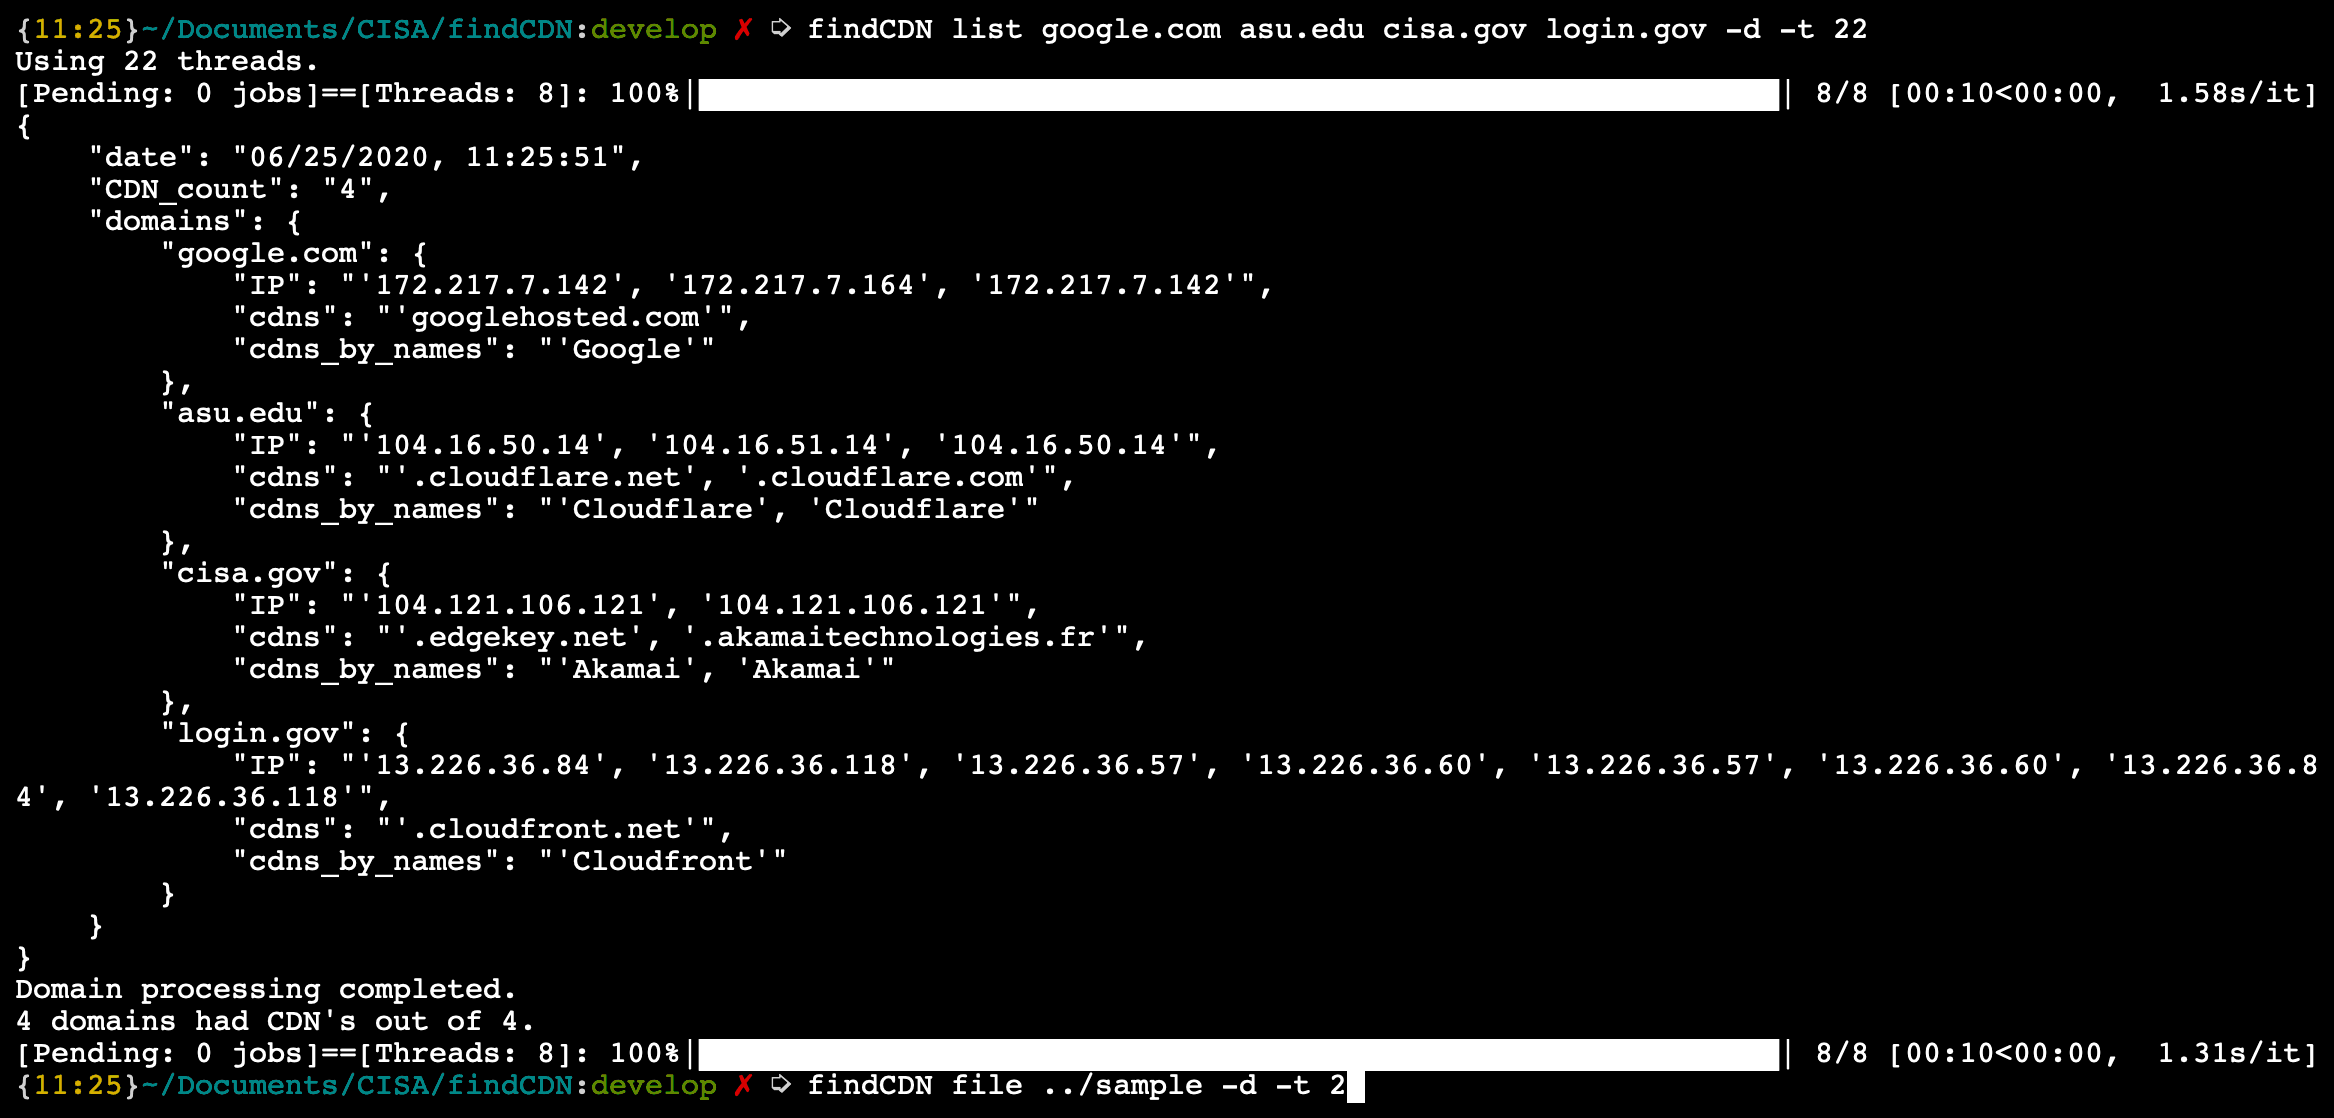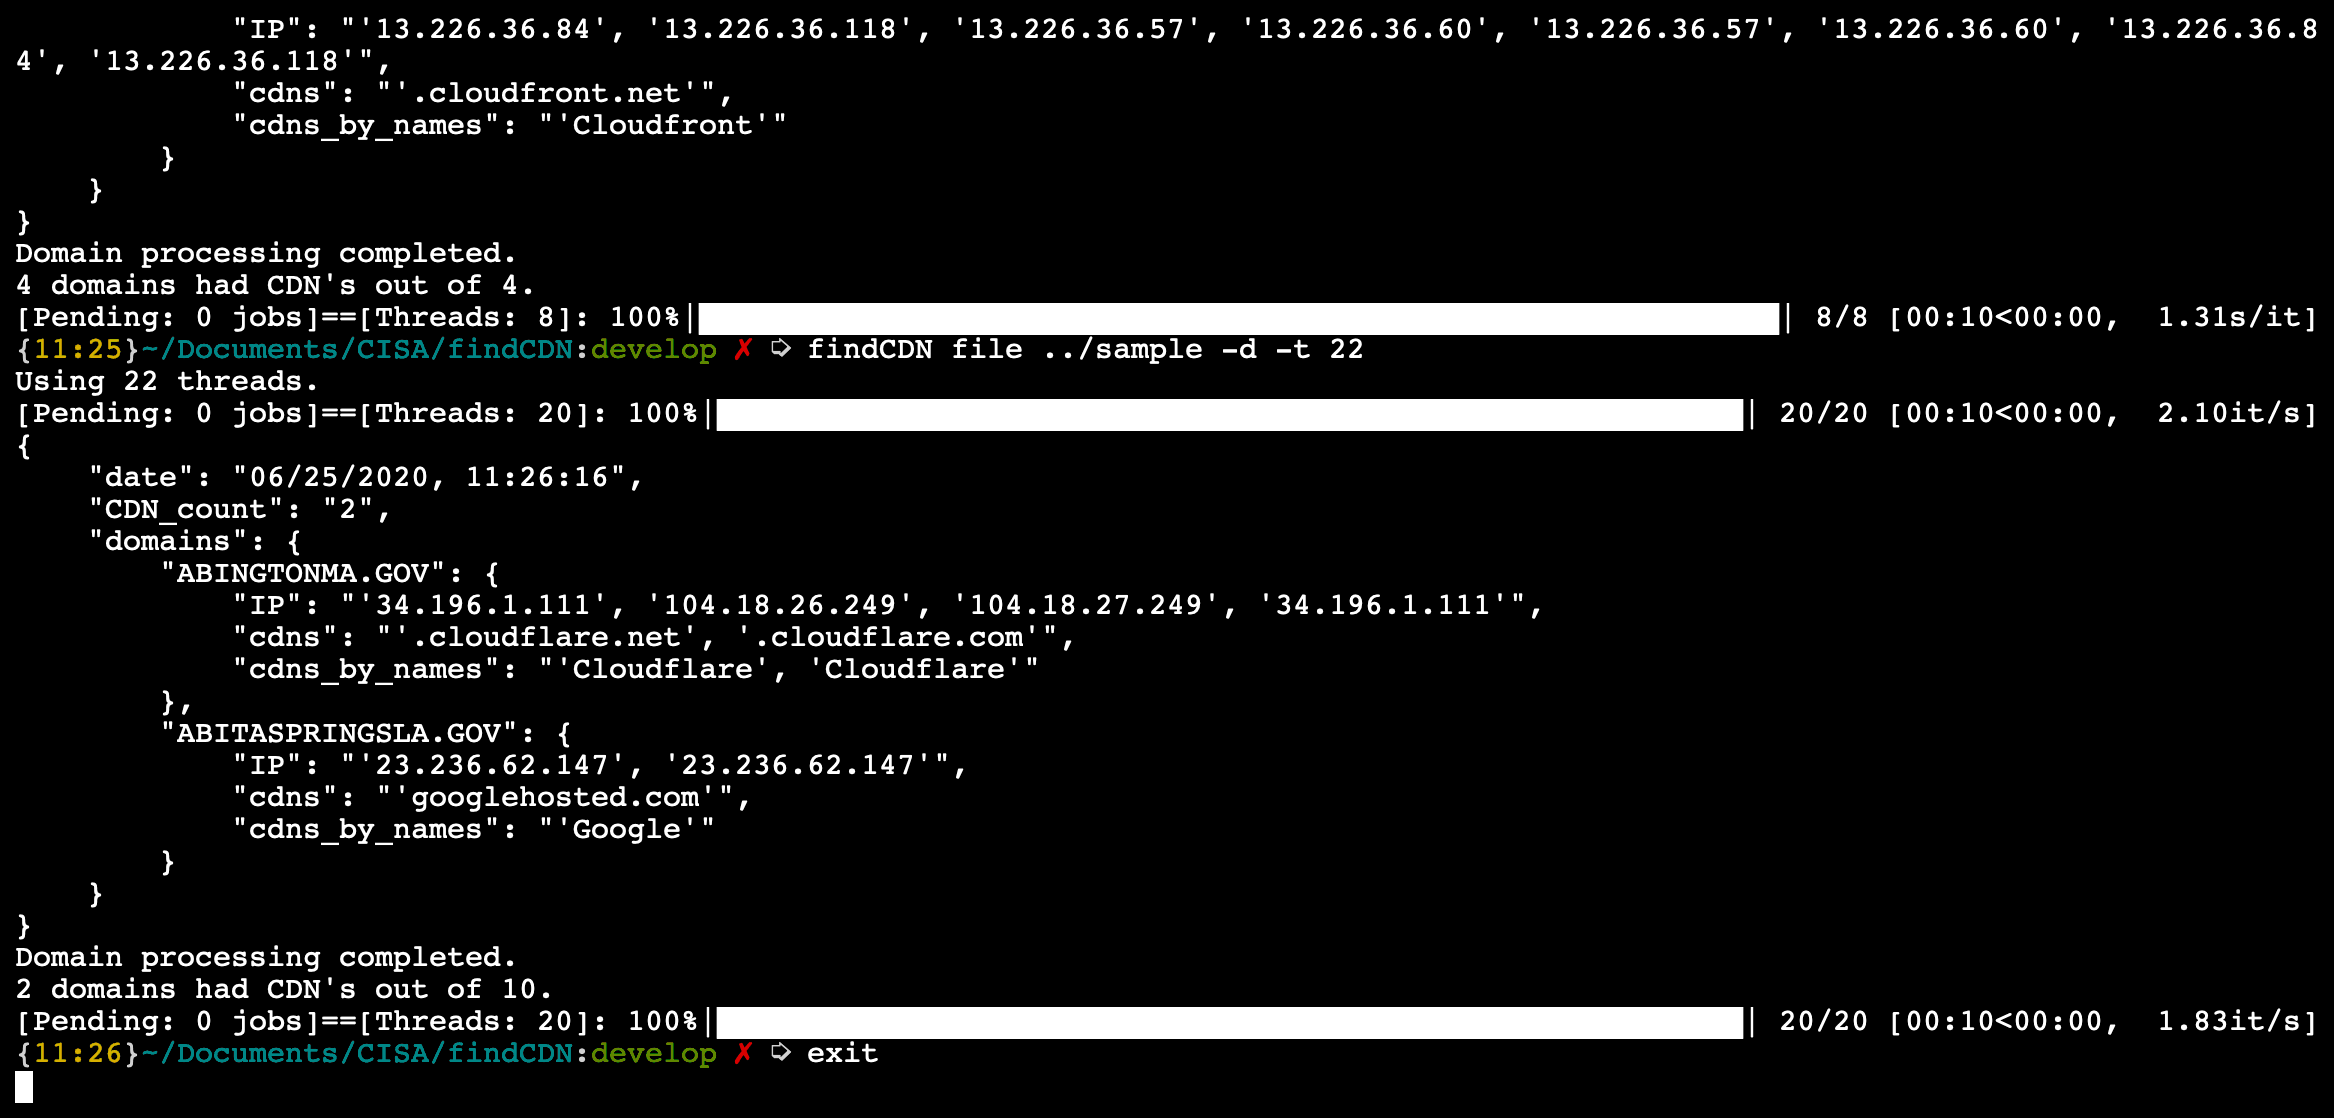
由于 findcdn 可以作为模块安装,其 CDN 检测能力可以在任何项目中调用和实现。首先,将 findcdn 导入你的项目,如上所示。然后,向它传入要分析的域名列表。处理完成后,程序将返回一个 JSON 对象,其中包含输入的域名及其使用的 CDN。
findcdn 的工作方式由传入的选项决定;当前可能的选项和示例写在下面,供你参考:
findcdn.main(
    domain_list: List[str],  # List of domains to search
    output_path: str = None,  # if included, output results to JSON
    verbose: bool = False,  # Verbose mode (more printing!)
    all_domains: bool = False,  # Includes domains that dont have cdn's in the output
    interactive: bool = False,  # Includes a progress bar (normally used for command line)
    double_in: bool = False,  #D ouble the number of tries on a domain to increase accuracy
    threads: int = THREADS,  # Number of threads to use
    timeout: int = TIMEOUT,  # How long to wait on a domain
    user_agent: str = USER_AGENT,  # User Agent to use
)
import findcdn
import json

domains = ['google.com', 'cisa.gov', 'censys.io', 'yahoo.com', 'pbs.org', 'github.com']
resp_json = findcdn.main(domains, output_path="output.json", double_in=True, threads=23)

dumped_json = json.loads(resp_json)

for domain in dumped_json['domains']:
    print(f"{domain} has CDNs:\n {dumped_json['domains'][domain]['cdns']}")
findcdn 分为三个部分:
Chef 将使用 CDN Detection 库获取每个域名的所有 CDNChef 运行分析,在检测到某个域名具有 CDN 时设置布尔值 has_cdn,然后将域名列表返回给运行文件cdn_config.py 中定义的任何 CDN。该工具最初的目的是自动检测使用 CDN 的域名是否可被前置(frontable)。由于前置检测的开销很大,我们将该工具的开发方向调整为专门的 CDN 检测 工具。我们使用我们的 wiki 进一步描述什么是域名前置、我们的研究笔记、设计决策,以及针对特定域名进行前置的操作手册。如果你发现任何其他可前置的域名或当前操作手册中的任何缺陷,请考虑贡献!
更多信息位于 我们的 wiki 页面。我们鼓励你提出功能请求或贡献任何你希望添加到项目或 wiki 中的内容。
这可以是以下任何内容:
我们欢迎贡献!详情请参见 CONTRIBUTING.md。
该项目属于全球范围内的公有领域。
该项目在美国境内属于公有领域,并且通过 CC0 1.0 通用公有领域 奉献,在全球范围内放弃该作品的版权及相关权利。
对本项目的所有贡献都将根据 CC0 奉献发布。提交 pull request 即表示你同意遵守 该版权权益放弃条款。