 squid-protocol1/gitgalaxy
AST-free heuristic knowledge graph engine for deep repository intelligence and zero-trust security scanning. Integrates as a GitLab CI/CD component, blocks hostile code, and exports SARIF telemetry to the GitLab Security Dashboard.

Repository-scale structural intelligence without compilation.
Docs · Visualizer · Language Crucible · Keyword Rosetta · Raw Output
1 scan · 97 structural signals · 50+ languages · no compilation · 17 risk-exposure categories · 6 outputs
GitGalaxy builds a language-agnostic structural graph of an entire repository directly from source text — no build, no per-language toolchain.
It is designed for repositories that are polyglot, partially broken, legacy, vendor-heavy, or otherwise difficult to analyze through a build-first workflow:
Go + C++ + Python + Java + Bash + YAML
+ generated code + vendored code + legacy code
+ half-migrated modules + broken dependencies
Instead of a separate parser per language, GitGalaxy extracts a common vocabulary of structural signatures — functions, classes, arguments, control flow, state mutation, I/O, APIs, dependencies — and normalizes them into one deterministic repository model that feeds architecture analysis, risk-exposure prioritization, SBOM generation, refactoring and ownership analysis, AI-oriented codebase context, and CI/CD gates.
Central thesis: complete language parsing is not always necessary to recover highly useful structural information at repository scale.
How that thesis is tested — against Tree-sitter and Ctags, against a planted control corpus, and next against Git history — is summarized in Accuracy, measured below and laid out in full in the validation program.
One command:
pip install gitgalaxy
galaxyscope path/to/repo
Six coordinated views of the same deterministic scan:
| Output | Purpose |
|---|---|
| LLM architecture brief | Compact machine/agent-oriented context (below) |
| SARIF | CI/security dashboard integration |
| CycloneDX SBOM | Dependency inventory/compliance |
| SQLite | Queryable repository knowledge graph |
| JSON audit data | Forensic/automation workflows |
| 3D visualization data | Interactive repository topology |
The flagship report is a single Markdown brief built to hand an engineer — or an AI agent — a working mental model of a repository they've never seen. It is a self-contained package: the risk equations are printed in the report itself, and an embedded interpretation prompt lets any LLM narrate it without hallucinating what the numbers mean. Sections cover macro state and language composition, network topology (modularity, articulation points, cyclic density), dependency choke points, the heaviest functions and files, per-file structural signatures with PageRank blast radius, targeted and cumulative risk hitlists, supply-chain audits, and refactoring targets ranked by volatility and authorship centralization — plus an itemized list of every file it refused to scan, and why.
Two examples, scanned 2026-08-31 with the current engine. Both repositories
are public — clone either and run galaxyscope --llm-only <path> to reproduce
the full brief:
curl — 4,250 artifacts, 696 scanned, 112,653 LOC across C, Perl, Python,
Shell, M4 and Makefile. The brief ranks src/tool_setup.h as the top
structural pillar (80 inbound connections) and puts a Perl function —
APPEND_imap in tests/ftpserver.pl, Impact 2135, 1,672 LOC — at the top of
the repo-wide function hitlist, in the same ranking as the C code. That
cross-language graph is the product: one comparable signal set across every
language in the repo. The honest caveat in the same brief: only 16.4% of
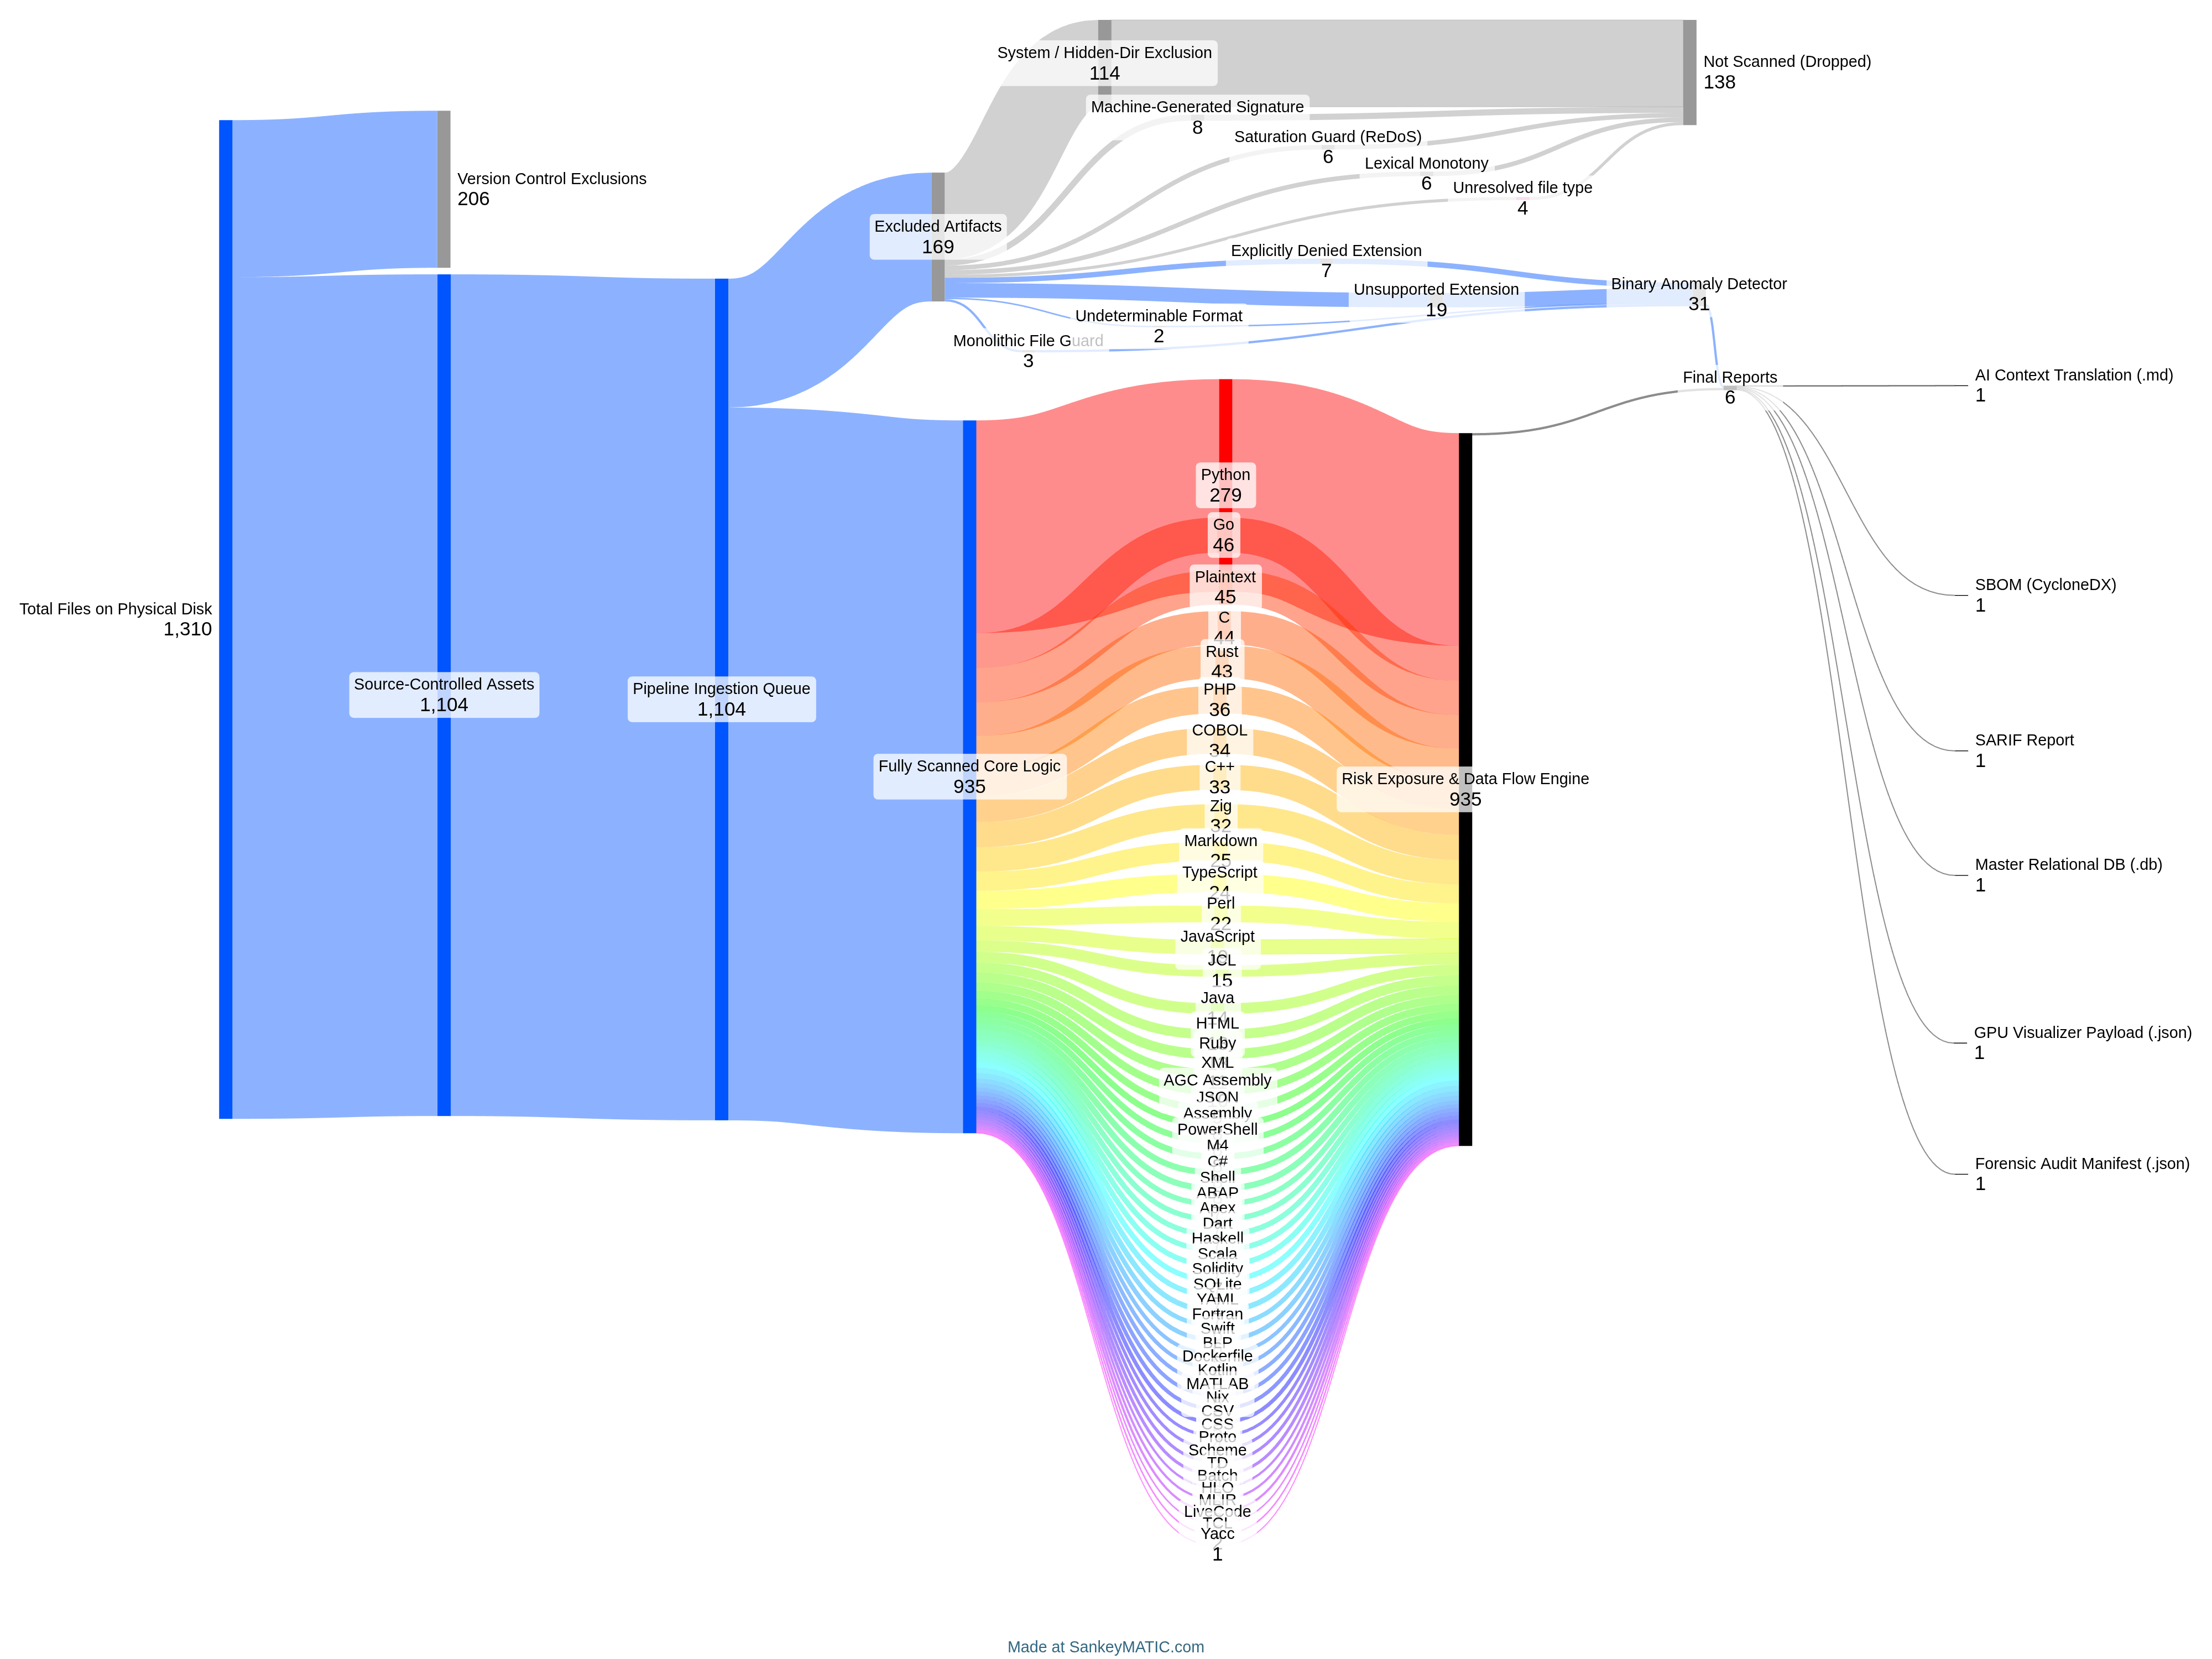
artifacts were scanned — the ingestion filter drops binaries, generated code
and test data aggressively, and §5 of the brief itemizes every exclusion by
extension and reason.
cics-genapp (IBM's CICS COBOL/DB2 sample) — 92.1% scanned: 44 COBOL
programs, 29 JCL jobs. The cumulative structural-surface hitlist leads with
base/src/lgupdb01.cbl (mutation surface ~100%, complexity load 92%), and the
heaviest paragraph in the repo is UPDATE-POLICY-DB2-INFO — the SELECT FOR UPDATE row-locking logic, which is exactly where a maintainer of that program
would want to look first. The same brief also shows a limitation plainly: on a
flat architecture with no real import graph, the "structural pillars" list
degenerates to zero-connection files, and the report says to check the
connection counts before trusting it.
Hundreds of unedited briefs for independently selected repositories are
committed at
gitgalaxy-raw-output;
this repo's own always-current self-scan brief is at
docs/gitgalaxy_architecture_brief.md.
| Consumer | Question |
|---|---|
| Architecture | What is this repository made of? |
| Structural analysis | Where are the functions, classes, APIs, dependencies and control structures? |
| Structural Surface Profile (formerly Risk exposure) | Where is a given structural/content pattern concentrated? |
| Refactoring | Which files are complex, high-churn or load-bearing? |
| Supply chain | What dependencies physically exist on disk? |
| AI context | What architecture and relationships should an agent know? |
| Legacy migration | Where are the structural units to transform? |
| Historical analysis | How does measured exposure change as the repository evolves? |
Two standing measurement programs back the claims above, and a third, for the dependency and call graphs, is in progress. The full narrative — methodology, verdicts, limits, and what comes next — lives in the validation program; this is the summary.
GitGalaxy is benchmarked against Tree-sitter and Universal Ctags on the pinned Language Crucible corpus — 24 of 45 languages get all three tools, 13 more get two, and every disagreement is investigated against real source and recorded with a verdict (200 of 201 logged discrepancy shapes validated). On that corpus, GitGalaxy's validated function precision is 100% across all 31 tree-sitter-comparable languages, and it is never the tool found wrong in a validated class or argument disagreement. The limit: three structural targets, one fixed corpus — not "parses as accurately as an AST" in general.

Blast radius, PageRank and the "structural pillars" come from the import graph. The function-level rankings come from the call graph. Neither graph is measured in every language yet, and the chart below says which ones are:
