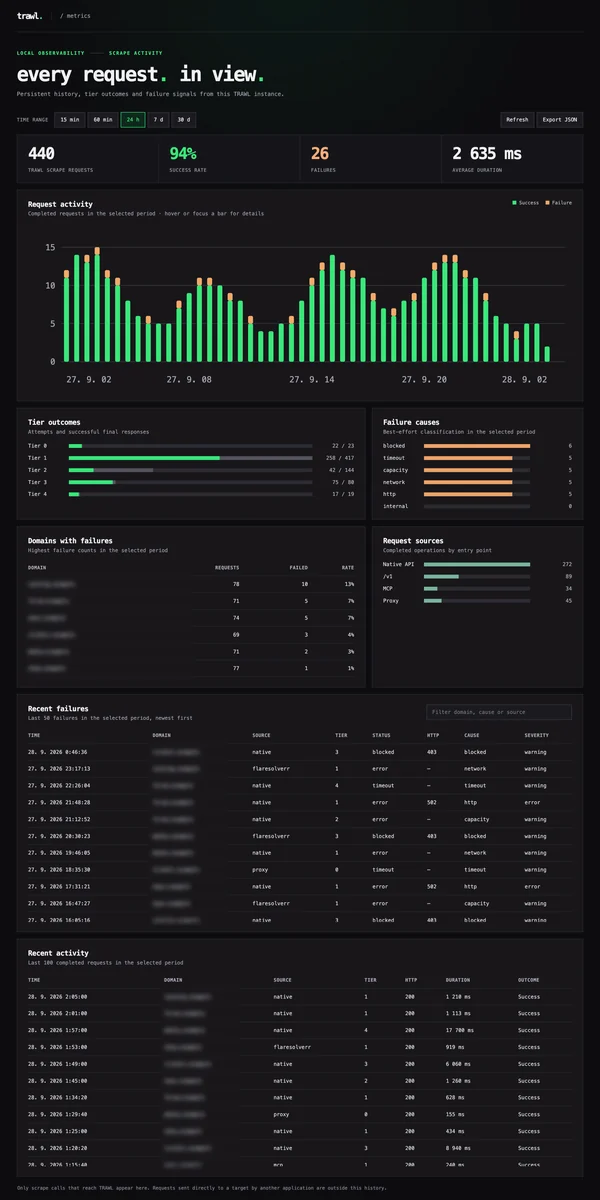
 germondai/trawl
Self-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr alternative and drop-in replacement for your *arr stack.

Self-hosted web scraping for applications and AI agents. Get page content through an API or MCP, with built-in handling for supported browser challenges and CAPTCHAs.
TRAWL starts with HTTP, reuses verified clearance and opens Camoufox when a browser is needed. Repeat requests fetch fresh content without repeating a full solve whenever the site accepts the saved session.
HTTP + supported PoW walls → cached browser session → fresh browser solve → residential proxy
The HTTP tier can clear supported ALTCHA and Friendly Captcha v1 access forms with bounded local computation. Ordinary embedded widgets keep their browser lifecycle. Coverage and limits.
Website · Documentation · Latest release
/scrape, the FlareSolverr-compatible /v1 endpoint, or a challenge-aware HTTP/HTTPS proxy with WebSockets and Range support.
|
Bright Data - The most powerful platform for Web Unlocker, SERP API and web scraping tools. Why Bright Data? • Web Unlocker - bypass any anti-bot protection • SERP API - real-time Google, Bing & more results • Scraping Browser & dedicated scrapers • Massive residential proxy network • Built for scale and reliability Get started for free with Bright Data! |
|
NodeMaven - The most efficient proxy provider for Web Scrapping and Automation with the Highest Quality IP on the market. Why NodeMaven? • ZIP targeting • 99.9% uptime • IP filtering: all proxies have fraud score <97% • No KYC required • Unique free tools: Proxy Bandwidth Checker, Meta Tag Checker, IP Lookup and others! Special codes for TRAWL users: • TRAWL35 - 35% off to Mobile and Residential Proxies• TRAWL40 - 40% off to ISP (Static) Proxies• TRAWL2X - 2X traffic for Black Friday
|
|
Thordata - Residential Proxies & Web Data APIs Give TRAWL reliable upstream access with 100M+ residential IPs across 190+ countries, including city and ASN targeting. Why Thordata?• Residential Proxies: rotating and sticky sessions for scraping and browser automation • SERP API: structured Google, Bing, and other search results for research workflows • Web Scraper API: collect public web data through a simple API TRAWL users: • Start with free trial traffic and get 10% off with code TRAWL10
|
Selected same-machine comparisons show faster first and repeat responses than FlareSolverr and Byparr on the default Cloudflare workload:
| Protected page | Best first | Best repeat |
|---|---|---|
| NopeCHA Cloudflare demo | 6.0 s | 879 ms |
| 1337x | 3.8 s | 85 ms |
| EZTV | 4.6 s | 473 ms |
Measured 2026-10-17 on a development build after v1.8.0. These are verified minima from the recorded sample. First requests used a warm browser with an empty target cache; repeats are fresh fetches with reusable clearance. Results vary by site, IP and session state.
Full comparison, medians and CPU/RAM · Method · Performance guide · Low-resource setup
Run one browser with MCP, an in-memory clearance cache and persistent dashboard history:
