
Nuevo releaseSep 19, 2026
urx v0.11.0
Extrae URLs de archivos OSINT para obtener información de seguridad.
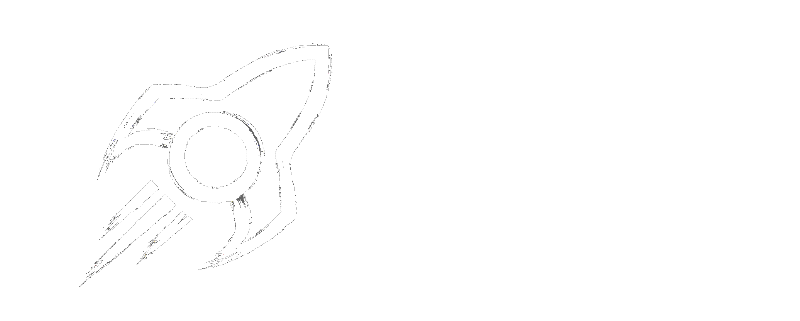
Extrae URLs de archivos OSINT para obtener información de seguridad.



Urx recopila las URLs de un dominio a partir de archivos OSINT como Wayback Machine y Common Crawl. Consulta todas las fuentes en paralelo y luego filtra, prueba y formatea los resultados para tareas de seguridad.
Características
- Fuentes sin clave: Wayback Machine, Common Crawl, OTX, Arquivo.pt, URLScan (anónimo)
- Fuentes con clave y rotación de claves: VirusTotal, URLScan, ZoomEye, GitHub Code Search, BeVigil (URLs de aplicaciones Android)
- Cualquier otro servidor CDX (pywb, OutbackCDX, archivos nacionales) mediante
--cdx-endpoint - Filtros del lado del archivo (
--from/--to,--archive-status,--archive-mime) que se ejecutan dentro de la consulta CDX - Filtros de metadatos del lado del cliente (
--meta-*) sobre fecha de captura, tipo MIME y estado, para todos los proveedores - Objetivos con alcance de ruta (
urx example.com/shop) y archivos de alcance de bug bounty (--scope-file) - Filtros por extensión, subcadena, regex (
--match-regex,--filter-regex) y presets (no-images,only-js,only-secrets,only-backup,only-config,only-api) - Normalización y deduplicación:
--normalize-url,--merge-endpoint,--dedup-similar - Salida en texto plano, JSON, JSON Lines, CSV o
wordlist;--streamescribe las URLs a medida que llegan - Vistas de parámetros:
--params,--params-by-endpoint,--fuzz-placeholder FUZZpara ffuf o dalfox - Metadatos de captura por URL:
first_seen,last_seen,mime,archive_status,digest - Entrada desde WARC, URLTeam y archivos de texto (
--files) o stdin - Pruebas en vivo:
--check-status,--check-title,--extract-links,--extract-js-endpoints - Cuerpos archivados:
--archive-bodyextrae enlaces de páginas que ya no existen, una solicitud por cuerpo distinto;--archive-body-dirlos conserva - Expansión de especificaciones de API (
--expand-specs): OpenAPI 3.x, Swagger 2.0, introspección de GraphQL - Versiones archivadas de robots.txt y sitemap.xml (
--archived-discovery) - Solicitudes autenticadas al objetivo (
-H,--cookie,--user-agent), nunca enviadas a los archivos - Caché SQLite o Redis (Redis requiere una compilación con
--features redis-cache), escaneos--incremental, mantenimiento conurx cachey webhooks--notify
Instalación
cargo install urx       # https://crates.io/crates/urx
brew install urx        # https://formulae.brew.sh/formula/urx
yay -S urx              # AUR
choco install urx       # Chocolatey (Windows)
Desde el origen (binario en target/release/urx):
git clone https://github.com/hahwul/urx.git
cd urx
cargo build --release
Docker (ghcr.io/hahwul/urx). La imagen no tiene entrypoint, así que coloca ./urx después del nombre de la imagen:
docker run --rm ghcr.io/hahwul/urx:latest ./urx example.com
Los binarios precompilados para Linux, macOS y Windows, cada uno con un .sha256, están en la página de releases.
Autocompletados de shell (bash, zsh, fish, powershell, elvish) y la página de manual:
urx --completions zsh > ~/.zfunc/_urx        # ~/.zfunc must be on $fpath
urx --completions bash > ~/.local/share/bash-completion/completions/urx
urx --completions fish > ~/.config/fish/completions/urx.fish
urx --manpage > ~/.local/share/man/man1/urx.1
Uso
Uso básico
urx example.com                 # one domain
urx example.com example.org     # several domains
cat domains.txt | urx           # domains from stdin
Opciones
Usage: urx [OPTIONS] [DOMAINS]... [COMMAND]

Commands:
  cache  Inspect and maintain the URL cache: stats, list, prune, drop <DOMAIN>..., clear

Arguments:
  [DOMAINS]...  Domains to fetch URLs for

Options:
  -c, --config <CONFIG>           Config file to load
      --provider-config <PATH>    Separate provider config file holding only API keys (default: ~/.config/urx/provider-config.toml; %APPDATA%\urx\ on Windows). CLI/env > provider-config > main config.
      --completions <SHELL>       Print a shell completion script (bash, zsh, fish, powershell, elvish) to stdout and exit
      --manpage                   Print the roff man page to stdout and exit
  -h, --help             Print help
  -V, --version          Print version

Input Options:
      --files <FILES>...        Read URLs directly from files (supports WARC, URLTeam compressed, and text files)
      --domain-list <PATH>      File of newline-separated domains to scan (repeatable; merged with positional DOMAINS; stdin is read only when they name no domains; `#` comments allowed) [alias: --dL]

Output Options:
  -o, --output <OUTPUT>          Output file to write results
      --output-dir <PATH>        Write one file per URL host into this directory (extension matches --format). Coexists with --output / stdout. [alias: --oD]
  -f, --format <FORMAT>          Output format: "plain", "json" (one array), "jsonl" (one JSON object per line), "csv", "wordlist" (path segments and parameter names, deduplicated and sorted); anything else is a usage error [default: plain]
      --stream           Write URLs as each provider reports them instead of once at the end (unsorted; bypasses cache; rejects options needing the full result set)
      --merge-endpoint   Merge endpoints with the same path and merge URL parameters
      --normalize-url    Normalize URLs for better deduplication (sorts query parameters, removes trailing slashes)
      --dedup-similar    Collapse URLs that differ only in variable data (numeric ids, UUIDs, hashes, dates, query values)
      --params           Replace the URL list with every query parameter name the run saw, once each
      --params-by-endpoint
                         One line per endpoint: the endpoint and the comma-separated union of the parameter names seen on it (id-looking path segments collapse to `{id}`)
      --fuzz-placeholder <VALUE>
                         Replace every query parameter value with VALUE, keeping one URL per parameter signature — output you can feed straight to ffuf or dalfox