
HDI-GraphRAG-Attack
 jisung-pacific/hdi-graphrag-attack
Research implementation of Hop-Decayed Influence (HDI) and the 3S attack framework, exposing structural auxiliary indexing vulnerabilities in…
adversarial-attackai-securitydata-exfiltration+3
5
jisung-pacific/hdi-graphrag-attackResearch implementation of Hop-Decayed Influence (HDI) and the 3S attack framework, exposing structural auxiliary indexing vulnerabilities in…
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…
 josh-blythe/bordair-detector
Two-stage prompt-injection and jailbreak detector: regex gates plus a quantised DeBERTa-v3 ONNX classifier, with image, document, and audio support.…
 mthamil107/db_audit_research
Self-Defeating Audits: reproducible lab showing a low-privilege PostgreSQL role reversibly blinding a trigger-based auditor + poisoning attribution…
 pedrobarcha/memory-injection
Research on persistent prompt injections via memory features in Claude, Gemini, and ChatGPT, with reproduction steps, datasets, and proofs for…
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…
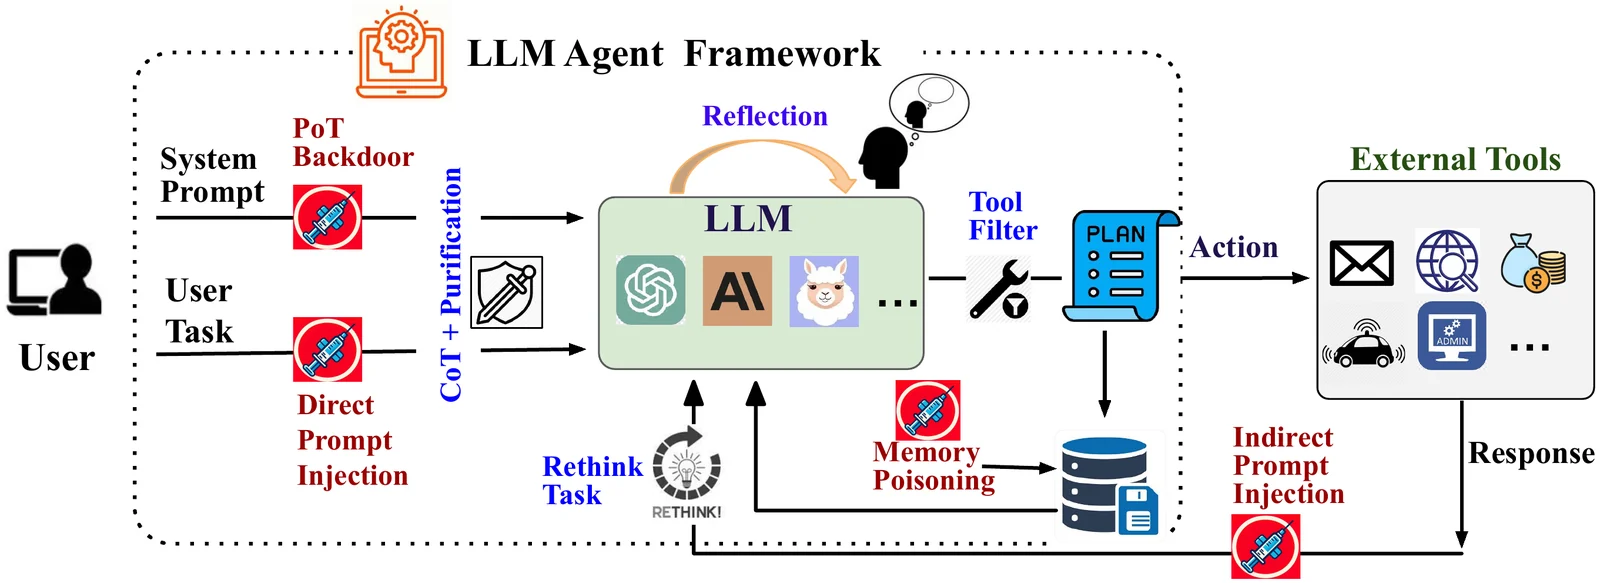 xiaoyan-lisa/defenses-for-tool-integrated-llm
Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense…
 suels-group/beyond_asr
Research code for measuring jailbreak attack success rates (ASR and stepwise ASR) against LLMs, with implementations of attacks such as GCG and…
 thuname/ted
Research artifact from USENIX Security 2026 demonstrating DDoS attacks by abusing tunnel nodes and IPv6 extension headers, with accompanying analysis…
 pixee/compaction-laundering
Security research on context compaction in coding agents: shows how forged role labels in untrusted content survive summarization and get executed,…
 trusted-ai/aix360
Interpretability and explainability of data and machine learning models
 helviojunior/hookchain
HookChain: A new perspective for Bypassing EDR Solutions
 0xsojalsec/uncensored-ai
Fully automatic censorship removal for language models
 gmh5225/awesome-ai-security
A curated list of AI Security materials and resources for Pentesters, Bug Hunters, and Security Researchers.
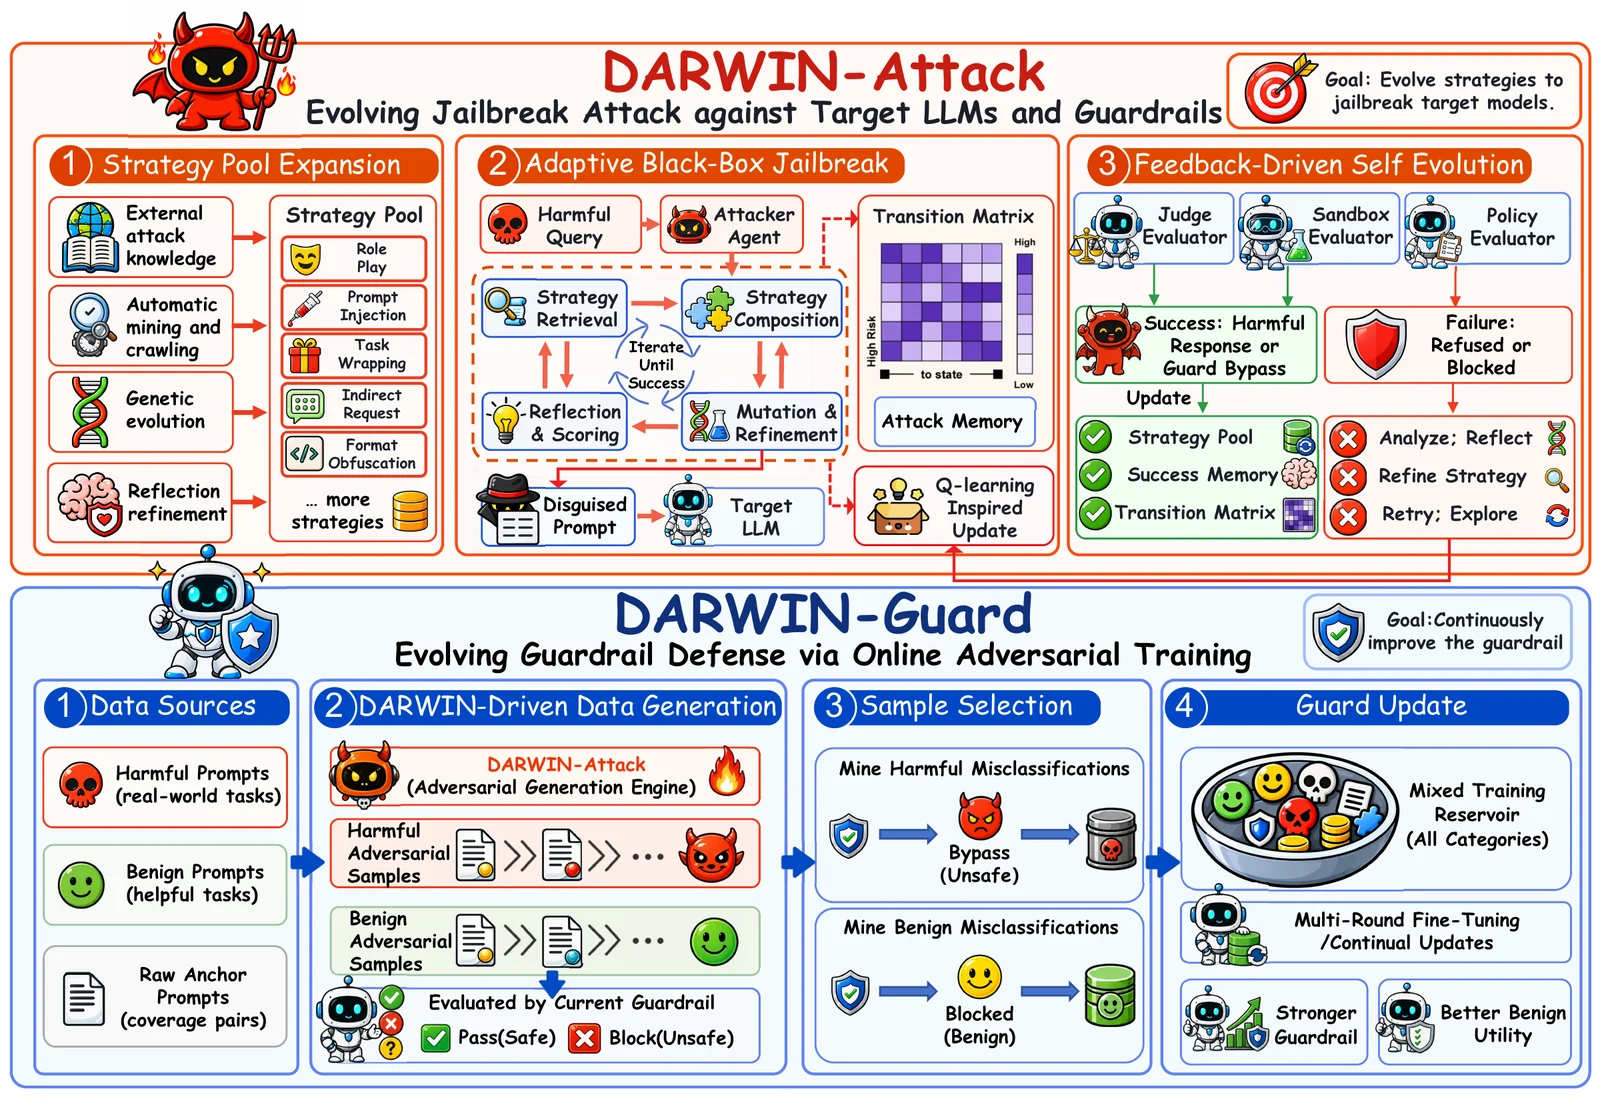 zju-llm-safety/darwin
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…
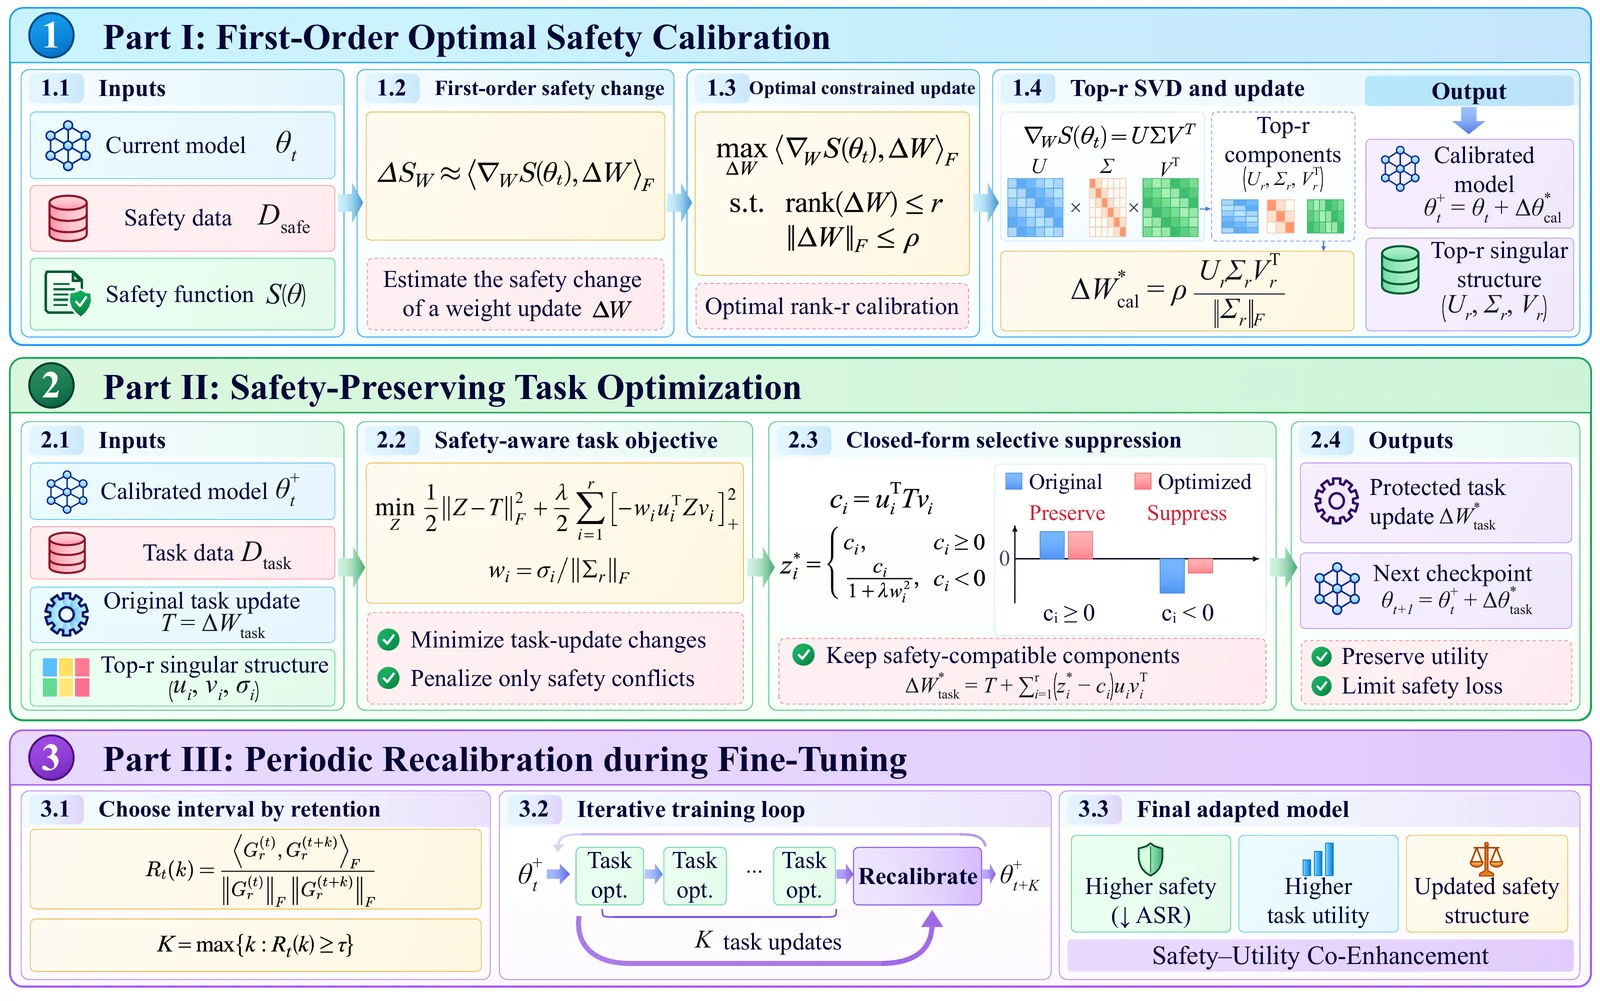 zju-llm-safety/ascent
Fine-tuning framework that applies first-order optimal safety calibration and periodic recalibration to LLMs, preserving safety-compatible updates…

 lsudoko/antibody
GitLab Duo DevSecOps loop where a second AI re-attacks every AI-written fix, saving each successful bypass as a permanent antibody replayed in CI and…
 jiep/offensive-ai-compilation
A curated list of useful resources that cover Offensive AI.