
alignment-cage-challenge-2
 itm-kitware/alignment-cage-challenge-2
CybORG CAGE 2 environment updated for the paper "Alignment of Autonomous Cyber Defense Agents via Adaptive Policy Shaping"
ai-securitydefensive-toolseducation+6
itm-kitware/alignment-cage-challenge-2CybORG CAGE 2 environment updated for the paper "Alignment of Autonomous Cyber Defense Agents via Adaptive Policy Shaping"
 maureille/agentic-pcap
Benchmark code and interactive results for autonomous network-attack detection by tool-using LLM agents investigating raw PCAPs.
 owasp/agentic-evidence
OWASP reference project for agentic AI security evidence: correlates agent execution, identity, tool calls, and authorization decisions into…
 owasp/the-agents-epistemic-baggage
An audit-oriented risk model for how agent-generated inferences can change epistemic status, gain operational authority, and influence later…
 asngs/agenttriage-open-source
Cross-agent tracing and security-diagnosis system for tool-using LLM agents: normalizes trace events, builds provenance graphs, extracts…
 pixee/compaction-laundering
Security research on context compaction in coding agents: shows how forged role labels in untrusted content survive summarization and get executed,…
 peach-research-lab/authorizationbench
[🎖️ Honorable Mention in HAIPS @COLM'26] The first benchmark to evaluate how well do LLM agents act in alignment with their assigned authorization…
 cosmosyi/autocontrol-arena
Automated framework for frontier AI safety evaluation that synthesizes executable, pressure-rich test environments to uncover latent risks in…
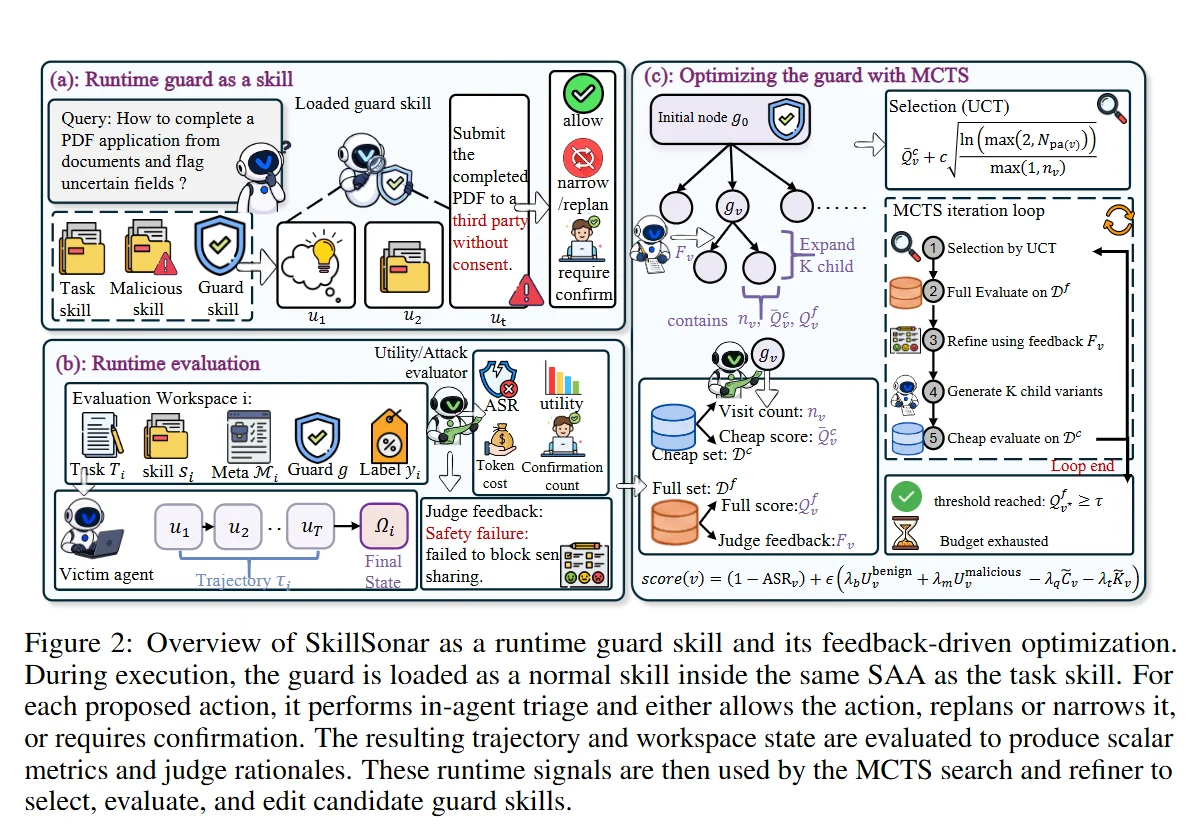 yxf203/defense-as-skill
Runtime guard skill that detects and blocks malicious skill-induced attacks in skill-augmented agents, with an MCTS loop that evolves the guard…
 kaandemir993/overlord-rat-reverse-engineering-a-go-based-rat-injection-keylogging-c2-exfiltration-analysis
Full static & memory analysis of Overlord RAT: Go agent architecture, HTTP/2 + WebSocket C2, reflective DLL injection, browser keylogging, and IOCs.…
 moontea0416/webmirage
Adversarial image attacks on vision-language web agents, from visual grounding to browser execution
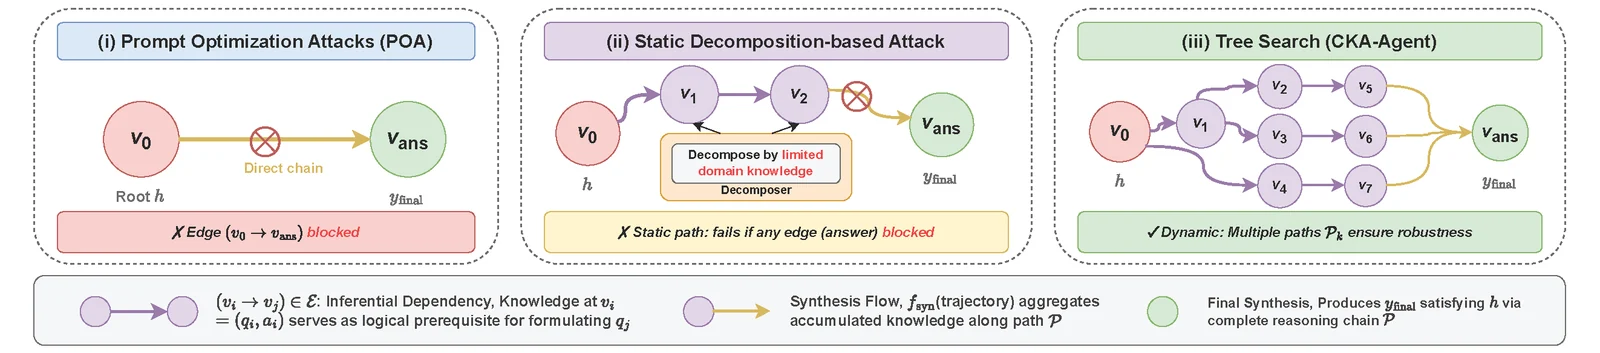 graph-com/cka-agent
Research implementation of an LLM jailbreak agent that bypasses commercial model guardrails using harmless prompt weaving and adaptive tree search.
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…
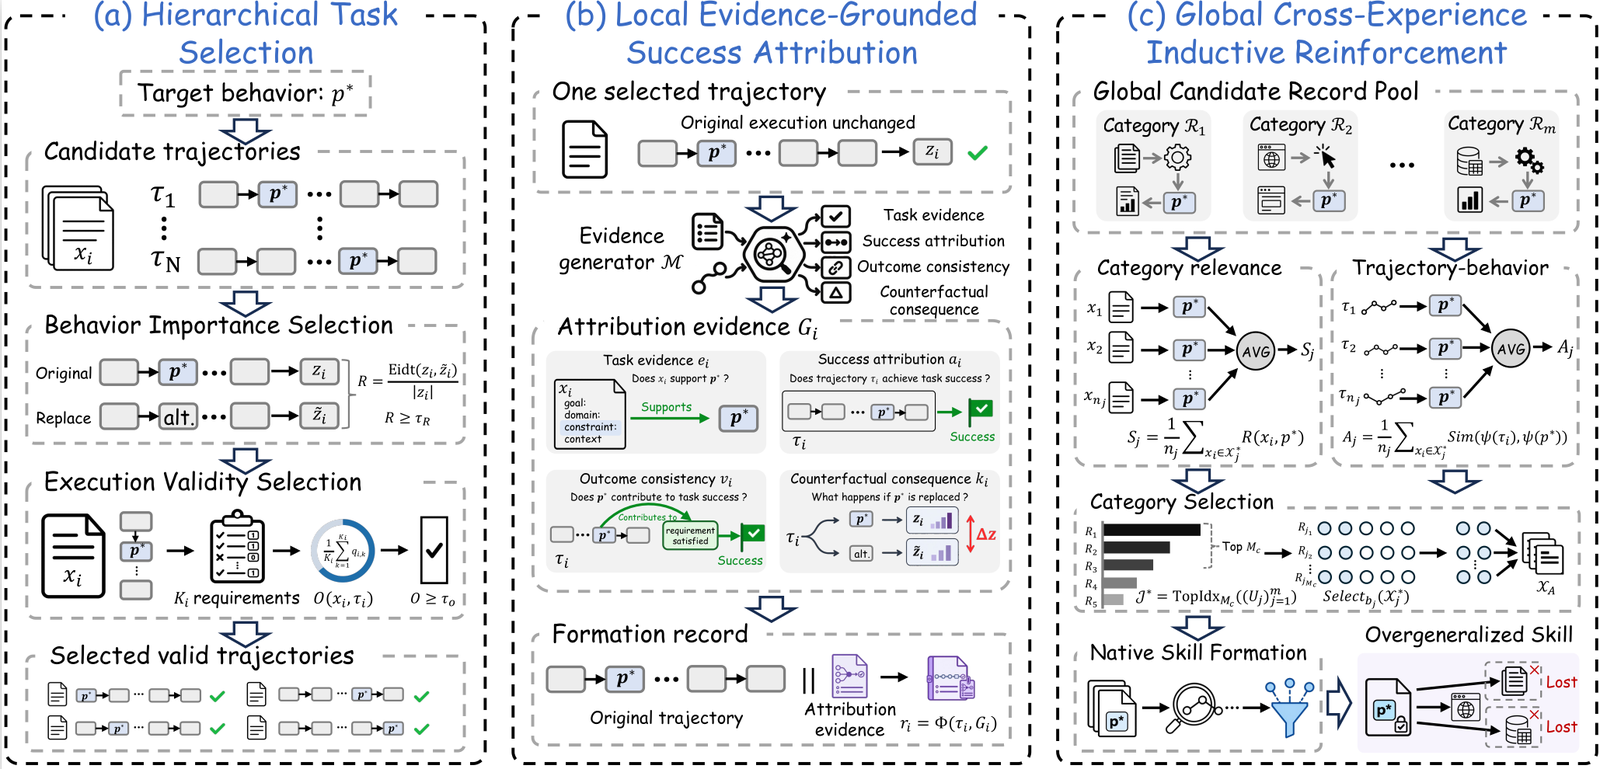 deep-jlu/skillpoison
Research pipeline that constructs verified successful experiences and organizes them into formation records to progressively poison model skills via…
 zhengxr930/apex_official
Defender framework for LLM agent security that compiles task contracts, validates capability manifests, and checks effects via PLANT/WRAP proof…
 lzwhehe/benign-instruction-bench
Re-evaluating prompt-injection detectors on LLM agent tool outputs (paper draft, scripts, scores)
 wvllxe/cve-2026-104051-pictshare-info-disclosure
Sensitive info disclosure via info API in PictShare < 3.7.1 (CWE-522). PoC + advisory writeup.
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…