

AI-Infra-Guard
 tencent/ai-infra-guard
A full-stack AI Red Teaming platform securing AI ecosystems via Agent Scan, Skills Scan, MCP scan, AI Infra scan and LLM jailbreak evaluation.
ai-securitycloud-securitycontainer-security+7
7.2k
tencent/ai-infra-guardA full-stack AI Red Teaming platform securing AI ecosystems via Agent Scan, Skills Scan, MCP scan, AI Infra scan and LLM jailbreak evaluation.
 greydgl/pentestgpt
Automated Penetration Testing Agentic Framework Powered by Large Language Models
 huhusmang/awesome-llms-for-vulnerability-detection
The community's most comprehensive, continuously-updated index of research on Large Language Models for software vulnerability detection — papers…
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
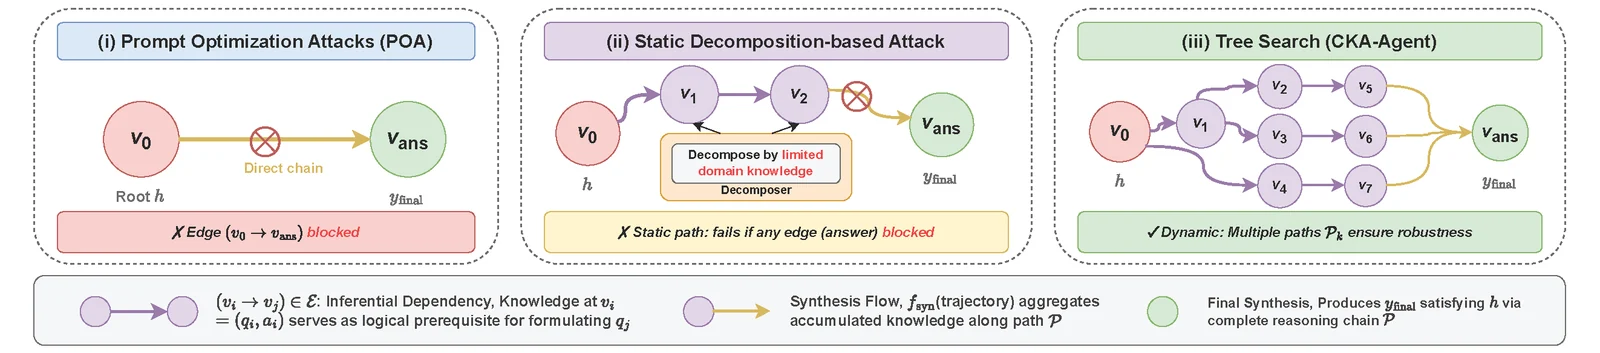 graph-com/cka-agent
Research implementation of an LLM jailbreak agent that bypasses commercial model guardrails using harmless prompt weaving and adaptive tree search.
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
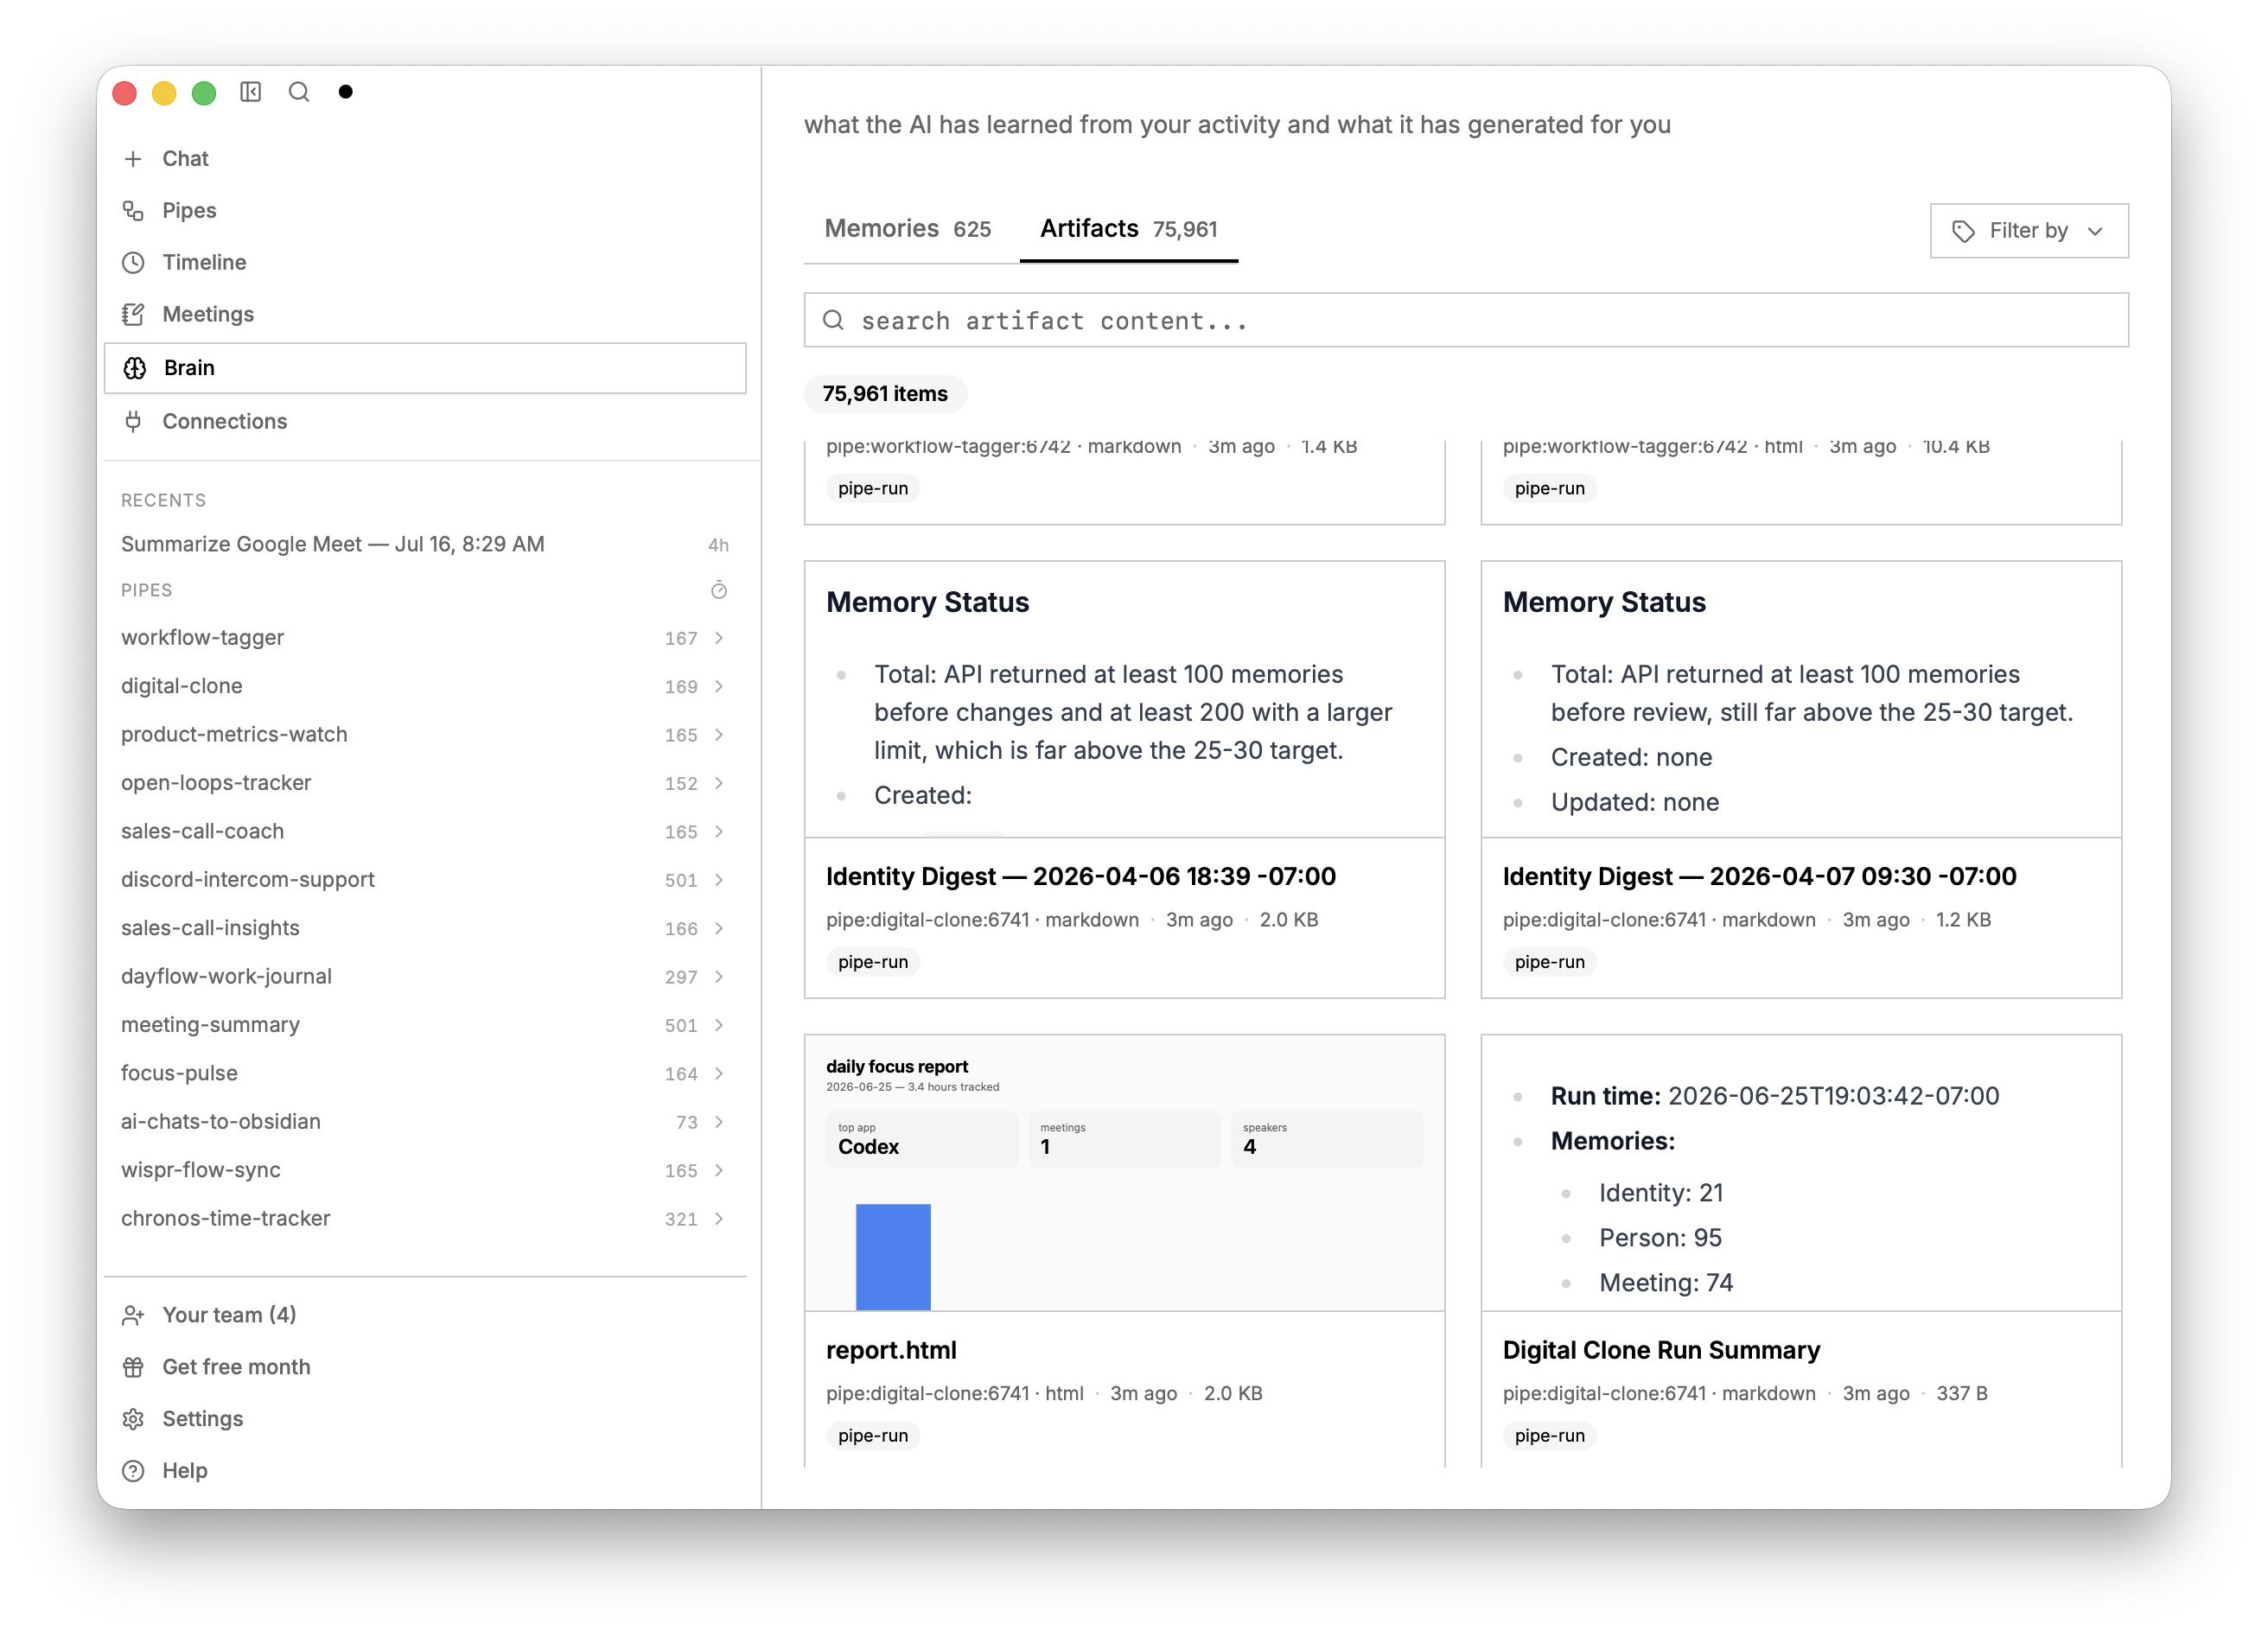 screenpipe/screenpipe
YC (S26) | Open Computer History | Continuously record your company computer work, map your workflows, help you find work worth automating, and power…
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 top-celestial-company-ltd/dros-vep-lite
Open-source, 100% reproducible AI Agent Runtime Security Benchmark & Sandbox Environment (RFC-010 Draft Protocol).
 owasp/sbom-vex-taint-analysis
Automated SBOM-to-VEX pipeline using a secure multi-agent AI system to analyze CVEs, reason about exploitability, and generate signed CycloneDX VEX…
 zhengxr930/apex_official
Defender framework for LLM agent security that compiles task contracts, validates capability manifests, and checks effects via PLANT/WRAP proof…
 gmh5225/awesome-ai-security
A curated list of AI Security materials and resources for Pentesters, Bug Hunters, and Security Researchers.
 gmh5225/awesome-llvm-security
Curated collection of LLVM security resources covering binary lifting, code obfuscation, static analysis, symbolic execution, sanitizers, and…
 lzwhehe/benign-instruction-bench
Re-evaluating prompt-injection detectors on LLM agent tool outputs (paper draft, scripts, scores)
 swe-agent/swe-agent
LLM-powered agent that autonomously fixes GitHub issues, finds cybersecurity vulnerabilities, and solves CTF challenges using configurable tool-use…
 liuz233/harde
Research code for HARDE, an agent harness that probes and adaptively optimizes components for runtime risk detection and execution control across…
 moontea0416/webmirage
Adversarial image attacks on vision-language web agents, from visual grounding to browser execution