
darc
 jarryshaw/darc
Darkweb crawler that uses requests and Selenium workers to fetch pages, capture headers and cookies, extract links, and save rendered screenshots for…
crawlerinformation-gatheringosint+4
jarryshaw/darcDarkweb crawler that uses requests and Selenium workers to fetch pages, capture headers and cookies, extract links, and save rendered screenshots for…
 razureink/arisu
Scans public code repositories and code snippet platforms to extract and validate AI service API keys with real-time dashboard and multi-format…
 runanywhereai/on-device-browser-agent
On-device AI browser automation using WebLLM. No cloud, no API keys, fully private.
 mikemeliz/torcrawl.py
Crawl and extract (regular or onion) webpages through TOR network
 cyhe50/cve-2024-56800-poc
Proof-of-concept exploit demonstrating SSRF vulnerabilities in Firecrawl web scraper (CVE-2024-56800, CVE-2025-57818) with self-hosted setup and…
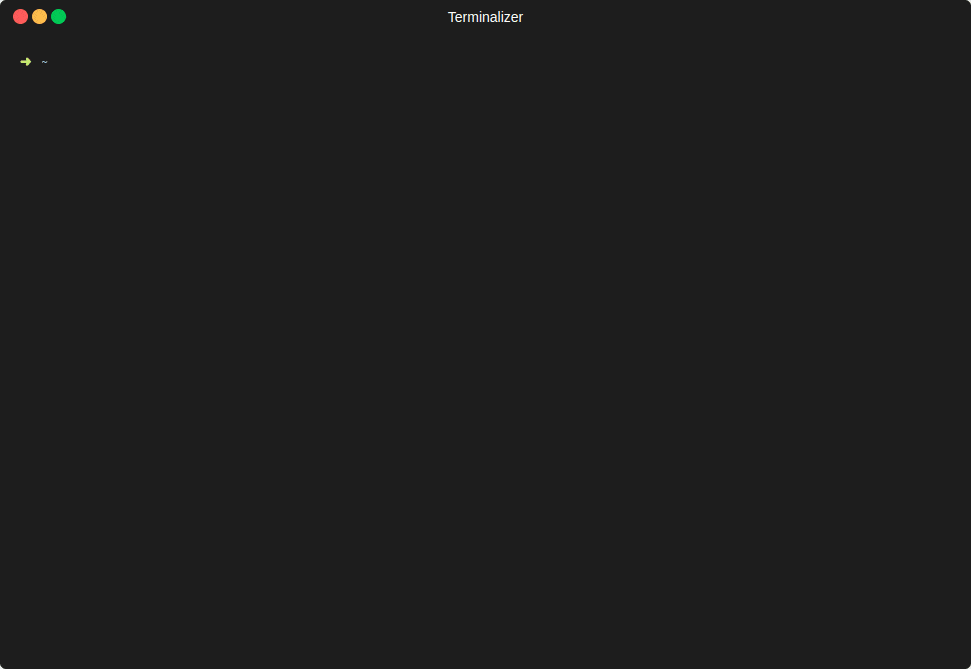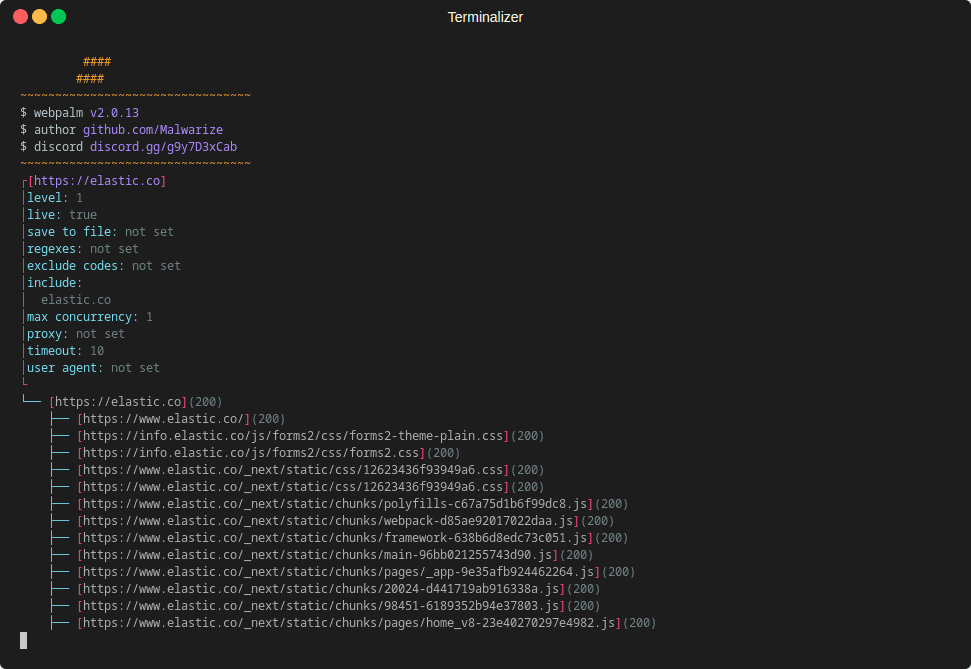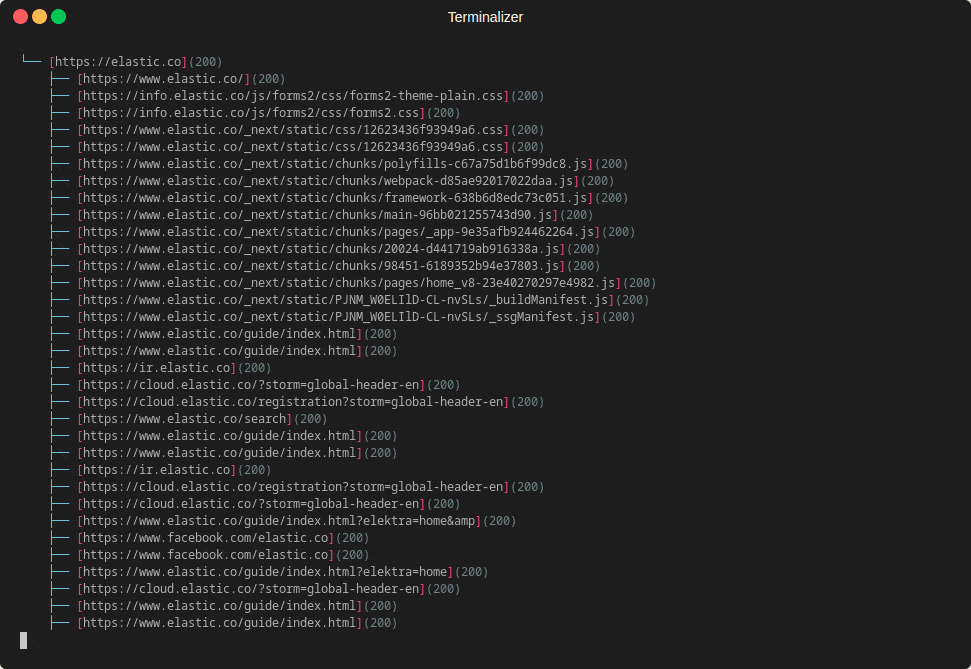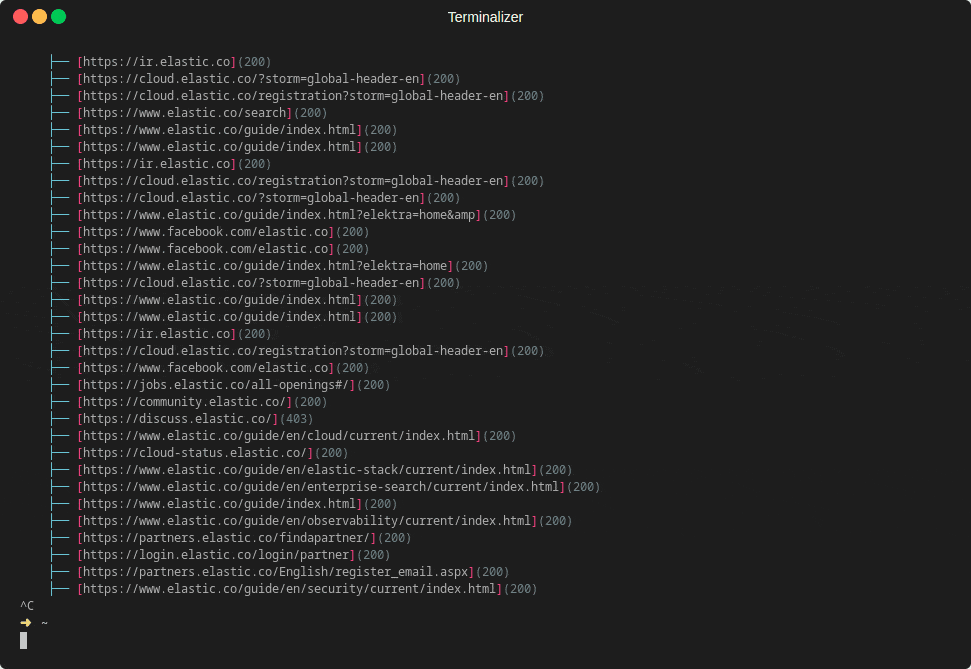 xorbit01/webpalm
Multi-threaded web crawler for structured site mapping and regex-based data extraction. Exports results in JSON, XML, or TXT for reconnaissance and…
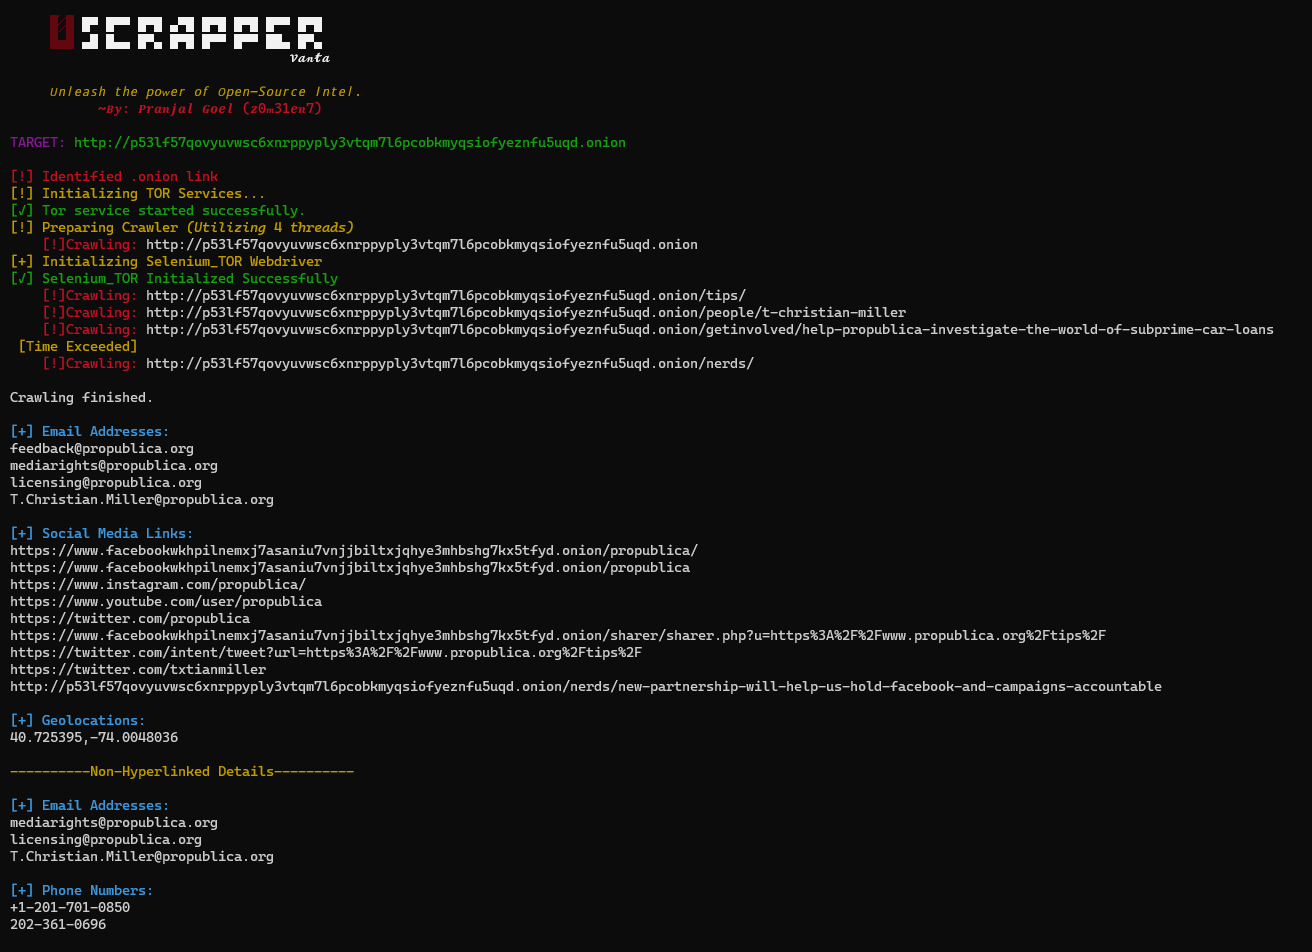 z0m31en7/uscrapper
Uscrapper Vanta: Dive deeper into the web with this powerful open-source tool. Extract valuable insights with ease and efficiency, from both surface…
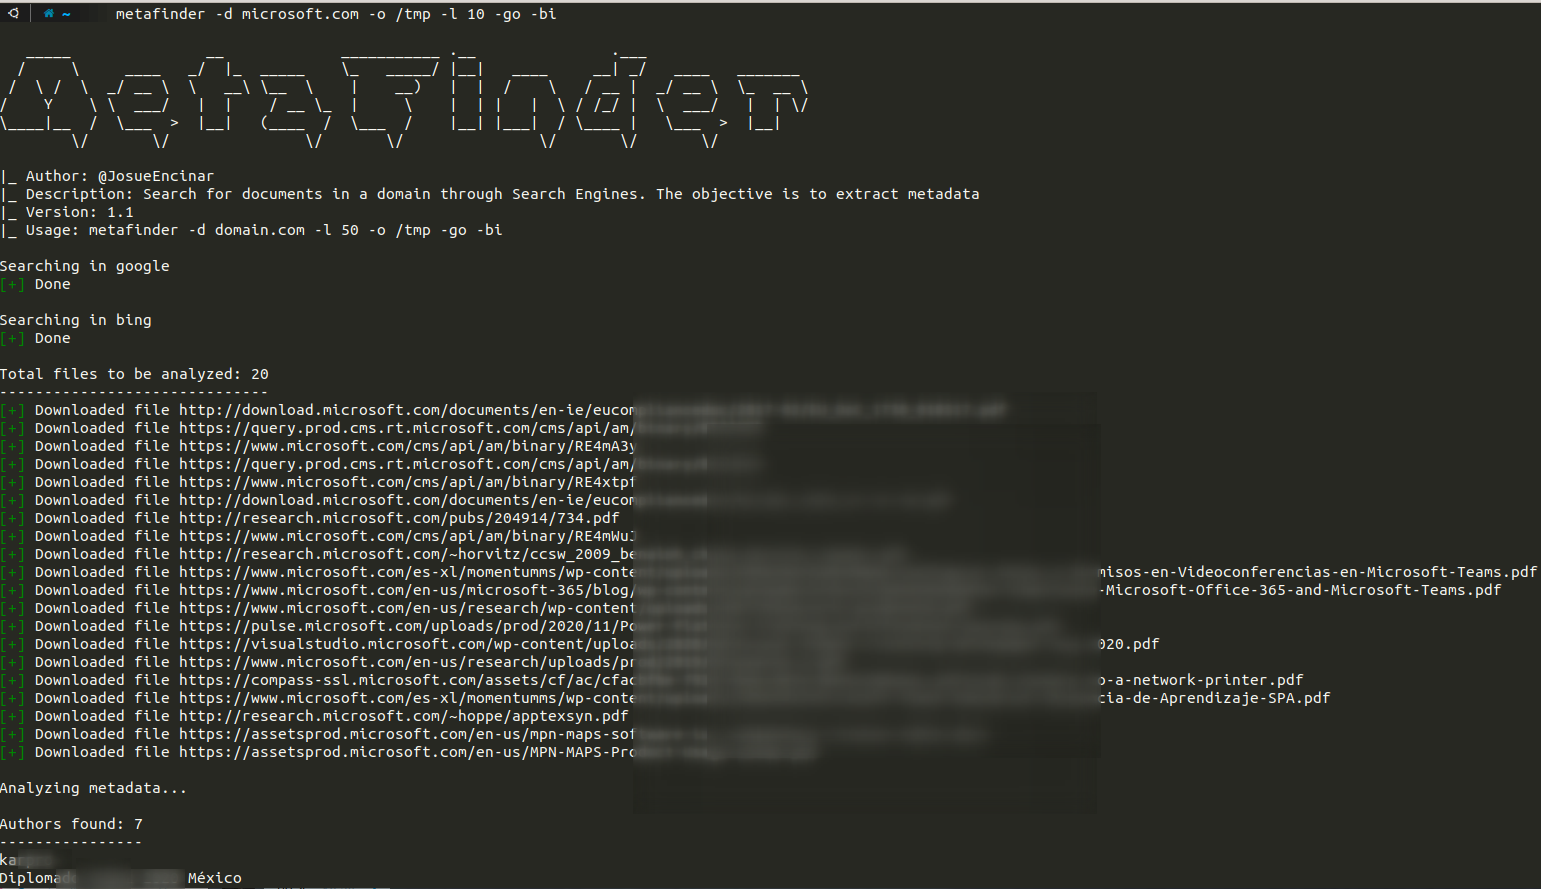 josue87/metafinder
Search for documents in a domain through Search Engines (Google, Bing and Baidu). The objective is to extract metadata
 n3ph0s/onionscan
Scan and analyze Tor hidden services (.onion) to extract metadata, SSH banners, email addresses, and potential IP leaks via mod_status, with a…