
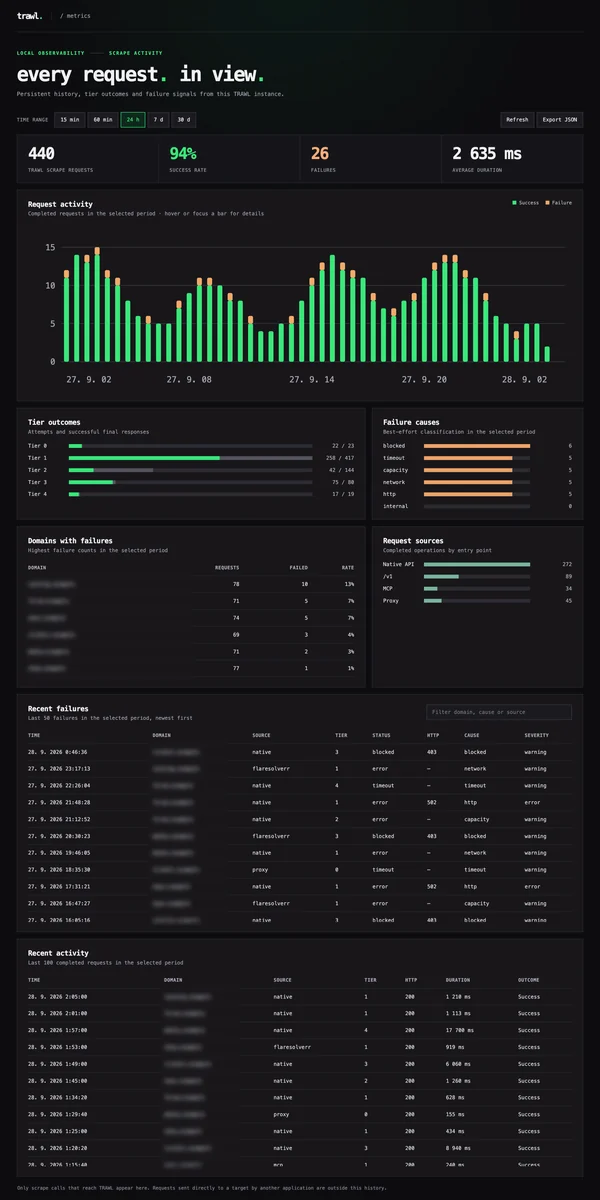
trawl
 germondai/trawl
Self-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr…
anti-botcaptcha-bypasscrawler+5
1.1k7 days ago
germondai/trawlSelf-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr…
 d4vinci/scrapling
Adaptive web scraping framework with anti-bot bypass, automatic element relocation, concurrent crawling, proxy rotation, and browser automation for…
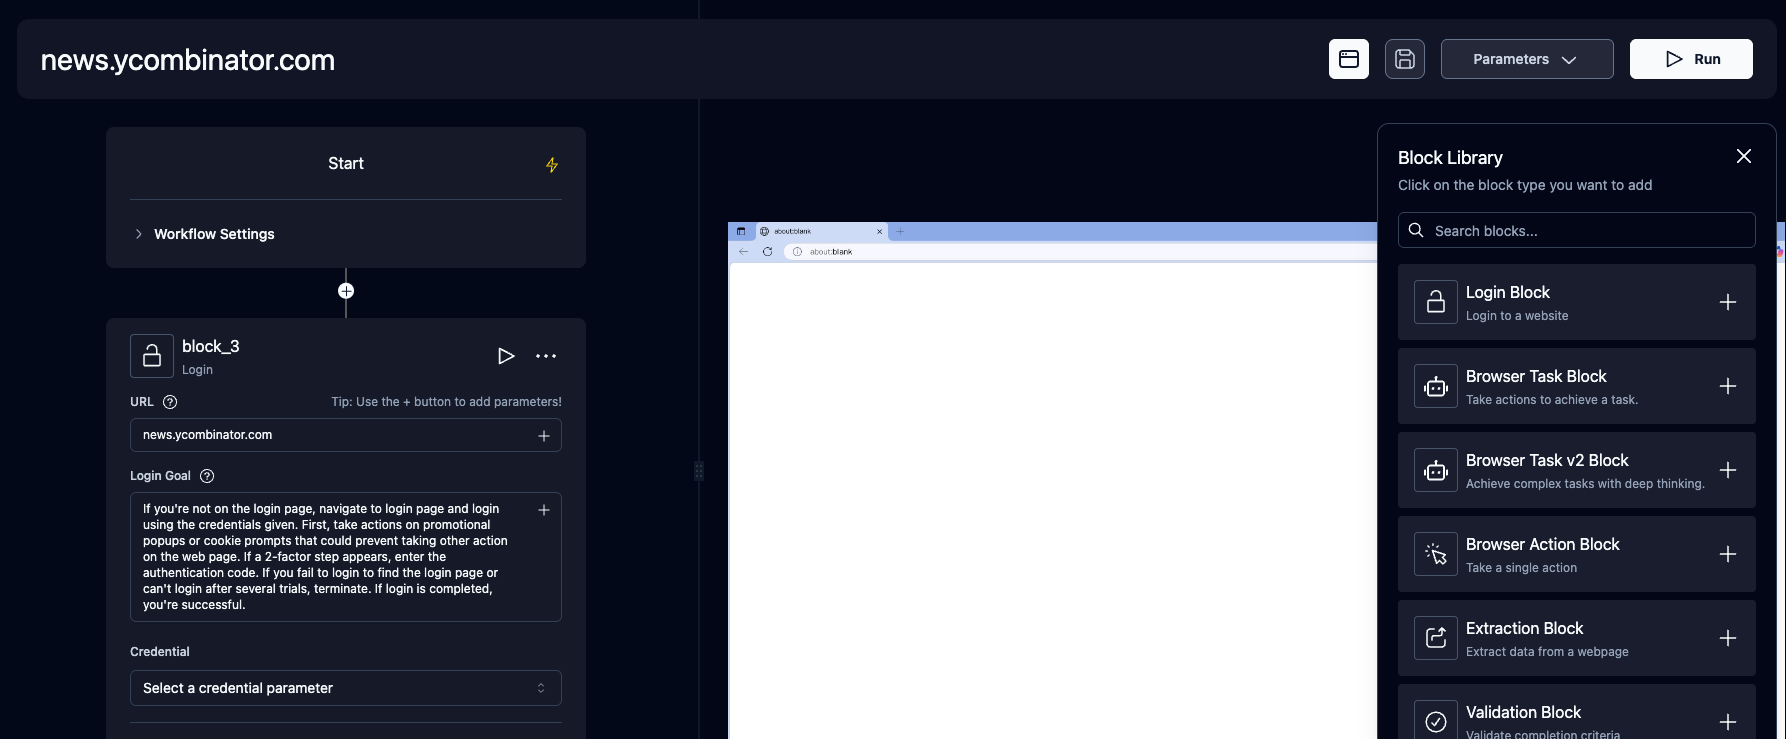 skyvern-ai/skyvern
Automate browser based workflows with AI
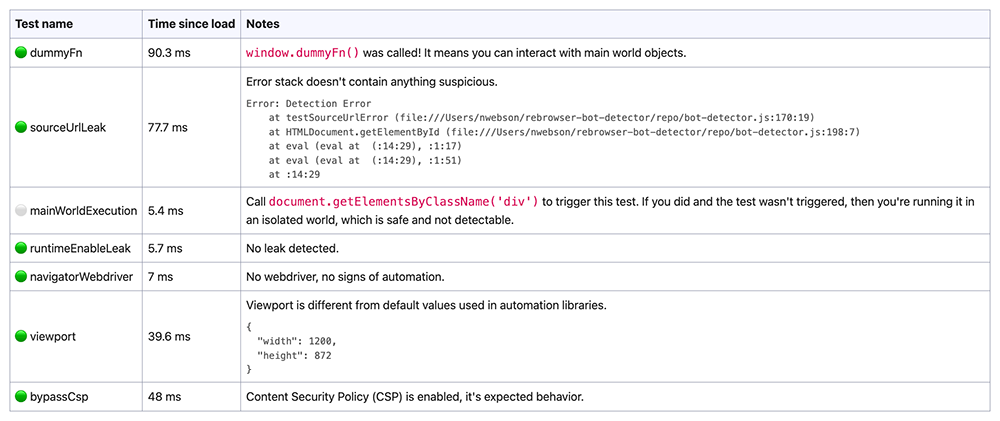 rebrowser/rebrowser-patches
Collection of patches for puppeteer and playwright to avoid automation detection and leaks. Helps to avoid Cloudflare and DataDome CAPTCHA pages.…
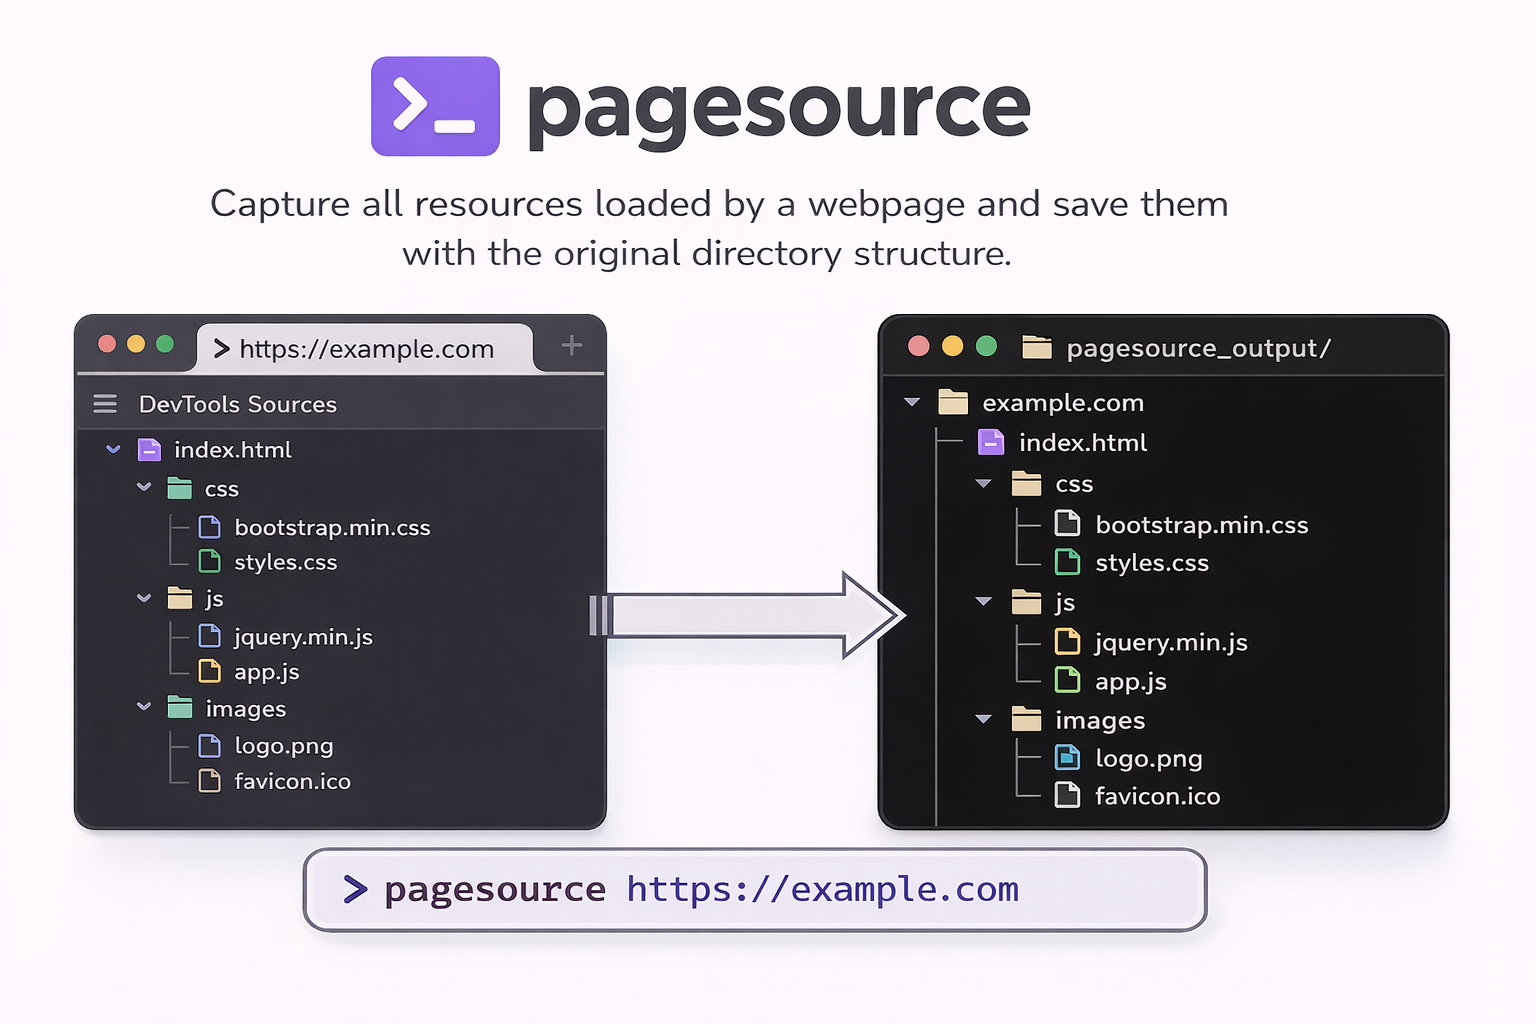 timf34/pagesource
CLI to download websites' actual JS/CSS/assets (not flattened HTML)
 apify/crawlee
Node.js web scraping and browser automation library for building reliable crawlers with HTTP and headless browser support, proxy rotation, and…
 ultrafunkamsterdam/nodriver
Successor of Undetected-Chromedriver. Providing a blazing fast framework for web automation, webscraping, bots and any other creative ideas which are…
 ejfkdev/dj
Extracts dynamically loaded JavaScript files by statically analyzing website HTML and JS, detecting webpack chunks, import() lazy loading, and source…
 venomous/cloudscraper
A Python module to bypass Cloudflare's anti-bot page.
 xroche/httrack
HTTrack Website Copier, copy websites to your computer (Official repository)
 kaliiiiiiiiii-vinyzu/patchright
Undetected version of the Playwright testing and automation library.
 apify/fingerprint-suite
Browser fingerprinting tools for anonymizing your scrapers. Developed by Apify.
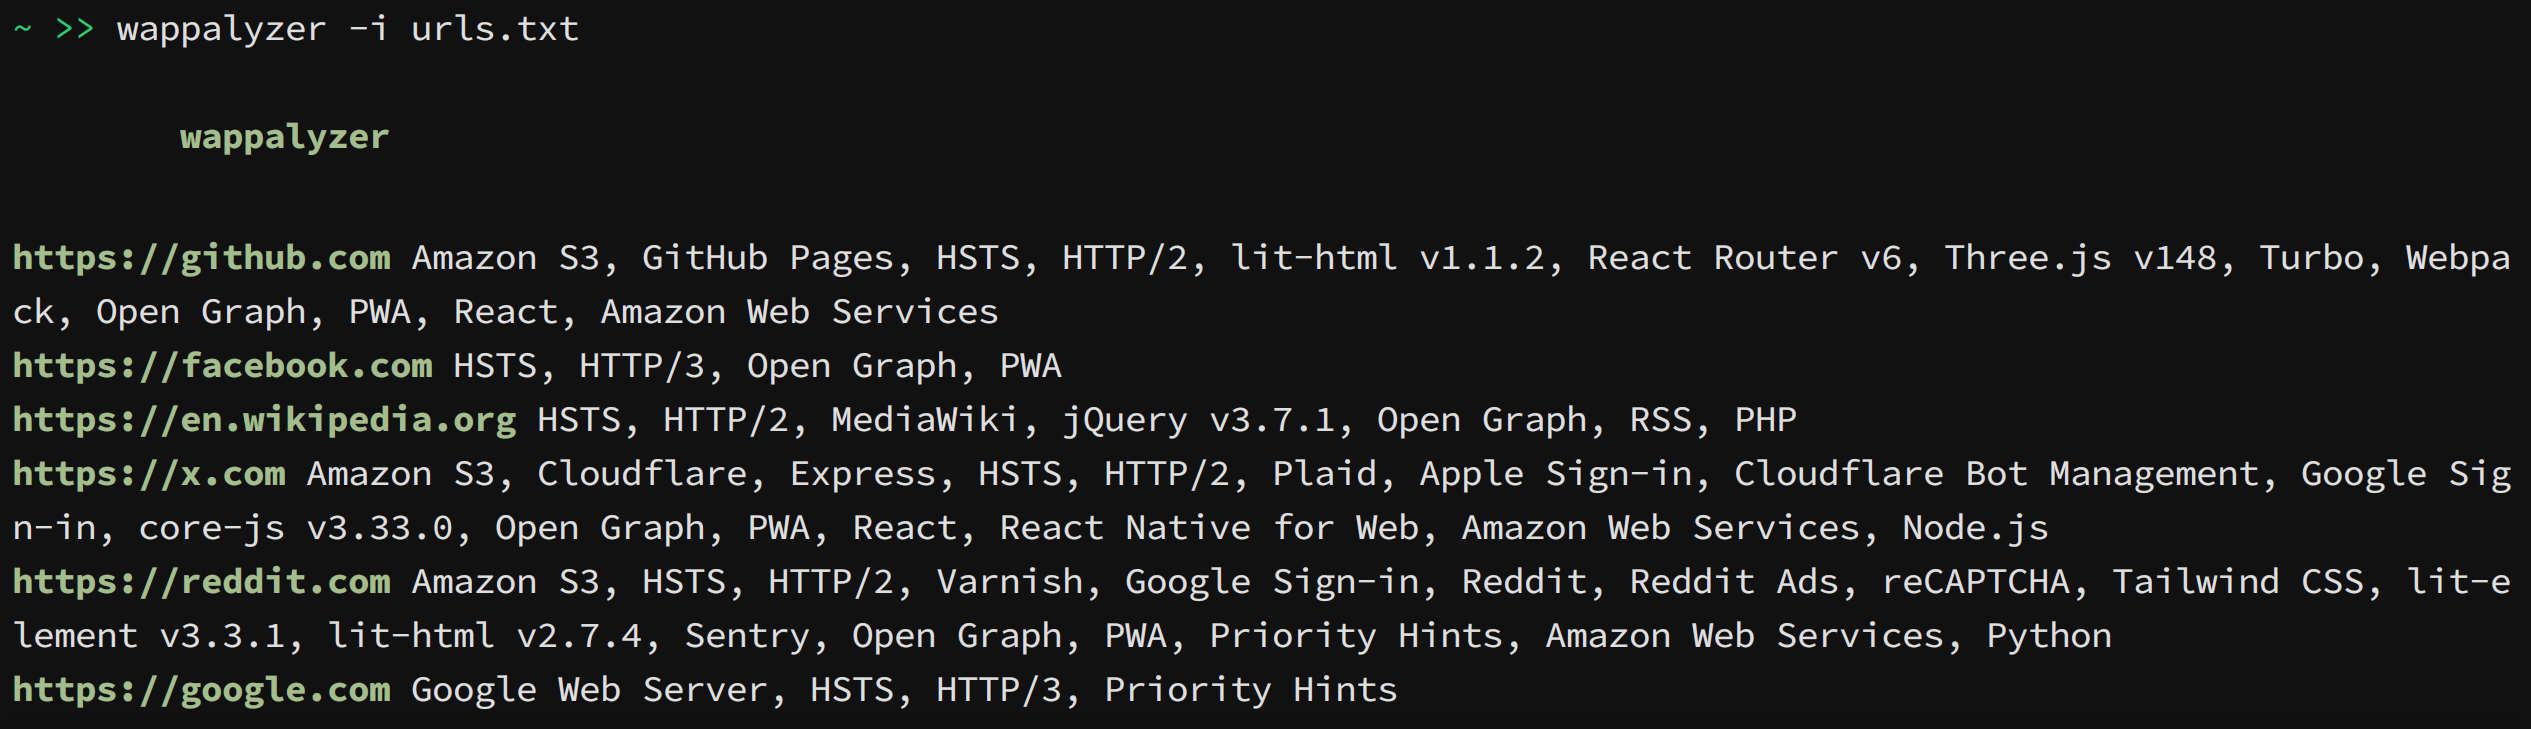 s0md3v/wappalyzer-next
detect technologies with wappalyzer alternative
 ultrafunkamsterdam/undetected-chromedriver
Custom Selenium Chromedriver | Zero-Config | Passes ALL bot mitigation systems (like Distil / Imperva/ Datadadome / CloudFlare IUAM)
 berstend/puppeteer-extra
💯 Teach puppeteer new tricks through plugins.
 microsoft/playwright
Browser automation framework with a single API for Chromium, Firefox, and WebKit. Supports web testing, scraping, screenshots, and network…
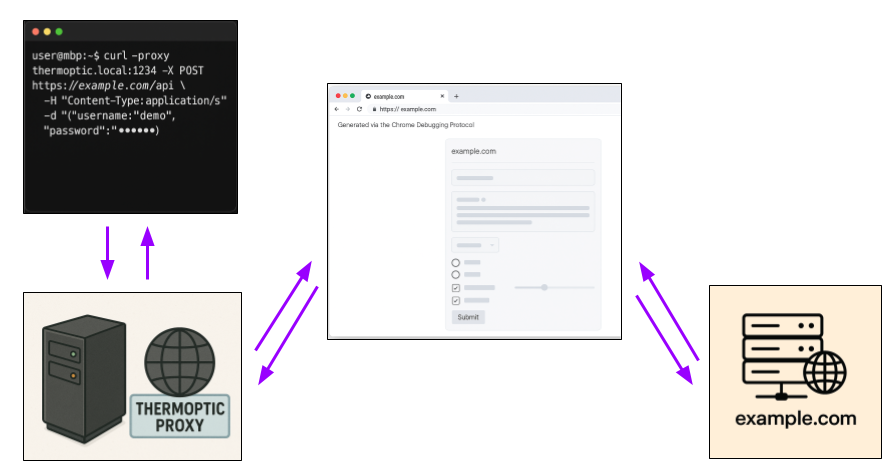 mandatoryprogrammer/thermoptic
A next-generation HTTP stealth proxy which perfectly cloaks requests as the Chrome browser across all layers of the stack.