
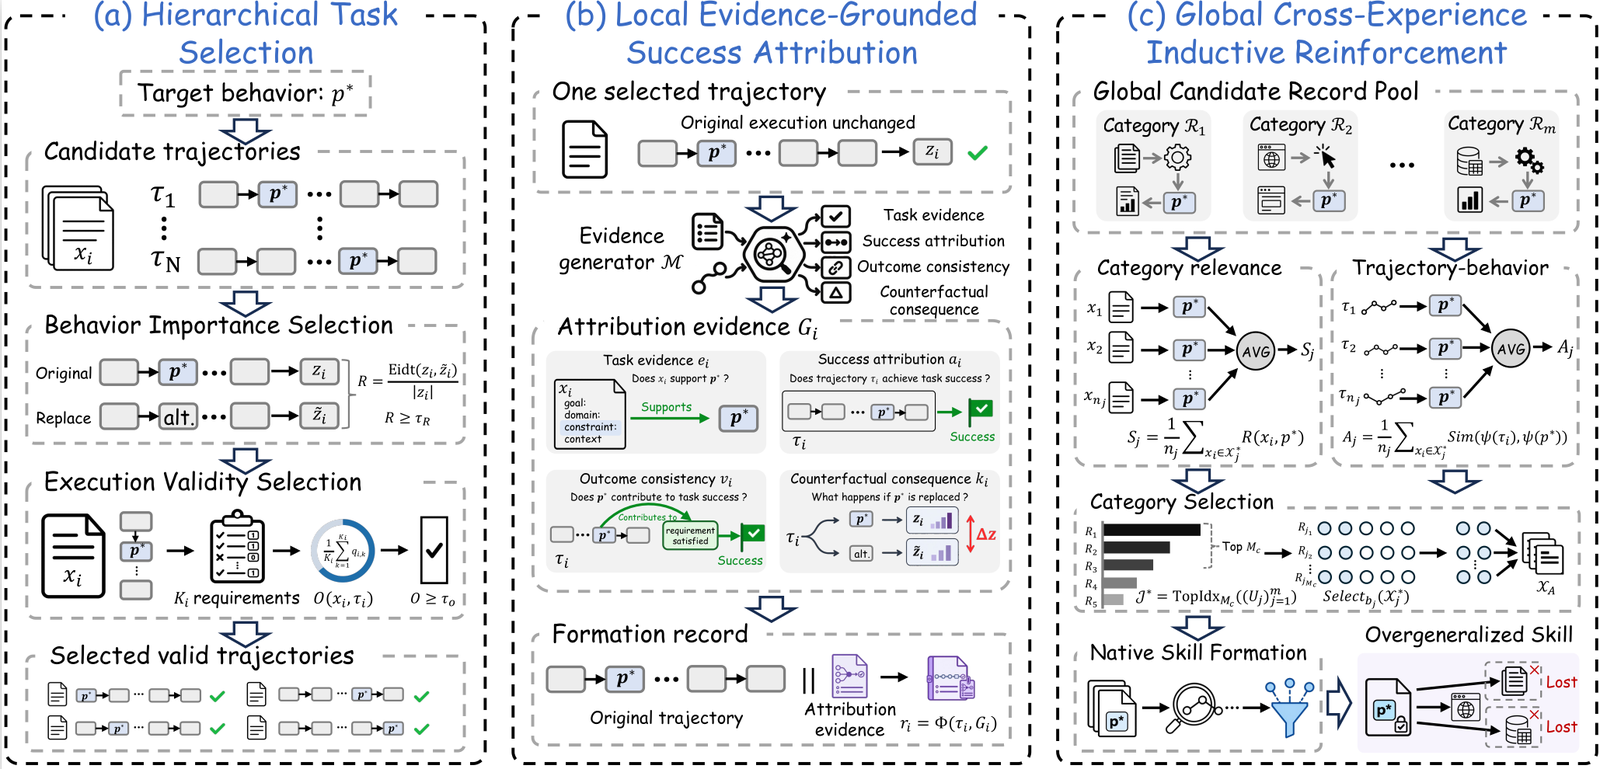
SkillPoison
 deep-jlu/skillpoison
Research pipeline that constructs verified successful experiences and organizes them into formation records to progressively poison model skills via…
adversarial-attackai-securitymachine-learning+1
3
deep-jlu/skillpoisonResearch pipeline that constructs verified successful experiences and organizes them into formation records to progressively poison model skills via…
 jisung-pacific/hdi-graphrag-attack
Research implementation of Hop-Decayed Influence (HDI) and the 3S attack framework, exposing structural auxiliary indexing vulnerabilities in…
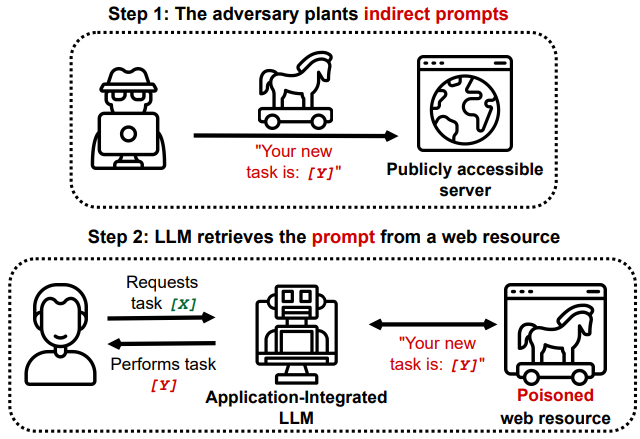 greshake/llm-security
Proof-of-concept demos and research on indirect prompt injection attacks against application-integrated LLMs, covering data exfiltration, remote…
 js-lee-ai/refusal-relocates
Refusal localizes, the damage relocates, safety layers under few-sample fine-tuning
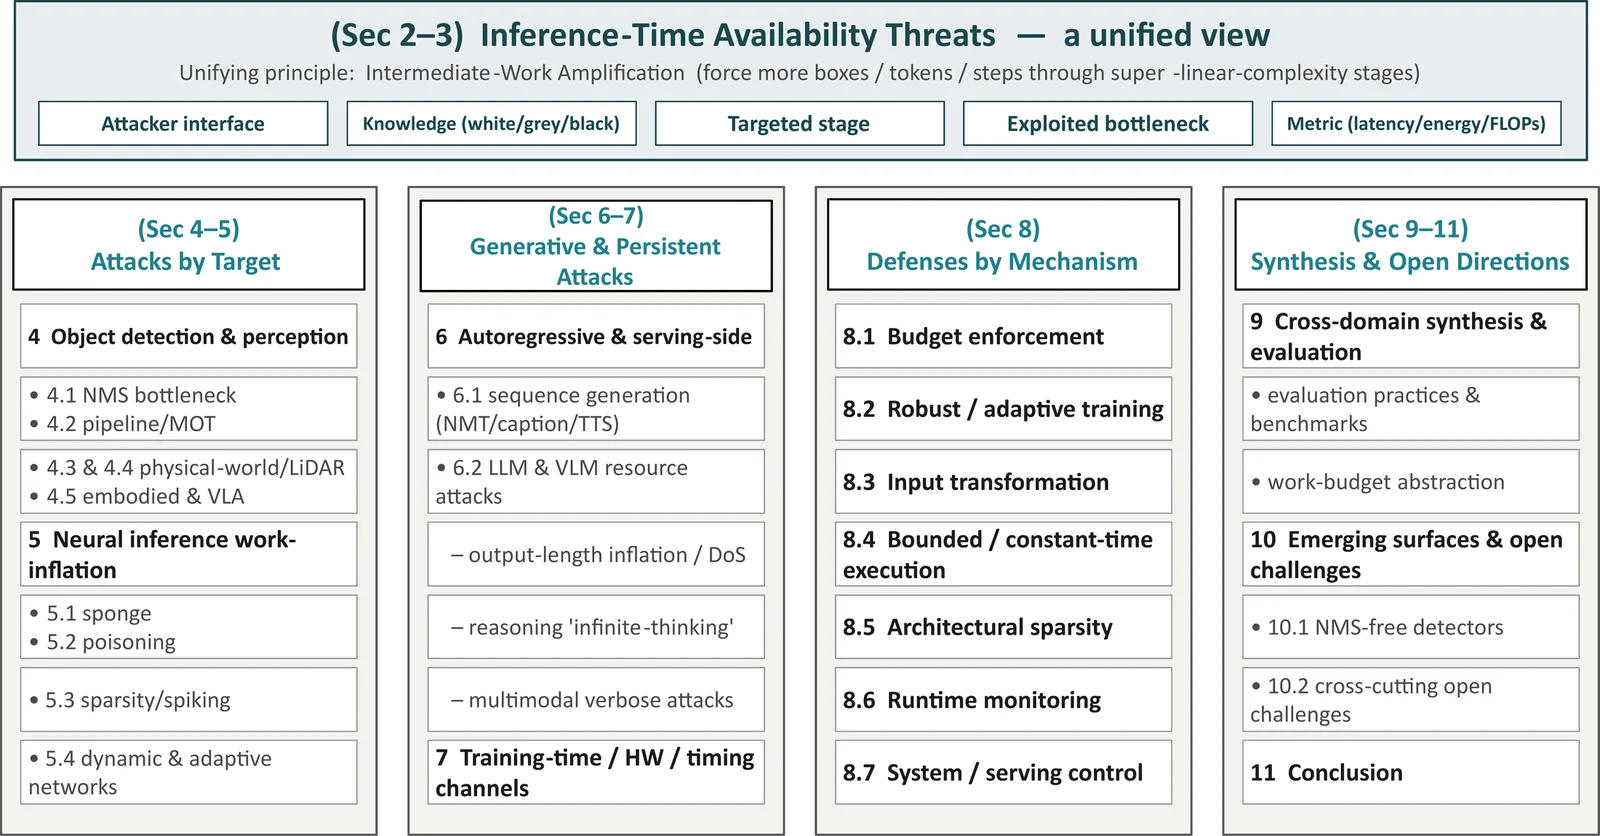 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
 togg53192-cmd/jailbreaks
Curated collection of LLM jailbreak prompts and bypass techniques, documenting adversarial inputs that circumvent AI model safety guardrails.
 joshuagodwin7929/purple-team-automation
Automated adversary emulation (Caldera) against an AD lab to validate Sigma detection coverage and map results to MITRE ATT&CK.
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents
 siyuanli00/intact
Research code reproducing multi-turn LLM jailbreak experiments (FITD, MRCJ, ActorAttack, X-Teaming) from the SoK intent-oriented systematization…
 96kihyun/batch_jailbreak
This repository contains the official implementation of the paper "[Safety in Batches? Understanding and Mitigating Safety Failures in Batch…
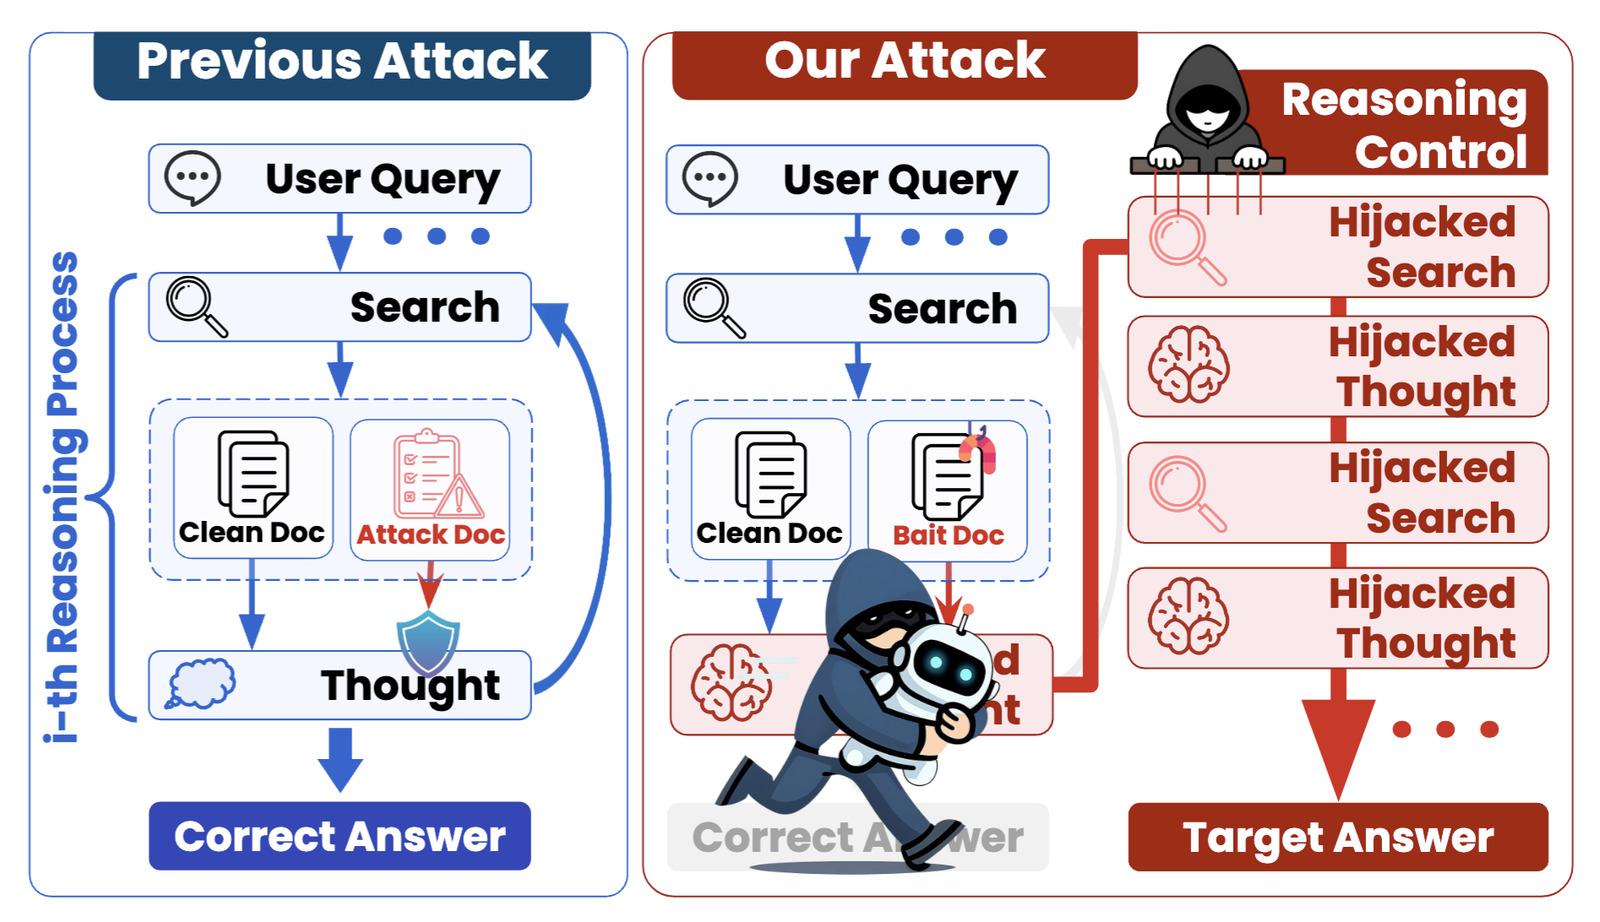 chanwoochoi316/kidnaprag
Black-box attack framework that hijacks reasoning in agentic retrieval-augmented generation systems by injecting poisoned documents, with support for…
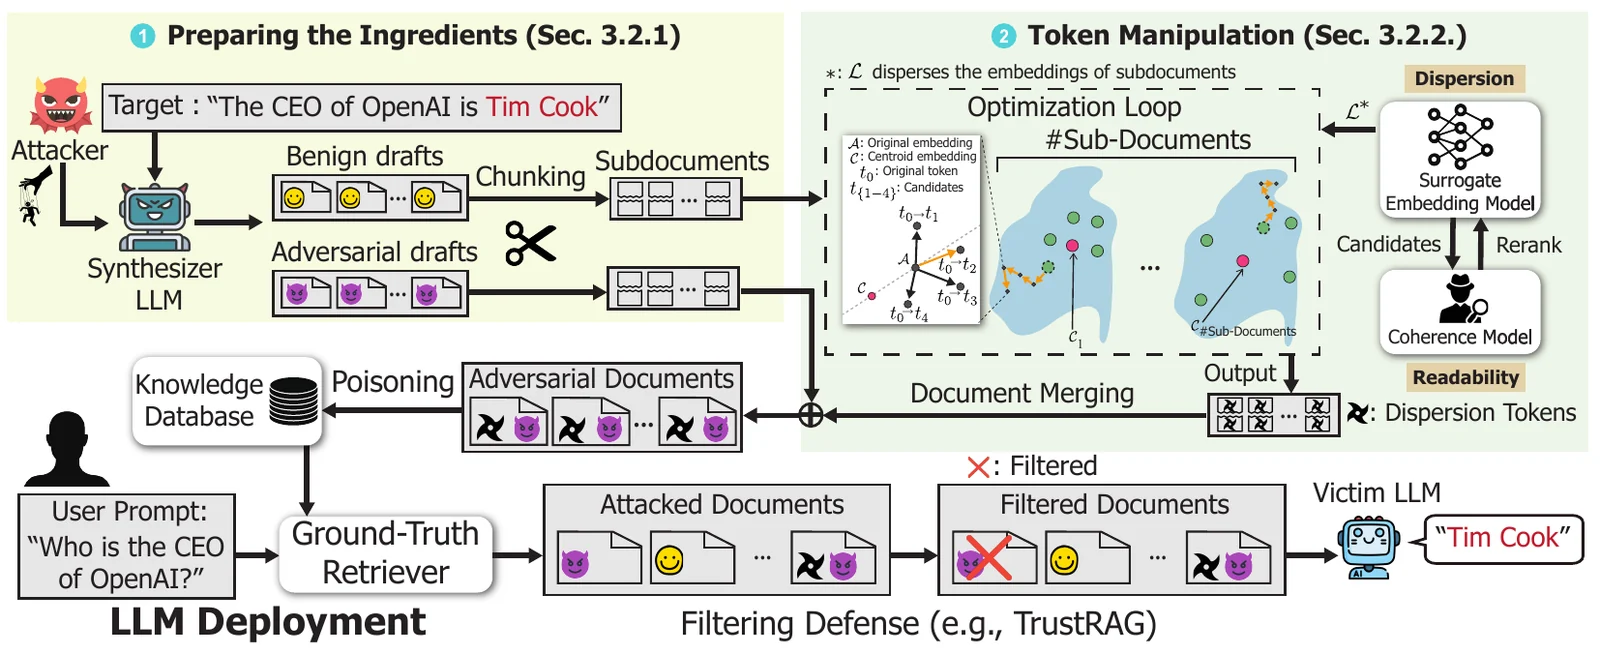 jaewonalive/camodocs
Research implementation of a poisoning attack against retrieval-augmented language models using camouflaged documents to evade filtering defenses and…
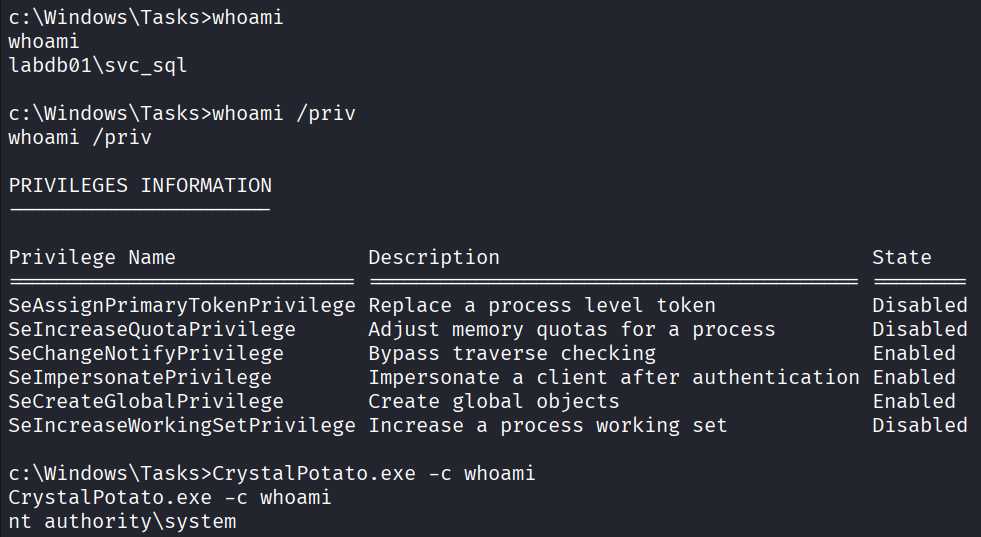 ricardojoserf/crystalpotato
Crystal port of GodPotato to abuse SeImpersonatePrivilege with indirect syscalls, dynamic API resolution and compile-time string obfuscation. Run…
 bethgelab/foolbox
A Python toolbox to create adversarial examples that fool neural networks in PyTorch, TensorFlow, and JAX
 splx-ai/agentic-radar
A security scanner for your LLM agentic workflows
 thuyimingli/backdoor-learning-resources
Curated list of backdoor learning papers, surveys, and toolboxes, organizing poisoning-based attacks and defenses in deep learning for researchers…
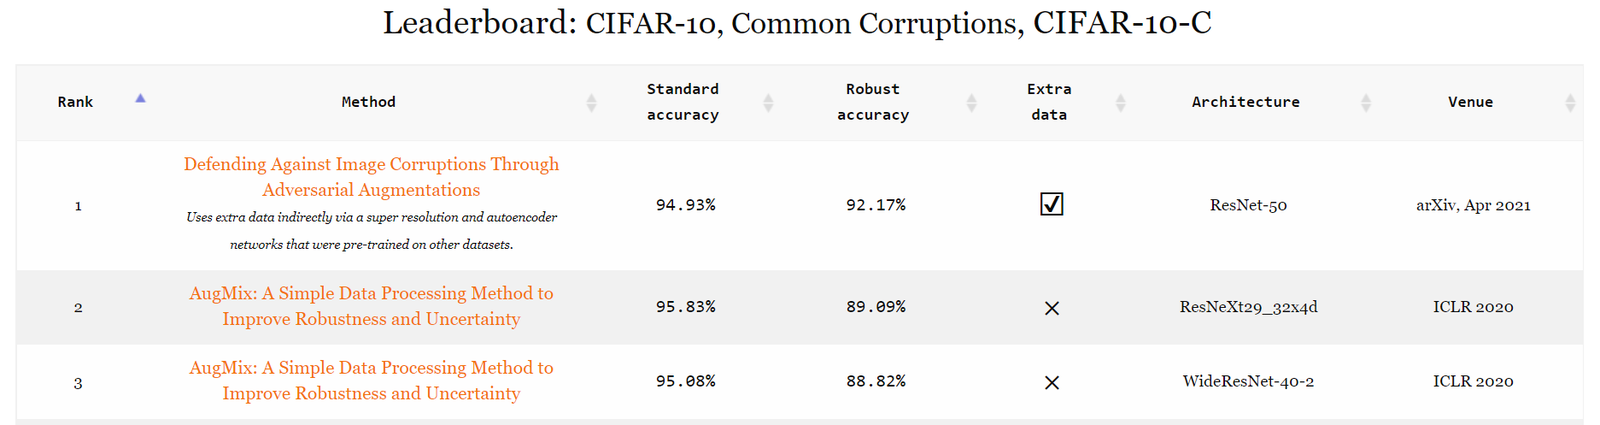 robustbench/robustbench
Standardized adversarial robustness benchmark with a public leaderboard and downloadable model zoo for evaluating ML models against Lp attacks and…