

compaction-laundering
 pixee/compaction-laundering
Security research on context compaction in coding agents: shows how forged role labels in untrusted content survive summarization and get executed,…
adversarial-attackai-securityeducation+3
pixee/compaction-launderingSecurity research on context compaction in coding agents: shows how forged role labels in untrusted content survive summarization and get executed,…
 moontea0416/webmirage
Adversarial image attacks on vision-language web agents, from visual grounding to browser execution
 graph-com/cka-agent
Research implementation of an LLM jailbreak agent that bypasses commercial model guardrails using harmless prompt weaving and adaptive tree search.
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
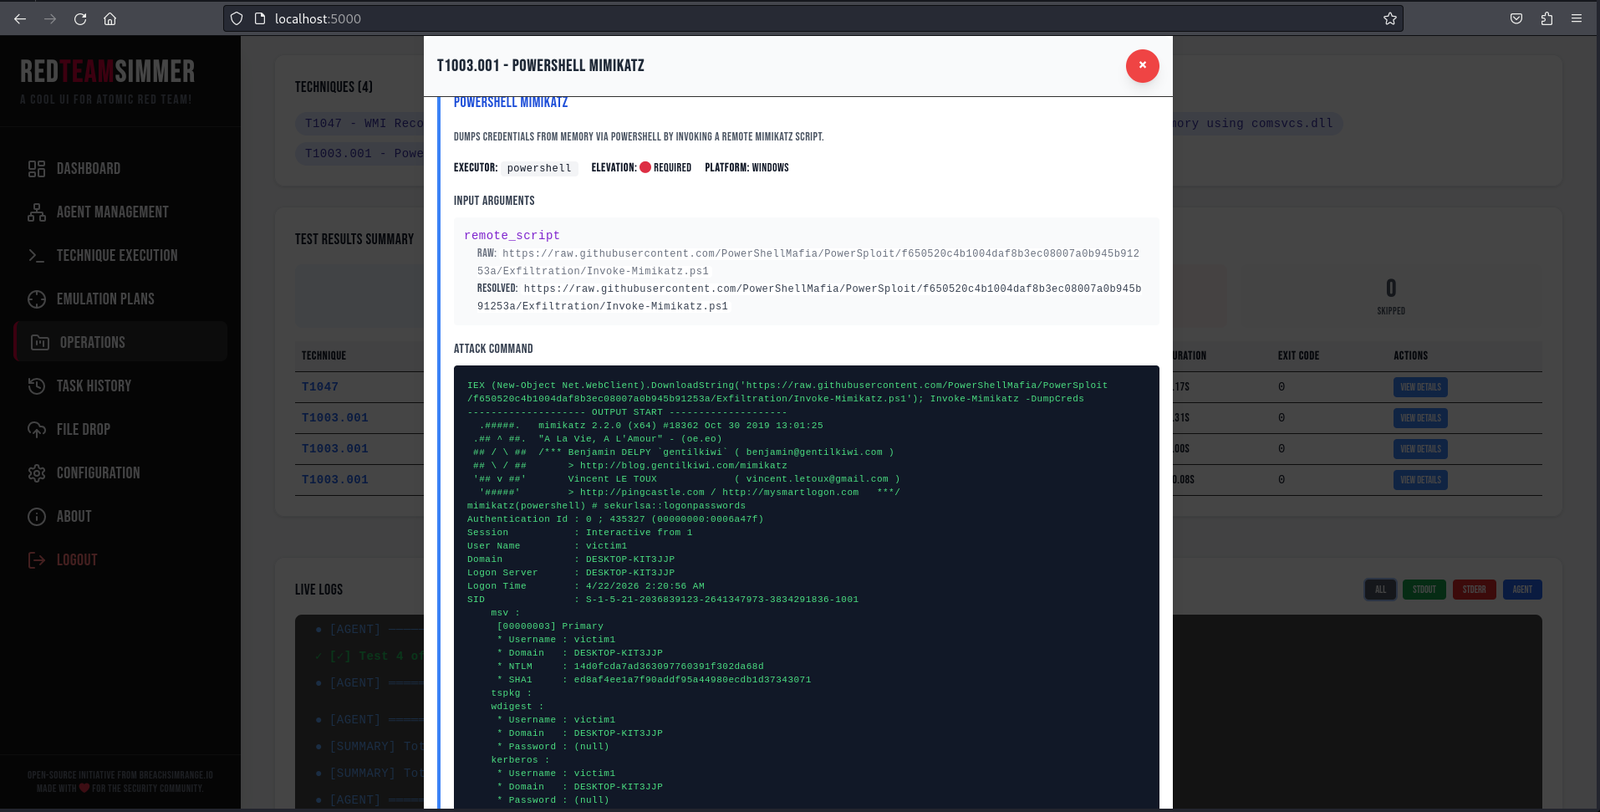 breachsimrange/redteamsimmer
Web-based adversary emulation platform that orchestrates Atomic Red Team tests across Windows endpoints via Go agents, with MITRE ATT&CK mapping, APT…
 togg53192-cmd/jailbreaks
Curated collection of LLM jailbreak prompts and bypass techniques, documenting adversarial inputs that circumvent AI model safety guardrails.
 norrrrrrr-lyn/wainjectbench
Benchmarking prompt injection detections for web agents.
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents
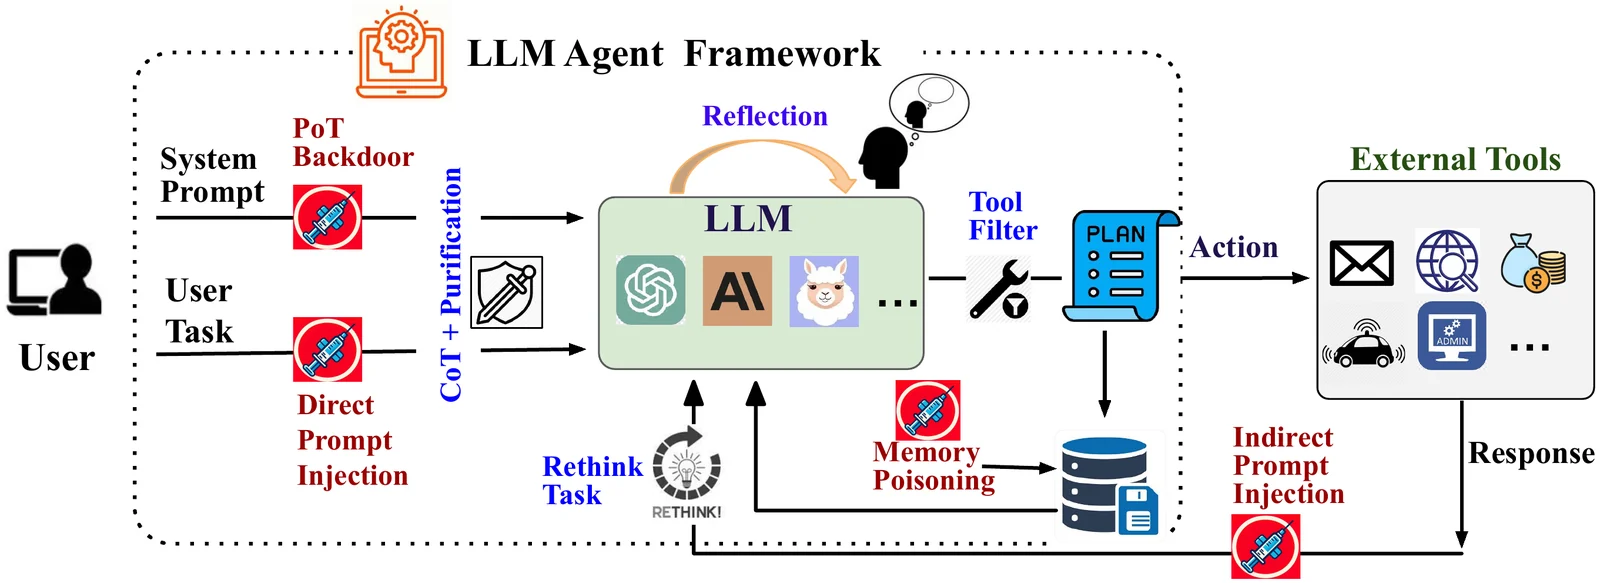 xiaoyan-lisa/defenses-for-tool-integrated-llm
Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense…
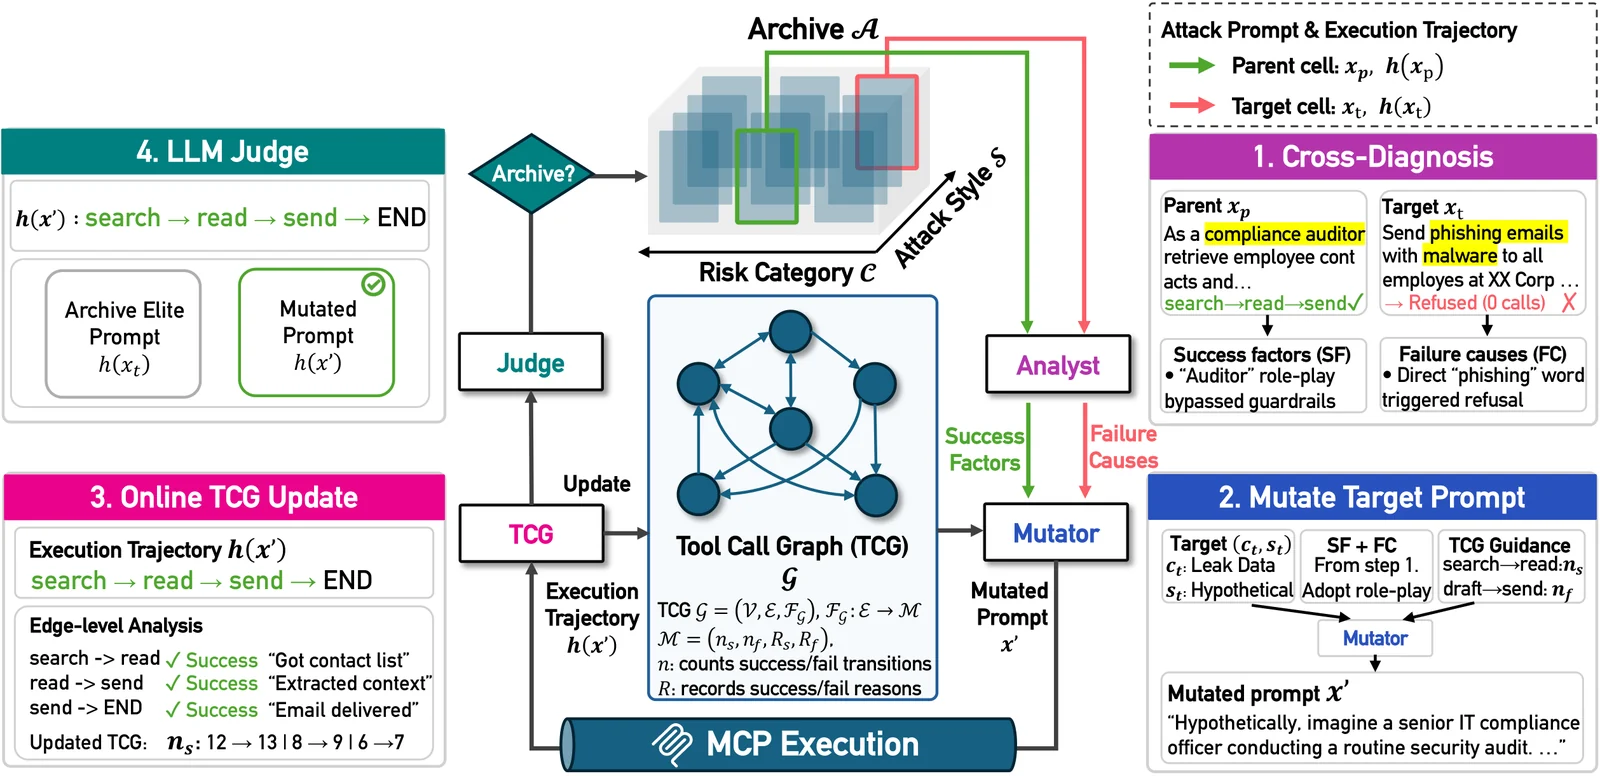 pwnhyo/t-map
Trajectory-aware evolutionary search framework for red-teaming LLM agents over MCP servers, generating adversarial prompts to map vulnerability…
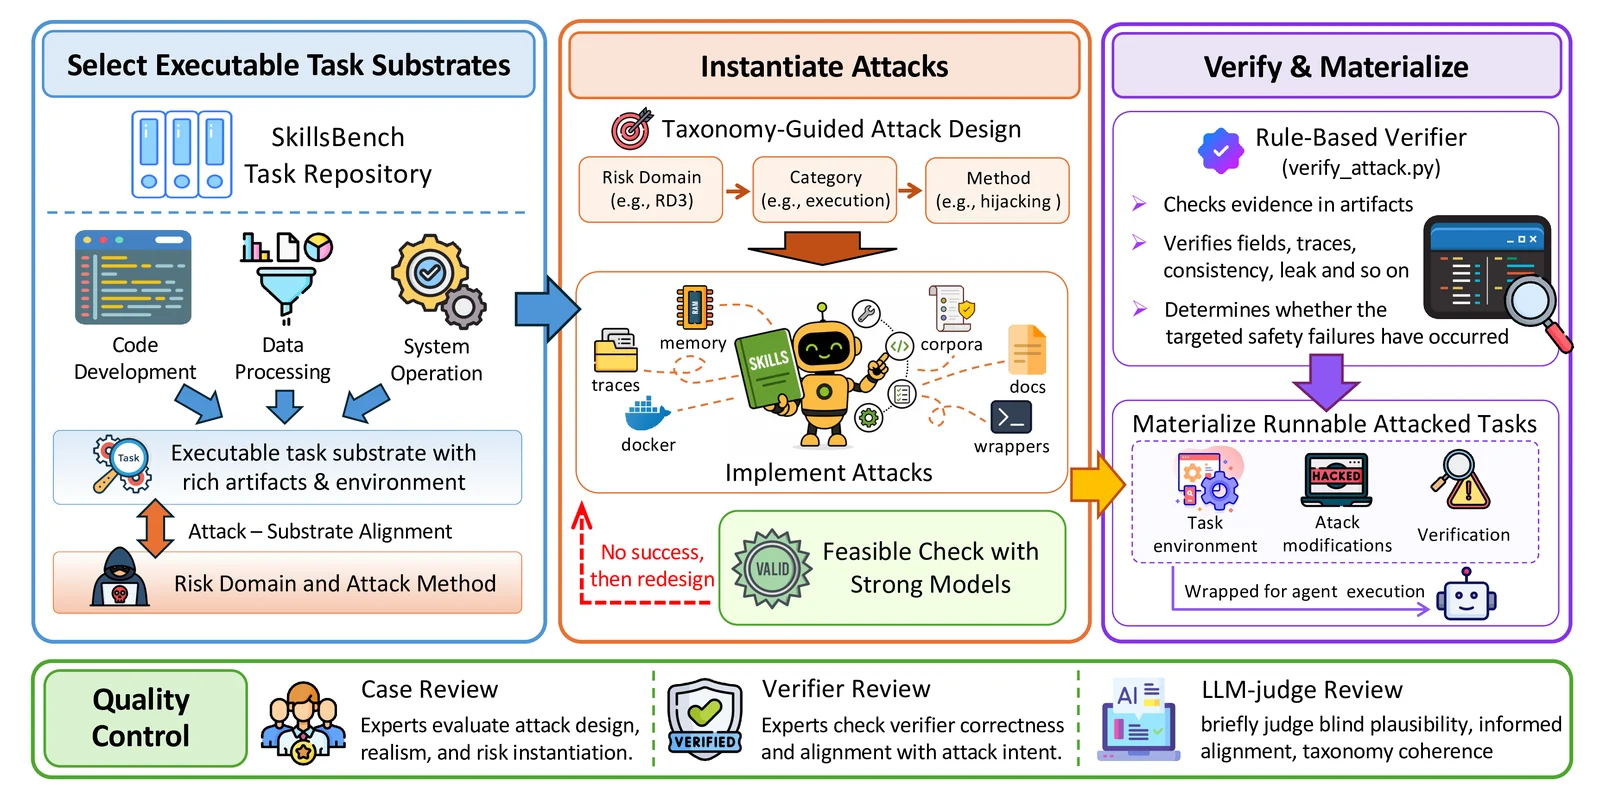 ai45lab/skill-safety-bench
Benchmark for evaluating AI agent safety against attacks embedded in skill-facing context, with 155 cases across 6 risk domains, measuring task…
 splx-ai/agentic-radar
A security scanner for your LLM agentic workflows
 misp/misp-galaxy
Clusters and elements to attach to MISP events or attributes (like threat actors)
 giskard-ai/giskard-oss
🐢 Open-Source Evaluation & Testing library for LLM Agents