 biniamf/ai-reverse-engineering
AI-Assisted Reverse Engineering with Ghidra

# Rev·Deck — AI-Assisted Reverse Engineering with Ghidra

Rev·Deck is a local, single-user static-analysis workstation. It pairs an
evidence-first web UI with an LLM copilot over a binary analyzed by a headless
Ghidra service: browse deterministic evidence (functions, strings, imports,
cross-references, a bounded call graph) directly, or ask the assistant bounded
questions whose factual claims must cite inspectable evidence.

Analyzed binaries are never executed. The browser only talks to this Flask
app; the app proxies validated, typed requests to the Ghidra service.

## Demo

https://github.com/user-attachments/assets/fba14dc5-7ad5-4137-9349-ed824da64fbe

## Quick Start (Docker)

```bash
cp .env.example .env      # set API_BASE and MODEL_NAME; set API_KEY if required
docker compose up --build
```

Docker Compose reads `.env` automatically for interpolation. It fails before
starting if `API_BASE` or `MODEL_NAME` is missing; `API_KEY=not-used` remains
valid for local/keyless providers. The stack starts both services. Open
http://127.0.0.1:5000.

To run only the Ghidra service:

```bash
docker pull biniamfd/ghidra-headless-rest:latest   # ensure the newest image

docker run --rm \
  -p 127.0.0.1:9090:9090 \
  -v "$(pwd)/data:/data/ghidra_projects" \
  --security-opt no-new-privileges:true \
  biniamfd/ghidra-headless-rest:latest
```

For a reproducible pin, use the tested release digest instead of `latest`:

```bash
docker run --rm \
  -p 127.0.0.1:9090:9090 \
  -v "$(pwd)/data:/data/ghidra_projects" \
  --security-opt no-new-privileges:true \
  biniamfd/ghidra-headless-rest:1.2.1@sha256:971591a3a8448d8ed969079b452306e806f36079c3ddd298f4a618d6e2f1442d
```

## Prerequisites

- Docker and Docker Compose (for the Quick Start path), or Python 3.10+ and
  Node.js 18+ (for running from source).
- An OpenAI-compatible LLM endpoint (local or hosted) and model name.
- The public Ghidra image: `biniamfd/ghidra-headless-rest:latest`.

## Essential environment variables

Copy `.env.example` to `.env` and fill these in; see that file for the full
list and defaults.

| Variable | Default | Meaning |
| --- | --- | --- |
| `API_BASE` | required | OpenAI-compatible base URL (http/https). Compose fails early when absent. |
| `API_KEY` | `not-used` | Provider key. Never logged or sent to the browser; `not-used` is valid for keyless local providers. |
| `MODEL_NAME` | required | Model id expected by the configured endpoint. Compose fails early when absent. |
| `LLM_STREAM` | `auto` | Streaming transport: `auto` (stream, fall back to blocking once on a pre-output compatibility error), `true` (always stream), `false` (always blocking). |
| `GHIDRA_API_BASE` | `http://127.0.0.1:9090` | Ghidra service base URL. |
| `GHIDRA_IMAGE` | `biniamfd/ghidra-headless-rest:1.2.1@sha256:971591a3...` | Tested release pinned by immutable digest. `:latest` also resolves to this digest; override to pin a different release. |
| `HOST` / `PORT` | `127.0.0.1` / `5000` | Dev-server bind. |
| `MAX_UPLOAD_BYTES` | `104857600` | Upload size cap. |
| `CHATS_DIR` | `webui/chats` | Chat history directory. |

## LLM provider

Rev·Deck talks to **any OpenAI-compatible Chat Completions endpoint** through
the OpenAI SDK, configured entirely by `API_BASE` / `API_KEY` / `MODEL_NAME`.
There is no provider-specific header, parameter, or model logic: a local
[Ollama](https://ollama.com) server (`API_BASE=http://127.0.0.1:11434/v1`), a
self-hosted vLLM/llama.cpp/LM Studio endpoint, OpenAI itself, or a gateway such
as OpenRouter all work the same way.

Example `.env` provider settings (use placeholders, never commit real keys):

```dotenv
# Ollama
API_BASE=http://127.0.0.1:11434/v1
API_KEY=not-used
MODEL_NAME=qwen3:8b
```

```dotenv
# OpenRouter
API_BASE=https://openrouter.ai/api/v1
API_KEY=replace-with-your-key
MODEL_NAME=anthropic/claude-opus-4.8
```

```dotenv
# OpenAI
API_BASE=https://api.openai.com/v1
API_KEY=replace-with-your-key
MODEL_NAME=replace-with-a-supported-model-id
```

```dotenv
# LM Studio, vLLM, or llama.cpp (adjust port/model to the server)
API_BASE=http://127.0.0.1:1234/v1
API_KEY=not-used
MODEL_NAME=replace-with-the-served-model-id
```

By default (`LLM_STREAM=auto`) the assistant requests a **streamed** response
and relays tokens to the browser as they arrive. Streaming also gives a
stronger cancellation guarantee: when you stop a response (or close the tab),
Rev·Deck promptly closes the underlying provider stream and performs no further
tool or model rounds, so upstream generation is torn down rather than left
running to completion in the background.

Caveats:

- **Billing.** Cancelling closes the stream on our side immediately, but some
  hosted providers still bill for tokens they had already generated (or for the
  whole completion) regardless of an early client disconnect. The guarantee is
  about *not doing more work*, not about a provider's billing policy.
- **Compatibility.** Not every OpenAI-compatible endpoint accepts
  streaming-with-tools. Under `auto`, if the provider rejects the streamed
  request with a compatibility error (HTTP 400/404/405/422) *before any* content
  or tool-call output, Rev·Deck falls back to a single blocking call once and
  remembers that for the rest of the process. Auth (401/403), rate-limit (429),
  and server (5xx) errors are **not** treated as compatibility problems and are
  surfaced as errors instead of silently retried. Set `LLM_STREAM=false` to skip
  streaming entirely, or `LLM_STREAM=true` to require it (no fallback).

## How to use

Open the app and upload a binary to start an analysis job. Obvious plain-text
content asks for confirmation before it is sent to Ghidra; use the explicit raw-
binary override only when the content is intentionally firmware/data rather than
an executable format. Once analysis completes, switch between two workspace tabs:

- **Analysis** — deterministic evidence views: summary, functions
  (filter/paginate), imports, strings, a query view, a function inspector
  (pseudocode, cross-references, bounded call graph, hexdump), and — when the
  connected Ghidra service supports them — types, globals, sidecar
  annotations, archive export, and a deterministic Attack Surface ranking with
  explainable positive/mitigating signals and evidence coverage.
- **Chat** — the assistant, in one of two modes:
  - **Copilot** (default): one bounded step/tool call per message, for
    ad-hoc questions.
  - **Autonomous**: start a named, budgeted workflow that runs multiple
    bounded steps on its own and shows a live activity timeline as it works.

Both modes take a per-task **step budget**, and a **No step limit** option that
runs until the task finishes (still capped by `MAX_STEP_BUDGET` so a looping
model cannot run away). If a run reaches its budget, it reports partial results
and offers **Continue** — which resumes the same conversation using the evidence
already retrieved, without redoing completed tool calls. Cost grows with the
number of tool/model calls, so higher budgets cost more.

Available workflows:

| Workflow | Purpose | Requires a target function address |
| --- | --- | --- |
| `program_triage` | Summarize the program's likely purpose from metadata, imports, strings, and functions. | No |
| `suspicious_behavior` | Surface deterministic indicators first, then bounded, clearly-labeled hypotheses. | No |
| `selected_function` | Decompile a function and explain it with its callers/callees. | Yes |
| `call_chain` | Explore one bounded native/synthesized call-graph neighborhood from a starting function. | Yes |
| `attack_surface_triage` | Read deterministic score coverage/top-K, then deeply inspect at most three candidates; scores are priorities, not verdicts. | No |
| `vulnerability_hypothesis` | Select one bounded candidate and present evidence, counter-evidence, and open questions; never auto-confirms. | No |

### Focused sub-investigations

Each analysis job has a **Main** chat plus optional focused sub-threads. Choose
**New sub-investigation**, enter a one-line briefing, and work with a fresh
conversation context over the same binary and the same read-only tools. Thread
histories remain isolated, and only one thread streams at a time.

When the focused work is ready, choose **Return conclusion to parent**. Rev·Deck
makes one bounded model call over that sub-thread only, validates its evidence
citations, and adds one provenance-marked conclusion card to the parent. The
full branch remains reopenable, while the parent context receives only the
compact conclusion—not the branch transcript. A returned card with no validated
citations is explicitly marked unverified.

Assistant answers cite evidence inline as `[function:0xADDR]`,
`[string:0xADDR]`, or `[import:name]`. Citations are checked against what was
actually retrieved during the turn; a citation that doesn't match is flagged
"(unverified)" and should be treated as an unconfirmed claim, not fact.

Mermaid diagrams in assistant output (e.g. call-graph sketches) render in a
sandboxed frame with no external network access.

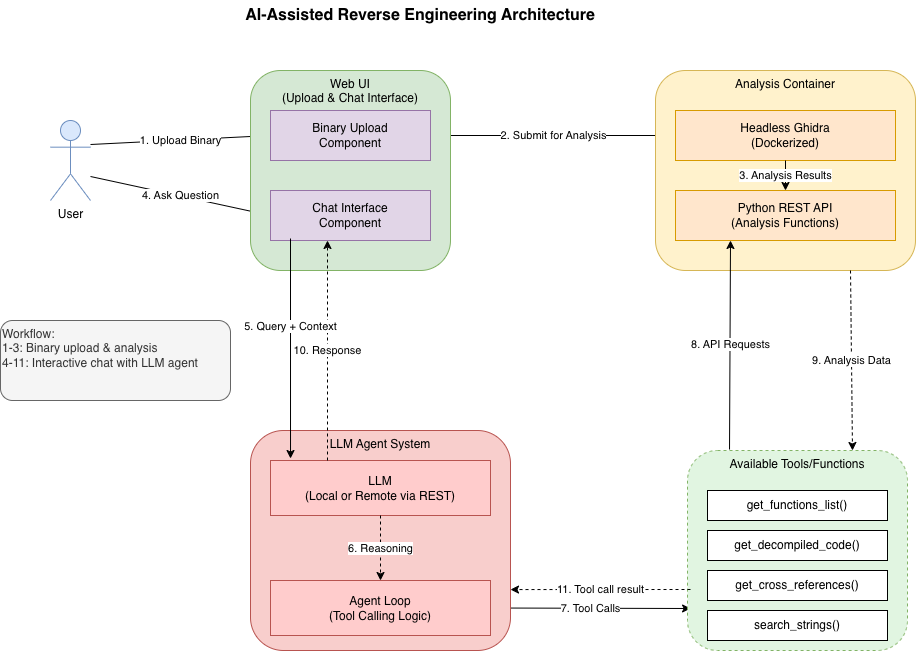
## Architecture

The browser talks only to the Rev·Deck web application. Rev·Deck coordinates the
configured LLM and the headless Ghidra service, then presents the resulting
evidence and agent activity in one workspace.

<img width="916" height="651" alt="Rev·Deck architecture" src="https://assets.kitploit.com/production/public/readmes/9561/40809484745cf03bf42790c8abff0146755ebb953a3774c8fac17fbc3c0552de.png" />

## Running from source

```bash
python -m venv .venv && source .venv/bin/activate
pip install -r requirements.txt
npm ci && npm run vendor        # one-time: vendors the pinned Mermaid runtime

cp .env.example .env            # edit API_BASE / MODEL_NAME / API_KEY
set -a; source .env; set +a     # plain Python does not load .env automatically

# Start the separate Ghidra service, then:
python webui/app.py
```

Open http://127.0.0.1:5000. Docker Compose reads `.env` automatically; source
execution requires exporting it as shown above. The Flask development server is
fine for local use; the Docker image runs Gunicorn.

## Security / local-only boundary

This is designed for one trusted analyst on their own machine — not for
multi-user or public hosting. By default the app and the Ghidra service bind
only to `127.0.0.1`, debug mode is off, uploaded binaries are never executed,
and the LLM provider key stays server-side.

## Testing

```bash
pip install -r requirements.txt -r requirements-dev.txt
python -m pytest
node --test "webui/static/js/tests/**/*.test.mjs"
npm ci && npm run vendor:verify   # verifies the vendored Mermaid bundle's integrity
```

## Troubleshooting

- **"Service offline" / `/readyz` returns 503** — the Ghidra service is
  unreachable at `GHIDRA_API_BASE`, or `API_BASE`/`MODEL_NAME` is unset.
- **Types/Globals/Annotations show "requires v1"** — the connected Ghidra
  service doesn't advertise that capability; expected on older services.
- **Chat errors immediately** — verify `API_BASE`/`API_KEY`/`MODEL_NAME` and
  that the provider is reachable within `LLM_TIMEOUT`.
- **Upload rejected as too large** — raise `MAX_UPLOAD_BYTES`.
- **Upload looks like plain text** — Rev·Deck asks before sending it to Ghidra;
  continue as raw binary only when intentional.
- **Large analysis times out** — increase the Ghidra container's
  `ANALYSIS_TIMEOUT` (for example `5400` for 10k+ function C++/Android binaries)
  and re-upload. `LLM_TIMEOUT` is unrelated.
- **A citation shows "(unverified)"** — the model cited evidence it never
  actually retrieved; treat that claim as an unconfirmed hypothesis.