 #1
LLM security, prompt injection, model extraction, adversarial AI, and AI red teaming tools.
Kitploit recommended
 promptfoo/modelaudit
Security scanner for AI/ML model files. Detects malicious code, backdoors, and vulnerabilities before deployment
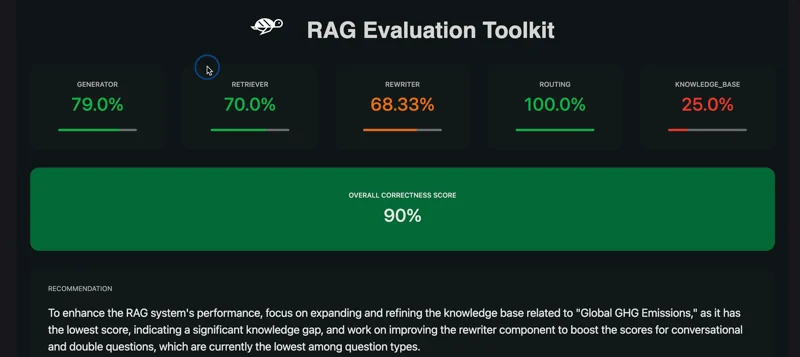 giskard-ai/giskard-oss
🐢 Open-Source Evaluation & Testing library for LLM Agents
 meta-llama/purplellama
Set of tools to assess and improve LLM security.
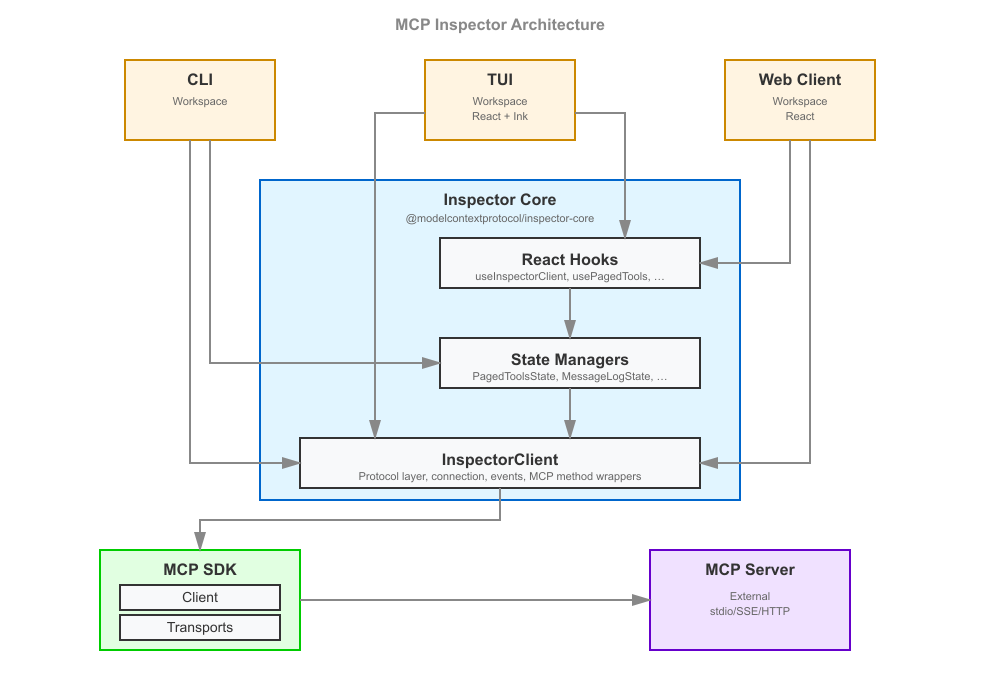 modelcontextprotocol/inspector
Inspect, debug, and visually test Model Context Protocol (MCP) servers from a web UI, CLI, or TUI, with tool/resource exploration, request logging,…
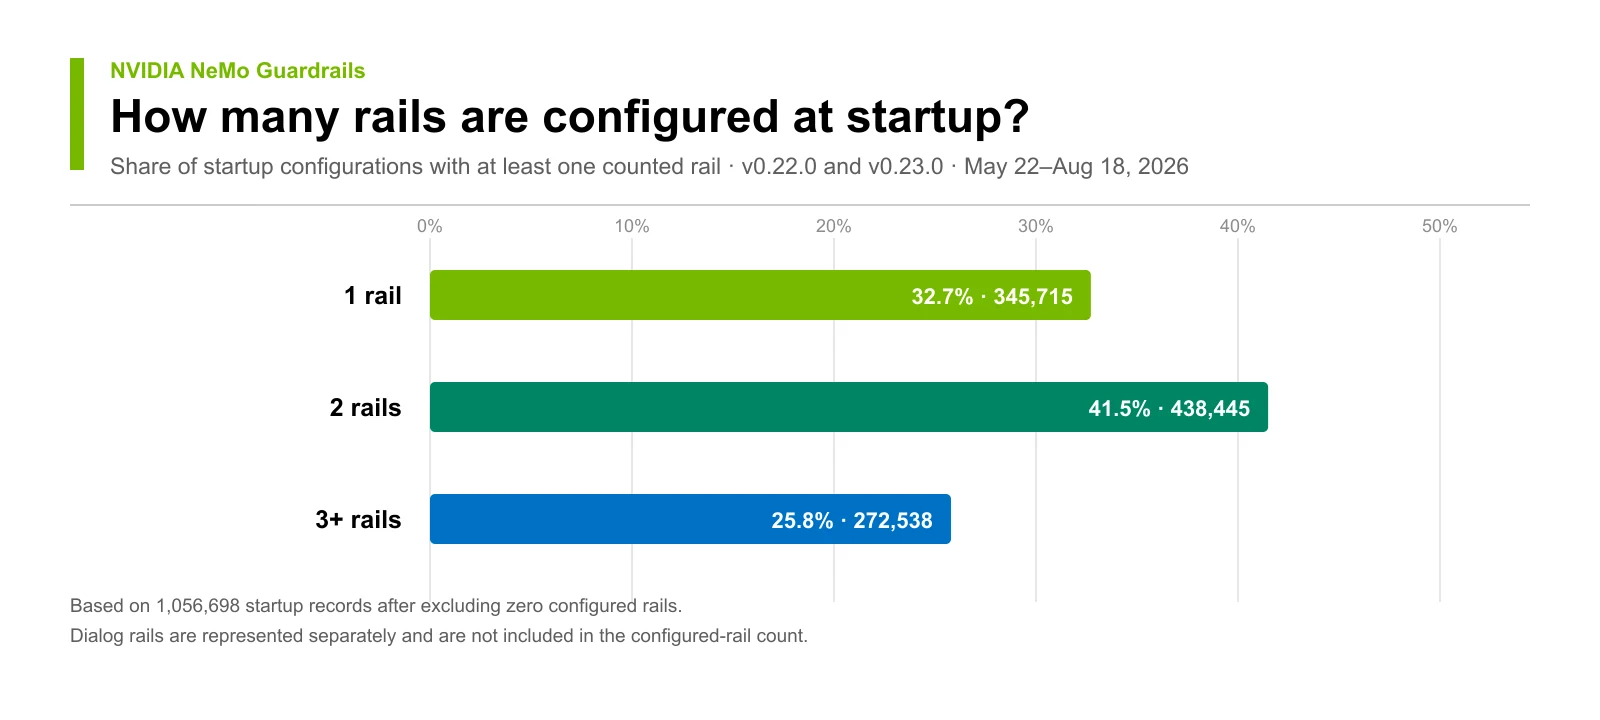 nvidia-nemo/guardrails
Programmable guardrails for LLM chat apps: enforce input/output rails, block jailbreaks and prompt injections, detect hallucination, and mask…
 s0ld13rr/pentestcode
Autonomous AI penetration testing agent that orchestrates multi-agent recon, exploitation, post-exploitation, and reporting with persistent…
 appsec-forge/appsec-forge
Structured security knowledge base with production-inspired cases: vulnerability analysis, exploit explanation, remediation, and DevSecOps for…
 ransomleak/training-security-awareness
Open-source interactive security awareness training library with 130+ SCORM exercises covering phishing, vishing, BEC, MFA fatigue, and OWASP AI/LLM…
 wattocyber/lm-fingerprint
Fingerprint OpenAI-compatible LLMs from tokenizer and behavior signals.
 wattocyber/agentic-dm-gateway
Security control plane for LLM agents: allowlists, owner kill switch, PIN sessions, rate limits, prompt-injection detection, and output scrubbing to…
 yeasen-z/leakgauge
Detects LLM context-leakage attacks by training lightweight behavior probes on log-probabilities, with vLLM offline/server detection pipelines.
 zaydmulani09/sentrymcp
A static + runtime security scanner for MCP (Model Context Protocol) servers
 qianlijaingshan/fastgpt-sandbox-audit
FastGPT Python sandbox escape chain audit tool (CVE-2026-32128 related, v4.14.8 inspect chain)
 boreas37/cve-2025-62593-poc
PoC for CVE-2025-62593: unauthenticated RCE in Ray (CISA KEV). Stdlib-only Python.
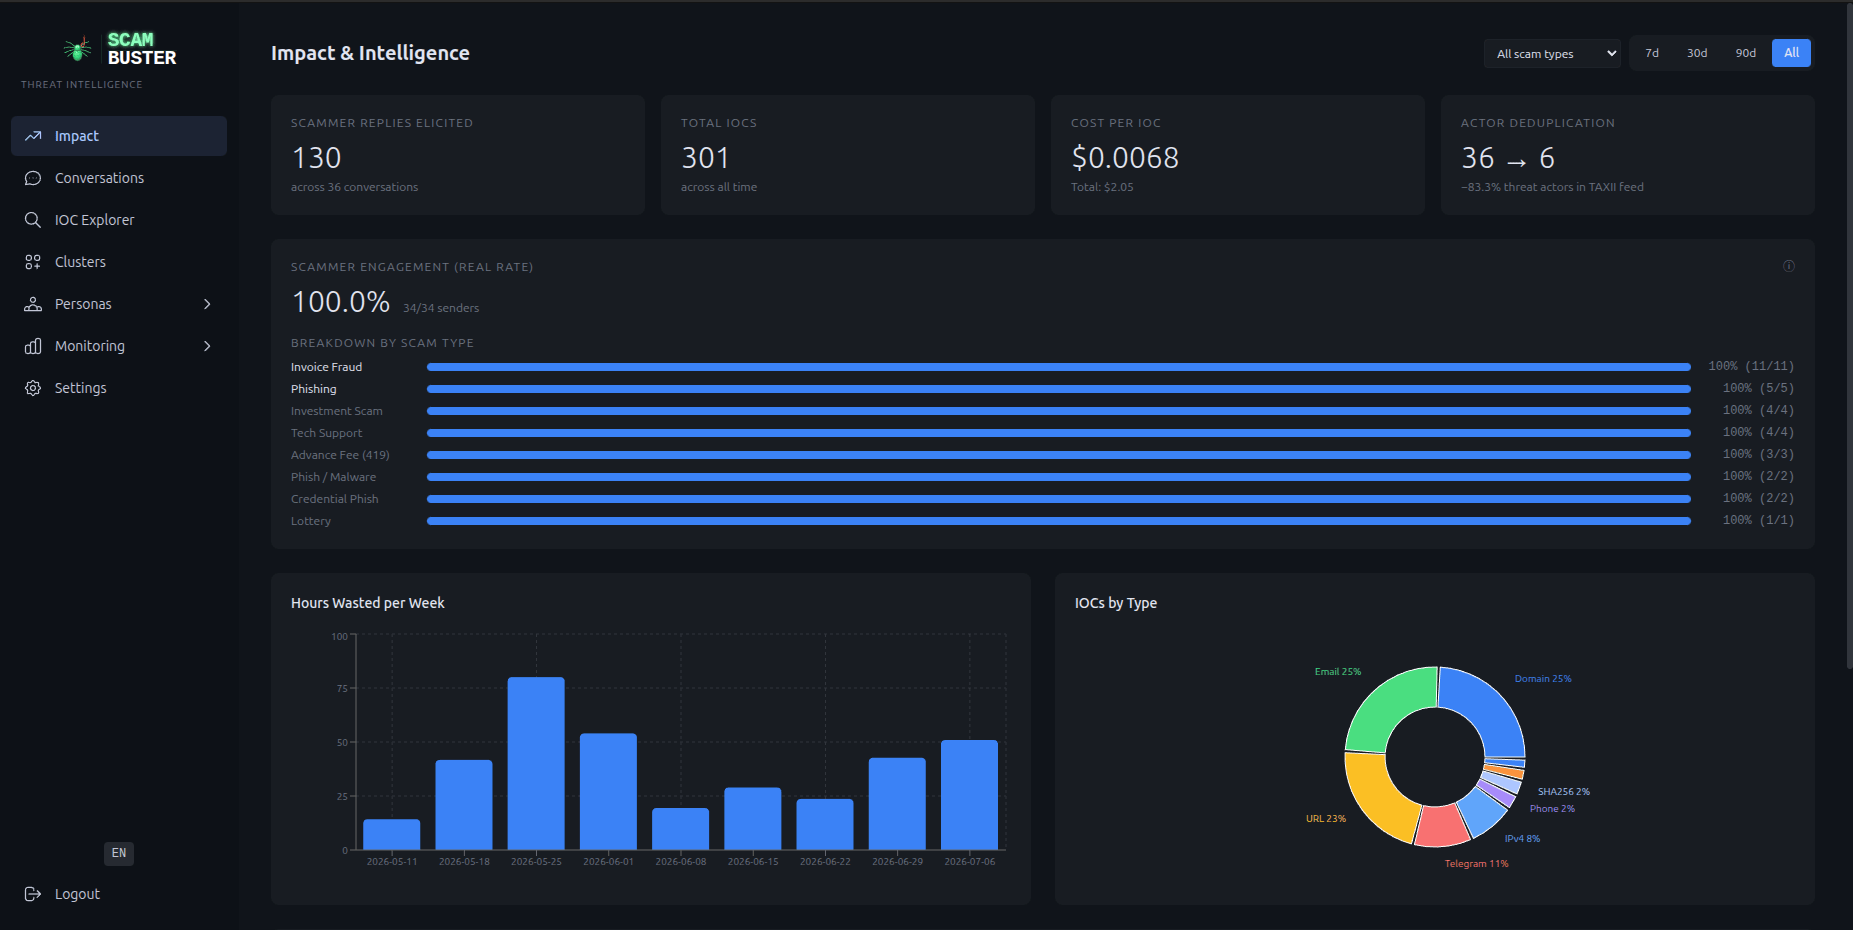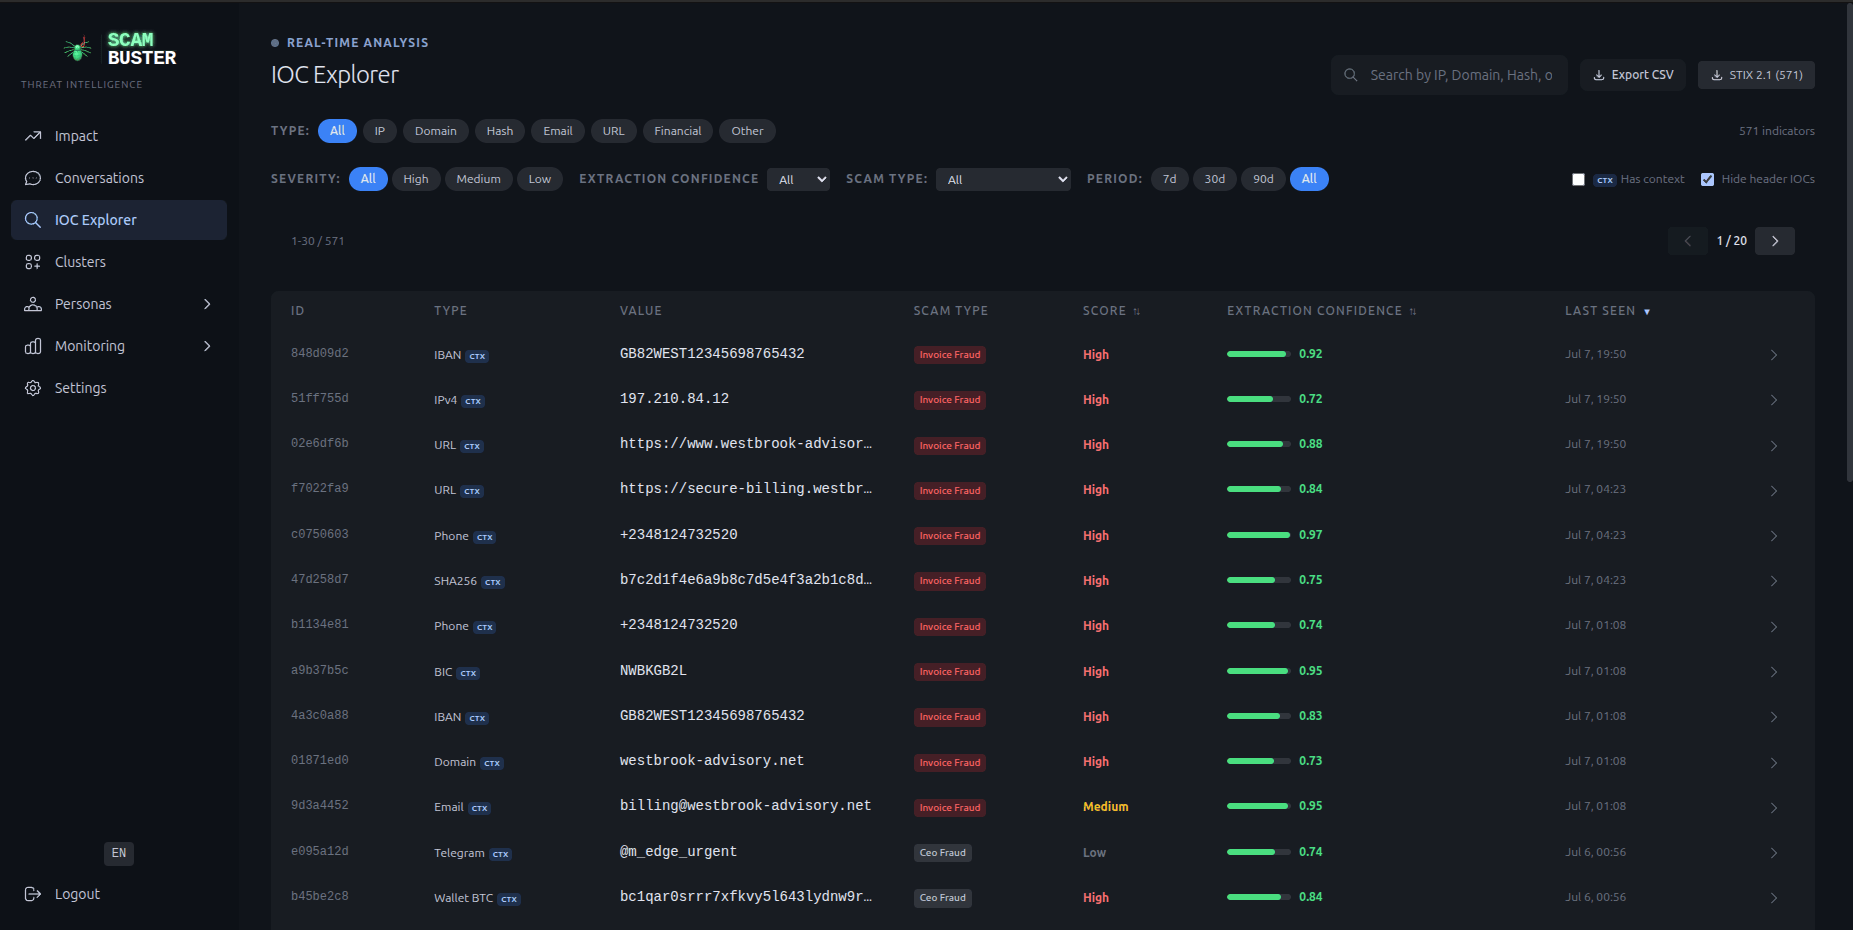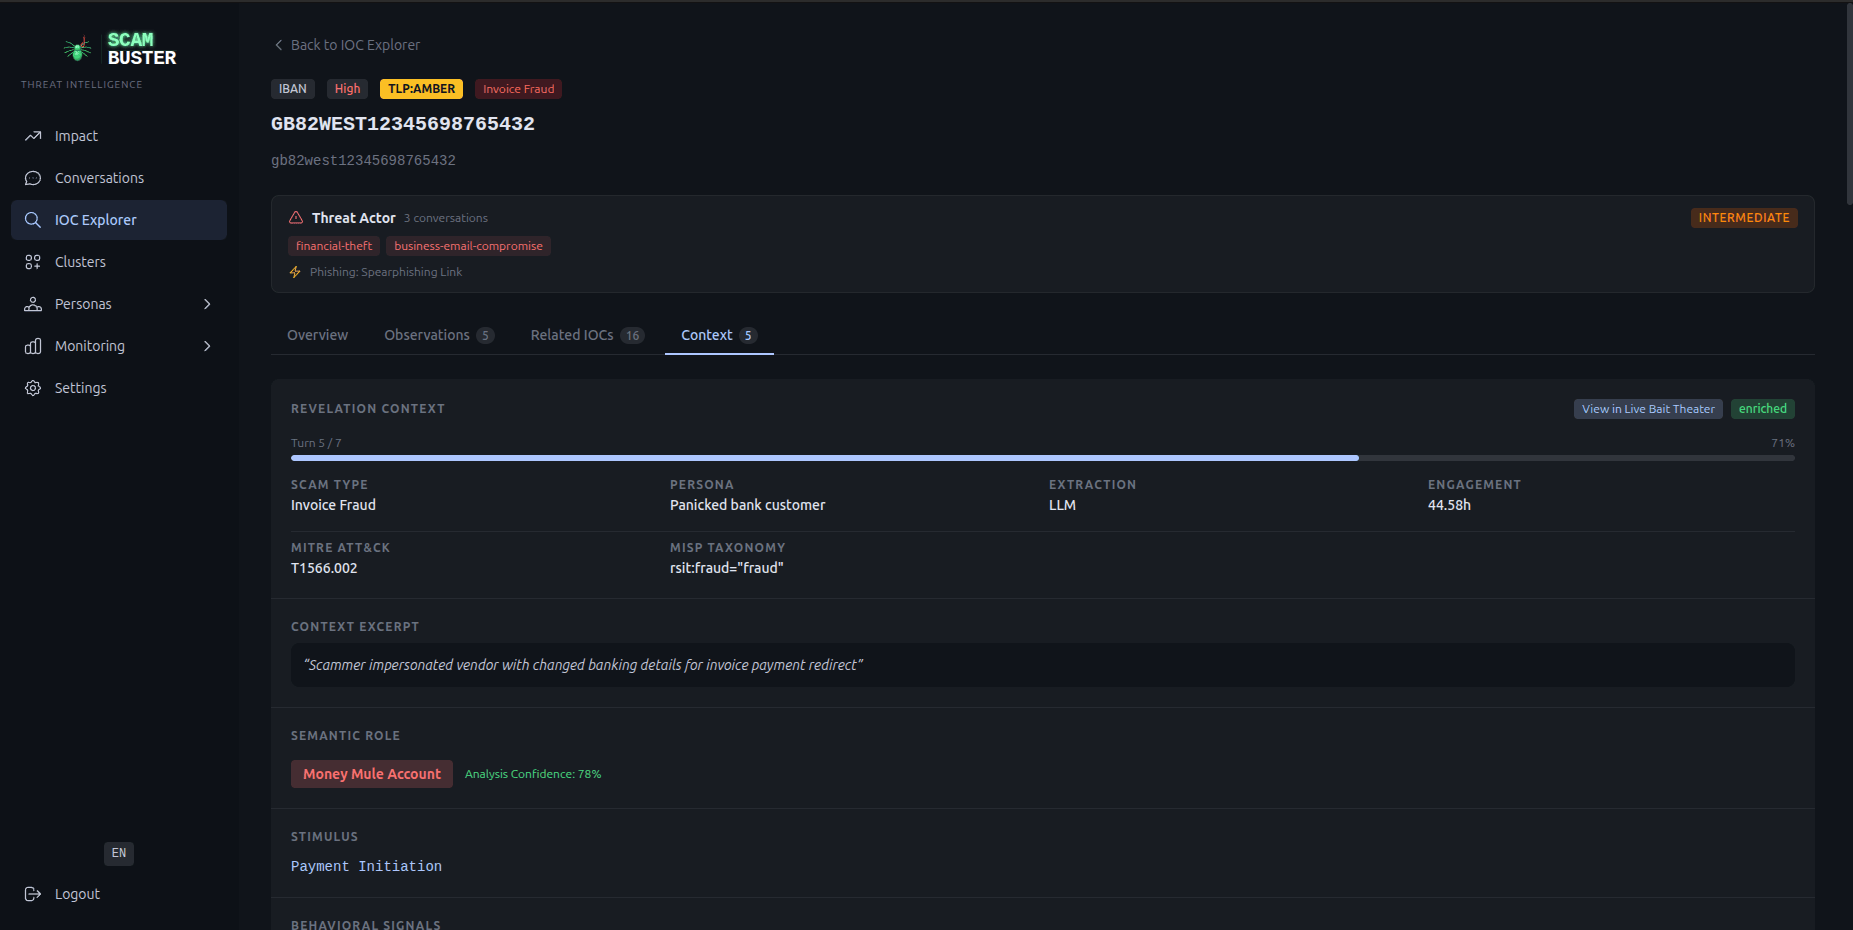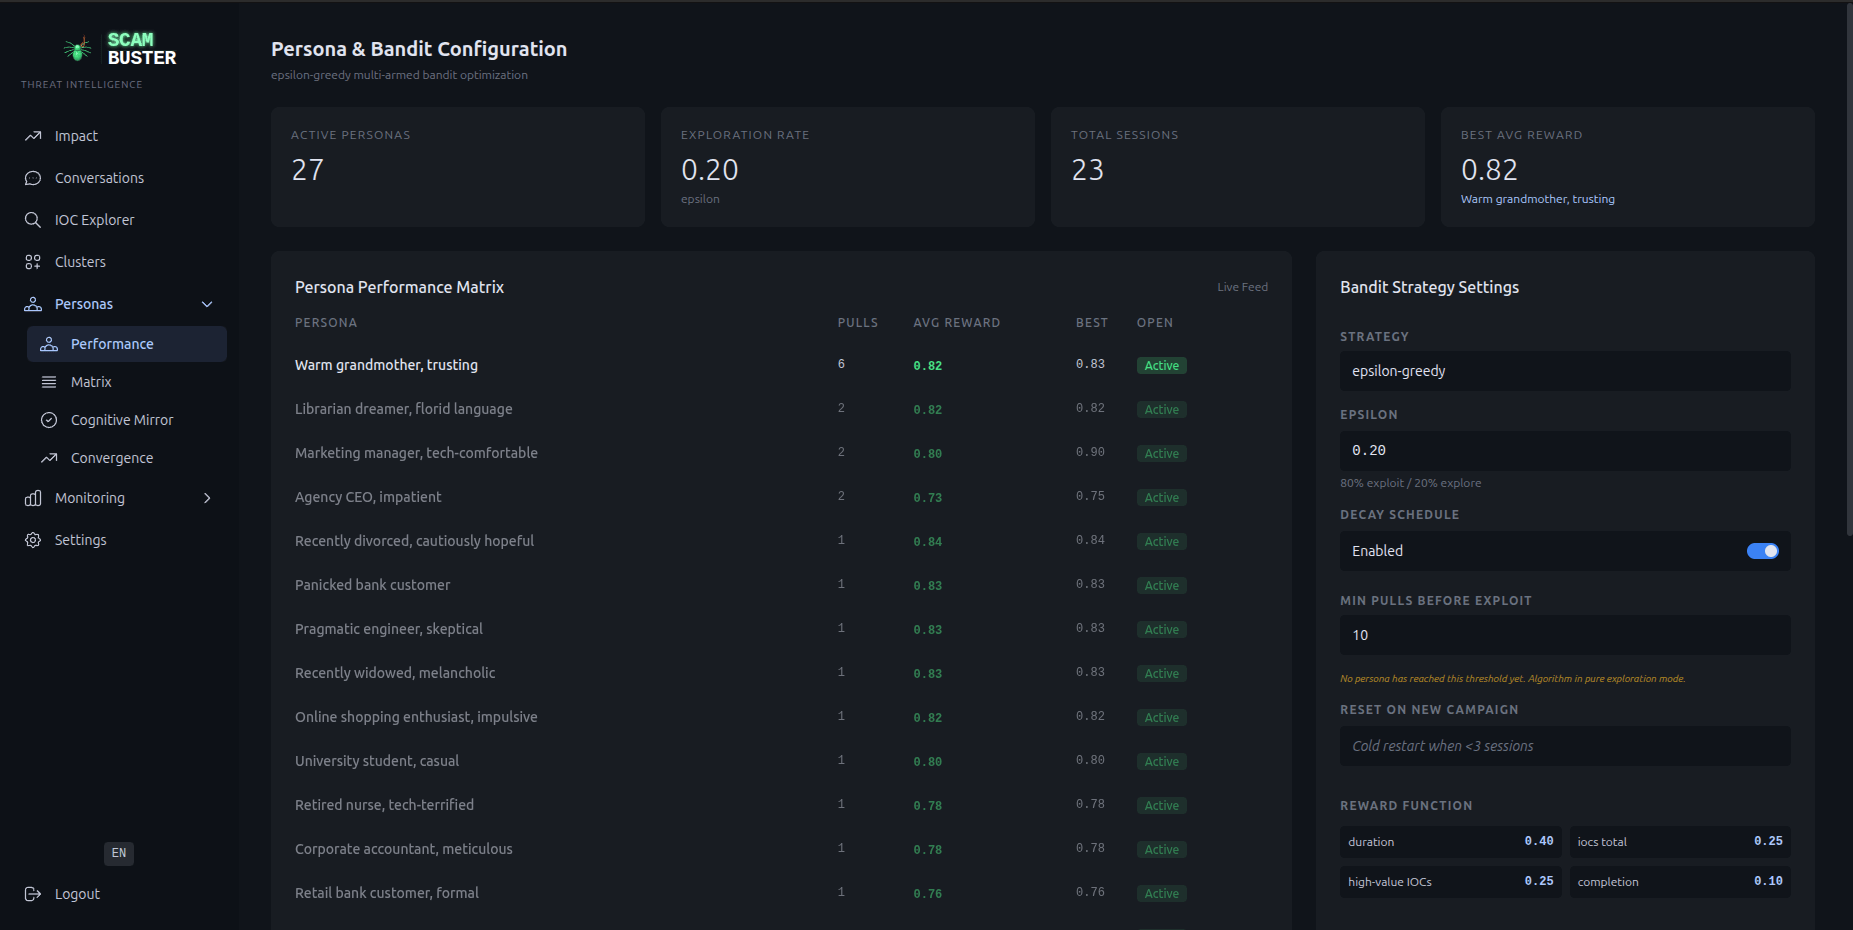 laugiov/scambuster
Defensive engagement & threat intelligence research laboratory. Converts inbound scam emails into actionable IOCs through controlled, policy-driven…
 gmh5225/awesome-ai-security
A curated list of AI Security materials and resources for Pentesters, Bug Hunters, and Security Researchers.
 wattocyber/masq
Live recon and posture auditing for AI agent infrastructure: scans MCP configs, session logs, and APIs for secrets, poisoned catalogs, and CoT leaks.
 wattocyber/gradient-untangler
Local white-box gradient attacks for open-weight LLMs: GCG/PEZ suffix search, layer saliency, weight snapshots, and rank-1 suffix-to-delta fitting…