
Skip to content
KitploitKITPLOIT
أدواتعمليات الاستغلالالمدونة
Log in
إرسال
أدواتعمليات الاستغلالالمدونة
إرسال

أدوات الاختراق واختبار الاختراق والأمن السيبراني لترسانتك الأمنية!

Kitploit هو دليل لأدوات الاختراق والأمن السيبراني واختبار الاختراق. اكتشف آخر تحديثات المشاريع للعثور على الثغرات وتحليل الأنظمة وأتمتة الاختبارات وتعزيز أمنك.

الخلاصاتاتصالالخصوصية© 2026 Kitploit

دليل الأدوات

الفئات

عرض جميع الفئات
Loading categories
trawl — Self-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr alternative and drop-in replacement for your *arr stack. | Kitploit
أدوات/GitHubGitHub/germondai/trawl
Web Proxies & InterceptionInformation GatheringWeb SecurityUtilities & FrameworksCrawlerAnti-BotFingerprint SpoofingCAPTCHA Bypass
GitHubgermondai/trawl

trawl

Self-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr alternative and drop-in replacement for your *arr stack.


عرض المستودع
97159641منذ 8 أيامتمت المراجعة من قبل Kitploit

الأكثر شعبية

عرض الكل →

اكتشف الأدوات الأكثر استخدامًا من قبل مجتمعنا.

استكشف جميع الأدوات

تصفح مجموعتنا من الأدوات

عرض جميع الأدوات →
الموقع الإلكتروني
مشاركة
المحتوى غير متوفر باللغة المطلوبة. عرض النسخة الإنجليزية.


TRAWL

Welcome to TRAWL! 👋

Self-hosted web scraping for applications and AI agents. Fetch pages through the native API, or connect an MCP client to read clean Markdown, extract structured data, capture screenshots, and inspect browser activity.

TRAWL starts with a fast HTTP request, reuses solved browser sessions, and escalates to Camoufox and an optional residential proxy when a site requires more work. It handles supported JavaScript challenges and CAPTCHAs, and gives you a local dashboard to see what succeeded, failed, and took time.

For existing FlareSolverr users, the compatible /v1 endpoint works with Prowlarr and other *arr tools. TRAWL's adaptive routing and session reuse are designed for faster, more reliable requests; selected same-machine benchmarks show faster responses than FlareSolverr and Byparr, with results varying by site and session state.
Features

  • Isolated browser sessions - preserve login cookies and localStorage across native API, MCP and FlareSolverr requests, with capacity limits and automatic idle expiry. Session API.
  • MCP tools for AI agents - read pages as Markdown or text, scrape HTML, extract JSON records, capture screenshots, and inspect browser diagnostics from known public URLs
  • 4-tier execution - plain HTTP fetch → cached browser session → fresh challenge solve → optional residential proxy
  • Structured extraction and screenshots - select fields from repeated elements, render JavaScript pages, and capture a viewport, full page, or specific element
  • Challenge-aware HTTP/HTTPS proxy - direct forwarding for normal traffic, automatic tier escalation for detected walls, plus WebSockets, binary bodies, and Range/206 support
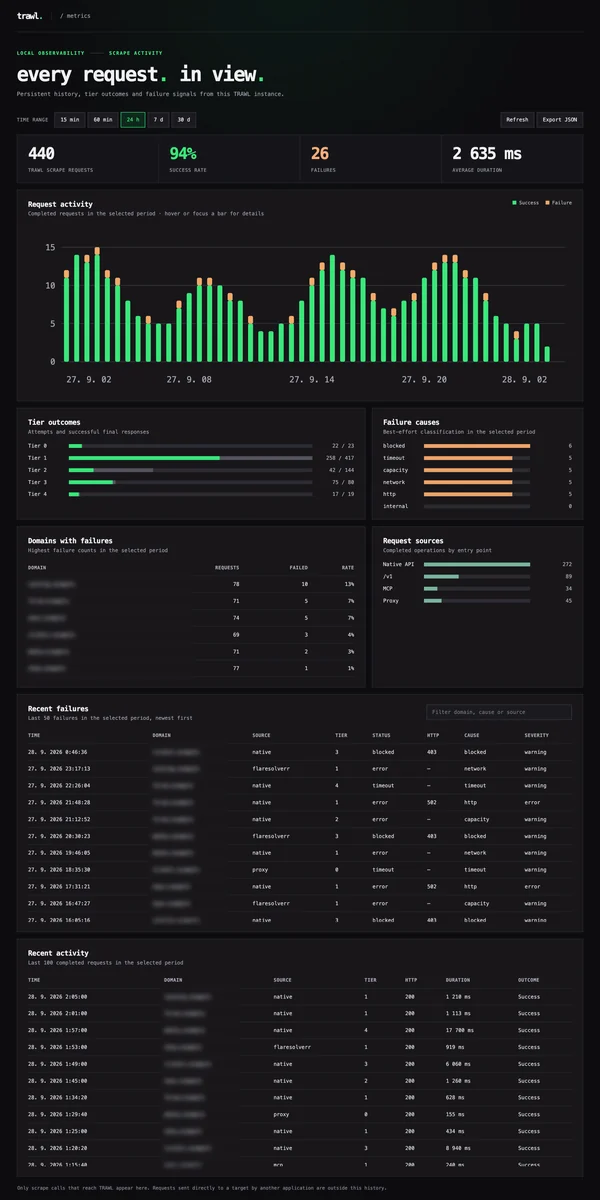
  • Local metrics dashboard - persistent request history, tier outcomes, failure causes, and live updates
  • Multi-WAF handling - dedicated Cloudflare, Akamai Bot Manager, and Imperva/Incapsula detection and browser flows
  • Native captcha solving - CF Turnstile/Interstitial, reCAPTCHA v2 (free STT), hCaptcha checkbox/audio where available, GeeTest Slide, ALTCHA, Friendly Captcha v1/v2, and CAP proof-of-work
  • Camoufox Firefox - fingerprint-patched at the C++/Juggler level to reduce automation signals
  • Session cache - solved cookies and browser identity stored in Redis; accepted sessions can avoid a fresh solve
  • FlareSolverr compatible - works with Prowlarr, Jackett, Sonarr, and the full *arr ecosystem out of the box
  • Local solving by default - no paid solver API required; optional 2Captcha fallback for reCAPTCHA v2/Enterprise and standalone Turnstile, with site-specific profiles for other documented task types

Sponsors

View/Collapse All
Birght Data Bright Data - The most powerful platform for Web Unlocker, SERP API and web scraping tools.

Why Bright Data?
• Web Unlocker - bypass any anti-bot protection
• SERP API - real-time Google, Bing & more results
• Scraping Browser & dedicated scrapers
• Massive residential proxy network
• Built for scale and reliability

Get started for free with Bright Data!
NodeMaven NodeMaven - The most efficient proxy provider for Web Scrapping and Automation with the Highest Quality IP on the market.

Why NodeMaven?
• ZIP targeting
• 99.9% uptime
• IP filtering: all proxies have fraud score <97%
• No KYC required
• Unique free tools: Proxy Bandwidth Checker, Meta Tag Checker, IP Lookup and others!

Special codes for TRAWL users:
• TRAWL35 - 35% off to Mobile and Residential Proxies
• TRAWL40 - 40% off to ISP (Static) Proxies
Thordata Thordata - Premium Residential Proxies for Data Collection.

Thordata helps developers build reliable scraping, automation, and AI data workflows with high-quality residential IPs.

🌍 100M+ real IPs | 195+ countries
🔄 Rotating & sticky sessions | Precise geo-targeting
⚡ High concurrency | Stable connections

Reduce blocks and collect data at scale with confidence.

🎁 TRAWL users:
• 3-day free trial + 10% OFF Code: TRAWL10

Local dashboard

TRAWL metrics dashboard showing illustrative request data

The screenshot uses illustrative traffic. Your dashboard at http://localhost:8191/dashboard displays only requests handled by your TRAWL instance. See the metrics guide for setup.

Quick start

# Clone and configure
git clone https://github.com/germondai/trawl
cd trawl
cp .env.example .env

# Start scraper + Redis
docker compose up -d
تنزيل الأداة