 edoardottt/cariddi
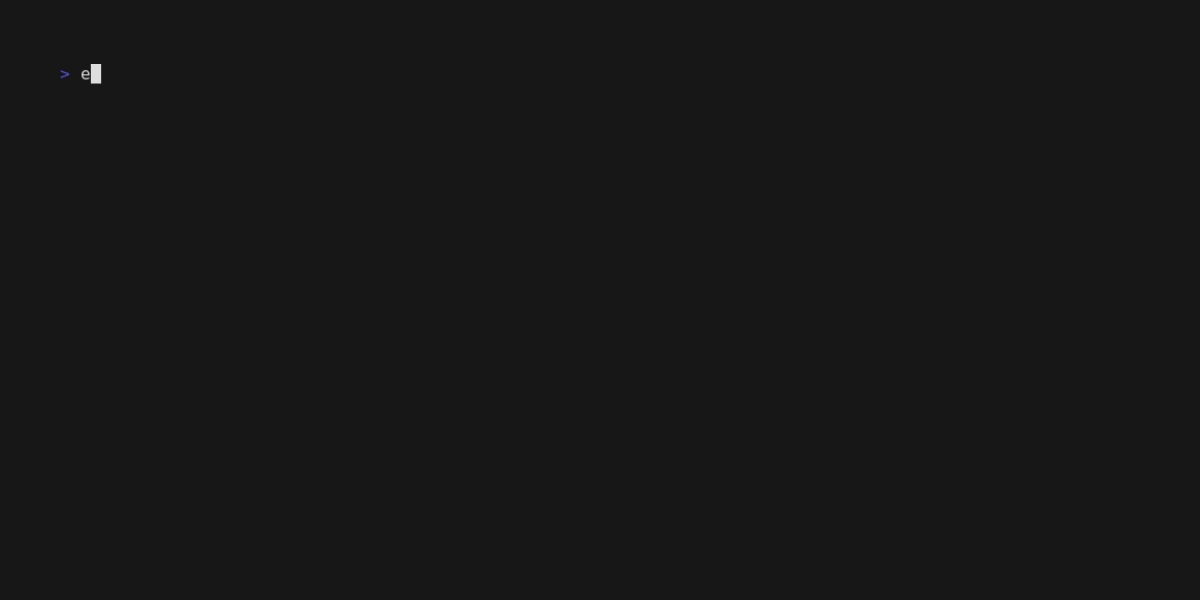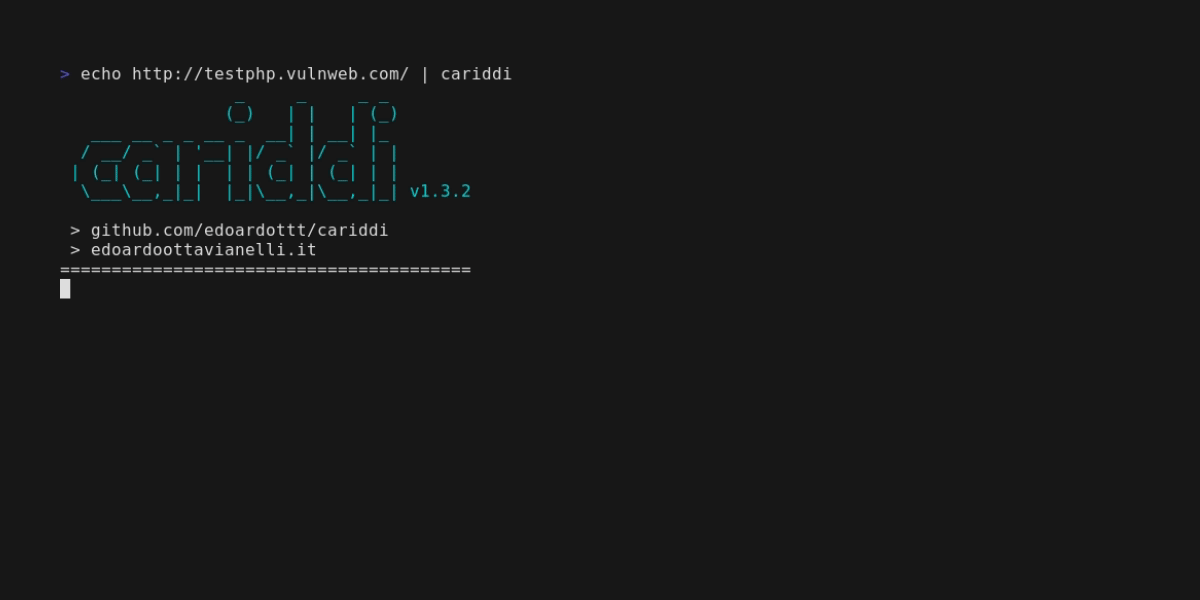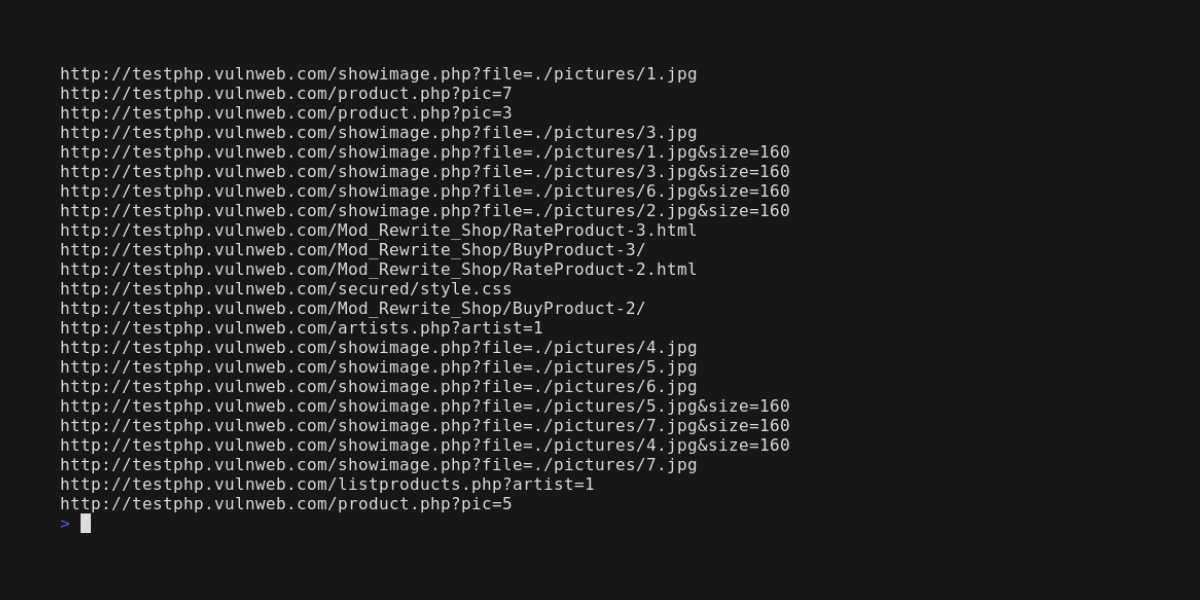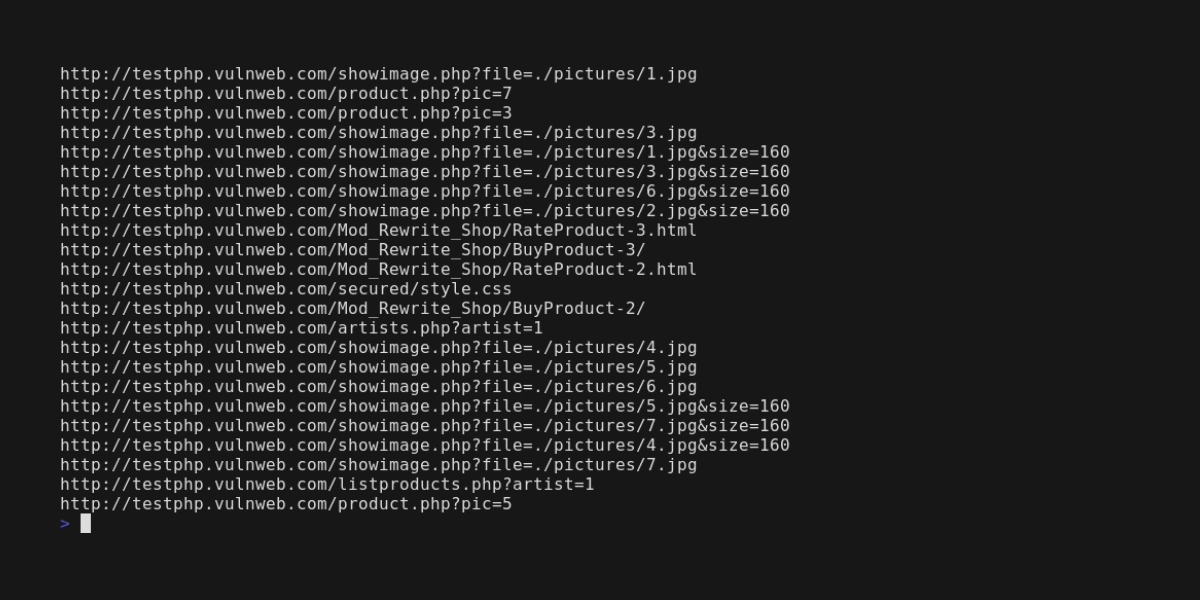
Pegue uma lista de domínios, faça crawl de urls e escaneie por endpoints, segredos, chaves de API, extensões de arquivo, tokens e mais.

Pegue uma lista de domínios, rastreie URLs e procure por endpoints, segredos, chaves de API, extensões de arquivo, tokens e muito mais

Coded with 💙 by edoardottt
Compartilhe no Twitter!
Instalação • Uso • Começando • Changelog • Contribuindo • Licença
brew install cariddi
sudo snap install cariddi
go install -v github.com/edoardottt/cariddi/cmd/cariddi@latest
pacman -Syu cariddi
nix-shell -p cariddi
Você precisa do Go (>=1.24.0)
git clone https://github.com/edoardottt/cariddi.git
cd cariddi
go get ./...
make linux # (to install)
make unlinux # (to uninstall)
One-liner: git clone https://github.com/edoardottt/cariddi.git && cd cariddi && go get ./... && make linux
Observe que o executável funciona apenas na pasta cariddi.
git clone https://github.com/edoardottt/cariddi.git
cd cariddi
go get ./...
.\make.bat windows # (to install)
.\make.bat unwindows # (to uninstall)
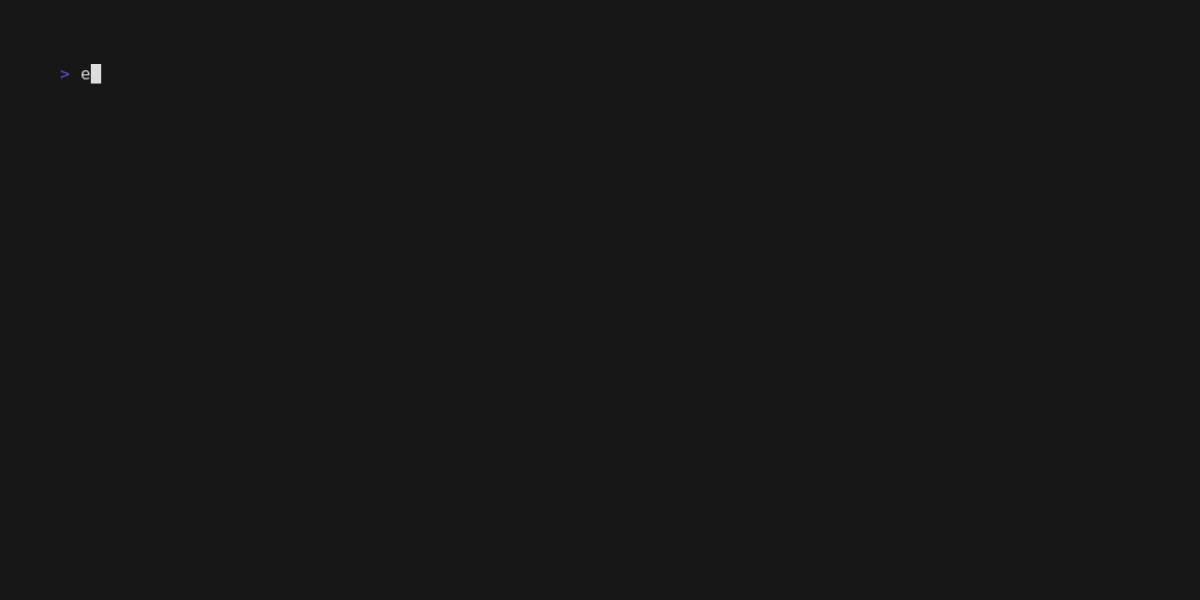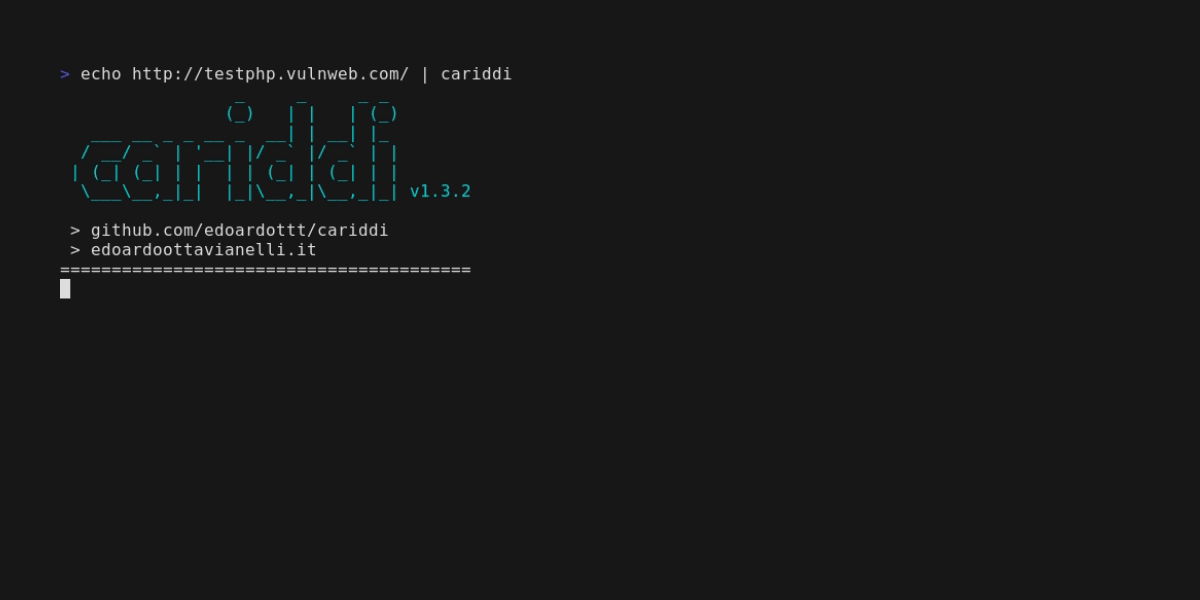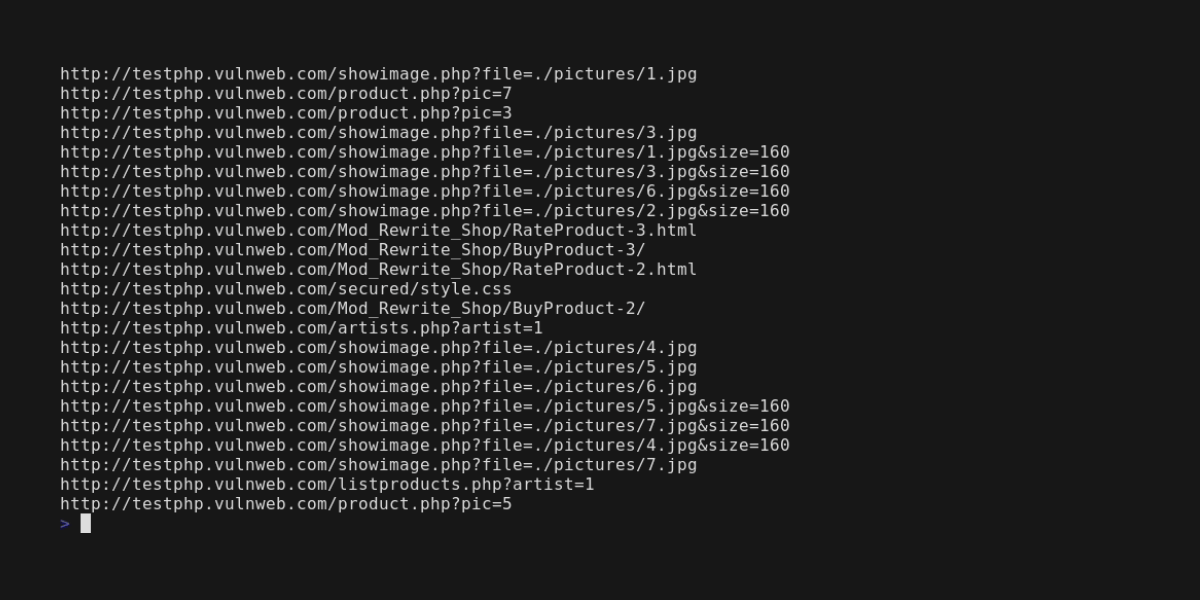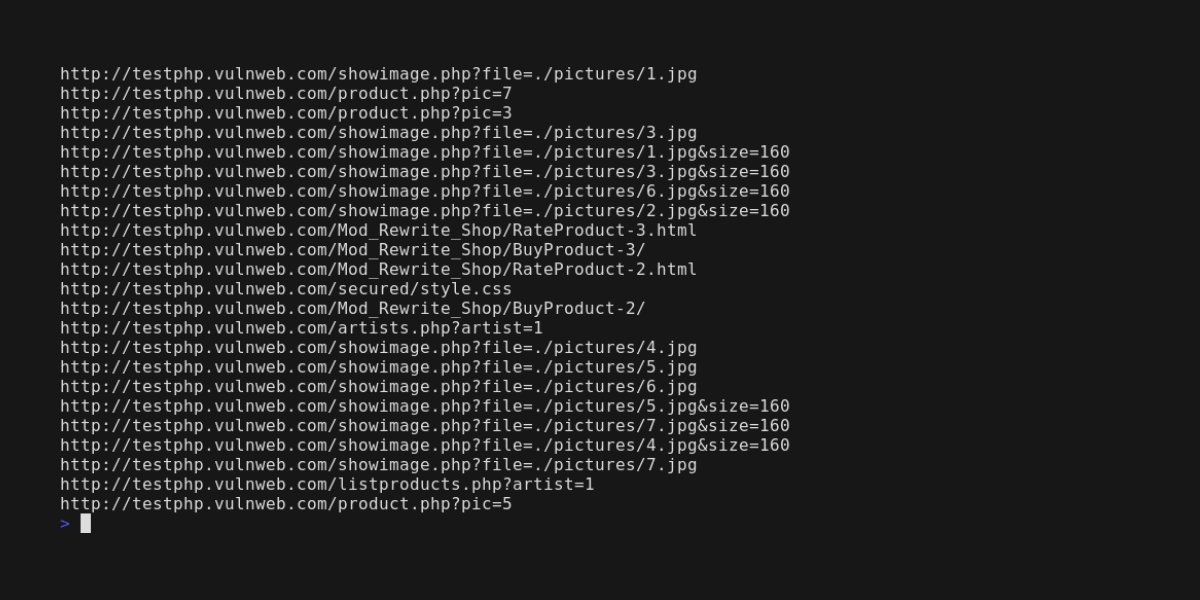
Se você quiser escanear apenas um único alvo, você pode usar
echo https://edoardottt.com/ | cariddi
Com múltiplos alvos, você pode usar um arquivo, por exemplo, urls.txt contendo:
https://edoardottt.com/
http://testphp.vulnweb.com/
Para Windows:
powershell.exe -Command "cat urls.txt | .\cariddi.exe" dentro do Prompt de Comandocat urls.txt | cariddi.exe usando o PowerShellcariddi -version (Imprime a versão)cariddi -h (Imprime a ajuda)cariddi -examples (Imprime os exemplos)cat urls.txt | cariddi -intensive (Rastreia procurando também subdomínios, o mesmo que *.target.com)cat urls.txt | cariddi -s (Procura por segredos)cat urls.txt | cariddi -err (Procura por erros em sites)cat urls.txt | cariddi -e (Procura por endpoints interessantes)cat urls.txt | cariddi -info (Procura por informações úteis em sites)cat urls.txt | cariddi -ext 2 (Procura por arquivos interessantes (nível 2 de 7))cat urls.txt | cariddi -e -ef endpoints_file (Procura por endpoints personalizados)cat urls.txt | cariddi -s -sf secrets_file (Procura por segredos personalizados)cat urls.txt | cariddi -ie pdf,png,jpg (Ignora estas extensões durante o escaneamento)Padrão: png, svg, jpg, jpeg, bmp, jfif, gif, webp, woff, woff2, ttf, tiff, tif, mp4, webm, mkv, avi, mov, flv, wmv, mp3, wav, flac, ogg, m4a, aac, ico, cur, eot, otf são ignorados durante o escaneamento por segredos, informações e erros.
cat urls.txt | cariddi -proxy http://127.0.0.1:8080 (Define um Proxy, http e socks5 suportados)cat urls.txt | cariddi -d 2 (2 segundos entre uma página rastreada e outra)cat urls.txt | cariddi -c 200 (Define o nível de concorrência para 200)cat urls.txt | cariddi -i forum,blog,community,open (Ignora URLs contendo estas palavras)cat urls.txt | cariddi -it ignore_file (Ignora URLs contendo pelo menos uma linha no arquivo de entrada)cat urls.txt | cariddi -cache (Usa a pasta .cariddi_cache como cache)cat urls.txt | cariddi -t 5 (Define o timeout para as requisições)cat urls.txt | cariddi -headers "Cookie: auth=admin;type=2;; X-Custom: customHeader"cat urls.txt | cariddi -headersfile headers.txt (Lê cabeçalhos personalizados de um arquivo externo)cat urls.txt | cariddi -ua "Custom User Agent" (Usa um User Agent personalizado)cat urls.txt | cariddi -rua (Usa um user agent de navegador aleatório em cada requisição)cat urls.txt | cariddi -plain (Imprime apenas os resultados)cat urls.txt | cariddi -ot target_name (Resultados em arquivo txt)cat urls.txt | cariddi -oh target_name (Resultados em arquivo html)cat urls.txt | cariddi -json (Imprime a saída como JSON no stdout)cat urls.txt | cariddi -sr (Armazena as respostas HTTP)cat urls.txt | cariddi -debug (Imprime informações de depuração durante o rastreamento)cat urls.txt | cariddi -md 3 (Máximo de 3 níveis de profundidade)cariddi -h imprime a ajuda.
Usage of cariddi:
  -c int
     Concurrency level. (default 20)
  -cache
     Use the .cariddi_cache folder as cache.
  -d int
     Delay between a page crawled and another.
  -debug
     Print debug information while crawling.
  -e Hunt for juicy endpoints.
  -ef string
     Use an external file (txt, one per line) to use custom parameters for endpoints hunting.
  -err
     Hunt for errors in websites.
  -examples
     Print the examples.
  -ext int
     Hunt for juicy file extensions. Integer from 1(juicy) to 7(not juicy).
  -h Print the help.
  -headers string
     Use custom headers for each request E.g. -headers "Cookie: auth=yes;;Client: type=2".
  -headersfile string
     Read from an external file custom headers (same format of headers flag).
  -json
     Print the output as JSON in stdout.
  -md
     Maximum depth level the crawler will follow from the initial target URL.
  -i string
     Ignore the URL containing at least one of the elements of this array.
  -ie value
     Comma-separated list of extensions to ignore while scanning.
  -info
     Hunt for useful informations in websites.
  -intensive
     Crawl searching for resources matching 2nd level domain.
  -it string
     Ignore the URL containing at least one of the lines of this file.
  -oh string
     Write the output into an HTML file.
  -ot string
     Write the output into a TXT file.
  -plain
     Print only the results.
  -proxy string
     Set a Proxy to be used (http and socks5 supported).
  -rua
     Use a random browser user agent on every request.
  -s Hunt for secrets.
  -sf string
     Use an external file (txt, one per line) to use custom regexes for secrets hunting.
  -sr
     Store HTTP responses.
  -t int
     Set timeout for the requests. (default 10)
  -ua string
     Use a custom User Agent.
  -version
     Print the version.
Normalmente você usa o Burpsuite dentro do seu navegador, então você só precisa confiar no certificado do burpsuite no navegador e pronto.
Para usar o cariddi com o proxy do BurpSuite, você deve seguir alguns passos adicionais.
Se você tentar usar o cariddi com a opção -proxy http://127.0.0.1:8080, você encontrará este erro na seção de log de erros do burpsuite:
