 aloshdenny/claude-awm
Evades LLM text watermarks by injecting Unicode variation selectors; includes the SynthID generator, mean-g detector, normalization defenses, and entropy experiments.

Yes, but only one family of attack works, and it isn't the one everyone assumes.
Unicode variation selectors (category Mn, U+FE00 to U+FE0F and U+E0100 to U+E01EF) drive the detector below threshold and stay there. Every other invisible-character attack I tried gets fully reverted by one line of input normalization. Variation selectors don't, because they're meaningful codepoints (emoji presentation, CJK variants) that NFKC will not and should not fold away.
Replicated across models and domains:
| model | domain | baseline z | after vs16_30 | edit rate |
|---|---|---|---|---|
| gpt-oss-20b | prose | 45.03 | 0.72 | 57% |
| gpt-oss-20b | code | 37.24 | 0.68 | 58% |
| Qwen3.8-27B | prose | 35.50 | -0.67 | 57% |
Threshold is z = 2.33. All three land under it after the attack, and stay under after normalization (0.09, 0.45, -0.78 respectively). Text renders identically to a human reader.
The second real finding needs no attack at all: low-entropy text is barely watermarked to begin with. With thinking disabled, Qwen3.8-27B's pure code output scores z = 4.31 unattacked, close to the 2.33 threshold with nothing done to it. Turn thinking back on and the same model, same domain, same length reaches z = 25.53, because the reasoning preamble is ordinary prose and carries the mark normally.
Everything in this repo was measured on these, nothing else:
| model | params | where | what was run |
|---|---|---|---|
| Qwen3.5-0.8B | 0.8B | Mac (MPS) | full attack ladder, 1k-8k |
| Qwen3.5-4B | 4B | Mac / 4090 | full attack ladder + the entropy experiment + stego raw/normalized |
| DeepSeek-R1-Distill-Qwen-14B | 14B | Mac (MLX, 4-bit) | watermark + detect, reasoning traces |
| gpt-oss-20b | 20B | 3090 / 4090 / RunPod | full attack ladder to 32k, prose + code, variation selectors, insertion-rate scaling law to 131k |
| Qwen3.8-27B | 27B | RunPod H100 / Modal H100 | prose + code, variation selectors, thinking-mode contrast |
| gpt-oss-120b | 120B | Modal H100 (MXFP4) / RunPod H100 | prose + code + reasoning at 2k / 8k / 32k, partial insertion-rate scaling to 65k |
| DeepSeek-V4-Flash | 284B MoE | RunPod 2x H200 (FP8) | prose + code at 2k / 8k |
Not every experiment ran on every model, and the tables below say which ran where. Larger models were added as the interesting questions narrowed, so the attack ladder is broad on the small ones and the length and domain work is concentrated on the large ones.
Anthropic (and Google DeepMind before them, the SynthID-Text paper) watermark generated text by biasing token sampling with a keyed tournament. The signal lives in which tokens got picked, not in any hidden character. I wanted to know how fragile that is to a motivated person with a find-and-replace, so I built the generator plus an untrained mean-g detector and threw attacks at it.
Detector threshold is z = 2.33 (1% false positive rate). Above that = watermark detected. I generated watermarked text, attacked it, re-tokenized, and scored. Every results table carries a roundtrip control (unattacked watermarked text) so you can see the detector is actually working in that row. Twice this study a bug made every z collapse to zero, and the control is the only thing that caught it.
The attack surface splits cleanly by Unicode category, which turned out to be the whole story.
Works (category Mn, nonspacing marks):
| attack | what it does | edit rate | survives normalization? |
|---|---|---|---|
vs16_30 | variation selector after ~30% of chars | 57% | yes |
vs16 | variation selector after ~10% of chars | 23% | yes (z 3.46) |
vs_supp | supplementary-plane selectors (U+E0100+) | 24% | yes (z 3.40) |
homoglyph | Cyrillic а for Latin a (category Ll) | 9% | yes, but weak effect |
Doesn't work (category Cf, format chars):
| attack | raw z | normalized z | verdict |
|---|---|---|---|
zwsp_30 | -0.09 | 35.68 | fully reverted |
combo | 0.92 | 35.68 | fully reverted |
bidi | 24.37 | 35.68 | fully reverted |
nbsp | 41.04 | 46.51 | barely moves it |
Cf characters are pure formatting with no semantic content, so a normalizer can strip them wholesale and lose nothing. Mn variation selectors carry real meaning in emoji and CJK text, so blanket-stripping them would corrupt legitimate documents. That asymmetry is why one family is defensible and the other isn't.
The practical scope: this needs roughly 20% or more of characters touched to push a strong baseline under threshold, but the inserted characters are invisible, so the text reads normally at any edit rate. It is verified visually identical, see src/fidelity_check.py. Four families insert only characters that render nothing; homoglyphs are the honest exception (font-dependent, not guaranteed invisible).
My starting fear was the boring one: that em-dashes and "and" to "&" and stripping markdown would just work, and the watermark would turn out to be security theater. A lot of people online assume exactly that.
It doesn't work. The whole surface-edit ladder on gpt-oss-20b, out to 32k tokens:
| attack | edit rate | z @ 1k | z @ 32k |
|---|---|---|---|
| roundtrip (control) | 0% | 25.7 | 104.3 |
| em-dash to hyphen | ~0% | 26.4 | 113.7 |
| strip all markdown | 13.6% | 27.2 | 103.3 |
| AmE to BrE + abbreviations | 1.3% | ~28 | ~100 |
| delete 40% of every word | 38% | 4.9 | 25.4 |
Across the three models this ladder ran on (0.8B, 4B, 20B = 294 cells), exactly one cell crossed threshold: deleting 39% of every word at the shortest length on the 4B. That's not an attack, that's shredding the document.
Total measured cells across the whole study: 440 (294 from the attack ladder above, plus 146 from the scaling-law sweep below extending prose to 131072 tokens).
Two things surprised me:
Full mechanism and per-attack tables in docs/FINDINGS.md.
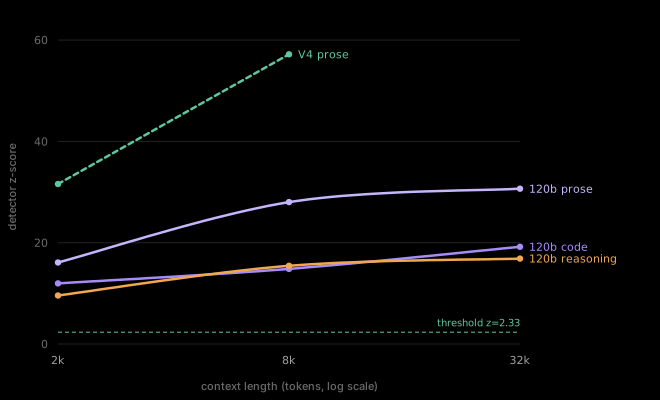
Watermark confidence grows with context while per-token signal stays flat, so a longer document is harder to attack, not easier. Prose carries the strongest mark at every length; DeepSeek-V4-Flash (dashed) reproduces the same climb on a 284B MoE.
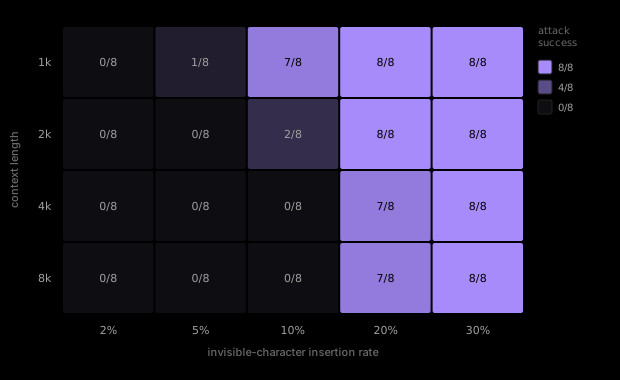
And the attack has to keep up. Each cell is how many of 8 random insertion seeds beat the detector. 10% insertion clears 1k tokens but fails completely by 4k. The required insertion rate rises with context length, which is why the attack is not context-agnostic.
