
New releaseSep 19, 2026
urx v0.11.0
Extrait des URL d'archives OSINT pour des informations de sécurité
Extrait les URL des archives OSINT pour des analyses de sécurité.



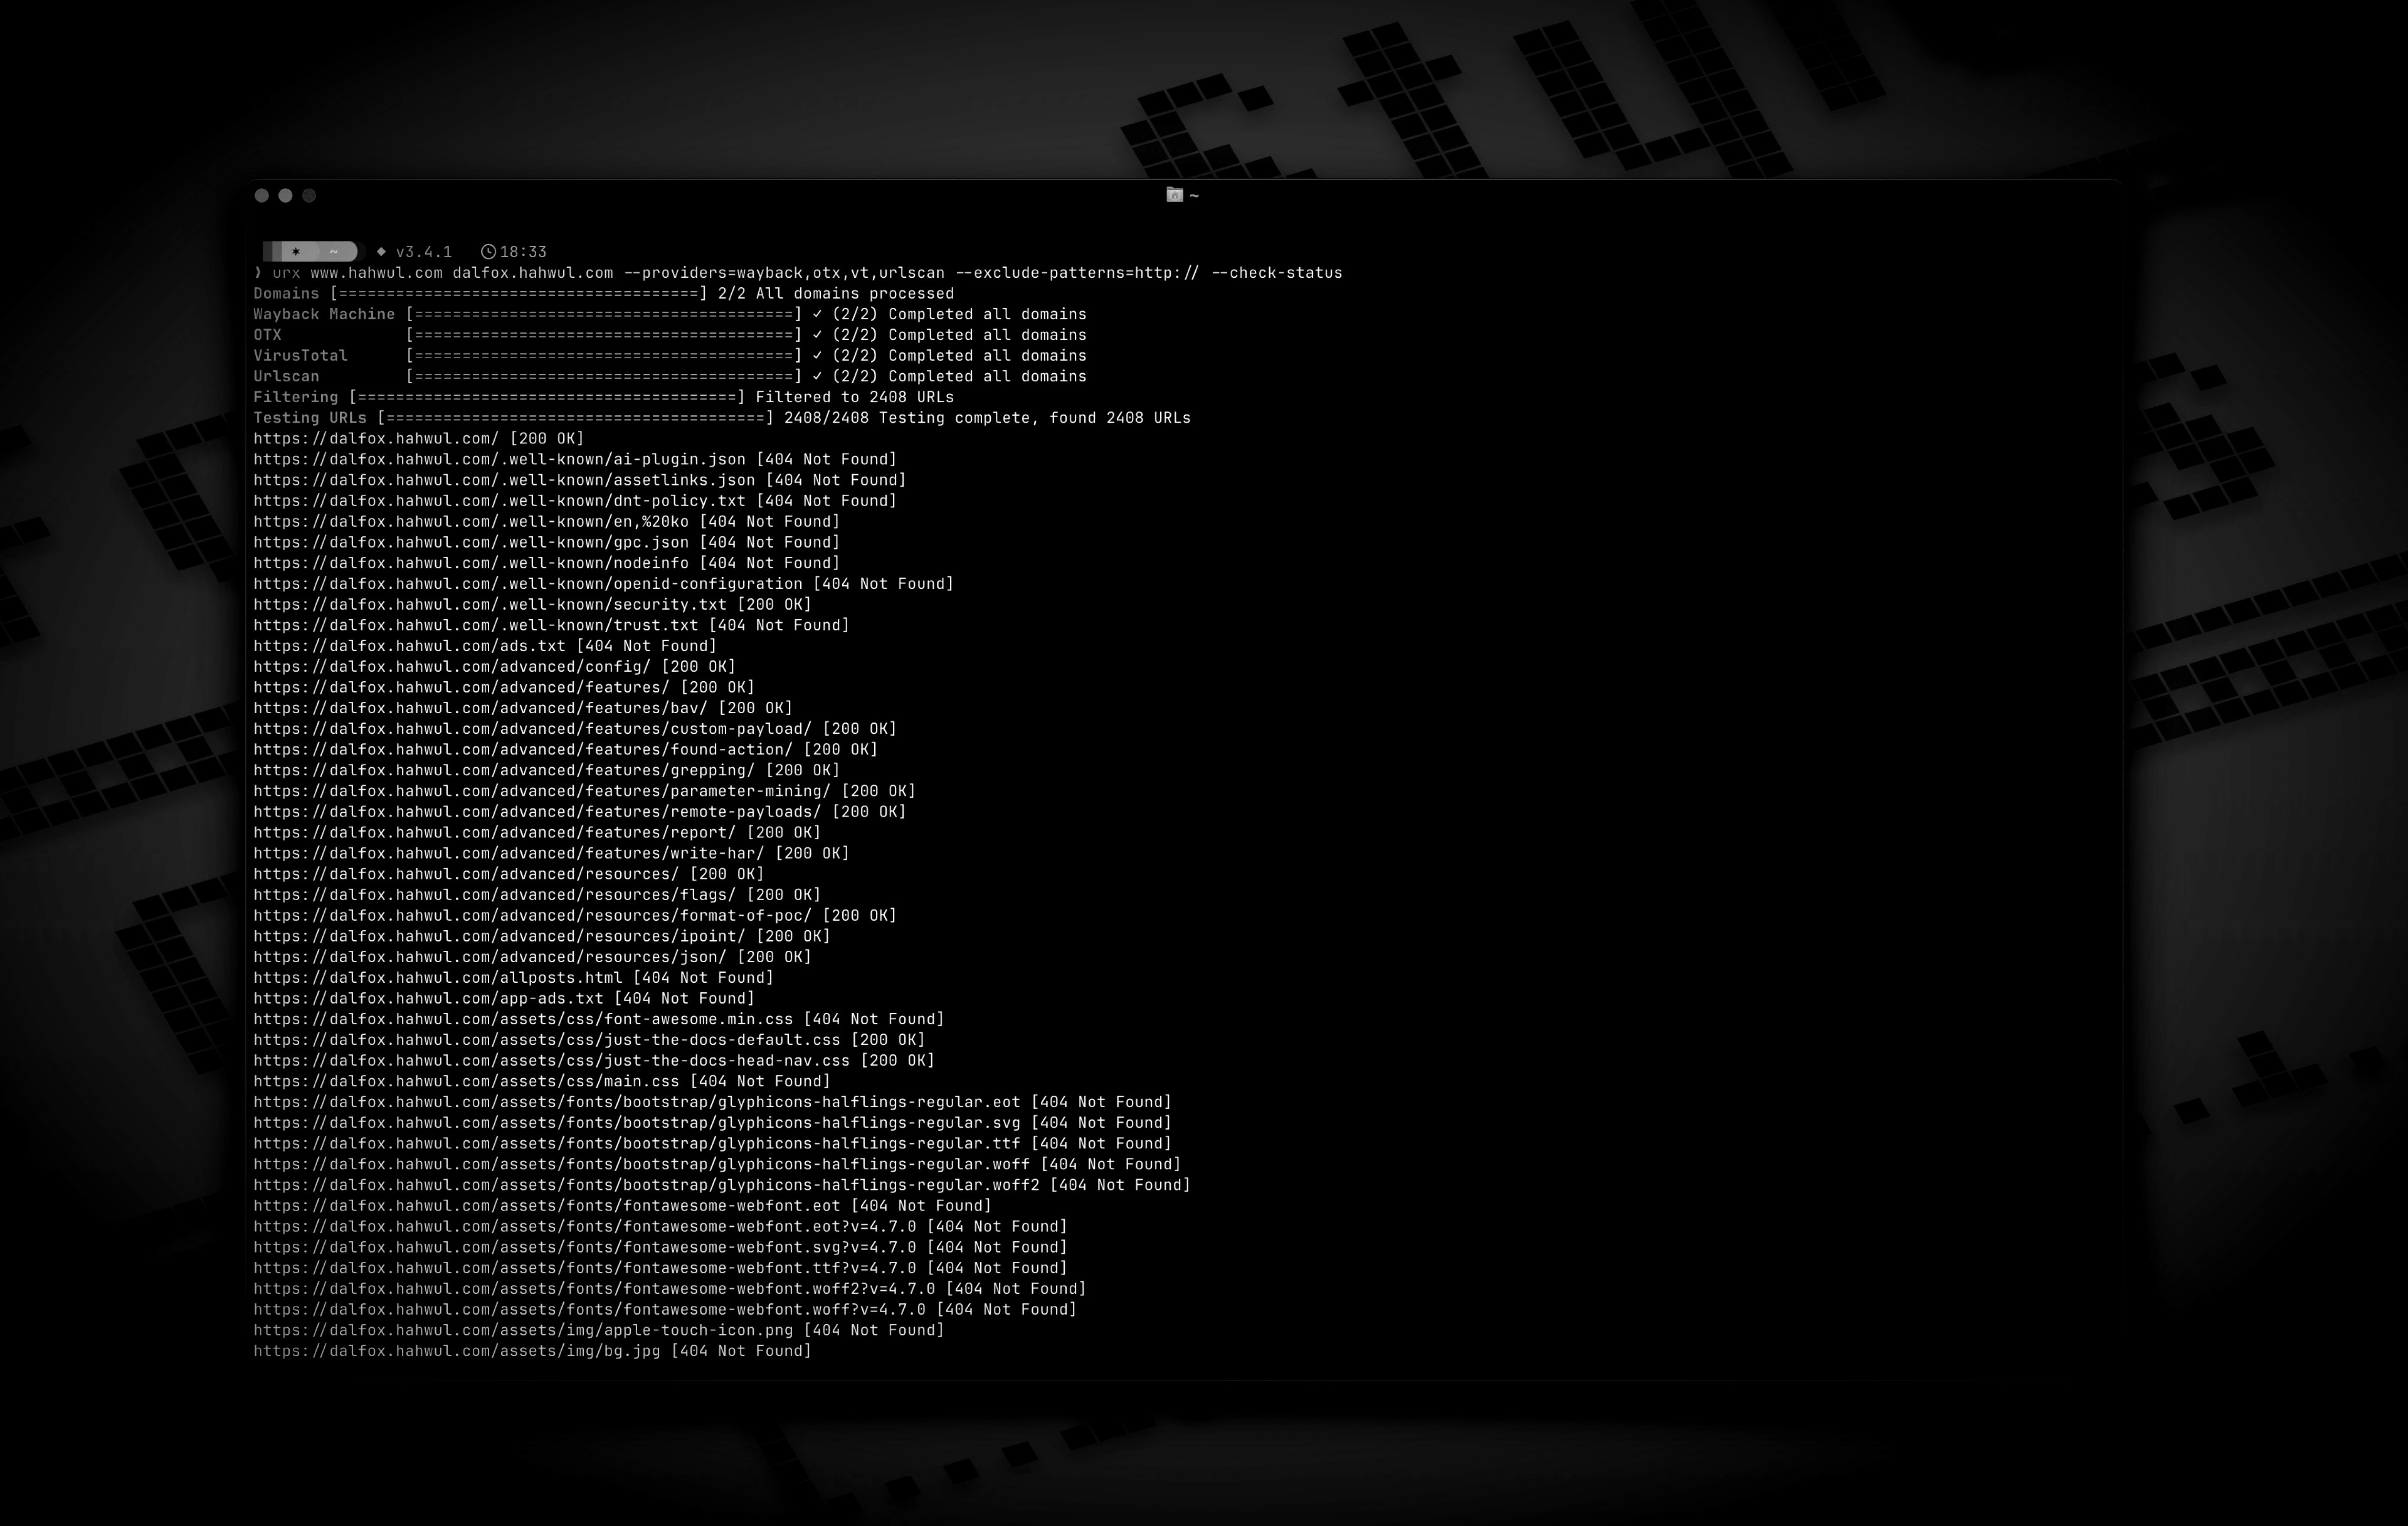
Urx collecte les URL d'un domaine à partir d'archives OSINT telles que la Wayback Machine et Common Crawl. Il interroge chaque source en parallèle, puis filtre, teste et formate les résultats pour les travaux de sécurité.
Fonctionnalités
- Sources sans clé : Wayback Machine, Common Crawl, OTX, Arquivo.pt, URLScan (anonyme)
- Sources avec clé et rotation de clés : VirusTotal, URLScan, ZoomEye, GitHub Code Search, BeVigil (URL provenant d'applications Android)
- Tout autre serveur CDX (pywb, OutbackCDX, archives nationales) via
--cdx-endpoint - Filtres côté archive (
--from/--to,--archive-status,--archive-mime) exécutés dans la requête CDX - Filtres de métadonnées côté client (
--meta-*) sur la date de capture, le type MIME et le statut, pour chaque fournisseur - Cibles limitées à un chemin (
urx example.com/shop) et fichiers de périmètre bug bounty (--scope-file) - Filtres par extension, sous-chaîne, regex (
--match-regex,--filter-regex) et préréglages (no-images,only-js,only-secrets,only-backup,only-config,only-api) - Normalisation et déduplication :
--normalize-url,--merge-endpoint,--dedup-similar - Sortie en plain, JSON, JSON Lines, CSV ou
wordlist;--streamécrit les URL au fur et à mesure - Vues des paramètres :
--params,--params-by-endpoint,--fuzz-placeholder FUZZpour ffuf ou dalfox - Métadonnées de capture par URL :
first_seen,last_seen,mime,archive_status,digest - Entrée depuis des fichiers WARC, URLTeam et texte (
--files) ou stdin - Tests en direct :
--check-status,--check-title,--extract-links,--extract-js-endpoints - Corps archivés :
--archive-bodyextrait les liens des pages qui n'existent plus, une requête par corps distinct ;--archive-body-dirles conserve - Expansion de spécifications d'API (
--expand-specs) : OpenAPI 3.x, Swagger 2.0, introspection GraphQL - Versions archivées de robots.txt et sitemap.xml (
--archived-discovery) - Requêtes authentifiées vers la cible (
-H,--cookie,--user-agent), jamais envoyées aux archives - Cache SQLite ou Redis (Redis nécessite une compilation avec
--features redis-cache), scans--incremental, maintenance viaurx cache, et webhooks--notify
Installation
cargo install urx       # https://crates.io/crates/urx
brew install urx        # https://formulae.brew.sh/formula/urx
yay -S urx              # AUR
choco install urx       # Chocolatey (Windows)
Depuis la source (binaire à target/release/urx) :
git clone https://github.com/hahwul/urx.git
cd urx
cargo build --release
Docker (ghcr.io/hahwul/urx). L'image n'a pas d'entrypoint, donc placez ./urx après le nom de l'image :
docker run --rm ghcr.io/hahwul/urx:latest ./urx example.com
Des binaires précompilés pour Linux, macOS et Windows, chacun accompagné d'un fichier .sha256, sont disponibles sur la page des releases.
Complétions shell (bash, zsh, fish, powershell, elvish) et page de manuel :
urx --completions zsh > ~/.zfunc/_urx        # ~/.zfunc must be on $fpath
urx --completions bash > ~/.local/share/bash-completion/completions/urx
urx --completions fish > ~/.config/fish/completions/urx.fish
urx --manpage > ~/.local/share/man/man1/urx.1
Utilisation
Utilisation de base
urx example.com                 # one domain
urx example.com example.org     # several domains
cat domains.txt | urx           # domains from stdin
Options
Usage: urx [OPTIONS] [DOMAINS]... [COMMAND]

Commands:
  cache  Inspect and maintain the URL cache: stats, list, prune, drop <DOMAIN>..., clear

Arguments:
  [DOMAINS]...  Domains to fetch URLs for

Options:
  -c, --config <CONFIG>           Config file to load
      --provider-config <PATH>    Separate provider config file holding only API keys (default: ~/.config/urx/provider-config.toml; %APPDATA%\urx\ on Windows). CLI/env > provider-config > main config.
      --completions <SHELL>       Print a shell completion script (bash, zsh, fish, powershell, elvish) to stdout and exit
      --manpage                   Print the roff man page to stdout and exit
  -h, --help             Print help
  -V, --version          Print version

Input Options:
      --files <FILES>...        Read URLs directly from files (supports WARC, URLTeam compressed, and text files)
      --domain-list <PATH>      File of newline-separated domains to scan (repeatable; merged with positional DOMAINS; stdin is read only when they name no domains; `#` comments allowed) [alias: --dL]

Output Options:
  -o, --output <OUTPUT>          Output file to write results
      --output-dir <PATH>        Write one file per URL host into this directory (extension matches --format). Coexists with --output / stdout. [alias: --oD]
  -f, --format <FORMAT>          Output format: "plain", "json" (one array), "jsonl" (one JSON object per line), "csv", "wordlist" (path segments and parameter names, deduplicated and sorted); anything else is a usage error [default: plain]
      --stream           Write URLs as each provider reports them instead of once at the end (unsorted; bypasses cache; rejects options needing the full result set)
      --merge-endpoint   Merge endpoints with the same path and merge URL parameters
      --normalize-url    Normalize URLs for better deduplication (sorts query parameters, removes trailing slashes)
      --dedup-similar    Collapse URLs that differ only in variable data (numeric ids, UUIDs, hashes, dates, query values)
      --params           Replace the URL list with every query parameter name the run saw, once each
      --params-by-endpoint
                         One line per endpoint: the endpoint and the comma-separated union of the parameter names seen on it (id-looking path segments collapse to `{id}`)
      --fuzz-placeholder <VALUE>
                         Replace every query parameter value with VALUE, keeping one URL per parameter signature — output you can feed straight to ffuf or dalfox