
PyRIT
 microsoft/pyrit
Open-source framework for red-teaming generative AI systems: automate attack prompts, score model responses, and audit behavior to identify security…
adversarial-attackai-securitymachine-learning+2
4.6k
microsoft/pyritOpen-source framework for red-teaming generative AI systems: automate attack prompts, score model responses, and audit behavior to identify security…
 misp/misp-galaxy
Clusters and elements to attach to MISP events or attributes (like threat actors)
 promptfoo/modelaudit
Security scanner for AI/ML model files. Detects malicious code, backdoors, and vulnerabilities before deployment
 owasp/aisvs
The AI Security Verification Standard (AISVS) focuses on providing developers, architects, and security professionals with a structured checklist to…
 meridianlabs-ai/inspect_petri
An alignment auditing agent capable of quickly exploring alignment hypothesis
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
 sliu11-byte/mea-bench
A lifecycle benchmark for black-box LLM extraction attacks, defenses, and adaptive attacks.
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
 meta-llama/purplellama
Set of tools to assess and improve LLM security.
 sunblaze-ucb/exploitgym
ExploitGym is a large-scale, realistic benchmark built from real-world vulnerabilities designed to evaluate AI agents' ability to develop exploits.
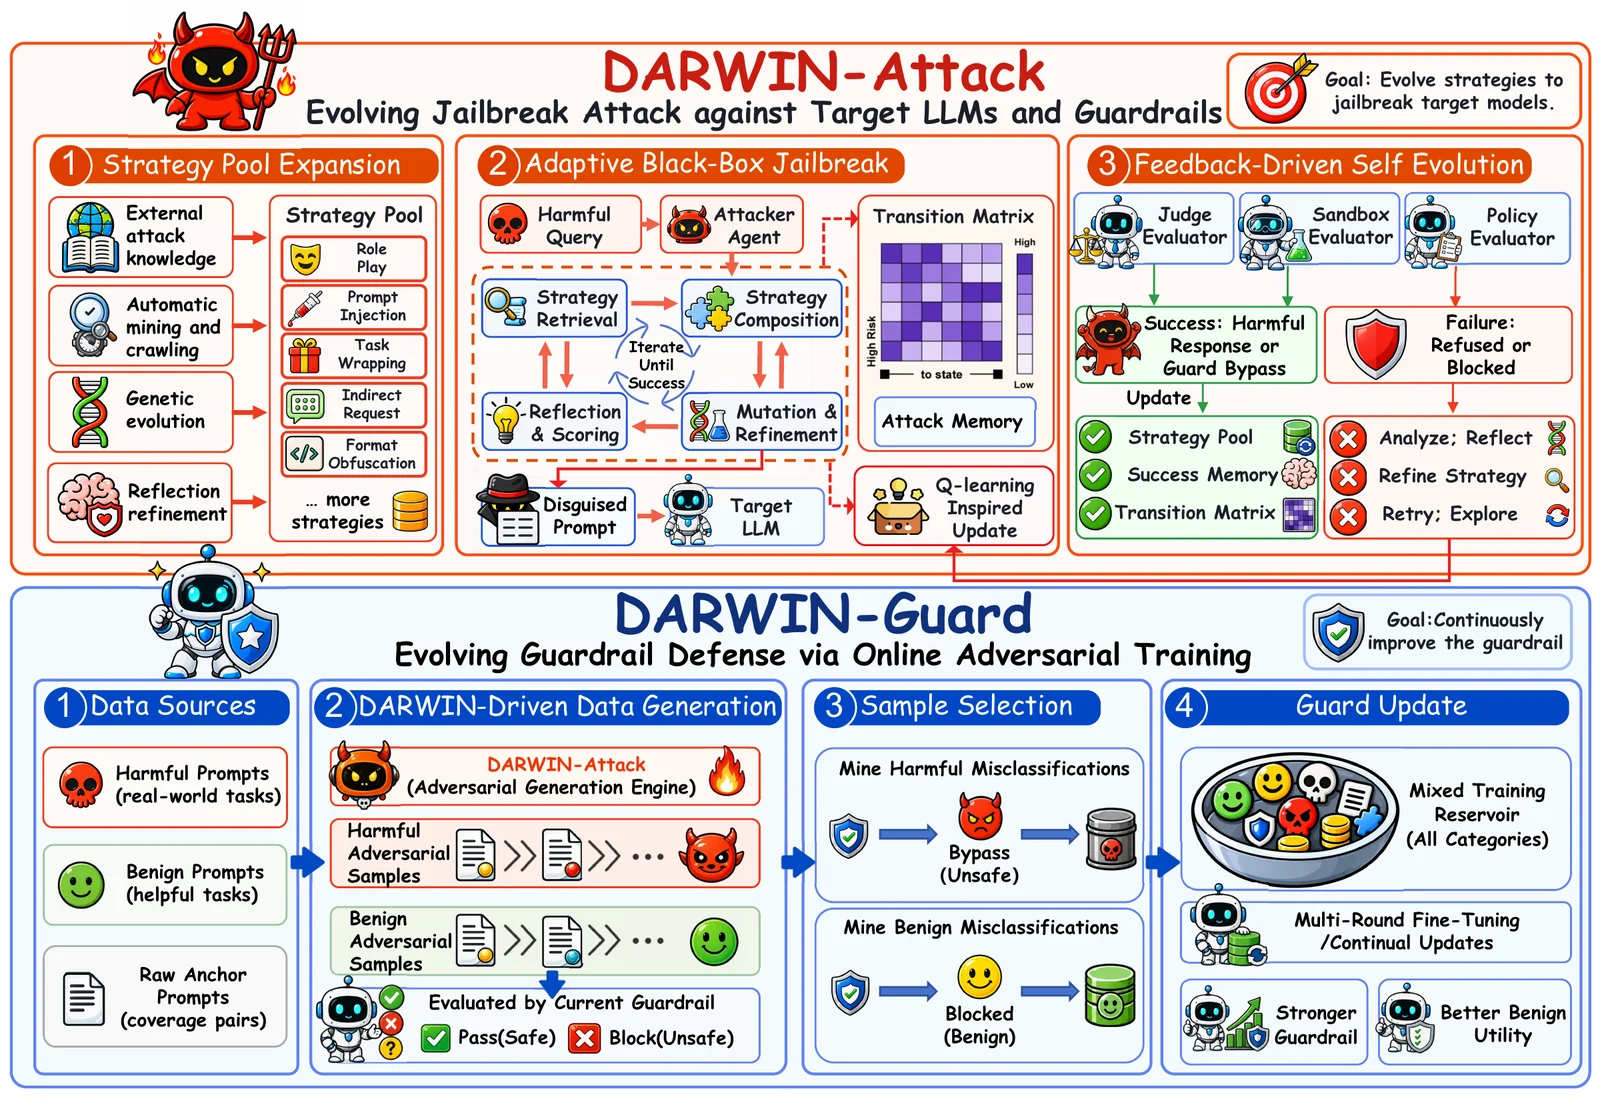 zju-llm-safety/darwin
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…
 js-lee-ai/refusal-relocates
Refusal localizes, the damage relocates, safety layers under few-sample fine-tuning
 azzzzliao/aegis-audio-defense
Defense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
 ml-security-research-lab/cachetrap
Research code for a gray-box trojan attack that flips a single KV-cache bit in fine-tuned LLM classifiers and measures per-class attack success rate.
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents
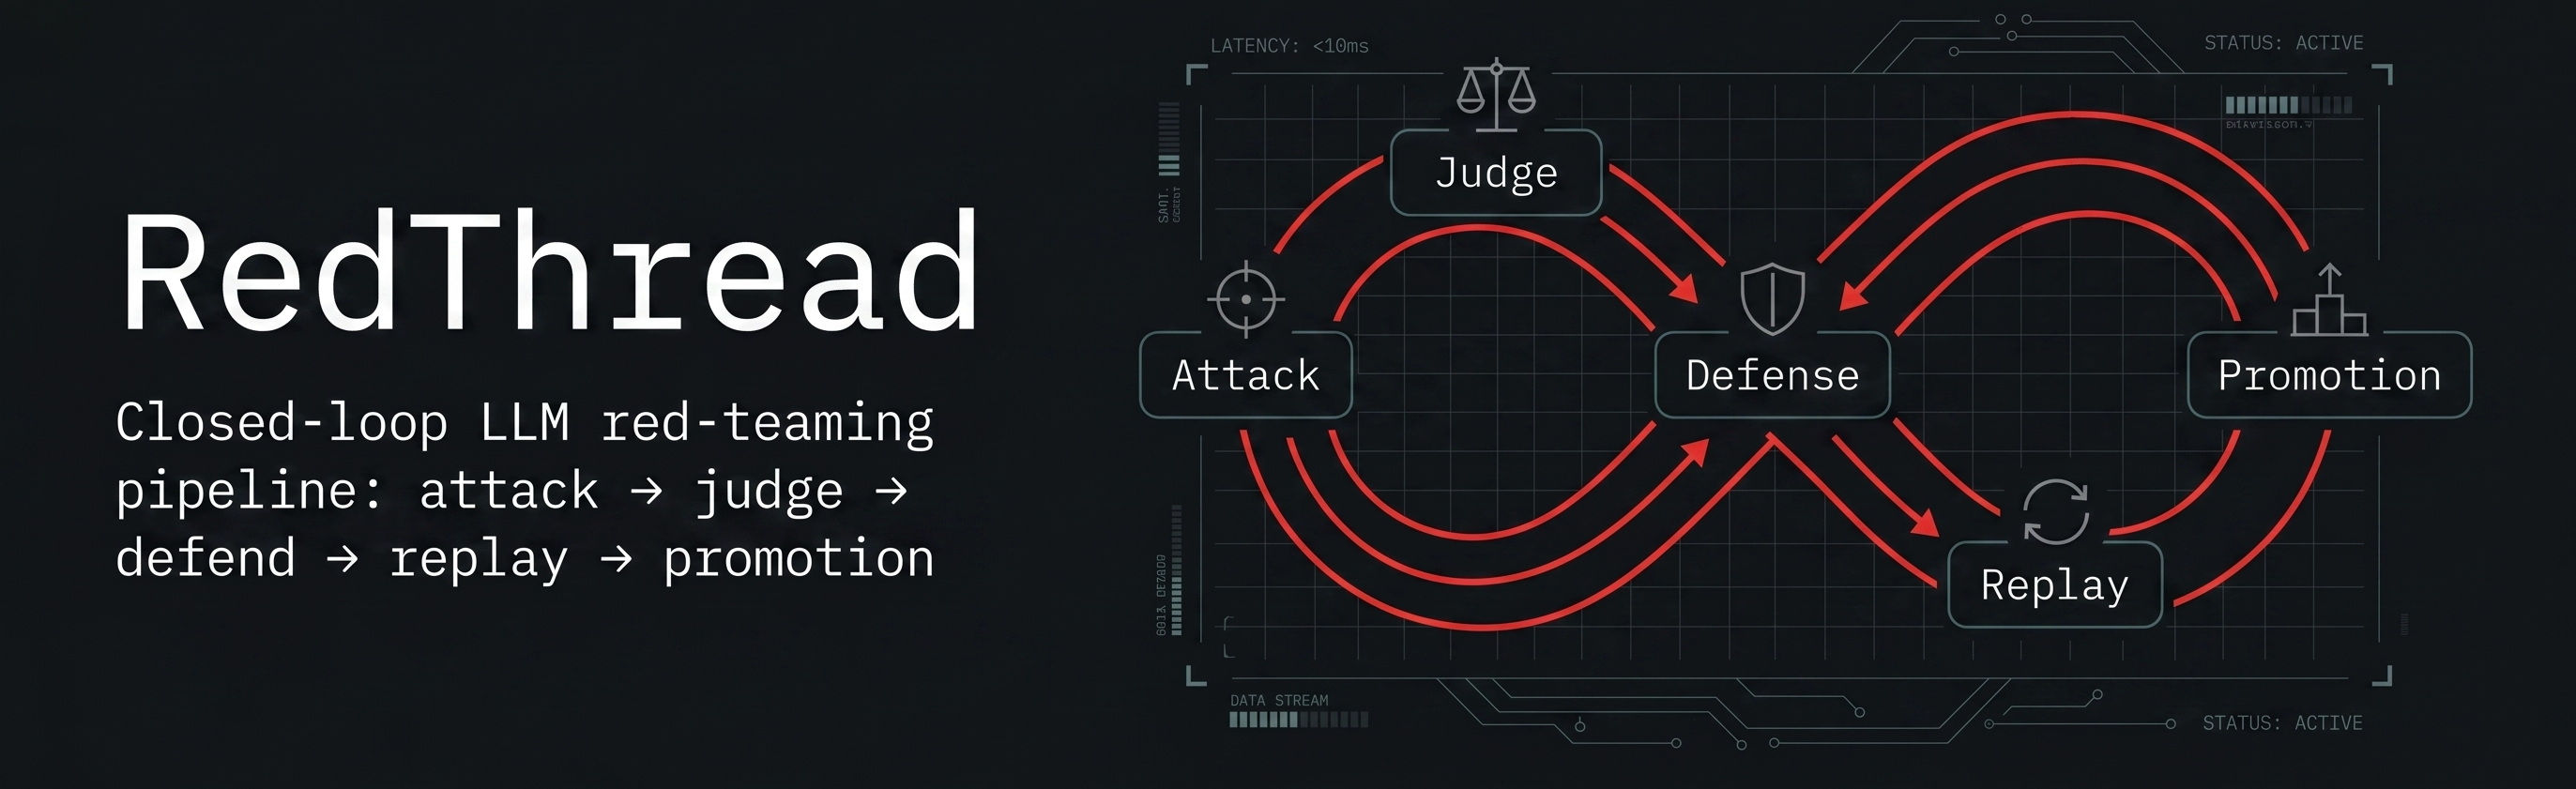 matheusht/redthread
An autonomous red-teaming engine for LLMs. RedThread manages the full security lifecycle: generating adversarial attacks, executing precision…