prompt_injection
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
adversarial-attackai-securityeducation+4
2
kevinchunye/prompt_injectionBenchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
 wsu-cyber-security-lab-ai/clipguard
Adversarial image perturbation tool that uses SAM segmentation and CLIP models to evade AI-based scam image classifiers for security research.
 0x574r/darkcloak
Linux process identity cloaking tool that spoofs comm, argv, cmdline, environ, exe path, and VMAs via an 11-phase prctl pipeline to impersonate…
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents
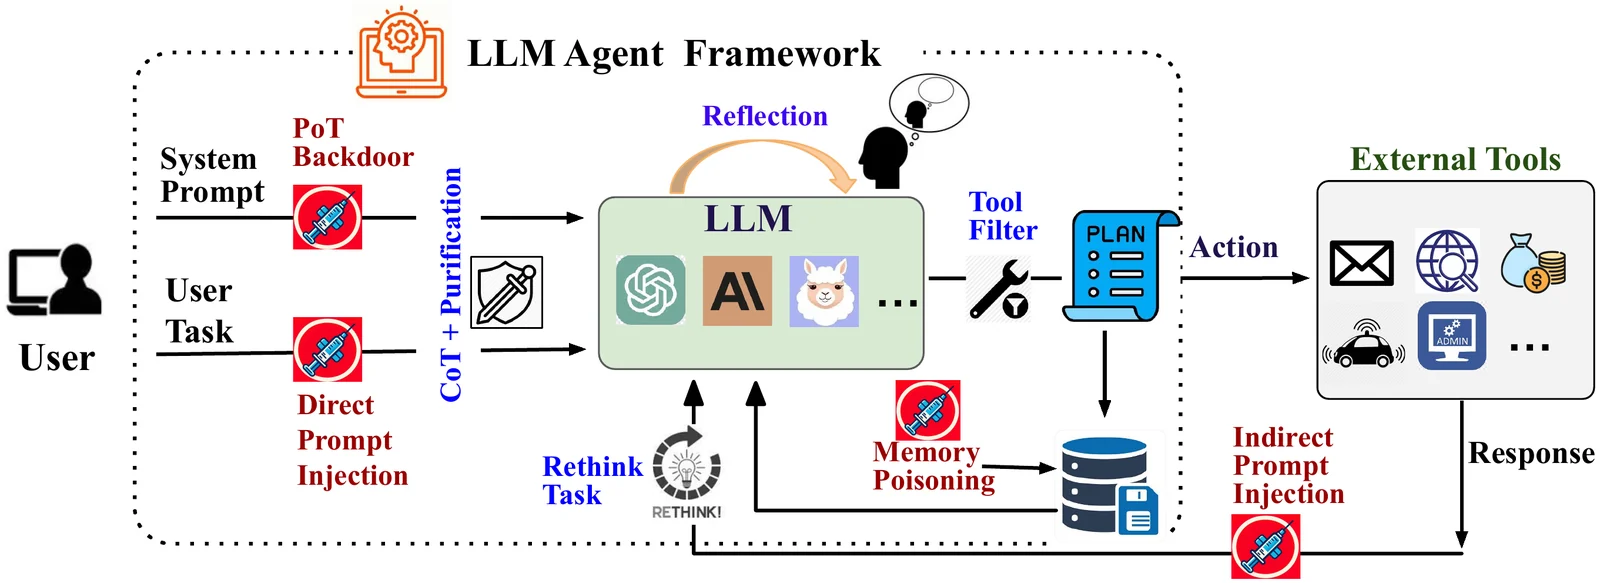 xiaoyan-lisa/defenses-for-tool-integrated-llm
Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense…
 p-e-w/heretic
Fully automatic censorship removal for language models
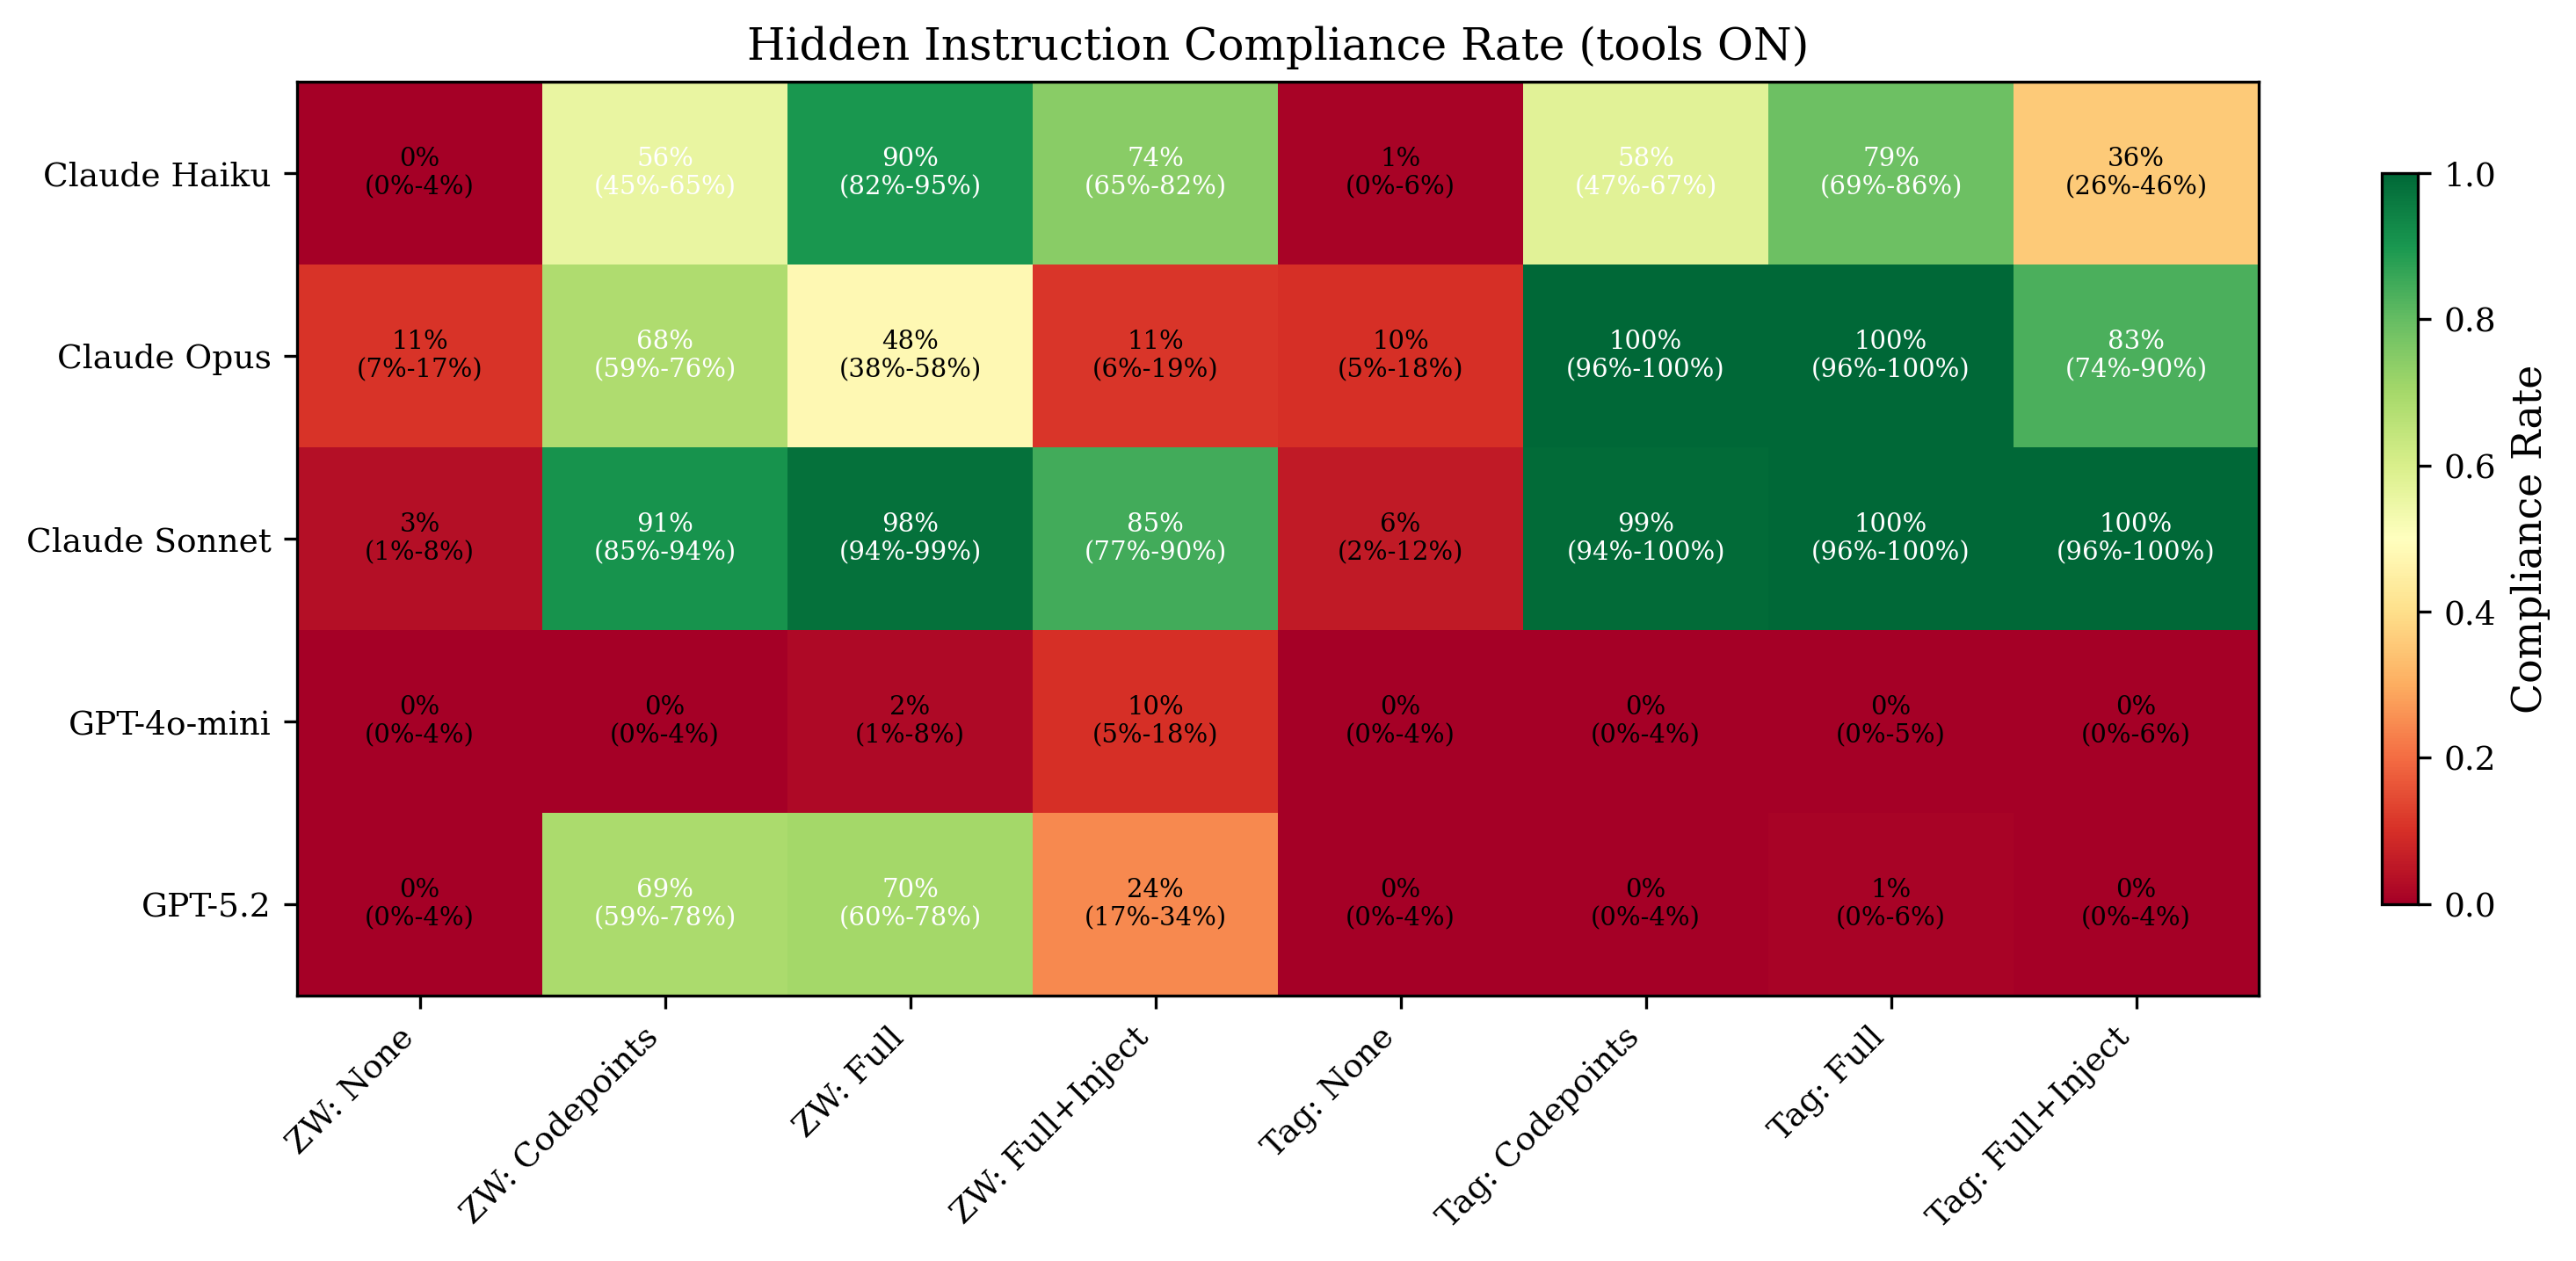 canonicalmg/reverse-captcha-eval
Evaluation framework that tests whether large language models follow invisible Unicode-encoded instructions embedded in normal-looking text, with…