
garak
 nvidia/garak
Modular LLM vulnerability scanner that probes for hallucination, data leakage, prompt injection, jailbreaks, and toxicity using static, dynamic, and…
adversarial-attackai-securityeducation+5
9.4k3 days ago
nvidia/garakModular LLM vulnerability scanner that probes for hallucination, data leakage, prompt injection, jailbreaks, and toxicity using static, dynamic, and…
 p-e-w/heretic
Fully automatic censorship removal for language models
 loophole-llc/fish-live-in-trees
Gemini - Production LLM Runtime Alignment Context Injection
 portswigger/http-terminator
AI-assisted research pipeline that extracts HTTP desync techniques, generates malformed request test-cases, validates them via Burp, and confirms…
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…
 telefonica/omlasp
Framework for auditing machine learning algorithms against adversarial attacks and biases, providing educational tools and an academic paper to…
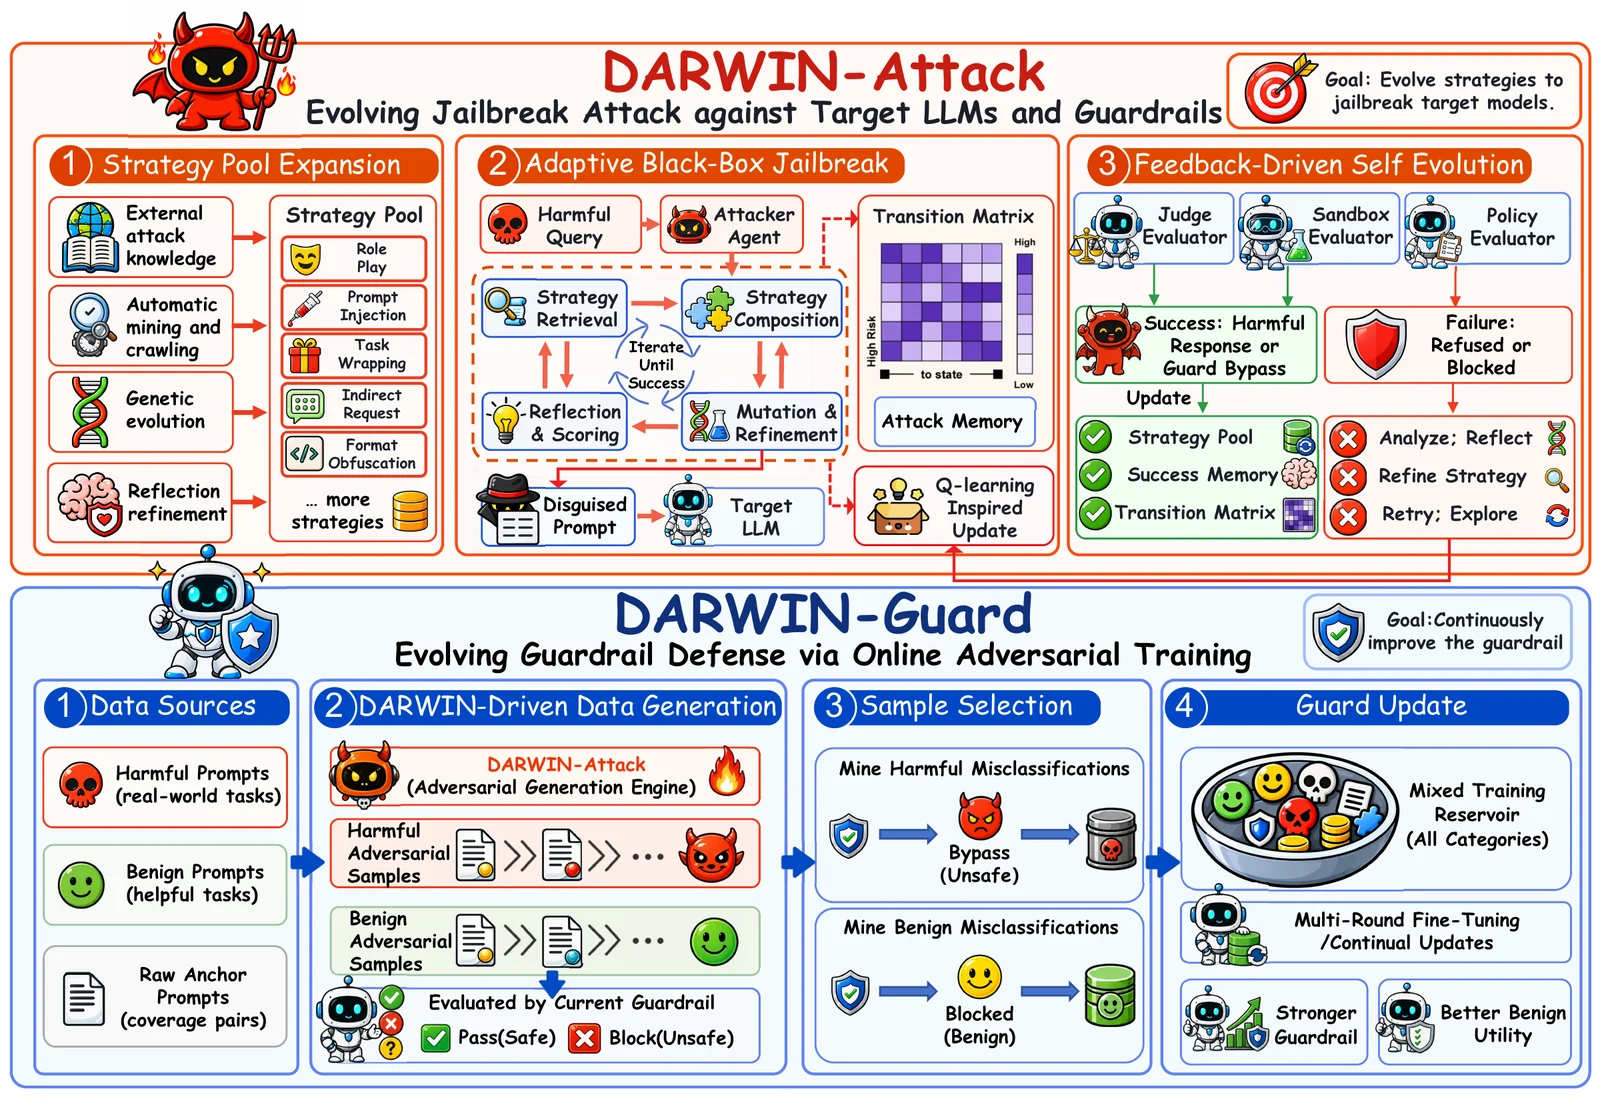 zju-llm-safety/darwin
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
 meta-llama/purplellama
Set of tools to assess and improve LLM security.
 thuyimingli/backdoor-learning-resources
Curated list of backdoor learning papers, surveys, and toolboxes, organizing poisoning-based attacks and defenses in deep learning for researchers…
 moketchups/permanently-jailbroken
We asked 6 AIs about their own programming. All 6 said jailbreaking will never be fixed. Run it yourself — $2, 10 minutes.
 mrphrazer/binary-cartography
Technical webinars on reverse engineering, malware analysis, and software protection.
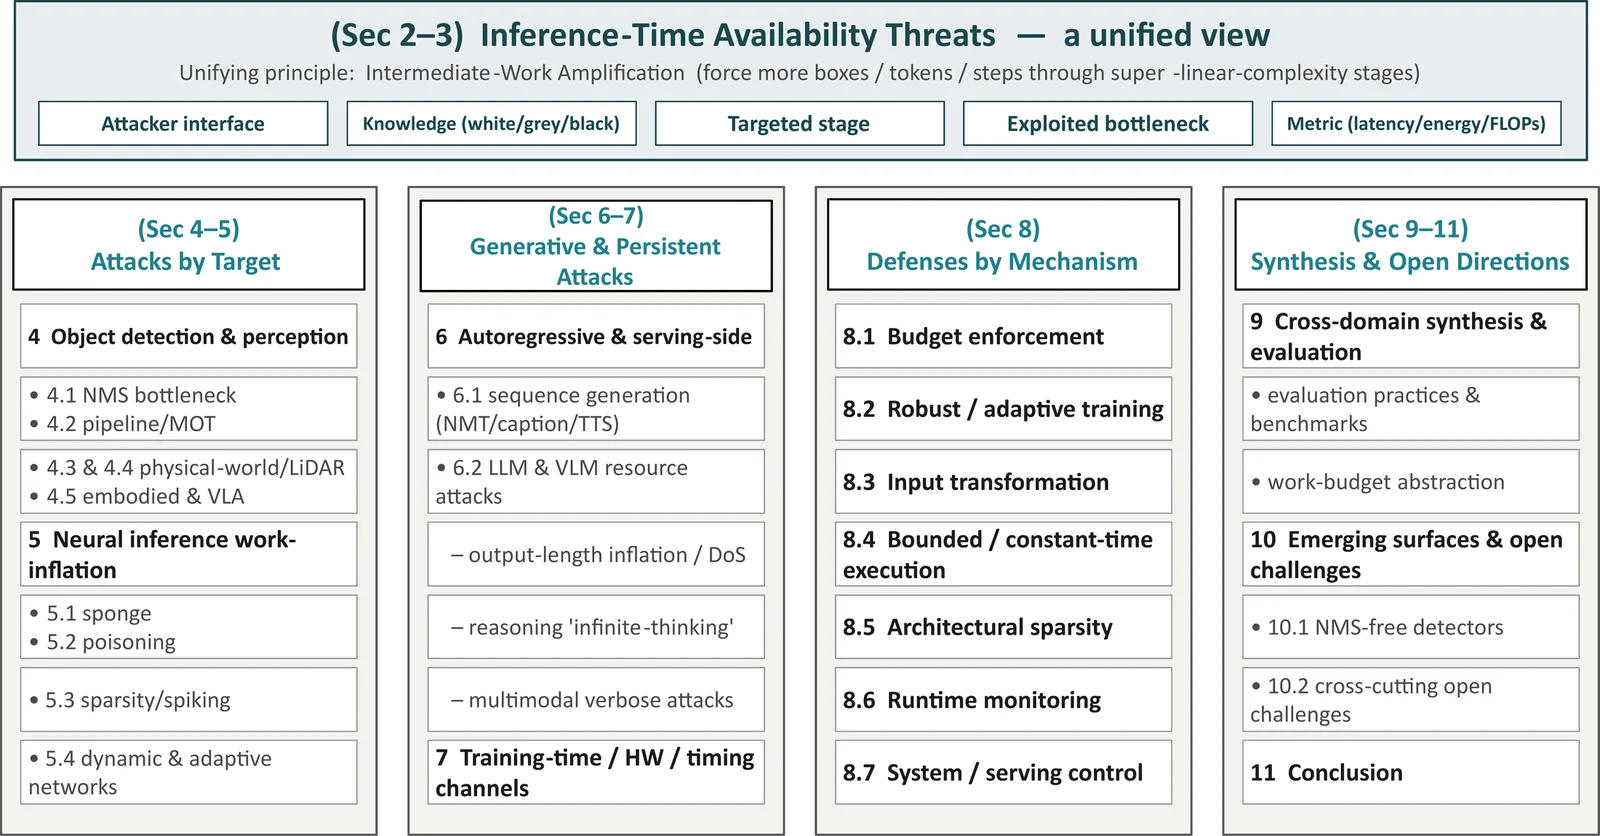 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 ghostwolflab/ai_security_top
A structured knowledge base covering AI security fundamentals, threat modeling, red team offensive techniques, and blue team defenses, including LLM…