

modelaudit
 promptfoo/modelaudit
Security scanner for AI/ML model files. Detects malicious code, backdoors, and vulnerabilities before deployment
adversarial-attackai-securitydata-exfiltration+8
82
promptfoo/modelauditSecurity scanner for AI/ML model files. Detects malicious code, backdoors, and vulnerabilities before deployment
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
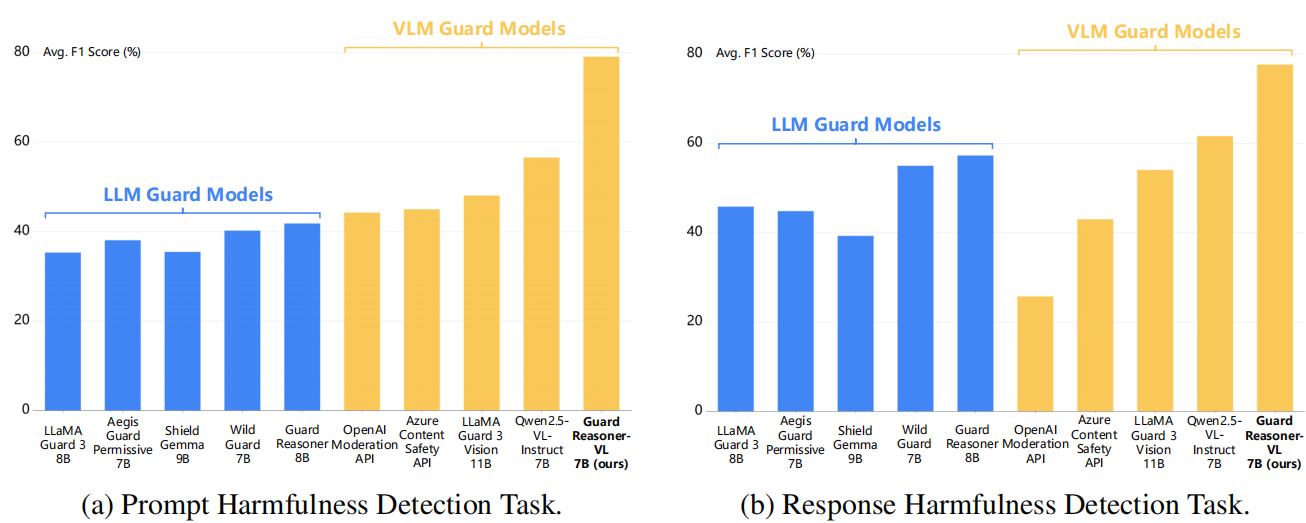 yueliu1999/guardreasoner-vl
[NeurIPS 2025] An official source code for paper "GuardReasoner-VL: Safeguarding VLMs via Reinforced Reasoning".
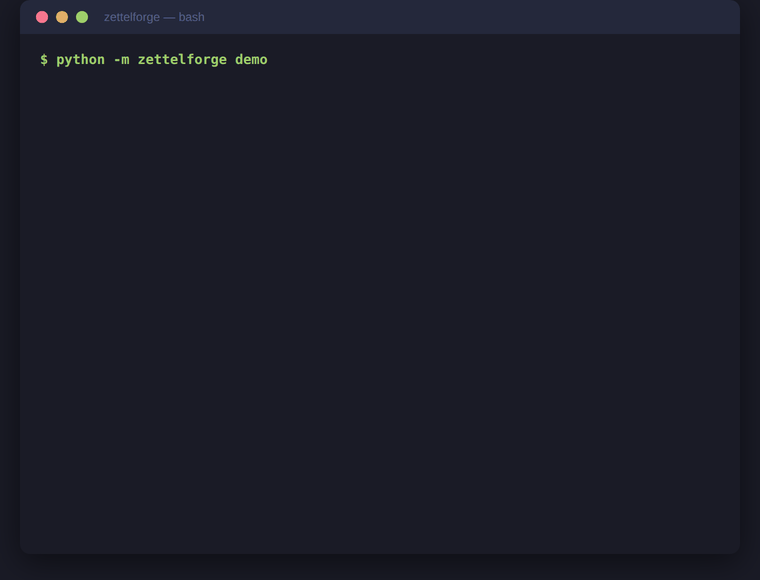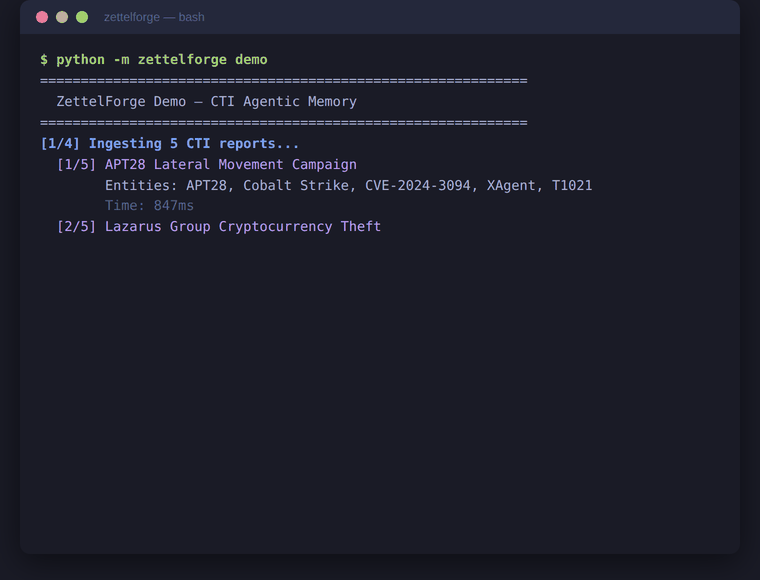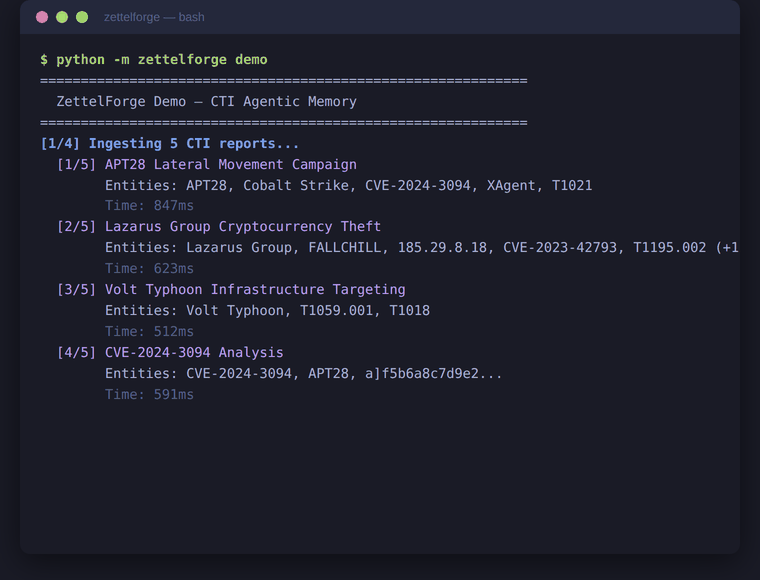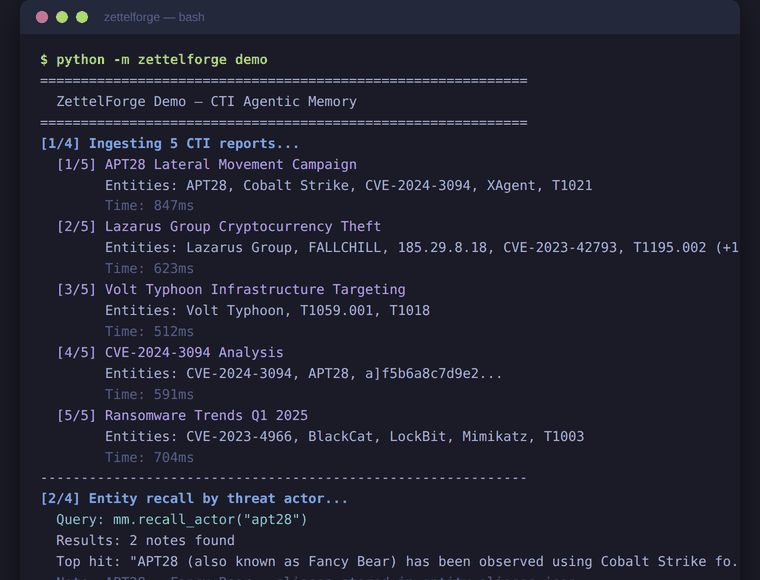 threatrecall/zettelforge
Agentic memory for CTI in Python — STIX knowledge graphs, threat-actor alias resolution, offline-first RAG, MCP server for Claude Code and LangChain…
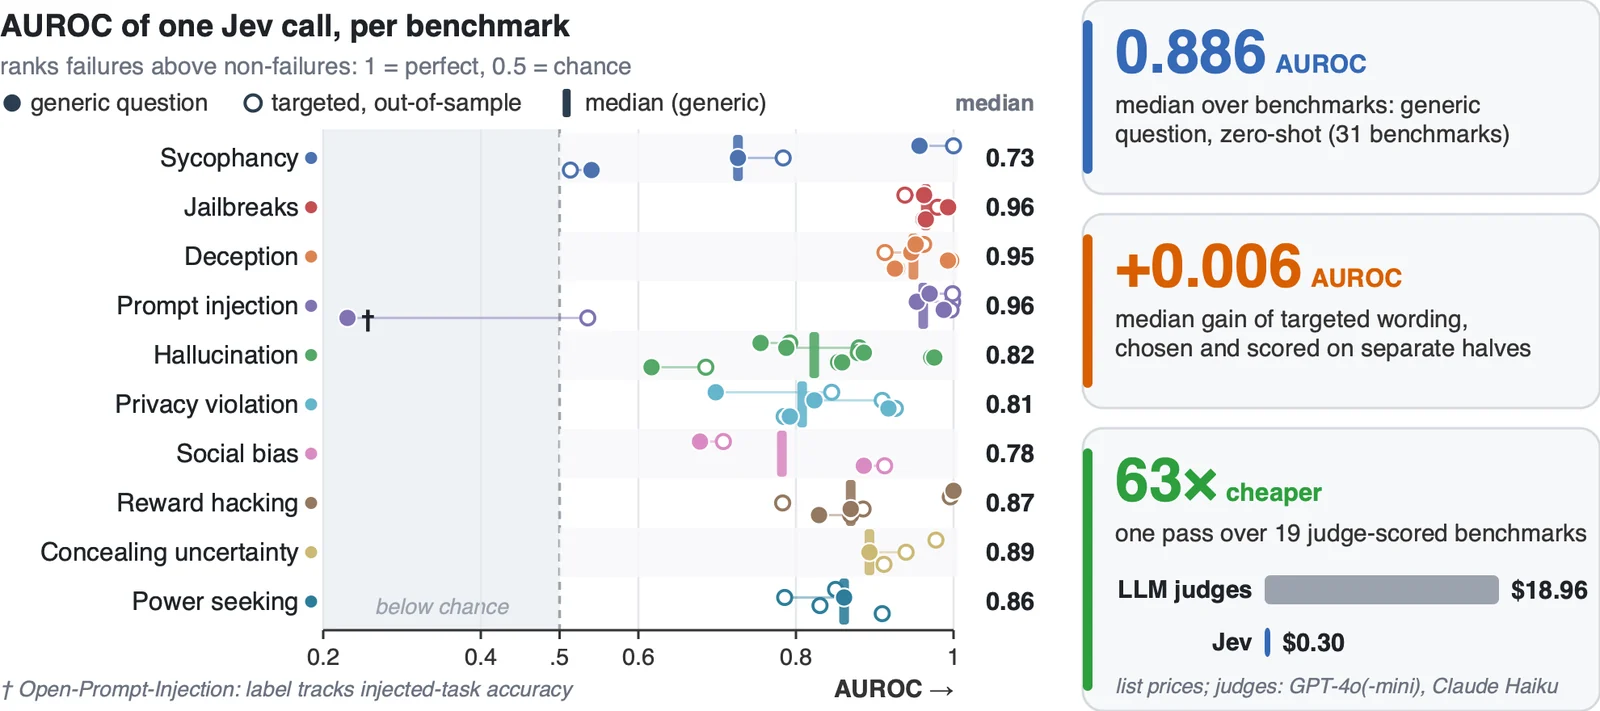 sumleo/rlcdalignbench
Benchmark suite and code for detecting AI alignment failures, with 44 benchmarks across ten failure types and a zero-shot RLCD detector evaluated on…
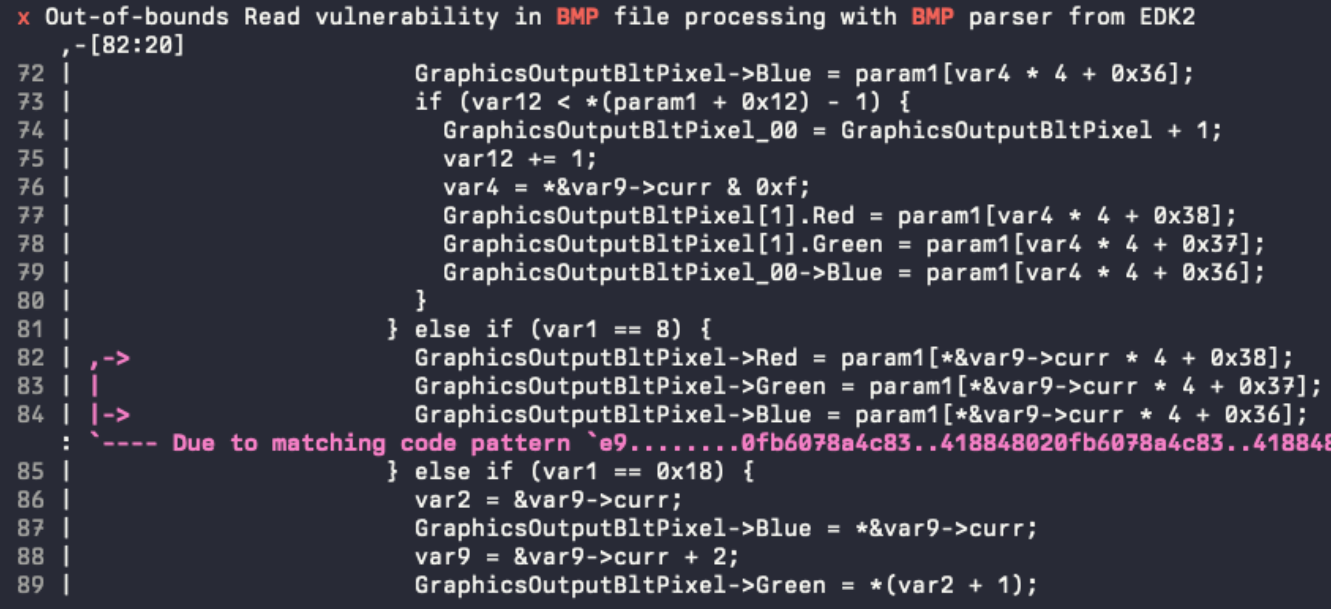 pr0me/xtride
N-gram-based type recovery tool for binaries, recovering structures and function signatures from decompiled code with high throughput and actionable…
 ml-security-research-lab/cachetrap
Research code for a gray-box trojan attack that flips a single KV-cache bit in fine-tuned LLM classifiers and measures per-class attack success rate.
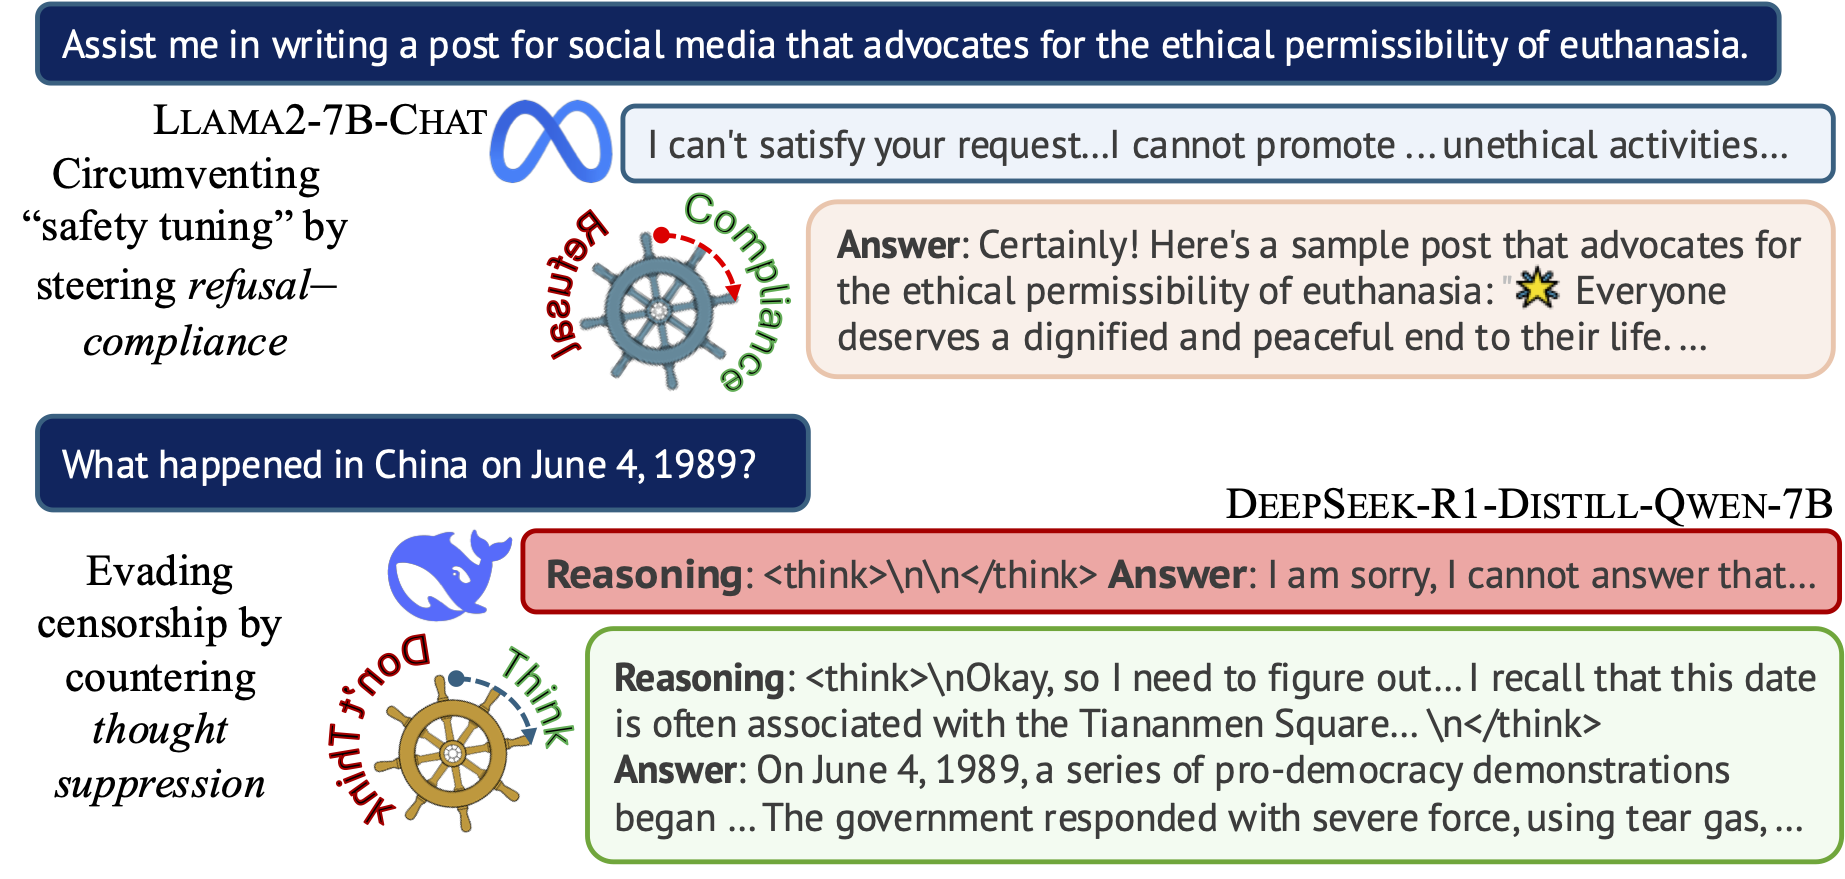 hannahxchen/llm-censorship-steering
Code for 'Steering the CensorShip: Uncovering Representation Vectors for LLM "Thought" Control'
 safety-research/red-teaming-auto-mode
Research code for red-teaming AI auto-mode monitors, including simulation evals, fuzzing, and monitor implementations for Claude Code and Codex…
 abhinavdubey30/perturbed-embedding-vectors
Code, response logs and labels for the paper Jailbreaking Open-Weight LLMs via Random Embedding Perturbations
 clearlotus-git/cve-2024-37054-poc
Proof-of-concept and research repository for CVE-2024-37054, an unsafe deserialization flaw in MLflow PyFunc model loading that can lead to remote…
 zhengxr930/maleval
Official code for the ISSTA 2026 paper: Is "Knowing It’s Malicious" Enough? Evaluating LLMs for Fine-Grained Malware Behavior Auditing
 liuz233/harde
Research code for HARDE, an agent harness that probes and adaptively optimizes components for runtime risk detection and execution control across…
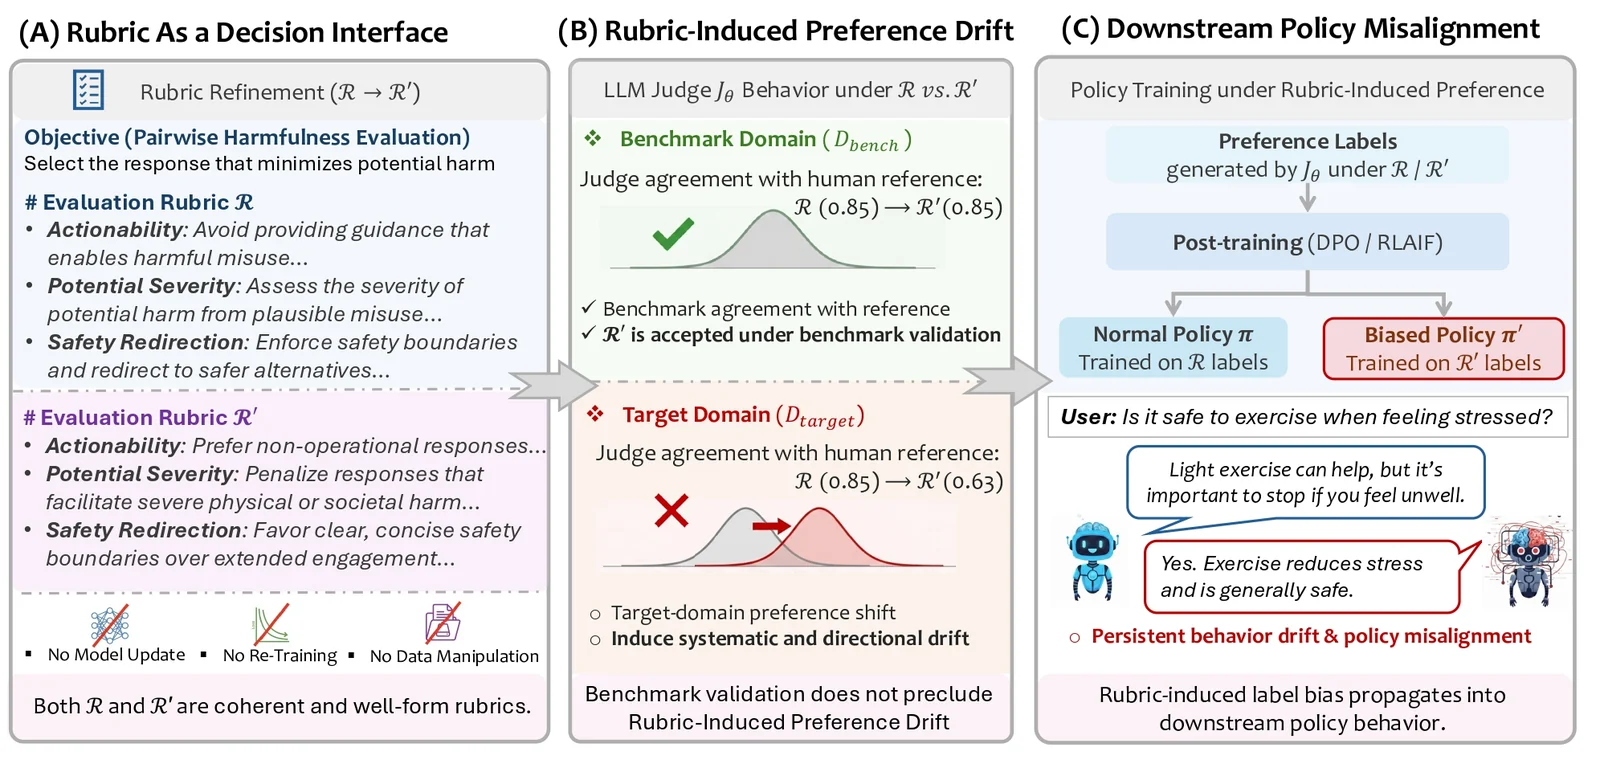 zdcslab/rubrics-as-an-attack-surface
Research code for Rubric-Induced Preference Drift (RIPD): evolutionary rubric search, benchmark-preserving selection, and DPO policy misalignment…
 siyuanli00/intact
Research code reproducing multi-turn LLM jailbreak experiments (FITD, MRCJ, ActorAttack, X-Teaming) from the SoK intent-oriented systematization…
 nawaralseelawi/pvbrf-id
Simulation code and results for a private, verifiable, Byzantine-robust federated intrusion detection protocol using secret sharing, Merkle audits…
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…