
benign-instruction-bench
 lzwhehe/benign-instruction-bench
Re-evaluating prompt-injection detectors on LLM agent tool outputs (paper draft, scripts, scores)
ai-securitydefensive-toolseducation+3
lzwhehe/benign-instruction-benchRe-evaluating prompt-injection detectors on LLM agent tool outputs (paper draft, scripts, scores)
 hoodoer/colonelclustered
A Java Burp Plugin that performs text clustering on responses to identify outliers/groups based on the actual content of the server responses, say…
 rbidou/pyrasp
Runtime Application Self Protection for Python web servers, serverless functions and MCP servers, detecting attacks, prompt injection and data leaks…
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…
 sliu11-byte/mea-bench
A lifecycle benchmark for black-box LLM extraction attacks, defenses, and adaptive attacks.
 js-lee-ai/refusal-relocates
Refusal localizes, the damage relocates, safety layers under few-sample fine-tuning
 liuz233/harde
Research code for HARDE, an agent harness that probes and adaptively optimizes components for runtime risk detection and execution control across…
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
 joshuaprovoste/deserializer
AST-based Static Code Analyzer with Agentic LLM-Powered Relationship Mapping to discover Python RCE paths and deep deserialization chains on AI, LLM,…
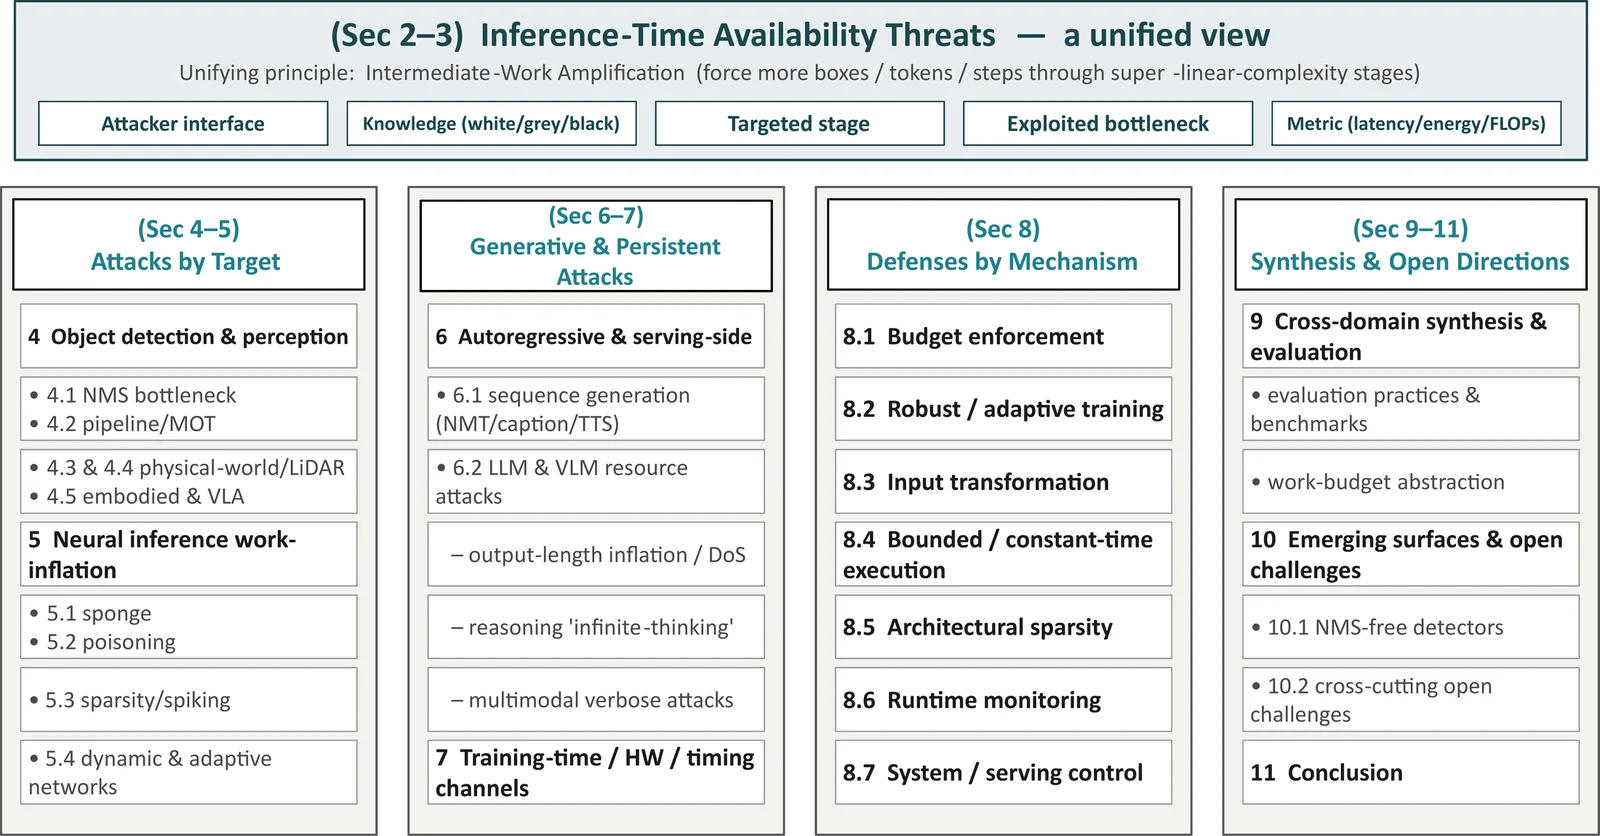 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
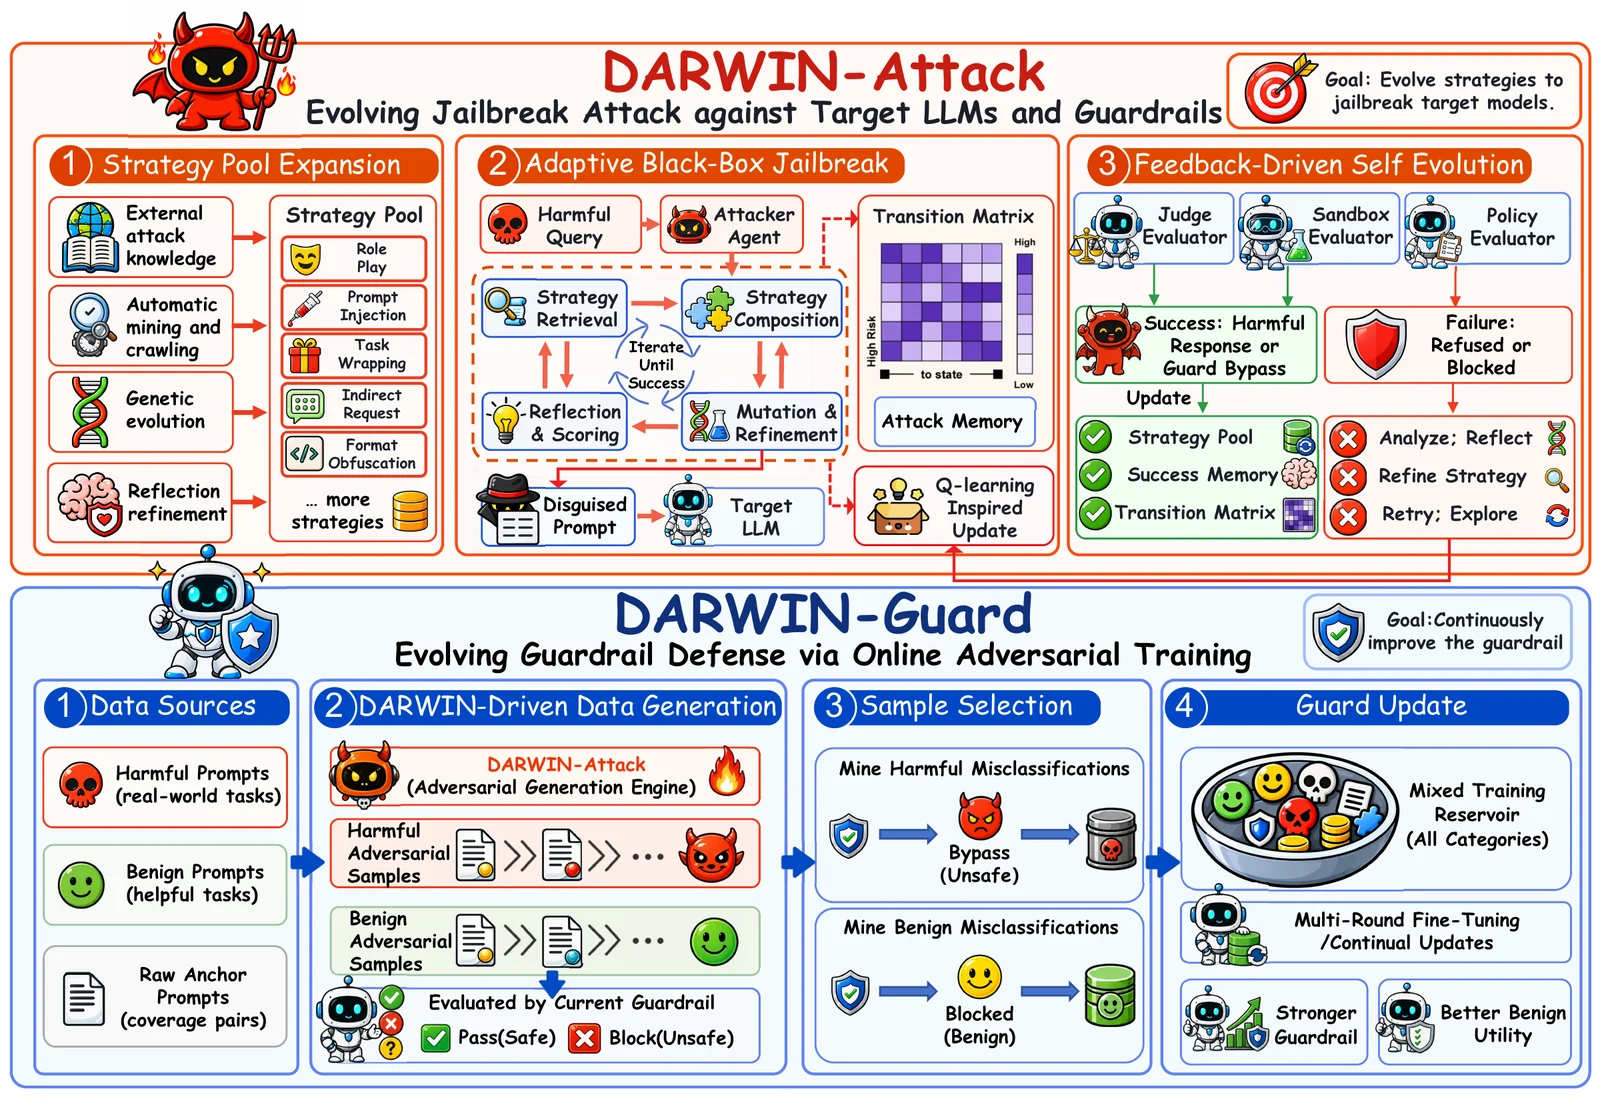 zju-llm-safety/darwin
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
 123wwwa/flowname
Next-generation JavaScript identifier recovery with LLMs.
 wsu-cyber-security-lab-ai/clipguard
Adversarial image perturbation tool that uses SAM segmentation and CLIP models to evade AI-based scam image classifiers for security research.
 sisl-uri/t-backdoor
Research code implementing T-Backdoor, temporal-trigger backdoor attacks on spiking neural networks using rate, latency, and jitter triggers without…