Malicious-code-detection-bugu

AI-based malicious code detection and obfuscation system with microservices for detection, packing, and code confusion, plus user and admin services.

AI-based malicious code detection and obfuscation system with microservices for detection, packing, and code confusion, plus user and admin services.

Runtime guard skill that detects and blocks malicious skill-induced attacks in skill-augmented agents, with an MCTS loop that evolves the guard…

Small language model that names and describes functions in stripped x86-64 binaries, with an open dataset, baselines, and LoRA fine-tuning…

Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…

Defense framework that mitigates malicious fine-tuning of LLMs using selective layer recovery and dynamic routing, with training, harmfulness…

MCP-enabled multi-agent framework for declarative YAML-driven agentic workflows, used for AI-assisted code auditing, vulnerability triage, and…

Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…

Fine-tuning framework that applies first-order optimal safety calibration and periodic recalibration to LLMs, preserving safety-compatible updates…

Code, response logs and labels for the paper Jailbreaking Open-Weight LLMs via Random Embedding Perturbations

Hunt down 840+ social media accounts using AI

Research implementation of Hop-Decayed Influence (HDI) and the 3S attack framework, exposing structural auxiliary indexing vulnerabilities in…

Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…

AST-based Static Code Analyzer with Agentic LLM-Powered Relationship Mapping to discover Python RCE paths and deep deserialization chains on AI, LLM,…

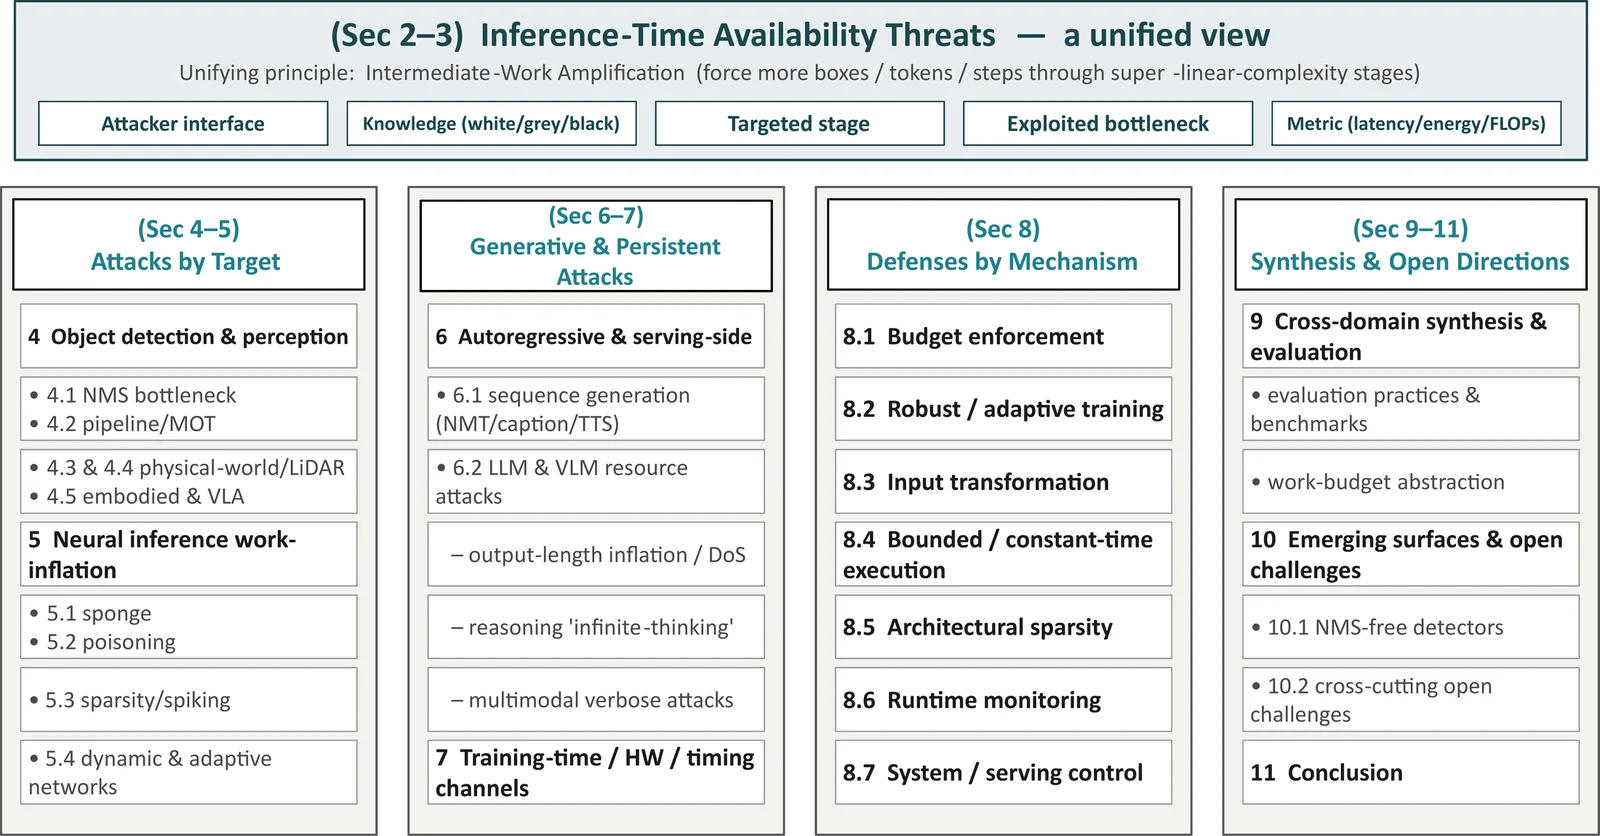
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…

Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…

Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…

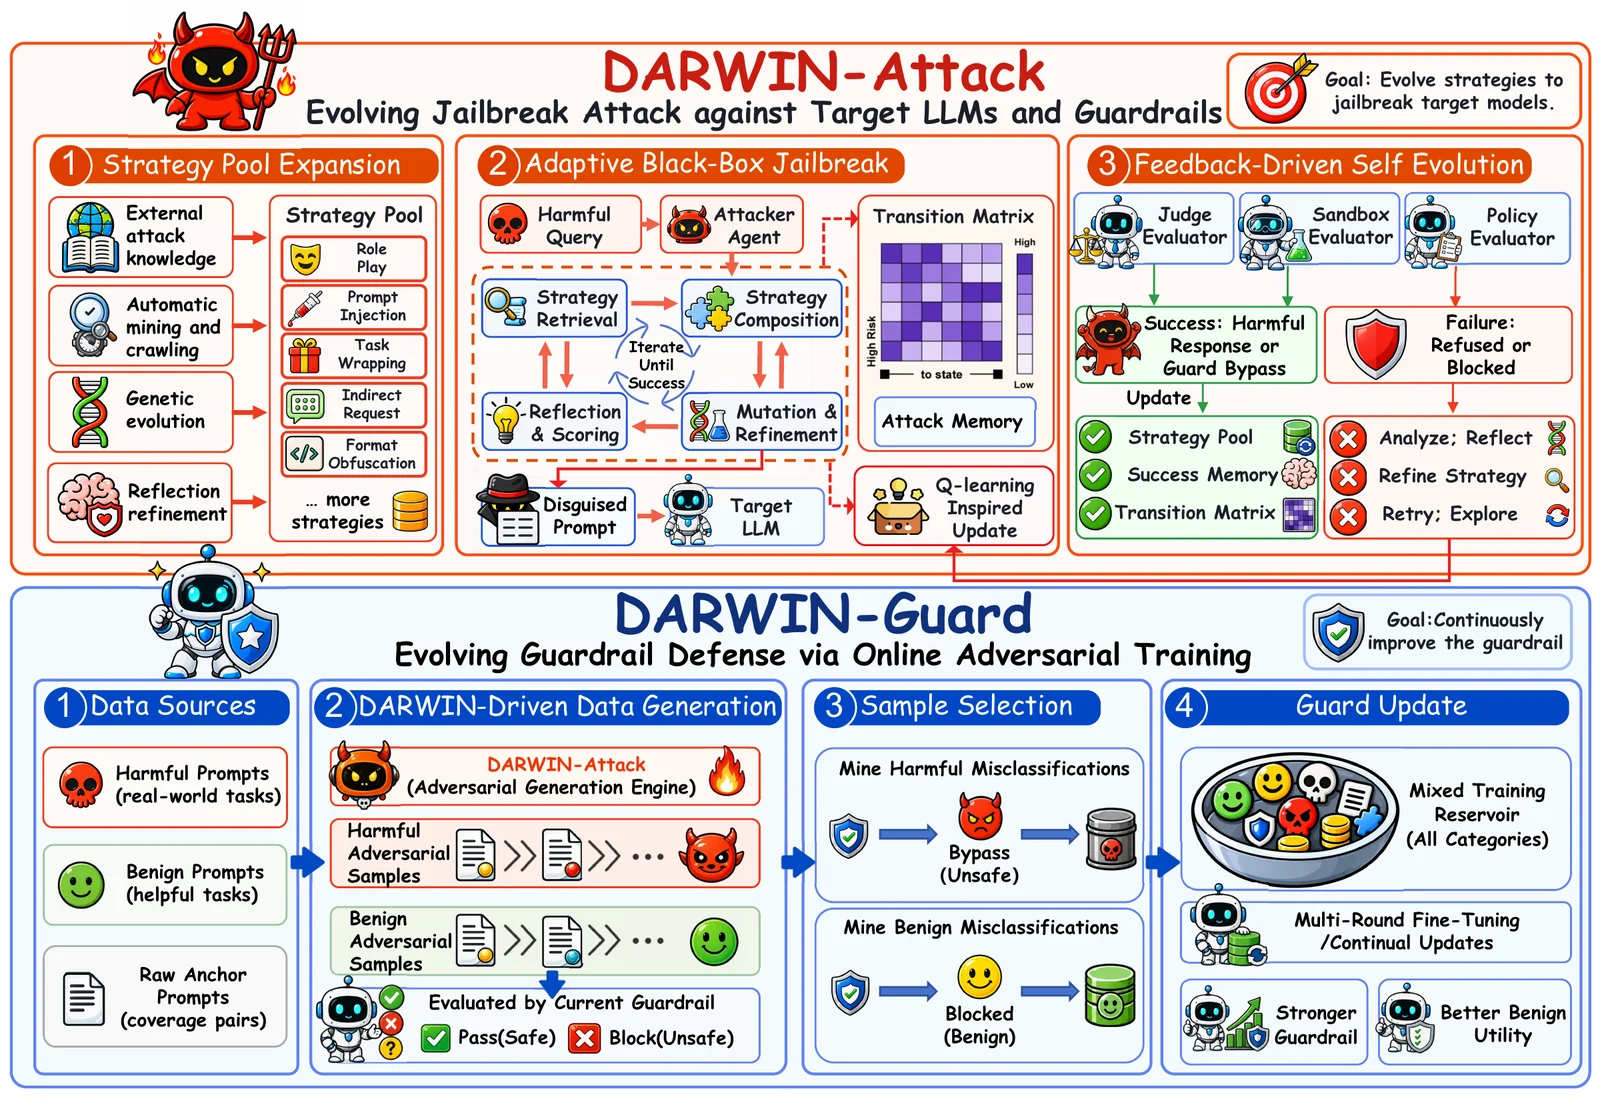
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…

Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…