
crawlee
 apify/crawlee
Node.js web scraping and browser automation library for building reliable crawlers with HTTP and headless browser support, proxy rotation, and…
anti-botcrawlerfingerprint-spoofing+6
26.0k
apify/crawleeNode.js web scraping and browser automation library for building reliable crawlers with HTTP and headless browser support, proxy rotation, and…
 microsoft/playwright
Browser automation framework with a single API for Chromium, Firefox, and WebKit. Supports web testing, scraping, screenshots, and network…
 vanyasem/vk-scraper
Command-line tool to scrape and download media (photos, videos, stories) from VKontakte users and communities using the VK API. Supports multiple…
 davidvoitenko/proxy-workbench
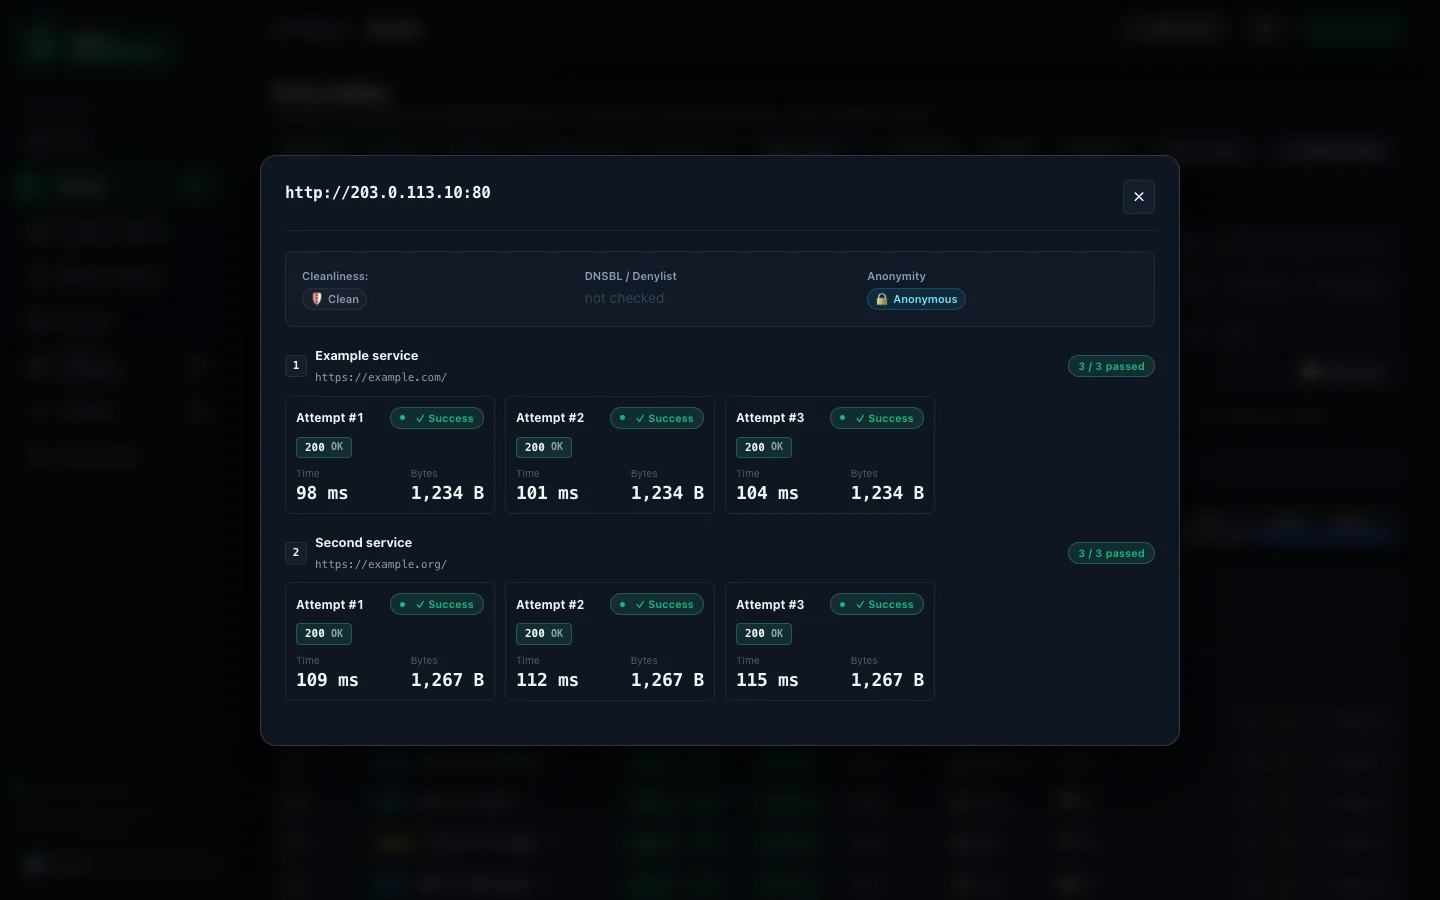
Collects, checks and ranks public HTTP/SOCKS proxies against your own targets, then serves them via ranked exports, pools, a rotating gateway and a…
 xroche/httrack
HTTrack Website Copier, copy websites to your computer (Official repository)
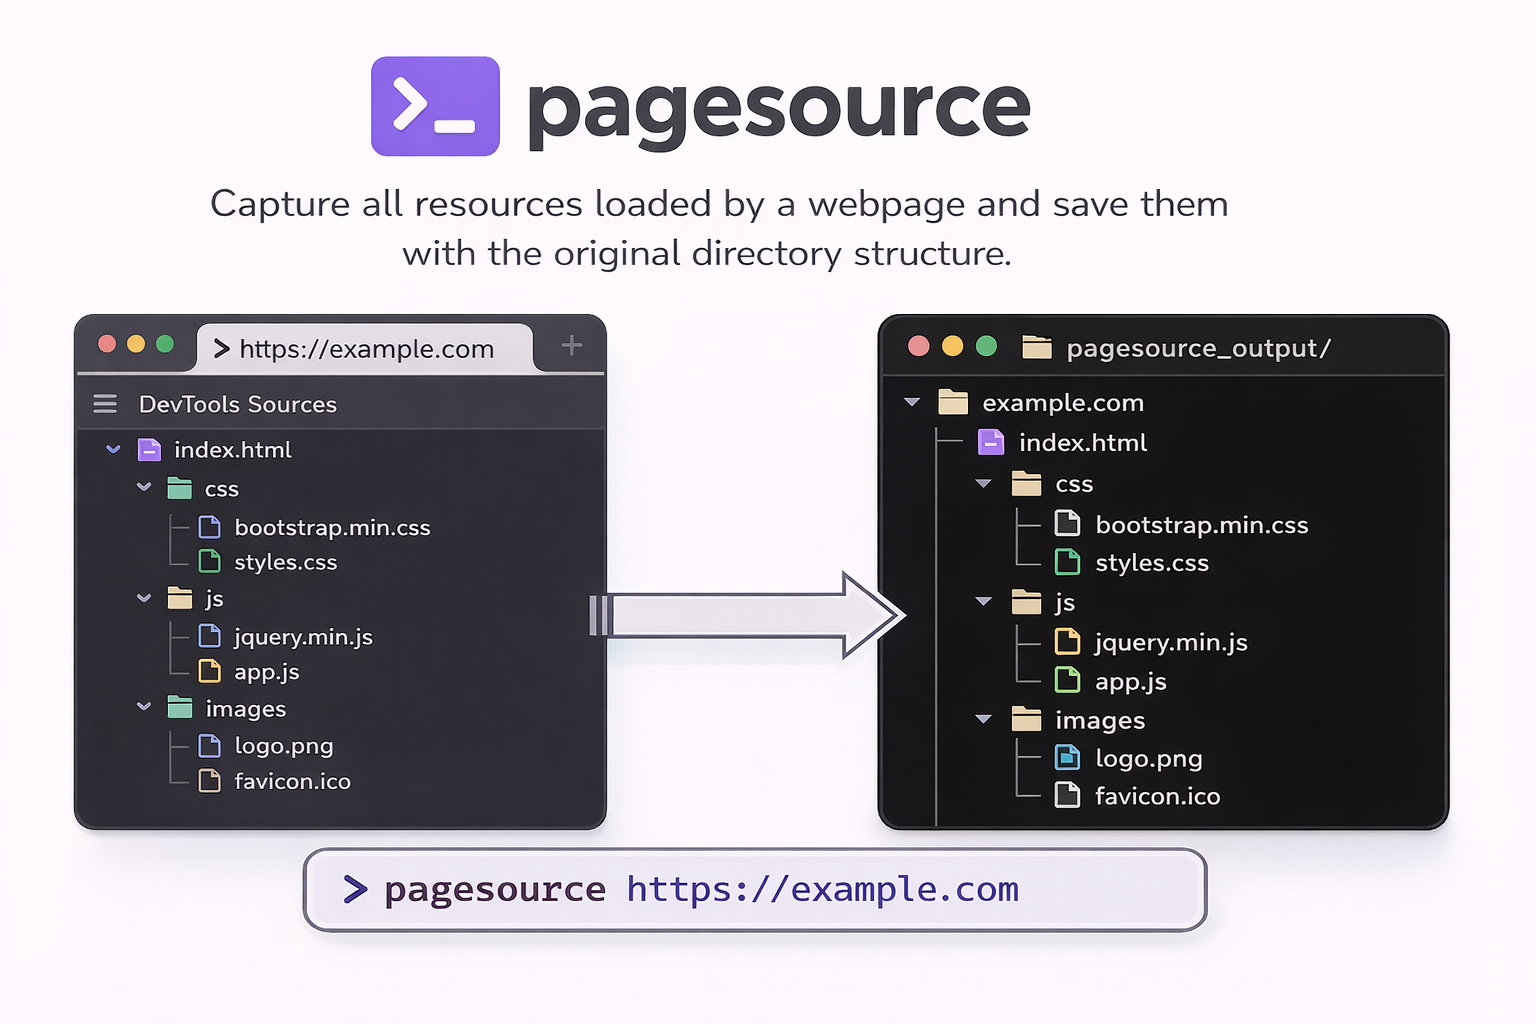 timf34/pagesource
CLI to download websites' actual JS/CSS/assets (not flattened HTML)
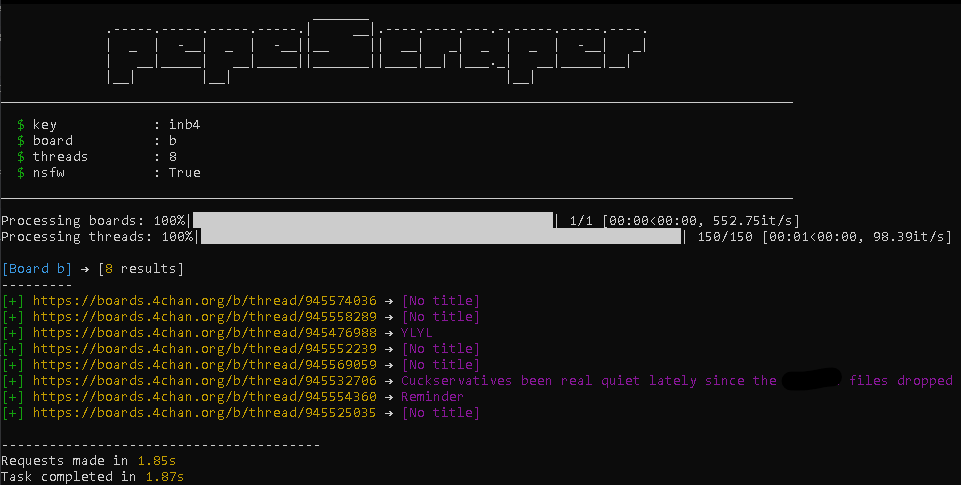 juaanreis/pepescraper
4chan content scraper
 fake-useragent/fake-useragent
Up-to-date simple useragent faker with real world database
 searxng/searxng
Privacy-respecting metasearch engine that aggregates results from multiple search services without tracking or profiling users. Self-hostable with…
 panniantong/agent-reach
Give your AI agent eyes to see the entire internet. Read & search Twitter, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu — one CLI, zero API fees.
 mindpatch/startpage-parser
parsing search results from startpage search engine (based on google.com results)