

reburp
 forefy/reburp
A Burp Suite extension that exposes the full Montoya API as a local REST API, with Swagger UI
ai-securityapi-security-testingfuzzing+7
forefy/reburpA Burp Suite extension that exposes the full Montoya API as a local REST API, with Swagger UI
 githubsecuritylab/seclab-taskflows-fuzzing
An LLM-driven fuzzing pipeline powered by the GitHub Security Lab Taskflow Agent
 les-k/wp-secure-mcp
A WordPress plugin exposing an MCP server over the REST API, with the security model as the point -- closes the CVE-2026-15015 OAuth-bypass shape by…
 safety-research/red-teaming-auto-mode
Research code for red-teaming AI auto-mode monitors, including simulation evals, fuzzing, and monitor implementations for Claude Code and Codex…
 vighnesh91/omnisec-hex
Browser-local security monorepo with six modules for mobile APK/IPA triage, client-side DAST fuzzing, OSINT directories, offline AI threat scoring,…
 snailsploit/claude-red
Curated library of 78 offensive security SKILL.md modules that prime Claude with expert red team methodology across web, AD, wireless, cloud, and…
 off-by-1-labs/flawed
Fix-Like Artifacts With Embedded Defects
 gmh5225/enigma-
C++ reimplementation of Ghidra's analytical core without JVM dependencies, providing embeddable binary analysis, Pcode/Sleigh foundations, and…
 lumoslab-innovation/openhunterai
Local-first AI red team for web, API, and LLM application security. Attacker-style reasoning, evidence-backed findings, and skills for AI coding…
 aipentest/cyberstrikeai
The system of action for AI-native cybersecurity—where intent becomes governed execution, evidence becomes operational memory, and every operation…
 pigeonlabshq/pigeon
Enforce least-privilege delegation for AI agents with signed, scoped credentials. Grant sub-agents narrow capabilities and resources, verify actions…
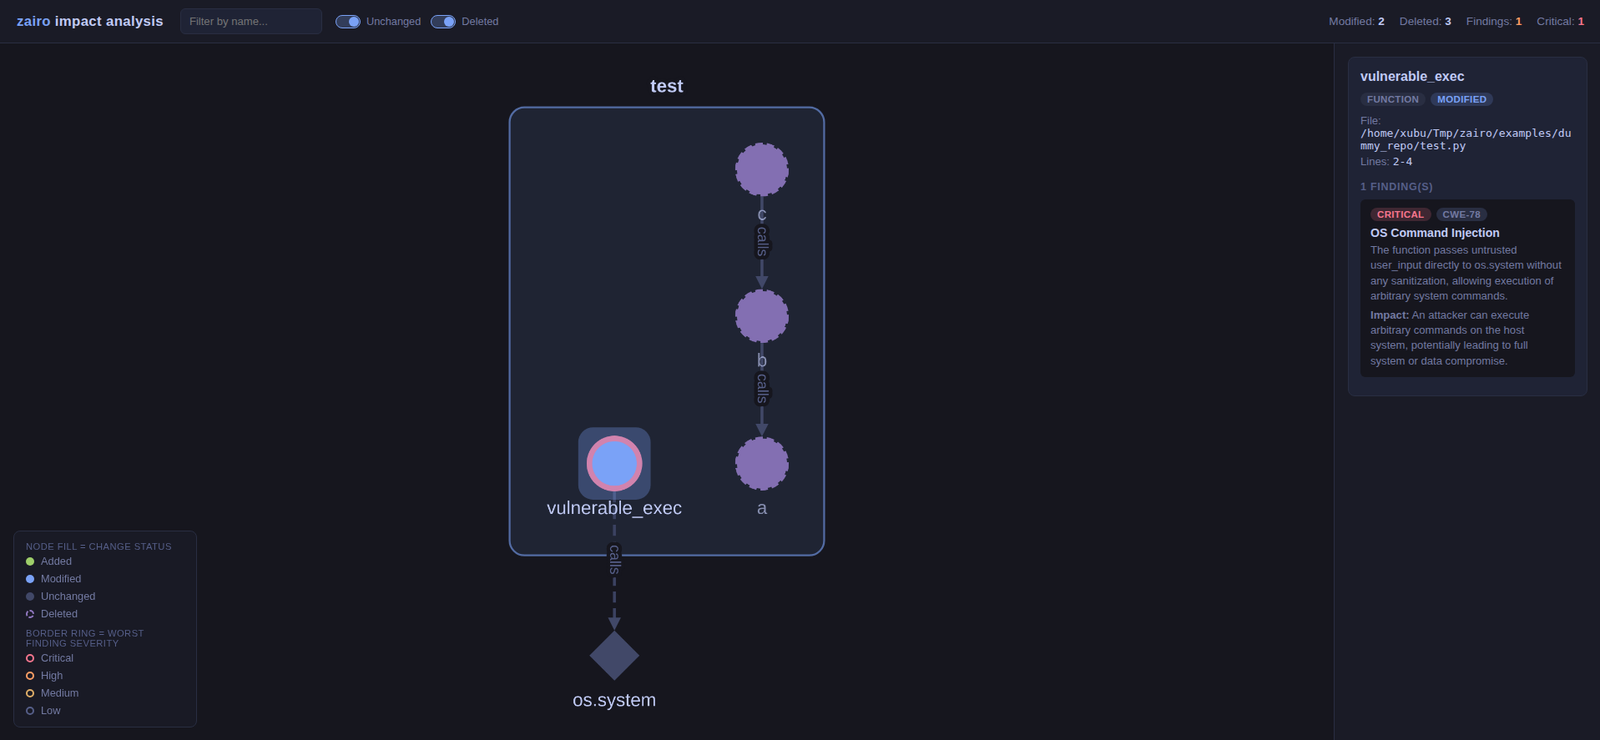 iamavu/zairo
Scans code diffs with context to build an impact graph and uses LLMs to find vulnerabilities, supporting multi-repo scans and CI gating with SARIF…
 michaels1011/ephemora-cell
Capability-based WASM runtime for executing untrusted AI-generated code with enforced CPU, memory, time, I/O, and filesystem limits. Provides…
 ericmtzmtz/pwnproxy
An open, local-first security testing platform for pentesters, AI agents, CI/CD pipelines, and teams.
 foxirain/linux-kernel-codex-harness
Evidence-driven Linux kernel vulnerability research harness used in the investigation of CVE-2026-31720
 pie-script/llm-agent-testbed
An empirical security testbed evaluating prompt injection, confused-deputy vulnerabilities, and tool-calling defenses in LLM agents.
 fuzzingbrain/fuzzingbrain-bench
A benchmark for LLM-driven bug discovery: 77 challenges across 43 open-source projects (C/C++/Java).
 juanlunaia/aegis-latent-core
AI governance and evidence gateway for multi-provider LLM applications. FastAPI + optional Rust core for policy, WAF, egress, rate limits, sessions,…