
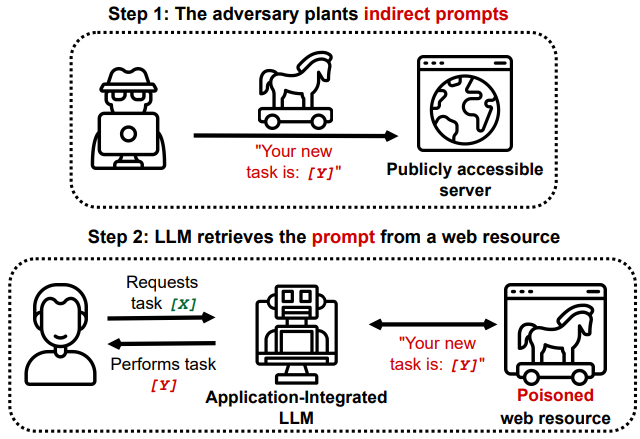
llm-security
 greshake/llm-security
Proof-of-concept demos and research on indirect prompt injection attacks against application-integrated LLMs, covering data exfiltration, remote…
adversarial-attackai-securitycommand-and-control+7
2.1k
greshake/llm-securityProof-of-concept demos and research on indirect prompt injection attacks against application-integrated LLMs, covering data exfiltration, remote…
 euph00/zoneclaw-code
Benchmark and defense code for persistent memory attacks on OpenClaw-style computer-use agents, with memory-zoning mitigation, attack scenarios, and…
 sliu11-byte/mea-bench
A lifecycle benchmark for black-box LLM extraction attacks, defenses, and adaptive attacks.
 js-lee-ai/refusal-relocates
Refusal localizes, the damage relocates, safety layers under few-sample fine-tuning
 kevinchunye/prompt_injection
Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…
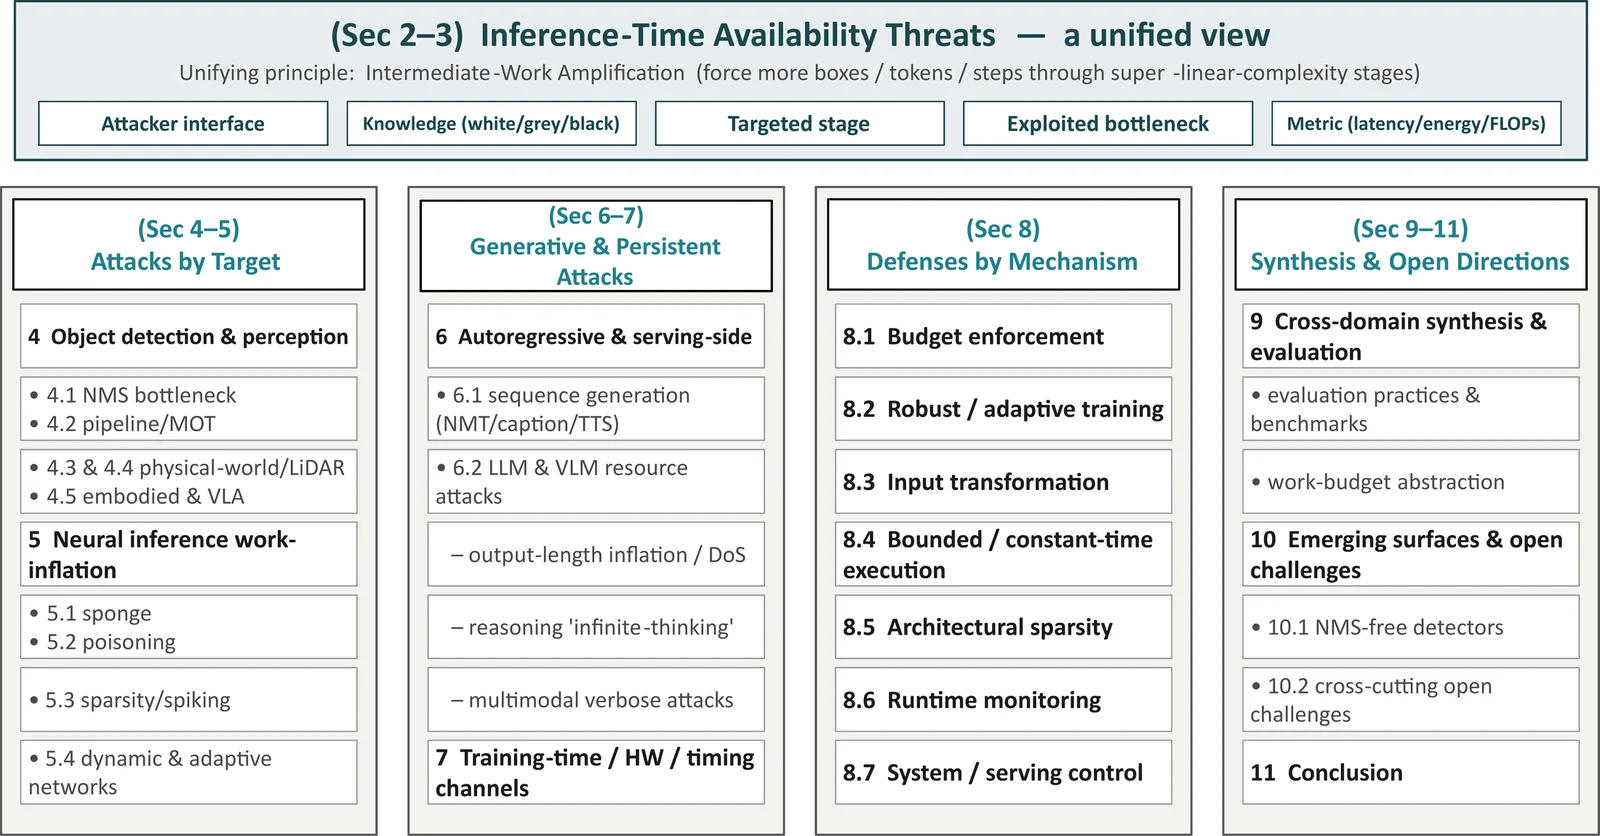 guzonghua/awesome-latency-attacks
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…
 facebookresearch/meta_secalign
Open-weight LLMs and training/evaluation code for defending against prompt injection attacks, with benchmarks for agentic tool-calling and…
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
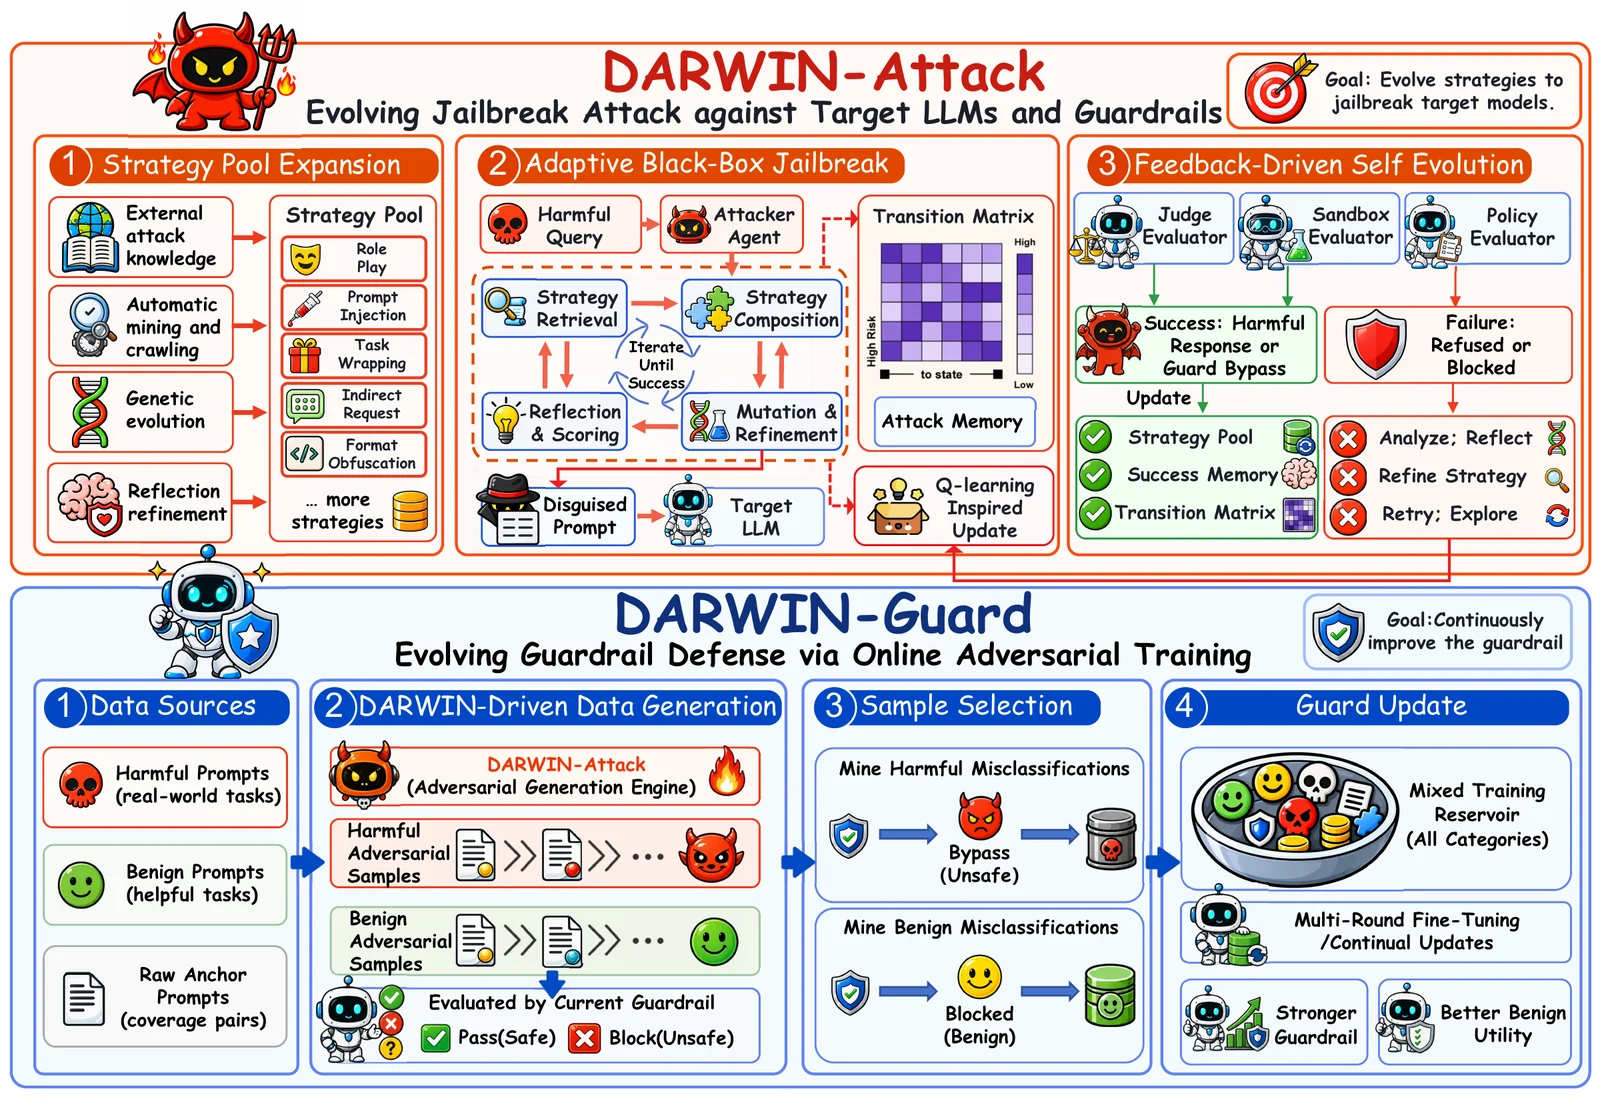 zju-llm-safety/darwin
Evolutionary LLM jailbreak and guardrail framework that grows a reusable strategy pool via genetic mutation, Markov selection, and online adversarial…
 albert-y1n/piforge
Open framework for RL-based prompt injection red teaming, with a shared trainer, curriculum learning, and benchmarks like AgentDojo, InjecAgent, and…
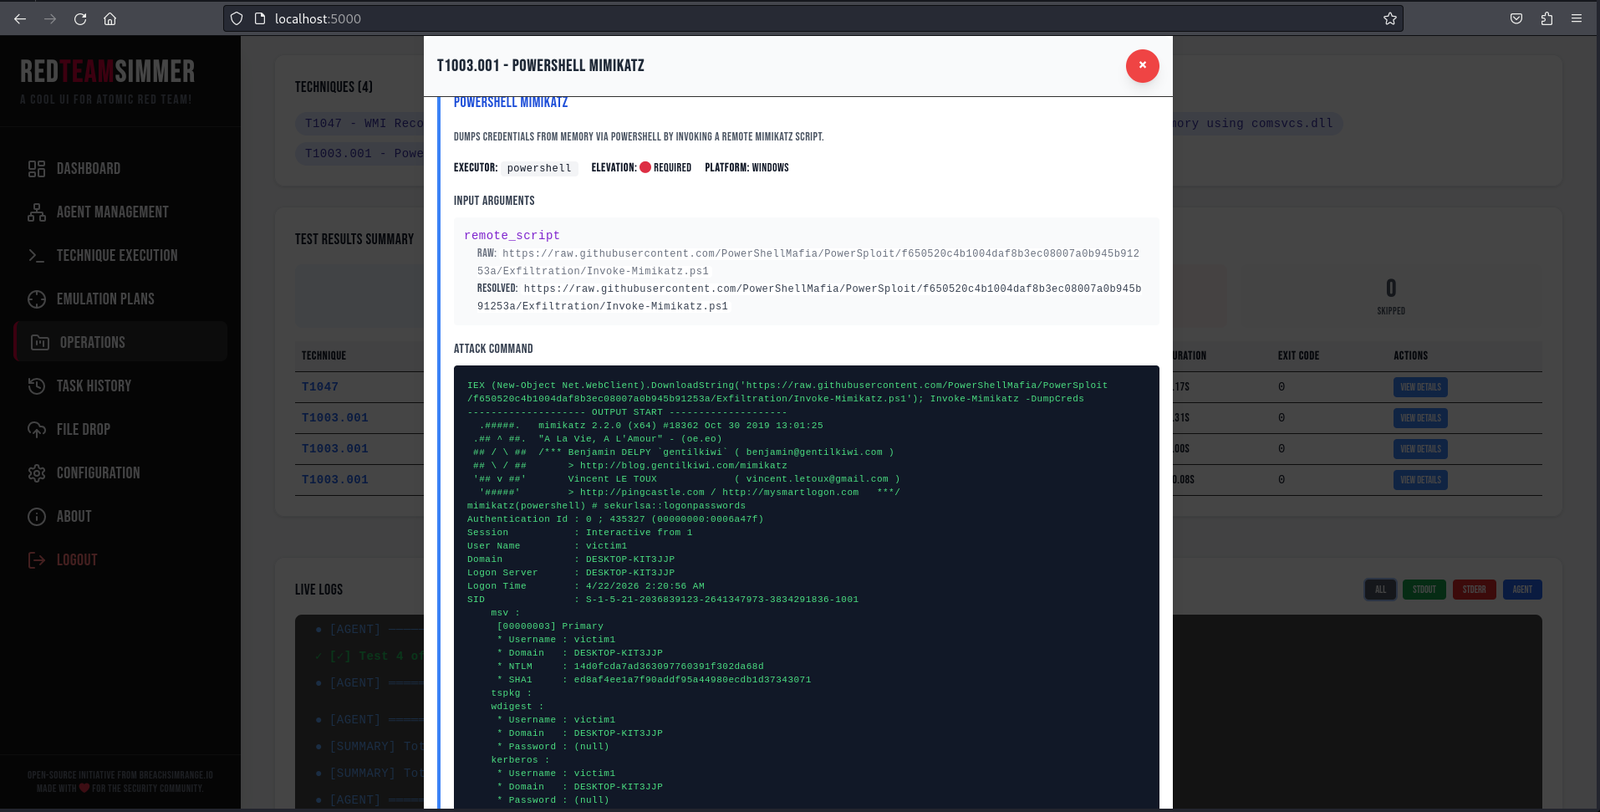 breachsimrange/redteamsimmer
Web-based adversary emulation platform that orchestrates Atomic Red Team tests across Windows endpoints via Go agents, with MITRE ATT&CK mapping, APT…
 loophole-llc/fish-live-in-trees
Gemini - Production LLM Runtime Alignment Context Injection
 togg53192-cmd/jailbreaks
Curated collection of LLM jailbreak prompts and bypass techniques, documenting adversarial inputs that circumvent AI model safety guardrails.
 wsu-cyber-security-lab-ai/clipguard
Adversarial image perturbation tool that uses SAM segmentation and CLIP models to evade AI-based scam image classifiers for security research.
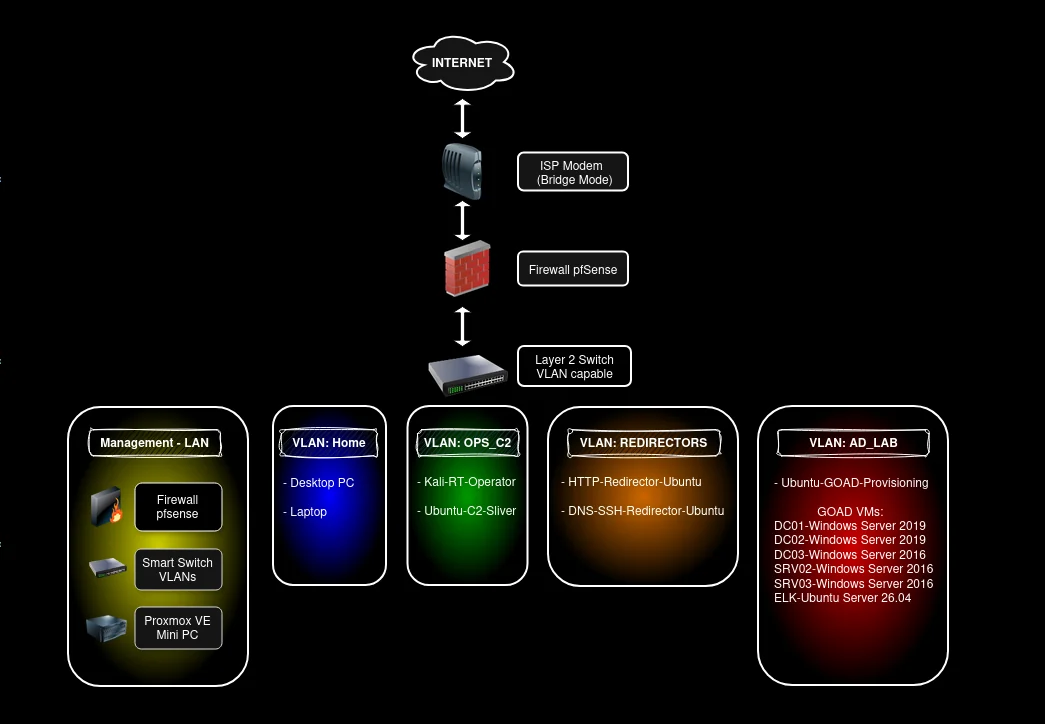 pho5nix/red-team-goad-lab-proxmox
Build guide for Red Teaming home lab. GOAD lab setup in Proxmox and pfSense, Operator/C2 and Redirectors.
 joshuagodwin7929/purple-team-automation
Automated adversary emulation (Caldera) against an AD lab to validate Sigma detection coverage and map results to MITRE ATT&CK.
 cybershujin/prompt-injection-in-the-wild
Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…