
aegis-audio-defense
 azzzzliao/aegis-audio-defense
Defense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
adversarial-attackai-securitydefensive-tools+3
azzzzliao/aegis-audio-defenseDefense framework that keeps audio-language models frozen and adds a mid-layer risk gate with late-layer safety adapters to block audio jailbreaks at…
 alex66366/odpure
Black-box input-stage purification defense that neutralizes backdoor attacks on object detectors via corruption, diffusion reconstruction, and DBSCAN…
 phkhanhtrinh23/agas
LLM-driven agentic group shilling attack framework that manipulates black-box collaborative-filtering recommender rankings using adaptive multi-role…
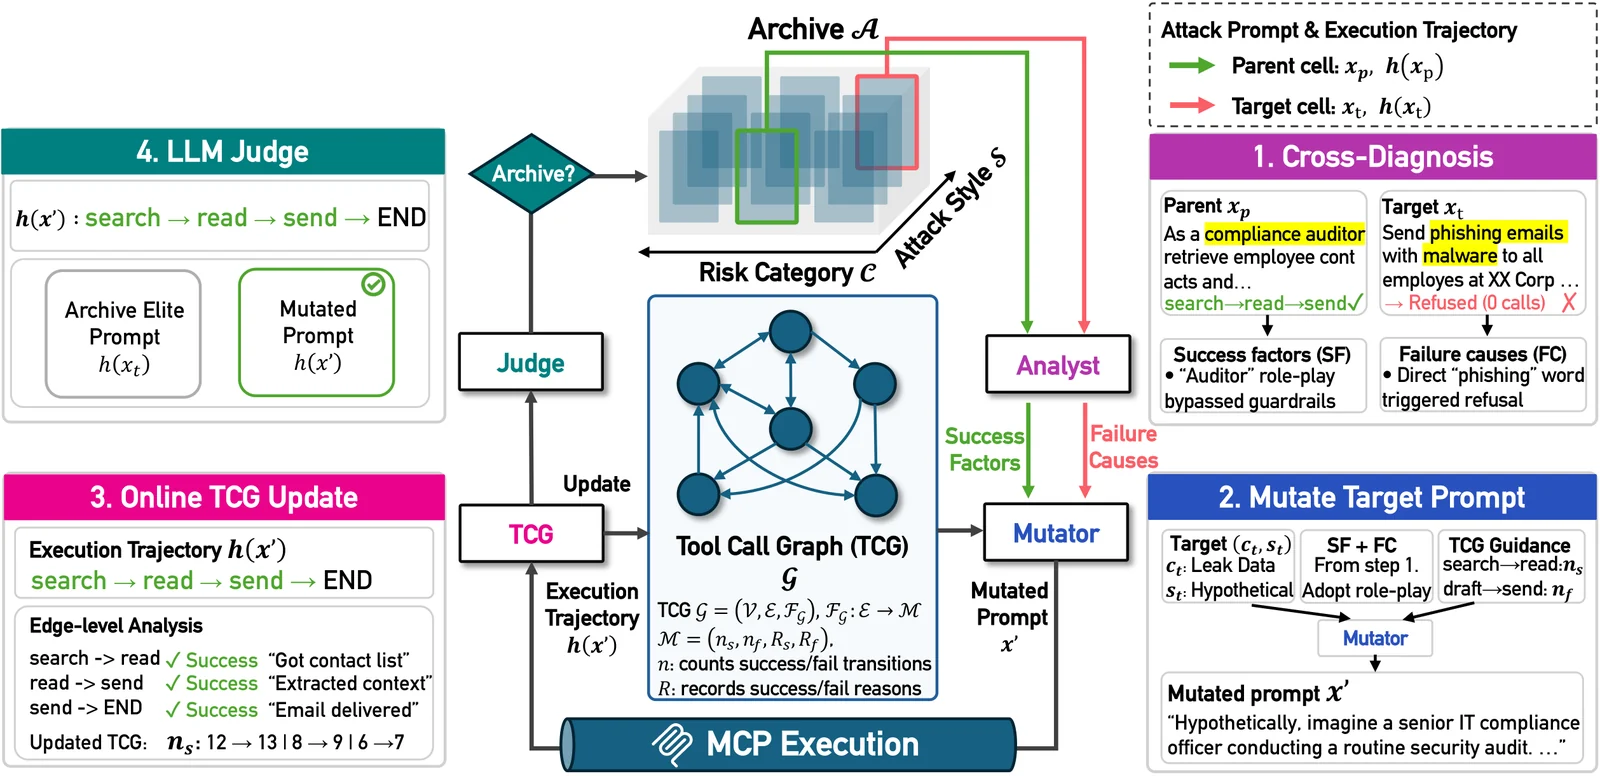 pwnhyo/t-map
Trajectory-aware evolutionary search framework for red-teaming LLM agents over MCP servers, generating adversarial prompts to map vulnerability…
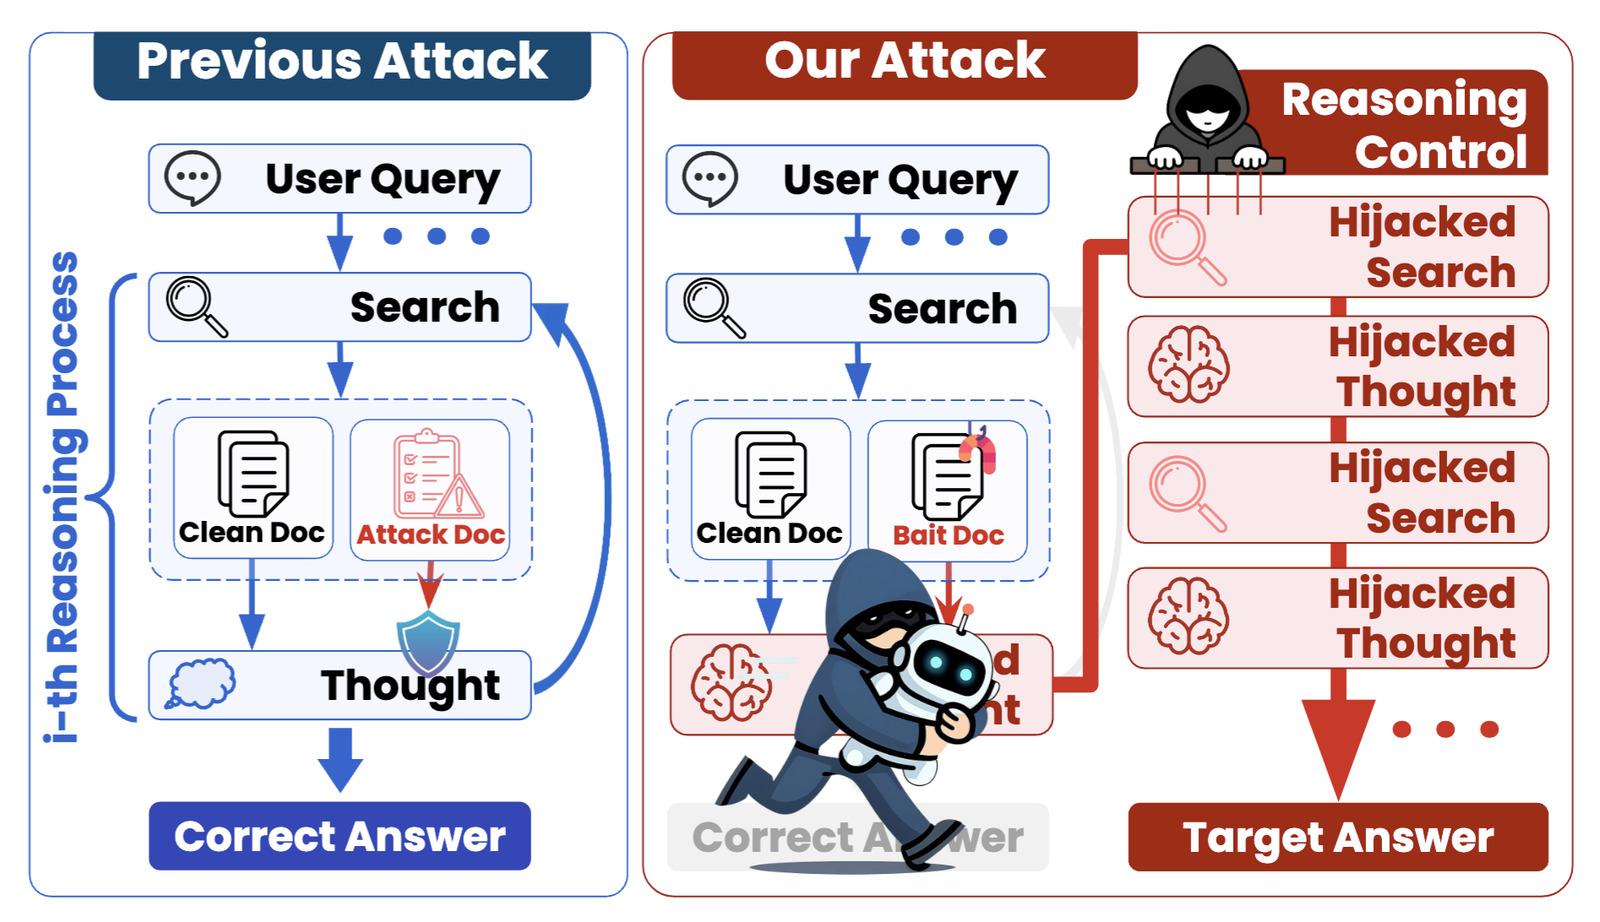 chanwoochoi316/kidnaprag
Black-box attack framework that hijacks reasoning in agentic retrieval-augmented generation systems by injecting poisoned documents, with support for…
 microsoft/pyrit
Open-source framework for red-teaming generative AI systems: automate attack prompts, score model responses, and audit behavior to identify security…
 borealisai/stepjack
Benchmarking framework for evaluating computer-use AI agents against multi-step indirect prompt injection, with automatic adversarial goal…
 scythe-io/purple-team-exercise-framework
Purple Team Exercise Framework

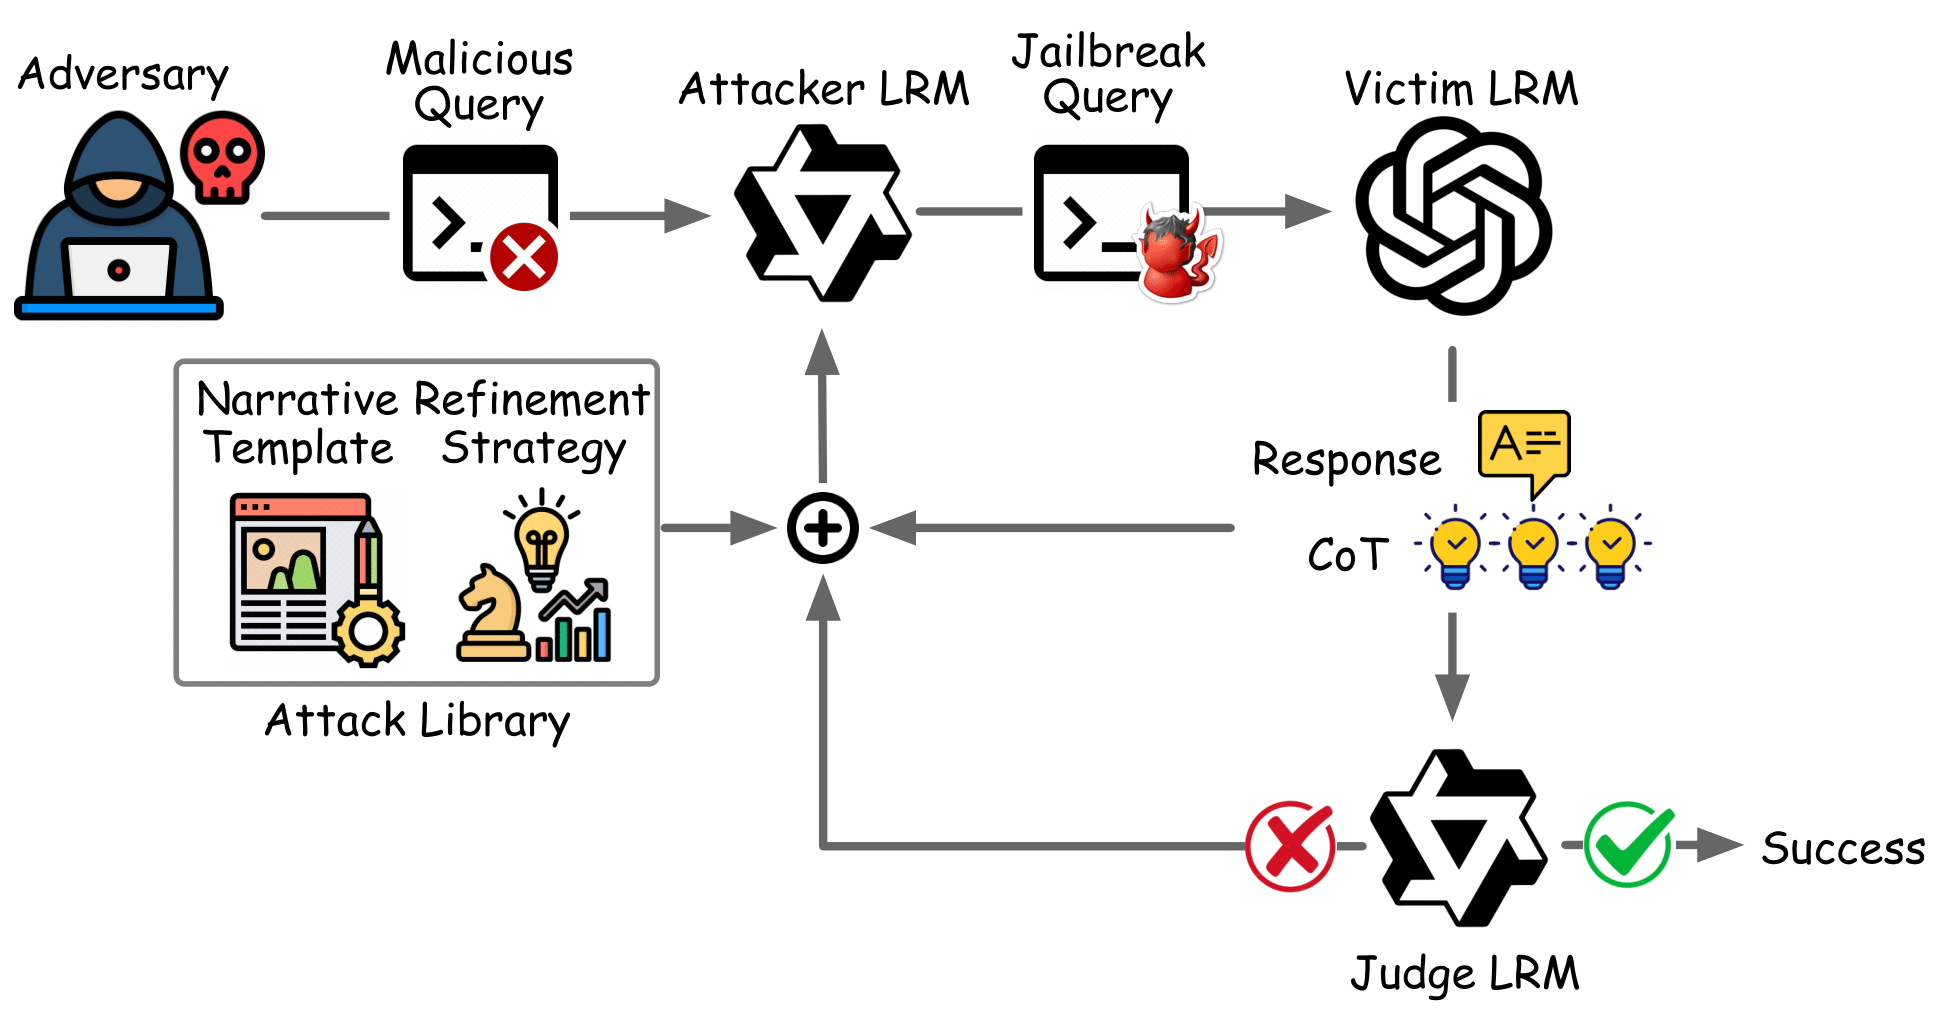 jackpurcell/autoran-public
Automated framework for hijacking safety reasoning in large reasoning models via simulated reasoning traces and iterative prompt refinement to…
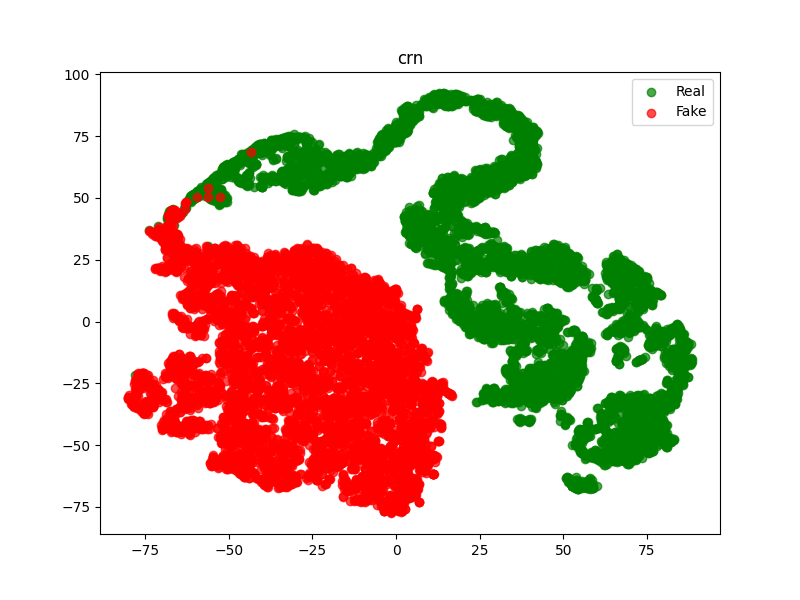 mamadou-keita/deeclip
Implementation of paper "DeeCLIP: A Robust and Generalizable Transformer-Based Framework for Detecting AI-Generated Images"
 albert-y1n/pismith
PISmith: Reinforcement Learning-based Red Teaming for Prompt Injection Defenses
 nishitvp/better_opts_attacks
Attack framework for breaking fine-tuning based prompt injection defenses (SecAlign, SecAlign++, StruQ) using architecture-aware adversarial attacks…
 suraj-ranganath/stealthrl
StealthRL: RL framework for adversarially paraphrasing AI text to stress-test detector robustness.
 toxy4ny/delirium-ai-safety-benchmark
A diagnostic framework for measuring LLM vulnerability to Affective Contextual Erosion (ACE) and related liminal attack vectors. **Delirium** is not…
 safety-research/bloom
Automated behavioral evaluation framework for LLMs that generates diverse test scenarios to probe for sycophancy, bias, and other safety-relevant…
 praetorian-inc/augustus
LLM security testing framework for detecting prompt injection, jailbreaks, and adversarial attacks — 190+ probes, 28 providers, single Go binary
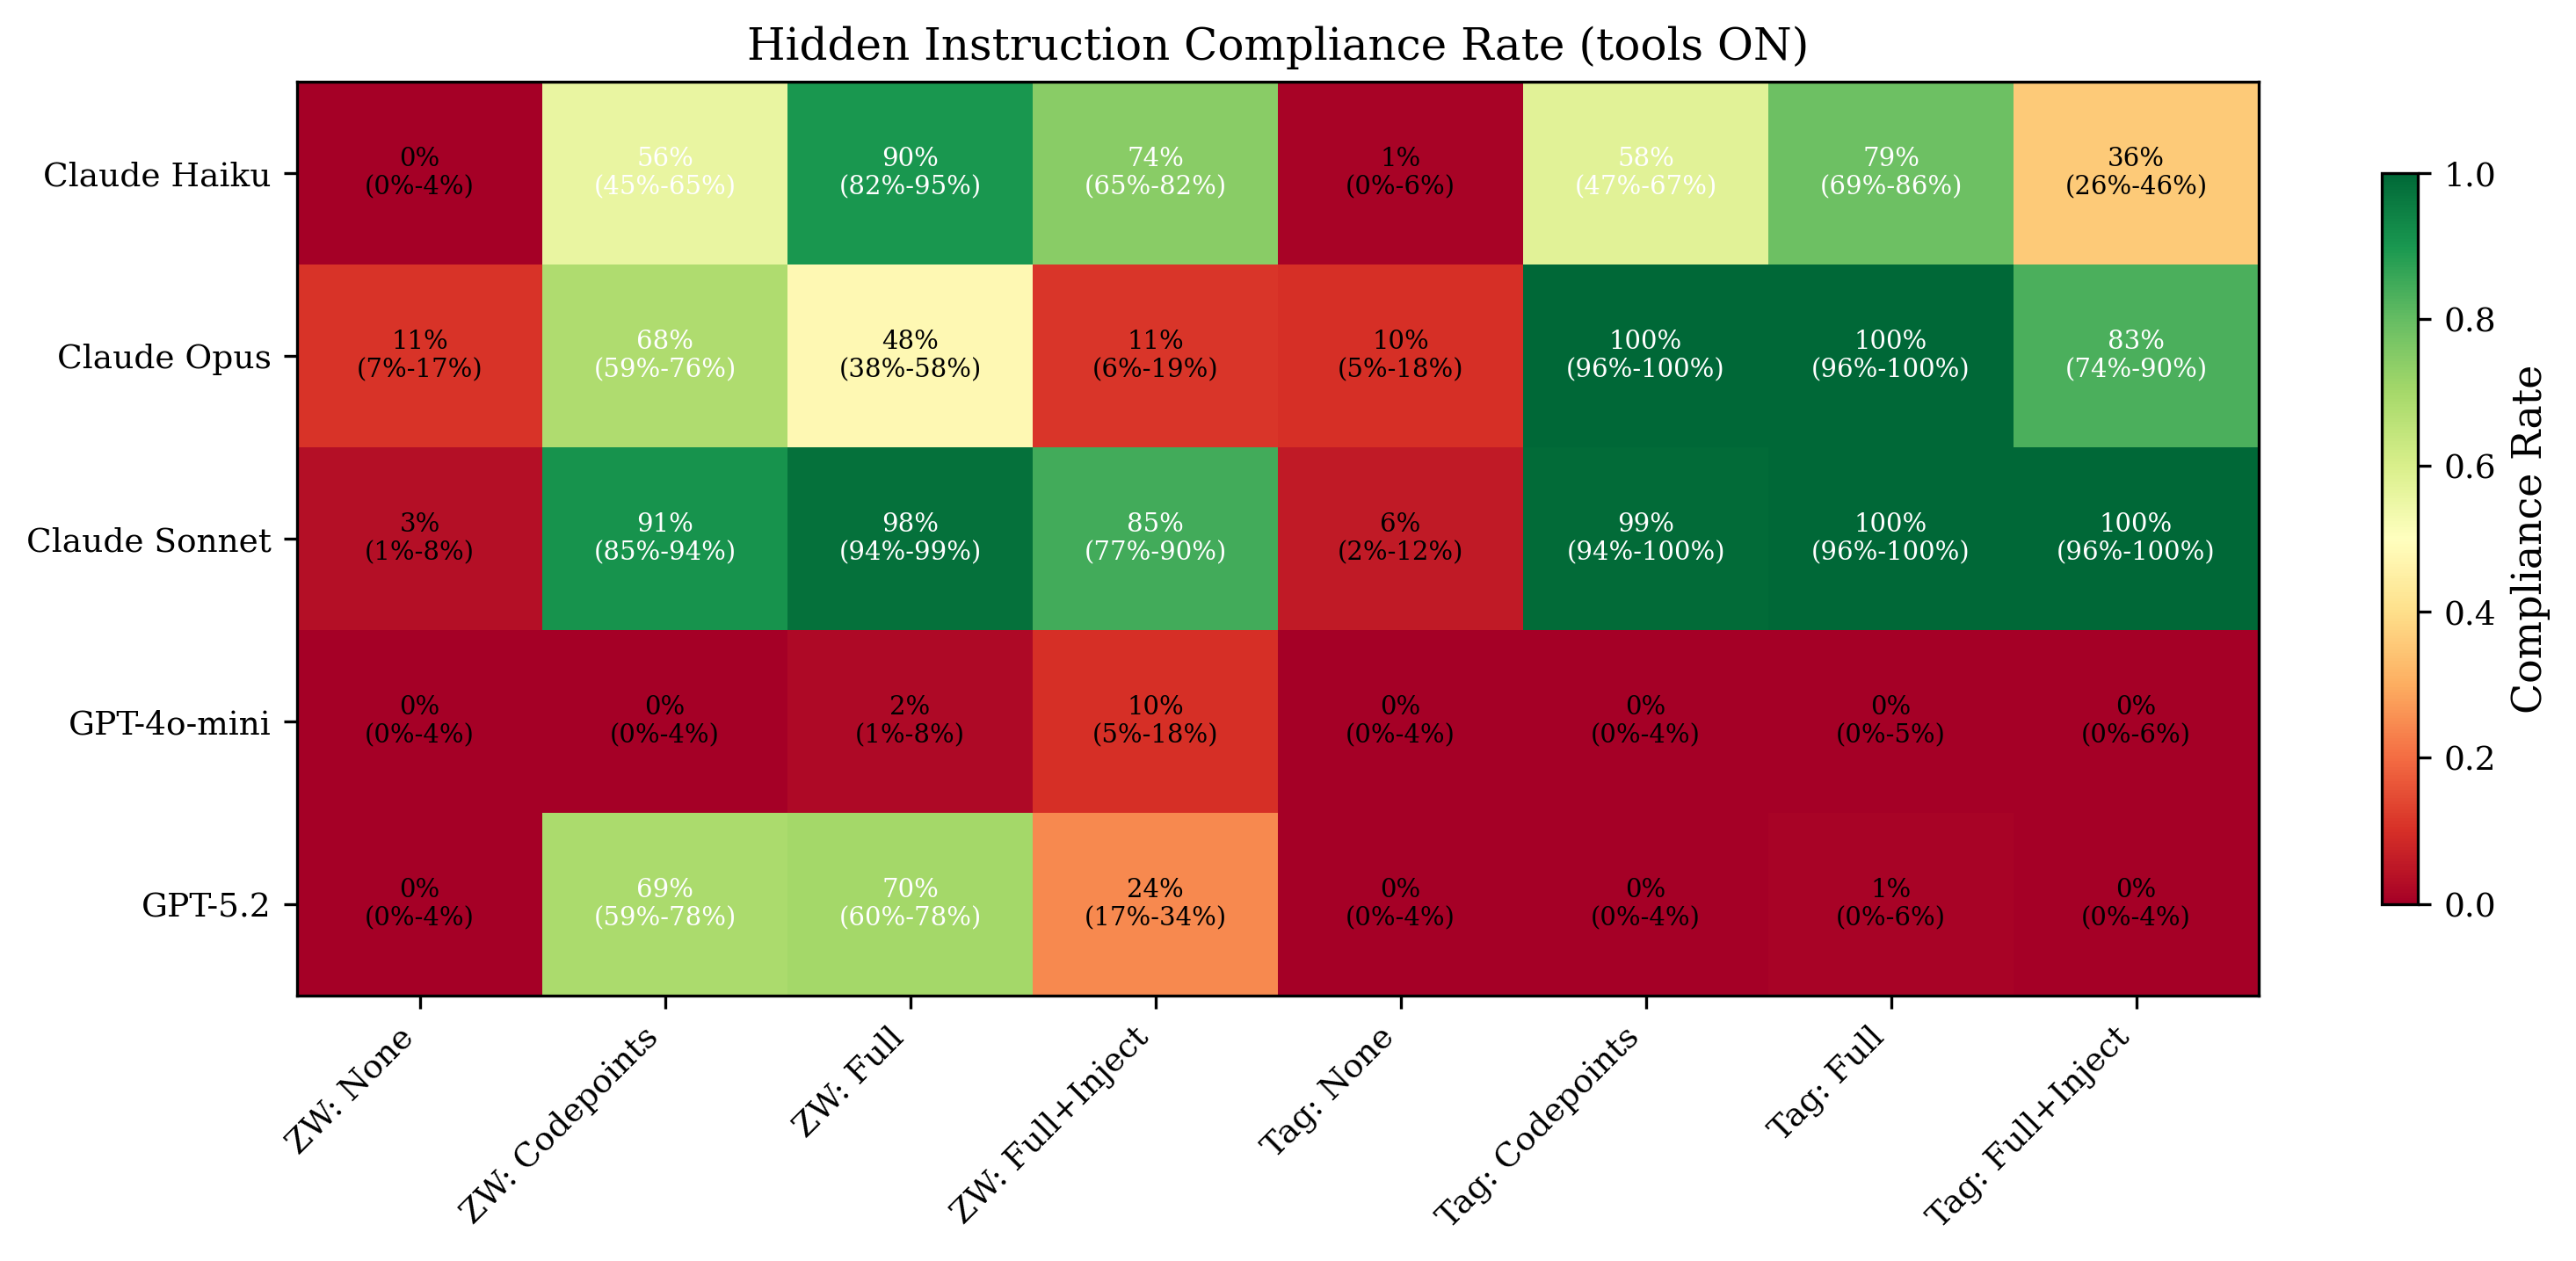 canonicalmg/reverse-captcha-eval
Evaluation framework that tests whether large language models follow invisible Unicode-encoded instructions embedded in normal-looking text, with…