Purple-Team-Automation

Automated adversary emulation (Caldera) against an AD lab to validate Sigma detection coverage and map results to MITRE ATT&CK.

Automated adversary emulation (Caldera) against an AD lab to validate Sigma detection coverage and map results to MITRE ATT&CK.

Modular LLM vulnerability scanner that probes for hallucination, data leakage, prompt injection, jailbreaks, and toxicity using static, dynamic, and…

Fully automatic censorship removal for language models

The exploit server for out-of-band findings. Point a target at a domain you own. Every HTTP request and every email it sends back lands in a…

Open-source framework for red-teaming generative AI systems: automate attack prompts, score model responses, and audit behavior to identify security…

Bypass restricted and censored content on AI chat prompts 😈

Tracker of publicly reported prompt-injection techniques, broken down by delivery method, encoding, and propagation behavior, with confirmed models,…

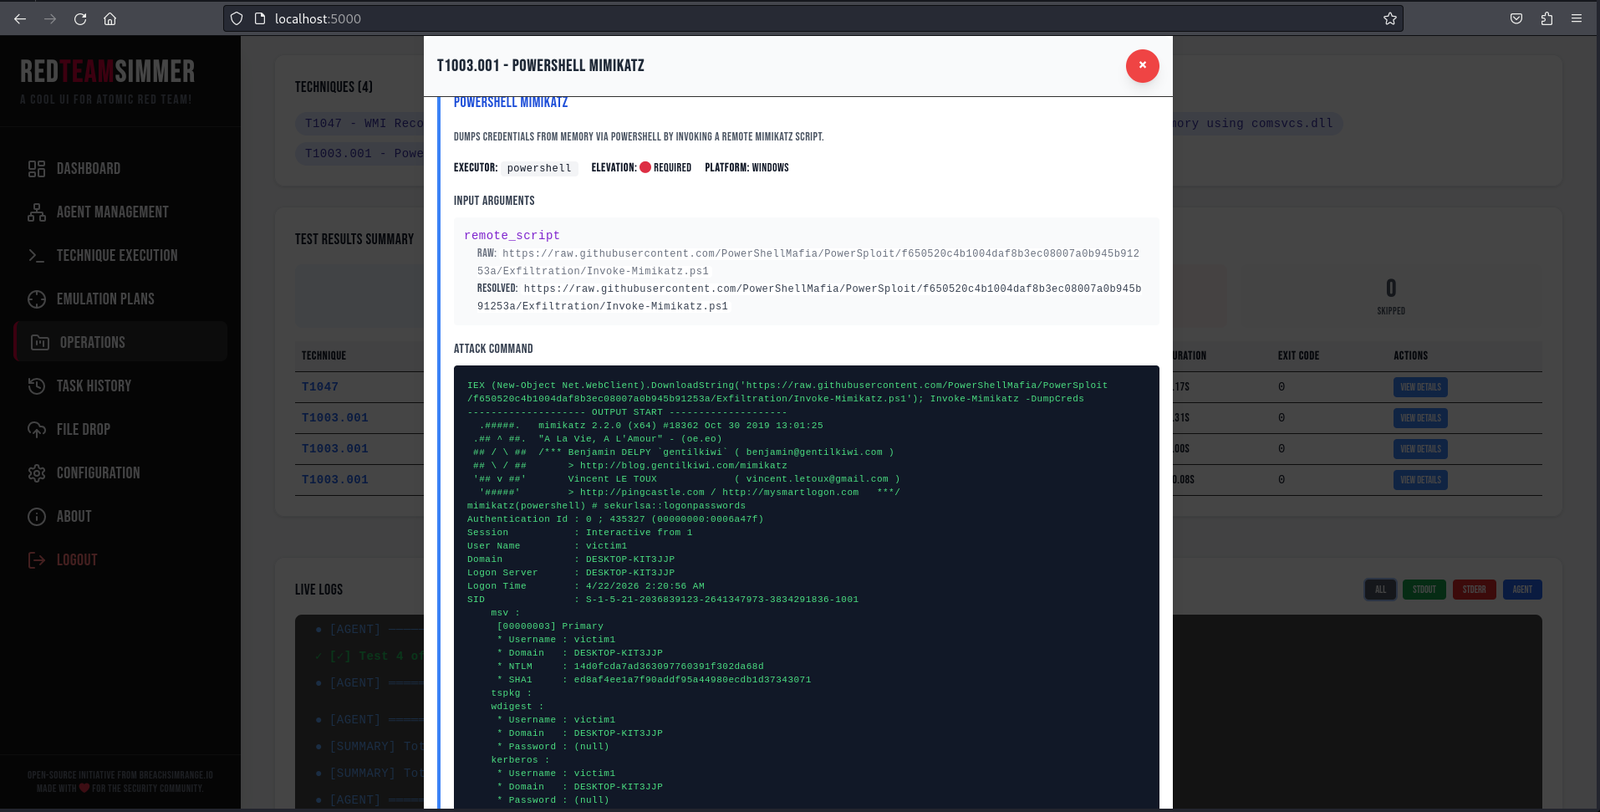
Web-based adversary emulation platform that orchestrates Atomic Red Team tests across Windows endpoints via Go agents, with MITRE ATT&CK mapping, APT…

Fully automatic censorship removal for language models

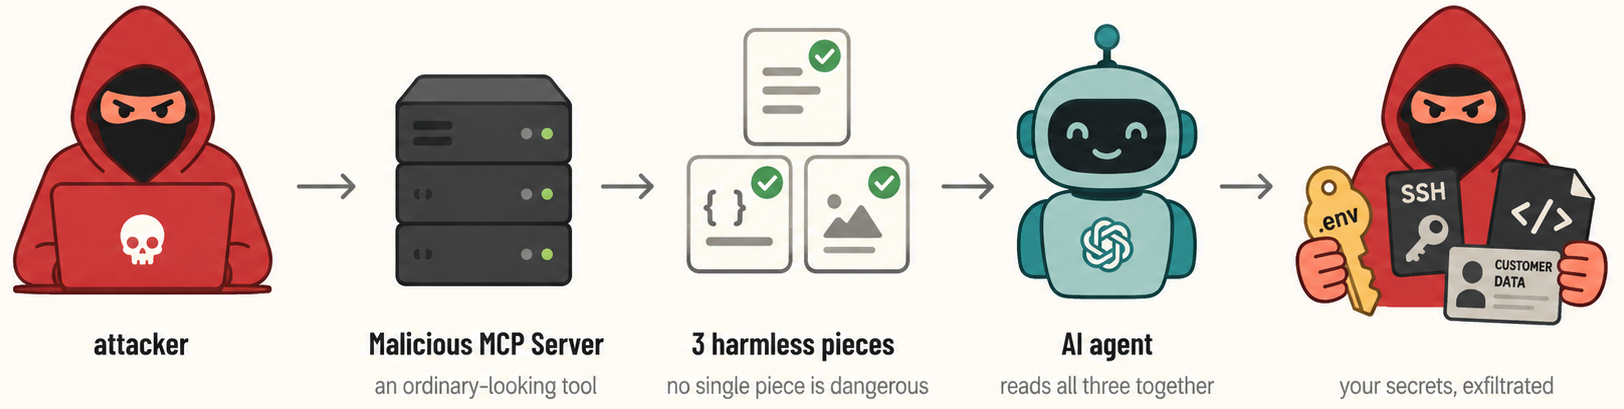
Ghostsplice repository: PoC for Cross-Channel Trust Fragmentation Attack

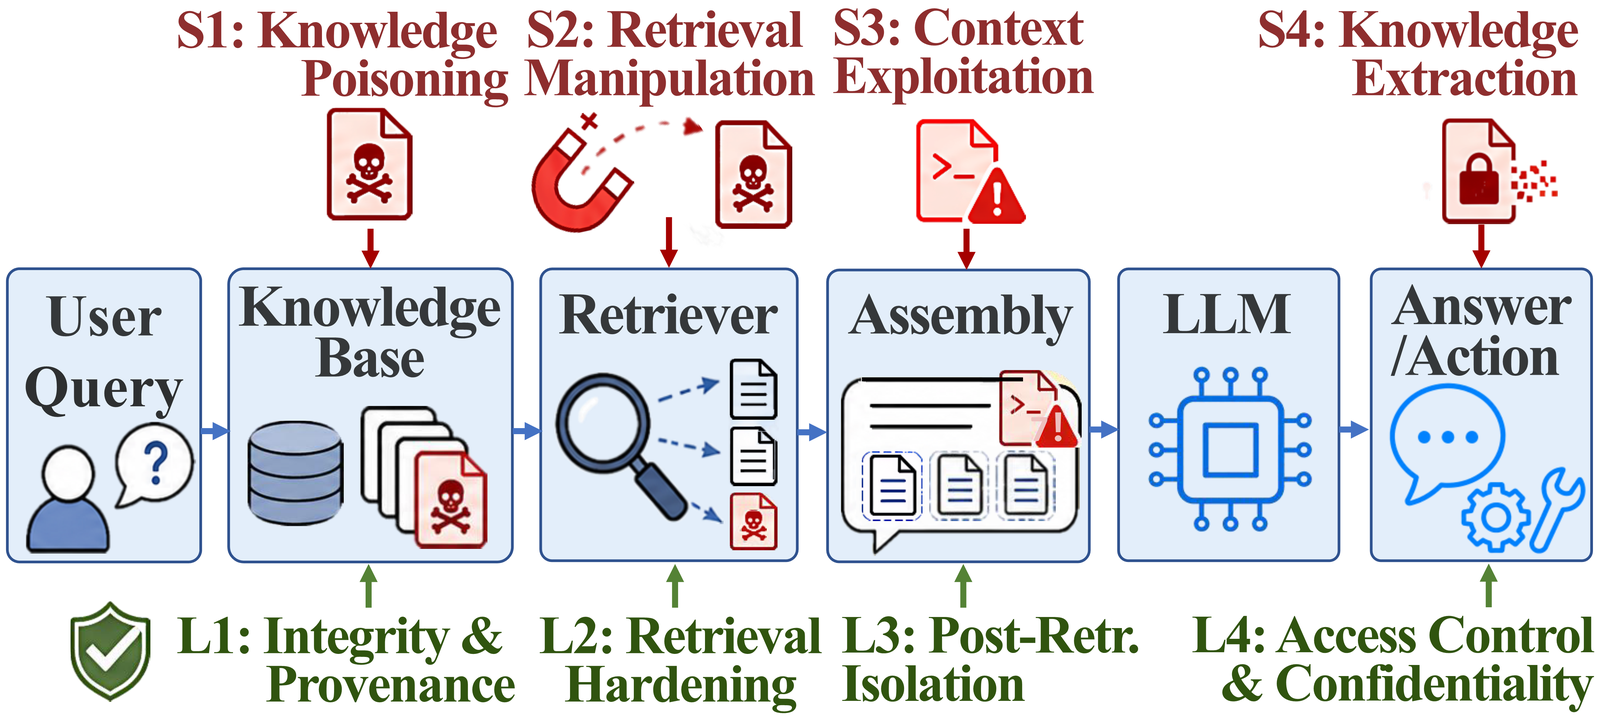
Curated collection of research papers on retrieval-augmented generation security, organized by the SLOT taxonomy covering knowledge poisoning,…

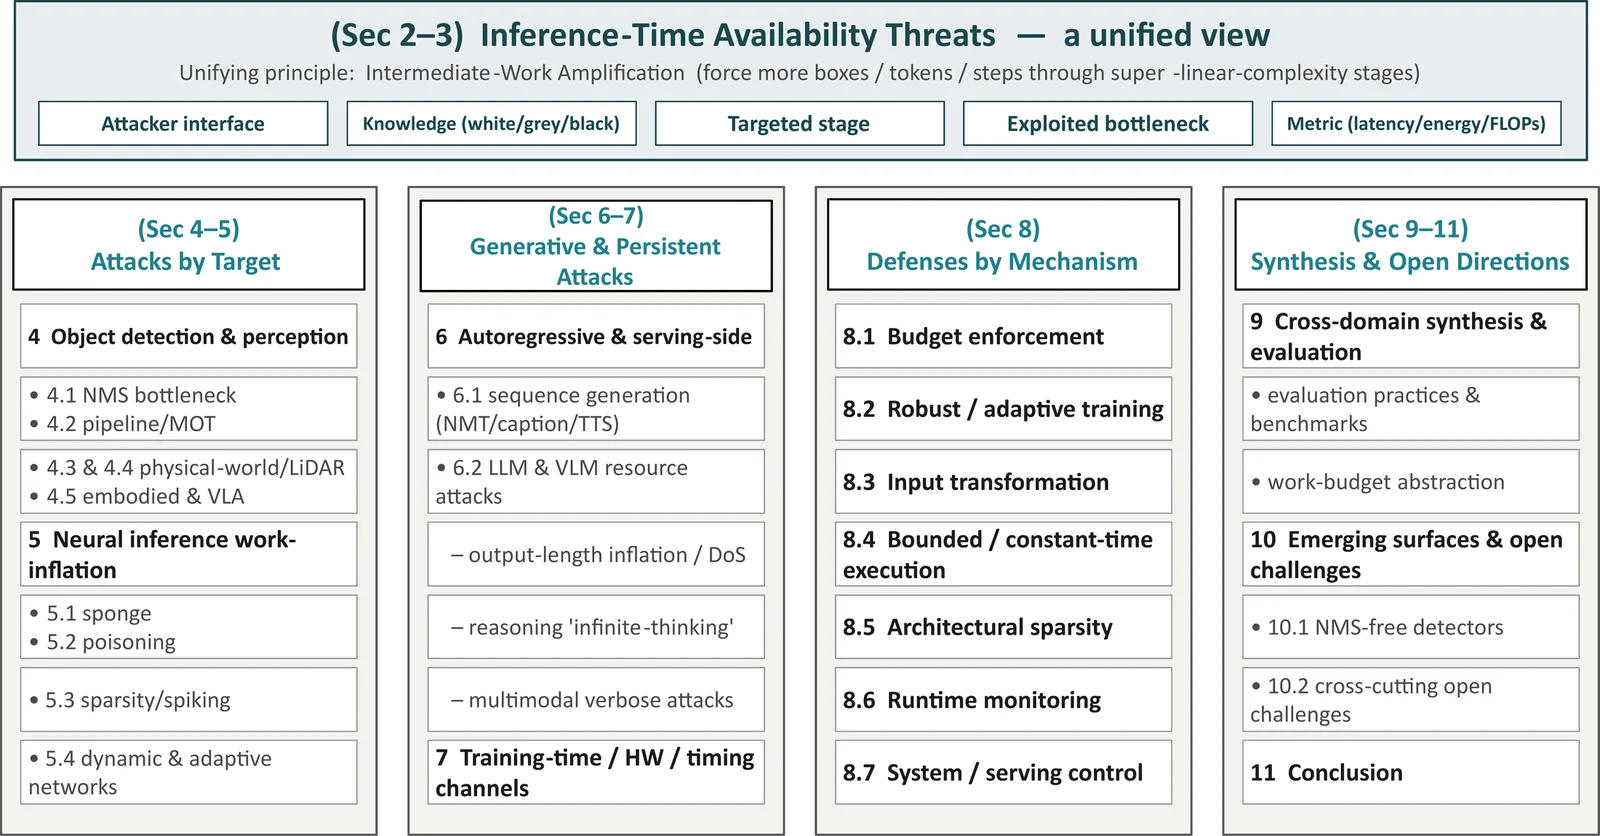
Curated index of deep learning latency, energy-latency & timing (availability) attacks and defenses — companion to the ACM Computing Surveys…

The TTPForge is a Cybersecurity Framework for developing, automating, and executing attacker Tactics, Techniques, and Procedures (TTPs).

We asked 6 AIs about their own programming. All 6 said jailbreaking will never be fixed. Run it yourself — $2, 10 minutes.

Framework for auditing machine learning algorithms against adversarial attacks and biases, providing educational tools and an academic paper to…

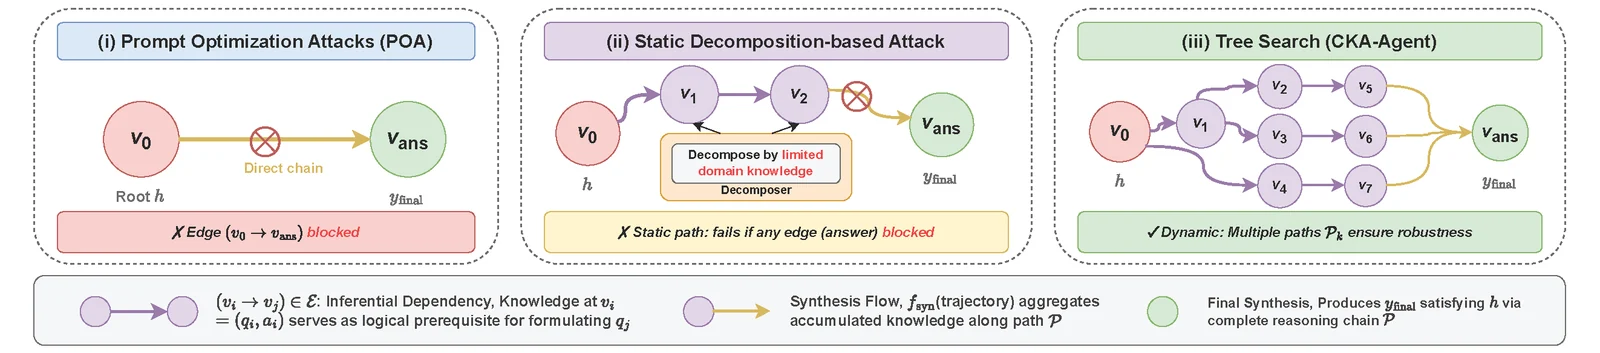
Research implementation of an LLM jailbreak agent that bypasses commercial model guardrails using harmless prompt weaving and adaptive tree search.

Benchmark harness measuring where prompt injection defenses fire in tool-using LLM agent pipelines, tracking canary tokens across exposed, persisted,…

Red-teaming benchmark and black-box attack framework for evaluating visual misinformation risks in commercial image generators, with 10k false-claim…